libfacedetection ships the CNN as C arrays: fast on x86, slow on a Pi, and rebuilt per target
An open source library for face detection in images. The face detection speed can reach 1000FPS.
At a glance
- What is it?
- ShiqiYu/libfacedetection is a CNN face detector with no runtime dependencies, because the trained weights are converted to static C arrays. That makes it easy to drop into an existing C++ build and awkward in three specific ways: the export header is a manual step, the Highway port has no runtime dispatch, and every SIMD gain is tied to the exact resolution in the published tables.
- Who is it for?
- Pick libfacedetection when you are writing C++ and want face boxes with nothing added to your dependency list, and when you control the target hardware and can rebuild for its instruction set.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 139 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
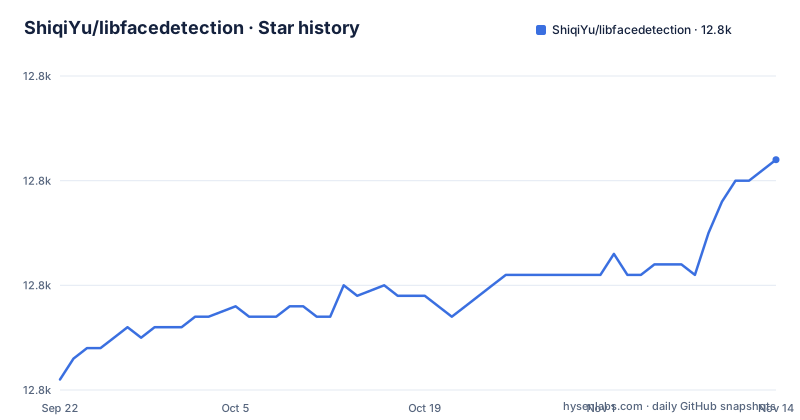
Star history
- ShiqiYu/libfacedetection12,822 ★ · +21
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| ShiqiYu/libfacedetection | 12.8k | 12.8k |
21 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The trained weights are C arrays, so there is nothing to install
libfacedetection is an open source library for CNN based face detection in images, and its unusual property is that the model travels as source code. The CNN has been converted to static variables in C source files, the model lives in src/facedetectcnn-data.cpp as C++ arrays, and the library itself depends on no other libraries. What you need is a C++ compiler, and the source is written in standard C/C++, so it compiles under Windows, Linux, ARM and anything else with a compiler behind it.
Adoption is therefore a copy operation rather than a package manager operation: take the files in src/ into your project and compile them alongside your other files, or build the whole thing as a static or dynamic library and link it. SIMD instructions are what make the detector quick, and you choose the path at compile time: AVX2 on Intel CPUs, NEON on ARM. The compiler flag is part of the design rather than an afterthought, which is why the next thing you need is a correct build configuration rather than a configuration file.
One export macro and one compiler flag sit between copying the files and a link error
The instructions are short enough to miss one step. Copy facedetection_export.h into the same position where you copy facedetectcnn.h, and add #define FACEDETECTION_EXPORT to facedetection_export.h. The project points at issue #222 for that step. Two compiler settings follow: add -O3 to turn on optimizations when building with g++, and choose Maximize Speed/-O2 in Microsoft Visual Studio. Both are stated as tips for making the code fast, so skipping them does not break the build, it just hands back a detector that never reaches the numbers quoted further down the README.
For more control, COMPILE.md is the place to look, and the repository already ships a CMakeLists.txt plus a platform toolchain file named aarch64-toolchain.cmake. The README's primary route is still manual: integration means copying files, defining a macro and choosing flags yourself, so a project with a strict dependency policy has to treat src/ as vendored code with a review obligation attached.
The frame rate table is one CPU, one face size and one thread count
The published numbers describe a specific machine: an Intel Core i7-7820X at 3.60GHz, with multi thread runs using 16 threads and 16 processors, and a minimal face size of about 10x10. On that machine with AVX2, a 640x480 frame takes 50.02 ms and 19.99 FPS single threaded, dropping to 6.55 ms and 152.65 FPS across the 16 threads. At 320x240 the single threaded cost is 13.09 ms and 76.39 FPS, and the multi threaded cost is 1.82 ms and 550.54 FPS. At 160x120 it is 3.61 ms and 277.37 FPS single threaded, 0.57 ms and 1745.13 FPS multi threaded, and at 128x96 it is 2.11 ms and 474.60 FPS single threaded, 0.33 ms and 2994.23 FPS multi threaded.
Switching to AVX512 moves each of those figures: 46.47 ms and 21.52 FPS at 640x480 single threaded, 6.39 ms and 156.47 FPS multi threaded, and 1.98 ms with 504.72 FPS single threaded and 0.31 ms with 3198.63 FPS multi threaded at 128x96. Read those as conditions, not as a spec. Every one of them is tied to a resolution and a face size, and the repository description claiming detection speed of 1000 FPS corresponds to the smaller resolutions with many threads, not to full size video. For OpenMP, the README is direct: you can enable it to speed things up, but the better solution is to call the detection function from different threads yourself, so the threading model is yours to write.
The Raspberry Pi table is where the frame rate claim stops applying
The same detector on ARM Linux, a Raspberry Pi 4 B with a Broadcom BCM2835 Cortex-A72 64-bit SoC at 1.5GHz and 4 threads and 4 processors, gives a very different picture. At 640x480 a frame takes 404.63 ms and 2.47 FPS single threaded, and 125.47 ms and 7.97 FPS multi threaded. At 320x240 it is 105.73 ms and 9.46 FPS single threaded, 32.98 ms and 30.32 FPS multi threaded. At 160x120 it is 26.05 ms and 38.38 FPS, and 7.91 ms and 126.49 FPS multi threaded, and at 128x96 it is 15.06 ms and 66.38 FPS single threaded against 4.50 ms and 222.28 FPS multi threaded.
The gap against the desktop AVX2 table at full resolution is about 8x single threaded (404.63 ms vs 50.02 ms) and about 19x multi threaded (125.47 ms vs 6.55 ms), and it does not come from a different algorithm: it is the same CNN and the same about 10x10 minimal face size, on a chip with a fraction of the throughput. For an embedded deployment the honest reading is that resolution is the lever you control, not the library. Drop to 160x120, keep NEON enabled, call the detector from your own threads, and accept multi digit frame rates. Anyone quoting the 1000 FPS figure for a Pi camera has skipped both the hardware line and the resolution column.
highway/ is a second library with its own header and no runtime dispatch
An independent Highway based implementation sits under highway/, and it deliberately leaves the original untouched while exposing a separate C API:
#include "facedetect_hw.h"

int* results = facedetect_hw_cnn(result_buffer, bgr_image_data,
                                 width, height, step);
The deployment model is the same as the original, which is the catch: you build separately for each instruction set or platform, because the Highway version does not use Highway runtime dynamic dispatch. On x86 the available paths are pure Highway, portable kernels for the pointwise, depthwise, maxpool, image, network and postprocess flow, and an x86 hybrid AVX2 path that pairs Highway packed pointwise with guarded AVX2 and FMA intrinsics in selected depthwise and maxpool kernels. The measured table puts those choices in context: at 640x480 single threaded, origin default or scalar manages 65.66 ms and 15.23 FPS, origin AVX2 manages 33.42 ms and 29.92 FPS, and Highway scalar manages 53.50 ms and 18.69 FPS, with 4.64 ms and 215.70 FPS against 4.56 ms and 219.10 FPS for origin AVX2 once external multi threading is used. Two consequences follow. First, the Highway scalar path is slower than the original AVX2 path single threaded, so adopting it is an experiment rather than an upgrade. Second, without dynamic dispatch a single binary cannot serve several machines, which pushes you back into the per target build you thought the port removed. The API also uses thread local internal workspaces, so the README recommends external parallelism with one result buffer per calling thread.
OpenCV DNN runs YuNet only when the input shape matches exactly
Alongside the C arrays, the project points at the ONNX model from OpenCV Zoo, and the scripts in opencv_dnn/ take C++ and Python paths into that model. The network architecture can be inspected through netron, using the model from the libfacedetection.train repository. The warning that comes with this route is specific and easy to get wrong: OpenCV DNN does not support the latest version of YuNet with dynamic input shape, so you have to ensure the input shape is exactly the one in the ONNX model to run the latest YuNet through OpenCV DNN.
That constraint decides the integration for anyone not compiling the C source. The preprocessing width and height have to be frozen to the model's own shape and every caller downstream inherits that. The model was trained by libfacedetection.train, so the two paths, compiled arrays and ONNX through OpenCV, are two distributions of the same network rather than two different detectors, and mixing expectations between them is the failure mode to watch for.
Tags stopped in 2021 while the master branch kept receiving commits
The release history and the commit history tell different stories. The two tags are v3.0, dated 20210920-release, published on 24 September 2021, and v2.0, dated 2021209-release, published on 9 February 2021. The last push to the default branch master landed on 28 June 2026, and the repository is not archived.
If you consume this project by tag, you are working from a 2021 snapshot and none of the later work is in your build; if you track master, you are tracking a branch whose release numbers no longer describe its contents. Pick one deliberately. Two smaller checks matter at the same time. There is a LICENSE file in the root, but GitHub reports NOASSERTION for this repository's license, so confirm the terms yourself before shipping it in a product. And the repository carries a ChangeLog, a .gitignore and wu-thesis-facedetect.pdf, which tells you where the original work was documented but not which of those artifacts match the code you just checked out.
Editorial conclusion
Pick libfacedetection when you are writing C++ and want face boxes with nothing added to your dependency list, and when you control the target hardware and can rebuild for its instruction set. Do not adopt it expecting the multi threaded frame rates in the tables to transfer: the same 640x480 case runs at 2.47 FPS single threaded on a Raspberry Pi 4 B. Before you commit, copy facedetection_export.h with the FACEDETECTION_EXPORT define, match the input shape exactly if you go through OpenCV DNN, and decide whether the last tagged release from 2021 is close enough to master, where the last push landed on 28 June 2026.
Frequently asked questions
Can you give me an example of face detection with libfacedetection?
examples/detect-image.cpp and examples/detect-camera.cpp show how to use the library, and example/benchmark.cpp plus example/benchmark-highway.cpp cover the timing side. The Highway port has its own header, facedetect_hw.h, whose entry point is facedetect_hw_cnn with a result buffer, the BGR image data, width, height and step.
How does facial recognition know who you are in libfacedetection?
It does not, and that is the point. libfacedetection is an open source library for CNN based face detection in images, and the CNN model has been converted to static variables in C source files. Nothing in it compares faces or returns an identity, so anything you build on top needs a separate recognition step.
How accurate is YuNet according to libfacedetection?
The library reports WIDER Face average precision on its default settings, scales=[1.], confidence_threshold=0.02, floating point: AP_easy=0.887, AP_medium=0.871, AP_hard=0.768. The published minimal face size is about 10x10.
How accurate is face detection with libfacedetection?
Accuracy is reported as WIDER Face average precision at default settings rather than as a percentage of correct boxes, with AP_easy=0.887, AP_medium=0.871 and AP_hard=0.768. The timing tables cover four resolutions from 640x480 down to 128x96 on an Intel i7-7820X and on a Raspberry Pi 4 B, all at a minimal face size of about 10x10.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shiqiyu-libfacedetection)Star history chart for your README
[](https://hysenlabs.com/projects/shiqiyu-libfacedetection)Was this useful?