PyMuPDF: wheels, optional OCR and Office packages, and the AGPL-3.0 license behind the Python PDF toolkit
PyMuPDF is a high performance Python library for data extraction, analysis, conversion & manipulation of PDF (and other) documents.
At a glance
- What is it?
- PyMuPDF wraps the MuPDF C engine for text, table, image and annotation work on PDFs and other formats. This look follows what a pip install gives you, which pieces need separate packages, and what the source build and license mean for your project.
- Who is it for?
- PyMuPDF is the right pick when you need fast PDF text, table, rendering and redaction work in Python and can accept AGPL-3.0 terms. Skip it, or get the license terms in COPYING reviewed, if you ship closed-source software, and test OCR on your own long documents before trusting either engine.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
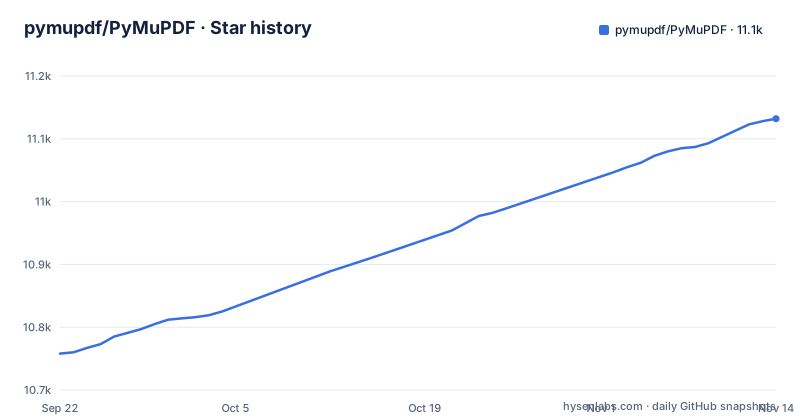
- pymupdf/PyMuPDF11,132 ★ · +374
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| pymupdf/PyMuPDF | 10.8k | 11.1k |
374 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One pip command, plus a force-reinstall repair for mixed pymupdf-layout and pymupdf4llm installs
The install line is a single upgrade command.
pip install --upgrade pymupdfThe repository gives a second command for a specific breakage: an installation left broken after upgrading PyMuPDF from earlier versions, or after running separate installation commands for pymupdf-layout or pymupdf4llm.
pip install --force-reinstall --no-cache-dir pymupdfThat command is meant to produce a clean installation. The practical reading is that PyMuPDF now overlaps with those two companion package names, and a virtual environment that once had them installed separately can end up in a state a plain upgrade does not fix. If an import fails right after moving from a 1.x release to 2.x, try the force-reinstall before debugging anything else.
Pre-built wheels cover Python 3.11 to 3.15, and everything else compiles from source
Wheels exist for Windows, macOS, and Linux on Python 3.11 to 3.15. If no pre-built wheel exists for your platform, pip compiles from source, which needs a C/C++ toolchain. A Python 3.10 environment or an unusual architecture therefore falls into the slow path, and a minimal Docker image without compilers will fail there.
The source build is driven by setup.py, with pyproject.toml declaring pipcl as the build requirement and a backend path pointing at the repository root. The script hard-codes the URL of the MuPDF tarball it needs, downloads it at build time, builds MuPDF locally, and then builds PyMuPDF against that exact release. Since the sdist no longer embeds the tarball, a source build on a machine without network access cannot complete by default. Packagers who want a system MuPDF set PYMUPDF_SETUP_MUPDF_BUILD to an empty string and point PYMUPDF_MUPDF_LIB at the directory holding libmupdf.so and libmupdfcpp.so.
Layout analysis depends on ONNX Runtime being usable in your environment
A note in the installation section warns that PyMuPDF uses the ONNX Runtime for certain layout analysis features, and tells readers to make sure their Python environment can support it. That matters for anyone deploying to a constrained image, since plain text extraction and the layout features do not share the same runtime requirements.
After installing, run the `pymupdf-config` command. It reviews what is installed and shows what other packages, Python and otherwise, may be available for your system and could improve accuracy and speed. Treat it as the first diagnostic step on a new machine: it tells you which optional pieces are missing before a job fails halfway through a batch. The page-level API is unaffected by it, but the quality of OCR and layout output can change depending on which extras it reports.
Office, fonts and OCR each live in a separate package, and Tesseract must be installed outside pip
The core wheel does not bring everything. The optional packages are pymupdf-office for Office document support, pymupdf-fonts for an extended font collection for text output, rapidocr as an OCR engine, and tesseract-ocr as another OCR engine.
# Office support
pip install pymupdf-office

# More fonts
pip install pymupdf-fonts

# OCR
pip install rapidocr

# OCR (Tesseract must be installed separately)
# macOS
brew install tesseract

# Ubuntu / Debian
sudo apt install tesseract-ocr
The consequence is that a service which opens DOCX or PPTX files fails until pymupdf-office is added, because DOC, DOCX, XLS, XLSX, PPT, PPTX, HWP and HWPX are listed under PyMuPDF Office rather than core input. Tesseract is a system dependency, so it has to be present in the image or on the host, and the OCR example is marked as requiring Tesseract installed and on PATH.
RapidOCR beats Tesseract overall in the project's own test, but not on documents over 50 pages
The README includes a comparison on the ExtractBench corpus of 370 PDFs. For short documents of 1 to 10 pages (252 PDFs), PyMuPDF with Tesseract scores 80.39% and with RapidOCR 88.94%. For medium documents of 11 to 50 pages (98 PDFs) the scores are 82.72% and 87.00%. For long documents over 50 pages (20 PDFs) the order flips: Tesseract 30.49% against RapidOCR 29.22%. Overall it is 78.31% against 85.20%, and the README concludes that RapidOCR is recommended for the best OCR accuracy.
Read that carefully. The long-document row has only 20 PDFs, and both engines score near 30%, so neither is reliable there. If your workload is mostly scans of 50 pages or more, run your own sample before choosing. This is the README's reported result, not a measurement made for this article. The OCR example calls `page.get_textpage_ocr(language="eng").extractText()` and needs Tesseract, so the RapidOCR path is a separate install.
Text, tables and page images come from short page-level calls
The quick start opens a file with `pymupdf.open` and iterates pages. Plain text is `page.get_text()`. Layout metadata comes from `page.get_text("dict")["blocks"]`, where a block with type 0 is a text block containing lines and spans, and each span carries text, font and size. Tables come from `page.find_tables()`, and each table converts with `to_markdown()` or `to_pandas()`.
import pymupdf

doc = pymupdf.open("spreadsheet.pdf")
page = doc[0]

tables = page.find_tables()
for table in tables:
    print(table.to_markdown())

    # or get as Pandas DataFrame
    df = table.to_pandas()
Rendering to an image is `page.get_pixmap(dpi=150)` followed by `pixmap.save("page_0.png")`. Output formats include PDF, SVG, images at any DPI, Markdown, JSON with bounding boxes, and plain text. The to_pandas call assumes pandas is installed in your environment, which the pip command above does not add.
Redaction is a two-step call, and merging mutates a new document, not the inputs
Annotation and redaction are separate steps. The example creates a `pymupdf.Rect(72, 100, 400, 120)`, calls `page.add_highlight_annot(rect)` for a highlight, then `page.add_redact_annot(rect)` followed by `page.apply_redactions()`, and finally saves to a new file name such as contract_redacted.pdf. Marking a redaction annotation alone does not remove content; the apply call is the step that does. A pipeline that skips it ships a file that still looks unredacted to the library.
Merging opens an empty document with `pymupdf.open()`, loops over paths, and calls `merger.insert_pdf(pymupdf.open(path))` for each before `merger.save("merged.pdf")`. Converting Markdown to PDF is `pymupdf.open("example.md")` followed by `save("example.pdf")`, and `doc.to_markdown()` returns text meant for an LLM or vector store. Input formats beyond PDF include XPS, EPUB, CBZ, MOBI, FB2, SVG, TXT, MD and common image formats.
Version 2.1 landed one day before the last push, and the license is AGPL-3.0
Recent releases are 1.28.2 on 2026-08-06, 2.0 on 2026-10-19, and 2.1 on 2026-11-02. The repository is not archived and the most recent push is dated 2026-11-02. The move from 1.28 to 2.0 is a major version change, so pin the version in requirements and read changes.txt before upgrading a production pipeline. The same file layout includes src and src_classic directories next to docs, tests, and a pymupdf-all folder.
The license is AGPL-3.0, with the text in the COPYING file. That is the answer to whether it is free to use: the source is open and free to obtain, but the terms are copyleft, and you should read COPYING before bundling it into a product you distribute or run as a hosted service. Nothing in the repository facts here describes a separate commercial license, so ask the maintainers if AGPL does not fit your project.
Editorial conclusion
PyMuPDF is the right pick when you need fast PDF text, table, rendering and redaction work in Python and can accept AGPL-3.0 terms. Skip it, or get the license terms in COPYING reviewed, if you ship closed-source software, and test OCR on your own long documents before trusting either engine.
Frequently asked questions
What is PyMuPDF used for?
PyMuPDF is a Python library for data extraction, layout analysis, conversion, rendering and manipulation of PDF and other documents. It is built on the MuPDF C engine.
Is PyMuPDF free to use?
The repository is licensed under AGPL-3.0, with the terms in the COPYING file. Read them before using it in a distributed or hosted product.
How can I convert a PDF to an image using PyMuPDF?
Open the file with pymupdf.open, take a page, call page.get_pixmap(dpi=150), then save the pixmap with pixmap.save("page_0.png").
How to install PyMuPDF using pip?
Run pip install --upgrade pymupdf. If an upgrade left a broken installation, use pip install --force-reinstall --no-cache-dir pymupdf instead.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pymupdf-pymupdf)Star history chart for your README
[](https://hysenlabs.com/projects/pymupdf-pymupdf)Was this useful?