wikiextractor has no dependencies, two console scripts, and one option that decides how long your run takes
A tool for extracting plain text from Wikipedia dumps. Warning**: problems have been reported on Windows due to poor support for StringIO in the Python implementation on Windows.
At a glance
- What is it?
- A look at a Wikipedia dump text extractor written in Python 3 with an empty install_requires: template expansion done by preprocessing the whole dump, a template file you can save and reload, a --no-templates switch that skips the expensive part, output split into megabyte-sized files, and a Windows fix that took until the 3.1.0 release in 2026.
- Who is it for?
- wikiextractor fits someone building a text corpus or a search index out of a Wikipedia dump who wants a script with no dependency tree to reason about and can live with the raw XML in and plain documents out. It does not fit someone who wants structured data, since the output is article text with revisions stripped of markup rather than parsed infoboxes or categories as fields.
- Can I use it commercially?
- Yes, with strict conditions. AGPL-3.0 is a network copyleft licence: if people use a modified version over a network, for example as a hosted service, you must offer them its source code under the same licence.
- Is it still maintained?
- Yes. The repository last received commits 26 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
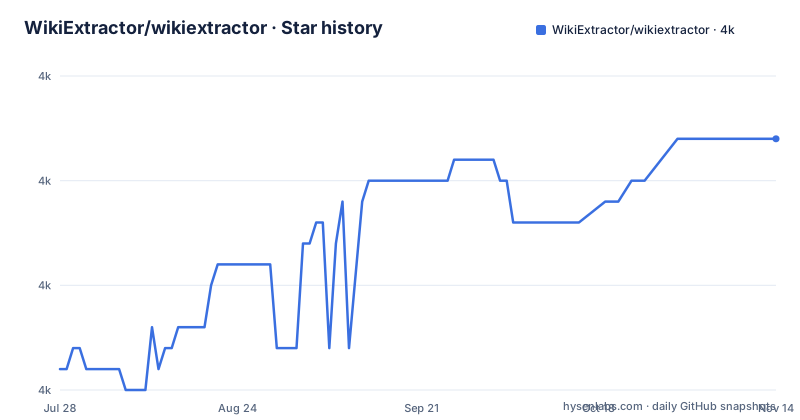
- WikiExtractor/wikiextractor4,007 ★ · +11
| Repository | 2026-07-28 | 2026-11-14 |
|---|---|---|
| WikiExtractor/wikiextractor | 4k | 4k |
11 Stars in the last 109 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
install_requires is empty and python_requires is 3.9
The stated requirement is Python 3 and no additional library, and the packaging metadata backs that up rather than just claiming it. The setup script declares install_requires with an empty list, and the interpreter floor is 3.9.
That is a rare combination for a tool of this age. Most Python extractors of Wikipedia text arrived with a list of XML and compression libraries, and this one uses the standard library for both. For a script whose job is to read a multi-gigabyte bzip-compressed XML file, that is the decision that makes it easy to run in a container or on a machine you do not control.
There are three ways to invoke it. Directly, as a module:
python -m wikiextractor.WikiExtractor <Wikipedia dump file>From PyPI:
pip install wikiextractorOr from a checkout with a setup script install, which the readme shows with an optional sudo in front of it.
The PyPI route installs two console scripts in addition to the module. One is named wikiextractor and is stated to be equivalent to the module invocation. The other is extractPage, which extracts a single page from a dump rather than the whole thing. That second script is the one to reach for when you want one article out of a dump you have not downloaded in full.
The long description for the package index is read straight out of the repository's README, with the content type set to markdown, so the page you read before installing is the same file that ships in the source tree.
Template expansion is done by preprocessing the entire dump
This is the mechanism that decides how long a run takes, and the readme states it in one sentence: WikiExtractor performs template expansion by preprocessing the whole dump and extracting template definitions.
MediaWiki templates are the reason Wikipedia text cannot simply be stripped of markup. An infobox is a template, a citation is a template, most of the layout is a template. To get article prose you either expand them or you discard the parts that used them.
That expansion is what the two template options control. The --templates option takes a file path and writes the extracted template definitions to it. Passing that same file back in on a later run reloads the definitions instead of recomputing them, which the readme says reduces the time to perform extraction. The mechanism is the same for the internal cache: a cache is kept of parsed templates, described as only useful for repeated extractions.
Then there is the other end of the trade. The --no-templates option is described as significantly speeding up the extractor by avoiding the cost of expanding MediaWiki templates. So the decision is explicit rather than implicit: pay for full expansion, or skip it and accept that template-generated content is not resolved.
Two things make the cost bearable. Multiprocessing is used to deal with articles in parallel, and the preprocessing pass over the dump happens once before the parallel work rather than per article.
Output is many files of a capped size, not one corpus file
The output shape is described twice in the same way: several files of similar size in a given directory, each containing several documents in the documented format.
The document format is a simple element with an id, a url and a title attribute and the article body inside it. That is the whole contract for a consumer, and it is documented on the project's wiki under a file format page.
The size cap is a command line option. The bytes option takes a number with an optional K, M or G suffix and sets the maximum bytes per output file, with a default of one megabyte. So a full English Wikipedia extraction arrives as a very large number of small files, which is convenient for streaming consumers and inconvenient for anything that wants to read the whole thing into memory.
The compress option compresses the output files using bzip. The output option names the directory, and in the Cirrus variant's help the directory can also be given as a dash, which dumps to standard output instead. That is the only place in the documentation where writing to a stream is described, so it is worth knowing which extractor supports it.
There is also a json flag and an html flag, and an html-safe option taking a value. Those four exist to change the shape of each document rather than the shape of the run.
The Cirrus variant has fewer options and two more attributes per document
There is a second script in the project, cirrus-extractor.py, described as a version of the script that performs extraction from a Wikipedia Cirrus dump. The reason for the separate tool is in one line: Cirrus dumps contain text with already expanded templates.
That single fact cascades through the whole design of the variant. Its help text has no template options at all, because there is nothing to expand. It also has a shorter option list: output, bytes, compress, namespaces, quiet and version, against the main extractor's much longer list.
The document format differs too. The Cirrus output writes an element with id, url, title, language and revision attributes. The main extractor's format has id, url and title only. The language attribute is the obvious one: Cirrus dumps are JSON with per-document metadata rather than one XML article stream, and that metadata survives into the output.
Its input is described as a Cirrus JSON wiki dump file, and those dumps are published separately from the article dumps, under the cirrussearch directory of the same dumps site.
So the choice between the two scripts is not a feature preference. It is a question of which dump format you have. If you already have a Cirrus dump, the main extractor is not a slower option for it, it is the wrong input format.
Version 3.1 fixes a security hole, and the suggested citation still says 2015
Two version facts sit next to each other and they point in opposite directions.
The security one is stated without hedging. The readme says the latest version, 3.1, fixes a serious security hole and that all users should update. There is a SECURITY.md in the repository root alongside the licence and the readme, so the disclosure trail exists rather than the note being a single sentence with nothing behind it.
The citation one is quietly out of date. The reference section gives a BibTeX entry with the author, the title WikiExtractor, the year 2015, the publisher GitHub, and a howpublished URL. That entry is what the project asks you to use in publications, and it predates the version carrying the security fix by eleven years.
So if you cite the tool, follow the advice on the version and ignore the advice on the year, or update the year field yourself. The author name in both the citation and the packaging metadata is Giuseppe Attardi, and every documentation link in the project points at a repository under that name rather than at the organisation the project page sits under.
The licence is the GNU Affero General Public License version 3, which is the same copyleft family as the AGPL identifier on the project page and a heavier choice than the permissive licences most text-processing tools use.
The Windows fix shipped in 2026, three years after the previous release
The repository description carries a warning that is unusual to see in a project summary, and it is about a specific platform.
It says that problems have been reported on Windows, and attributes them to poor support for StringIO in the Python implementation on Windows. StringIO is the in-memory text buffer that the standard library offers on other platforms, so this is a portability problem in the reading path rather than a bug in the extraction logic.
The release history shows what happened next. v3.0.7 was published on 2023-01-24. Then nothing for three and a half years. v3.0.8 came on 2026-07-23 with the title update Python regexes, and v3.1.0 followed on 2026-08-10 with the title Windows compatibility.
Two things follow from that sequence. The first is that the Windows problem was real enough to be the reason for a minor version bump, and the second is that this project releases in response to specific problems rather than on a schedule. The gap is not a sign of abandonment: the repository is not archived and the last push was on 2026-10-04.
If you are on Windows, the version to use is 3.1 or later. If you are on Linux or macOS and pinned to something older, the security note still applies to you, because that fix is what the current version carries.
The version lives in the module and setup.py appends a zero to it
There is a small piece of logic in the packaging script that is worth knowing about if you cut a release.
The version is not written in the setup script. It is imported from the extractor module itself, and a helper function normalises it: if the version matches a pattern of one or more digits, a dot and one or more digits, a .0 is appended. Otherwise the value is used unchanged.
So a developer working with 3.1 in the module gets 3.1.0 in the package metadata, and a three-part version like 3.0.8 passes through untouched. That is the whole purpose of the function, and it exists because the two forms appear in different places: the release tags and the module.
The rest of the packaging is conventional and tells you what the project expects of a user. Packages are found with a filter for the wikiextractor package only, the classifiers describe it as production and stable, intended for developers, in the text processing and linguistic topic, and Python 3.
The repository root also has an extract.sh script and directories for tools and tests. So the distribution shape is a Python package with two console scripts, plus a shell wrapper and a test directory beside it.
Namespaces, processes and html-safe output are three flags most runs never touch
The main extractor's option list is long, and most of it is about narrowing or shaping the output rather than about making the run faster.
The namespaces option takes a comma separated list of accepted namespaces. That is the filter that decides which pages end up in your corpus at all, and it is the option people reach for when their extraction contains more than they wanted.
The processes option takes a number, which caps the multiprocessing fan-out. Leaving it alone means the script decides how many workers to use, which is usually right on a machine whose memory you do not know.
The html-safe option takes a value rather than being a flag, which tells you it configures escaping behaviour in the html output mode. It pairs with the plain html flag, and with the json flag for a different document shape entirely.
The remaining switches are ordinary instrumentation: quiet to suppress progress reporting, debug for logging, a short form for debug logging, and version to print the program version. The progress reporting is the default, so on a run that takes hours you get told what it is doing unless you turn it off.
Editorial conclusion
wikiextractor fits someone building a text corpus or a search index out of a Wikipedia dump who wants a script with no dependency tree to reason about and can live with the raw XML in and plain documents out. It does not fit someone who wants structured data, since the output is article text with revisions stripped of markup rather than parsed infoboxes or categories as fields. Before running it, decide whether you need template expansion, because skipping it is the difference between a fast run and a slow one, save the template file on the first run if you are extracting more than once, and take version 3.1 rather than anything older, since it fixes a security hole the project states plainly.
Frequently asked questions
How do I use wikiextractor on a Wikipedia dump?
Invoke it with the dump file as the argument, either as python -m wikiextractor.WikiExtractor <Wikipedia dump file> or with the installed wikiextractor command, which is stated to be equivalent. Adding --templates writes the extracted template definitions to a local file you can pass back in later to reduce extraction time.
Where do I get the Wikipedia dump that wikiextractor reads?
The dumps are published by Wikimedia, and the readme links the English pages-articles XML dump as the example input. Cirrus dumps, which cirrus-extractor.py reads instead, are published separately under the cirrussearch directory of the same dumps site.
What does wikiextractor need installed, and does it work on Windows?
It requires Python 3 and no additional library; the packaging metadata declares an empty install_requires and a minimum of Python 3.9. The repository description carries a warning that problems have been reported on Windows because of poor support for StringIO in the Python implementation on Windows, and the 3.1.0 release is titled Windows compatibility.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/wikiextractor-wikiextractor)Star history chart for your README
[](https://hysenlabs.com/projects/wikiextractor-wikiextractor)Was this useful?