torchaudio: both citation entries are malformed, and one shipped model is non-commercial
Data manipulation and transformation for audio signal processing, powered by PyTorch
At a glance
- What is it?
- A PyTorch library for machine learning on audio, now decoupled from torch versioning and in a maintenance phase after features deprecated in 2.8 were removed in 2.9. It is the small library the PyTorch ecosystem kept for audio data work, and the details worth checking are in its packaging and its citation block rather than its API.
- Who is it for?
- torchaudio suits a project that already uses PyTorch and wants audio transforms, dataset loaders and Kaldi-compatible front ends without leaving the tensor ecosystem. It does not suit anyone expecting new features, because the library has declared a maintenance phase and its stated goal was to remove redundancy with the rest of PyTorch.
- Can I use it commercially?
- Yes. BSD-2-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
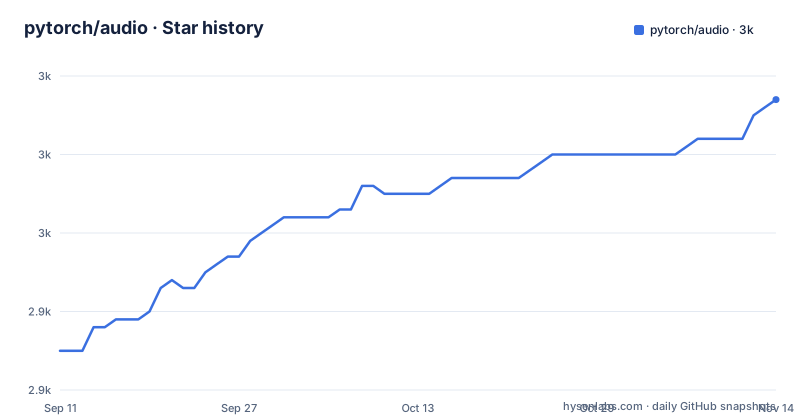
- pytorch/audio2,967 ★ · +32
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pytorch/audio | 2.9k | 3k |
32 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The release train decouples torchaudio from torch versioning
The important note at the top states that TorchAudio 2.11 works with `torch` 2.11 and with every future torch release, that it is the latest release and the only one needed, that there is nothing to upgrade in TorchAudio when torch is upgraded, and that installing TorchAudio does not pin torch to a version. The installation section repeats it: 2.11 requires torch 2.11 or newer, including future releases, and does not pin it. So the two projects version independently, and the compatibility matrix for older releases is delegated to the installation page rather than kept in the repository. The releases themselves are still cut per minor version, with 2.9.1, 2.10.0 and 2.11.0 in the recent list, but the last push to the repository is dated 2026-10-04, more than six months after the 2.11.0 tag was published on 2026-03-23.
Maintenance phase, with the removals already done rather than pending
The second note announces that TorchAudio has transitioned into a maintenance phase and that the migration process removed some user-facing features, deprecated from TorchAudio 2.8 and removed in 2.9. It is written in the past tense throughout: the features are already gone, not scheduled to go. The stated goals were to reduce redundancies with the rest of the PyTorch ecosystem, make the library easier to maintain, and scope it more tightly to its strength of processing audio data for machine learning, with the reasoning deferred to a community message in the project's issue tracker. The practical reading is that new capability is not the plan here, and a project that needs a transform removed in 2.9 has to implement it or move it.
Neither BibTeX entry is complete enough to compile
The citation section asks users to cite the package and then provides two entries, both of which are broken in the file. The first, an article entry with a title about building blocks for audio and speech processing and a long author list, ends mid-field: the last line is nothing but the letter y, so the year key is cut in half and the closing braces are absent. The second, a miscellaneous entry for TorchAudio 2.1, ends on `year={2023` with no closing brace at all, so the entry never terminates. Both are the kind of breakage that comes from editing a fenced block without rechecking it, and it lands on the one part of the file that every academic user copies verbatim.
A BSD-2 library ships a model under a non-commercial license
The library itself is BSD-2-Clause, but the file is explicit that the pre-trained models it provides may carry their own licenses or terms derived from the dataset used for training, and that determining permission for a use case is the user's responsibility. The example given is a model released under the Creative Commons Attribution Non Commercial 4.0 International license. So a project on a commercial footing can install the library, use every transform, and still be barred from one of its models by a term that is unrelated to the library's own. The dataset disclaimer is the same shape: the library downloads and prepares public datasets, does not host or distribute them, does not vouch for their quality or fairness, and does not claim you have a license, with removal requests handled through an issue.
pyproject.toml configures formatters and nothing else
The packaging metadata is split across three files, and the modern one is not the one that matters. `pyproject.toml` contains three tool sections and no build system or project table: usort with first-party detection disabled, black with a line length of 120 and a target version of py38, and ufmt excluding the tutorials directory from formatting. The package metadata itself lives in `setup.py`, with `setup.cfg` alongside it. That target version is worth noting next to the rest of the file, since a formatter configured for Python 3.8 sits in a package that requires torch 2.11. The top level also carries C++ tooling in `.clang-format` and `.clang-tidy` next to Python tooling in `.flake8`, `.pre-commit-config.yaml` and `mypy.ini`, which is consistent with a package that still builds native extensions.
The build script imports torch, so building requires torch
`setup.py` imports torch at the top level and also pulls a helper from an in-repository `tools` package, so the build environment needs the framework present before packaging starts. Version resolution reads a `version.txt` file, lets an environment variable override it, and otherwise appends the first seven characters of the commit hash after a plus sign, which is how local builds get distinguished from releases. That version is then written into a generated `src/torchaudio/version.py` alongside the full hash. The file also subclasses the standard clean command to delete every shared object under `src/` and remove the build directory, and it parses URLs out of text files with a regular expression. All of that is ordinary packaging work, and none of it is documented in the readme.
The requirements file has three lines, and one dependency is never named
Installation is a single command:
pip install torchaudioUnderneath it, the requirements file is three lines of substance: torch as the minimum runtime dependency, torchcodec as an optional runtime dependency, and a note that build and test-time dependencies are in the contributing guide rather than in the file. The readme body never mentions torchcodec anywhere, so an optional runtime dependency exists in the packaging with no explanation of what it enables or when you would want it. The install section itself defers the full instructions, the build steps, and the compatibility matrix for older releases to the documentation site, which means the repository carries the one-line path and nothing about what happens when the wheel for your platform is not the one published.
It is positioned as a machine learning library, not a signal processing one
The stated philosophy is that applying PyTorch to the audio domain brings the same priorities as elsewhere: strong GPU acceleration, trainable features through the autograd system, and consistent style for tensor and dimension names. The file then draws a line it wants readers to notice, saying torchaudio is primarily a machine learning library and not a general signal processing library. The feature list follows that line, covering dataset loaders, functions such as forced alignment, a transform set of spectrogram, amplitude to decibels, mel scale, mel spectrogram, MFCC, mu-law encoding and decoding, and resampling, plus compliance interfaces matching Kaldi's spectrogram, filter banks and MFCC. The examples tree mirrors the scope, with directories for speech recognition, beamforming, HuBERT, source separation, self-supervised learning and several text-to-speech pipelines, though the file does not state which of those examples still run after the 2.9 removals.
Editorial conclusion
torchaudio suits a project that already uses PyTorch and wants audio transforms, dataset loaders and Kaldi-compatible front ends without leaving the tensor ecosystem. It does not suit anyone expecting new features, because the library has declared a maintenance phase and its stated goal was to remove redundancy with the rest of PyTorch. Three things to settle before you depend on it. The library is BSD-2 but the shipped models are not uniformly so, with one named model released under a non-commercial license, so check the license of each model you use. Build and test dependencies are not in the requirements file at all. And if you cite it, fix the citation, since neither of the two BibTeX entries in the file is complete enough to compile.
Frequently asked questions
What is torchaudio?
A library that applies PyTorch to the audio domain for machine learning, providing GPU acceleration, trainable features through autograd, and consistent tensor and dimension naming. The file states it is primarily a machine learning library rather than a general signal processing library.
How do you install torchaudio?
With pip install torchaudio. TorchAudio 2.11 requires torch 2.11 or newer, including future releases, and does not pin torch to a specific version. Full build instructions and the compatibility matrix for older releases are on the documentation site.
Is torchaudio still being developed?
It has transitioned into a maintenance phase. Features deprecated from version 2.8 were removed in 2.9, and the stated goals were to reduce redundancy with the rest of the PyTorch ecosystem and narrow the scope to processing audio data for machine learning.
Which audio transforms does torchaudio provide?
Spectrogram, AmplitudeToDB, MelScale, MelSpectrogram, MFCC, MuLawEncoding, MuLawDecoding and Resample, alongside dataset loaders and compliance interfaces for Kaldi's spectrogram, filter banks and MFCC.
Can torchaudio be used commercially?
The library is BSD-2-Clause, but the file states the pre-trained models may carry their own terms derived from their training datasets, and names one model released under CC-BY-NC 4.0. Permission for each model you use is your responsibility to determine.
What are torchaudio's runtime dependencies?
One minimum, torch, and one optional, torchcodec, which the readme itself does not mention. Build and test-time dependencies are not listed in the requirements file and are referred to the contributing guide instead.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-audio)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-audio)Was this useful?