TorchRL caps its tensor container below the next minor and calls two of its extras mutually exclusive
A modular, primitive-first, python-first PyTorch library for Reinforcement Learning.
At a glance
- What is it?
- TorchRL is PyTorch's library of composable reinforcement learning pieces, built around a named tensor container that lives in another repository. Its packaging tells you more about the constraints than its feature list does: an upper bound on that container, two extras declared incompatible, and a build that needs a compiler before anything can be imported.
- Who is it for?
- TorchRL is worth adopting when you want reinforcement learning code that looks like PyTorch code, with one data structure carrying observations, masks, rewards and recurrent state instead of parallel arrays. Three things to know first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
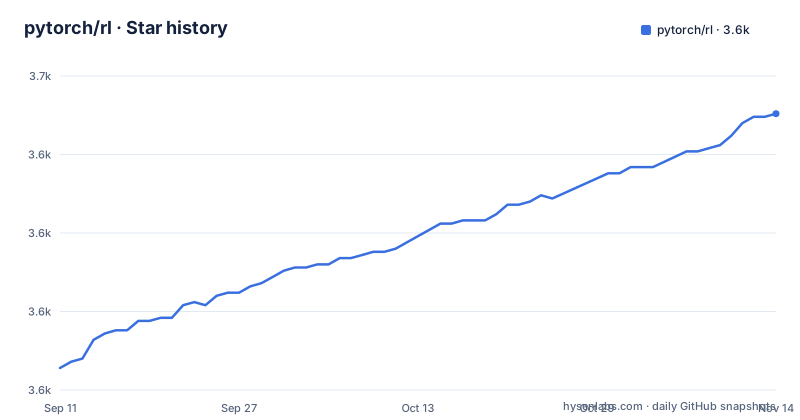
- pytorch/rl3,638 ★ · +81
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| pytorch/rl | 3.6k | 3.6k |
81 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The data structure everyone passes around lives elsewhere
The README states three ideas and the first two are about data. Data should have names, structure, batch dimensions and devices all the way through the training loop, and environments, policies, replay buffers, objectives and collectors should be independent modules that can be swapped without rewriting the rest of the stack. The third says research code should scale from a local prototype to vectorized, multiprocess, distributed, compiled, recurrent, multi-agent, model-based or offline workflows without changing the data model. The object that makes that possible is a dictionary-like tensor container with PyTorch operations, device transfers, shared-memory support, memmaps, lazy views and module wrappers. It is not in this repository: it has its own project and its own release cadence. The operations on it are deliberately structure-preserving:
# These operations preserve the structure and operate on every compatible value.
batch = torch.stack(list_of_tensordicts, dim=0)
batch = batch.reshape(-1)
batch = batch.to("cuda")
mini_batch = batch[:128]
Stacking, reshaping, moving to a device and slicing all leave the named fields intact, which is why a collector can emit one, a replay buffer can store it without flattening its structure, and a loss can read exactly the keys it needs.
The container dependency has an upper bound, not a floor
Most dependencies in this library are floors: a minimum PyTorch version, and minimums or open ranges for the packaging, serialisation and tensor helpers. The tensor container is the exception. It is required at a specific minor line and above, with the range closing before the next one, which means an upgrade of the container to its next minor is blocked until this library moves. That is a deliberate choice rather than an oversight: the whole value proposition is that components compose through one data model, so a breaking change in that model is a breaking change for everything built on it. The practical effect is on your resolver, which will now be constrained by two projects rather than one.
Two extras are declared mutually exclusive
Near the bottom of the packaging metadata there is a conflicts declaration listing two extras and stating that they cannot be installed together. One is named for a simulation lab and the other for an engine, and both are simulation-related, so the restriction is about two simulators that evidently cannot coexist in one environment rather than about two features being incompatible in principle. That is the kind of constraint that is usually discovered the hard way, at resolution time, so it is worth knowing before you add an extra rather than after. The same section allows prereleases, and there is a separate index configured pointing at the PyTorch nightly wheel repository, which is how the library tracks unreleased PyTorch builds.
The build needs a toolchain before anything imports
The build system requirement list is unusual for a Python library: alongside the packaging tools it names PyTorch itself, a build accelerator, a C++ toolchain, a compiler toolkit, a binding generator and NumPy. That is because the package ships compiled extensions, not just Python. The setup script imports PyTorch's extension machinery directly and builds C++ and CUDA extensions from there, and it probes for the CUDA compiler by checking the environment variable for the toolkit location and then looking for the right binary name for the platform, with the Windows executable suffix applied only on Windows. There is one piece of genuine care in it: before doing any work, the script checks whether the binding generator is installed and, if not, raises an error that names the exact install command to fix it.
The Makefile deletes compiled objects by hand
The development build file is four targets and a phony declaration listing three of them, so the combined clean-and-build target is defined without being declared. The clean target is a list of deletions rather than a catch-all: the build and distribution directories, both egg-info directories at the root and inside the package, the compiled shared objects with a wildcard, the generated version module, every byte-code cache directory found by a find command, and every compiled Python file. The build target compiles the extensions in place, and the development target installs the project in editable mode with build isolation turned off, which means every build dependency has to be present in your environment already. The test target runs the test directory verbosely with a sixty second timeout per test.
The quick demo stops in the middle of a line
The demo is the part most readers copy, and it does not finish. It builds a transformed environment from a native pendulum task with a step counter, wraps a small sequential module so the policy declares its input and output keys explicitly, and then starts the rollout call, at which point the line ends mid-word. What is visible is still the shape of the API: the environment is an ordinary object, the policy is an ordinary module with declared keys, and the rollout takes a step count and a policy. The README says explicitly that nothing in the pattern is specific to that task, and that the same keys-and-container interface is used by batched environments, multi-agent tasks, collectors, replay buffers, recurrent modules, transforms and losses.
Two packages are published and the name is rewritten at build time
There are two packages on the index, one for releases and one for nightly builds, and the manifest carries a comment next to its own name saying that the name is overridden by the setup script for nightly builds. A shell script at the root is named for building that nightly, and the setup script matches a release branch pattern before it does anything else, which is how the same source produces two artefact streams. The rest of the packaging is three files deep: a project metadata file, a setup script that does the compiling, and a configuration file that predates both. Two version artefacts sit at the root as well, a plain text version and an HTML file that a static host can serve.
Sixteen example directories, two of them about language models
The example tree is organised by what it demonstrates rather than by algorithm, and reading the directory names tells you what the maintainers consider the hard parts. There are agents, collectors, distributed training, environments, replay buffers and services, which are the infrastructure claims of the README. Then the domain-specific ones: simulation macros, an environment collection, a satellite example that the release notes also mention, a memory-mapped example, and two that stand out, one for large language model work and one for reinforcement learning from human feedback. A single script sits alongside the directories, a monitor that pairs a distributed execution framework with an experiment tracker. The release notes for the current version lead with three themes of their own: a model-based algorithm, asynchronous scale, and composable replay.
Editorial conclusion
TorchRL is worth adopting when you want reinforcement learning code that looks like PyTorch code, with one data structure carrying observations, masks, rewards and recurrent state instead of parallel arrays. Three things to know first. The tensor container is a separate package with an upper bound, so your resolver constraints are set partly by another project. The build compiles C++ and CUDA extensions, so a source install needs a toolchain and pybind11 before anything imports. And the project publishes a second, nightly package under a different name, which is where new work lands first.
Frequently asked questions
What is TorchRL?
A PyTorch-native library of composable pieces for reinforcement learning, decision making, robotics and simulation. The README is explicit that it is not one algorithm implementation or a narrow benchmark suite, but a set of modules built around a common data model.
What does the TorchRL tensor container do?
It is the dictionary-like tensor container the whole pipeline passes around, with PyTorch operations, device transfers, shared-memory support, memmaps and lazy views. Nested keys let next-state, per-agent and recurrent data live inside the batch instead of beside it. It lives in its own repository.
Which environments does TorchRL support?
Its own PyTorch-native environments including a pendulum task and custom MuJoCo tasks, plus wrappers for Gymnasium, Gym, DM Control, Brax, Jumanji, PettingZoo, VMAS, OpenSpiel, Safety-Gymnasium and Isaac Lab, with serial and parallel vectorised containers on top.
What does building TorchRL from source require?
A C++ toolchain. The build system requires the packaging tools plus PyTorch, a build accelerator, a compiler toolkit, a binding generator and NumPy, and the setup script builds C++ and CUDA extensions, raising a clear error naming the install command if the binding generator is missing.
How are the TorchRL tests run?
The Makefile test target runs the test directory with verbose output and a sixty second timeout per test, after a development build. Formatting is handled by a pre-commit configuration and type checking by a separate configuration file at the root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/pytorch-rl)Star history chart for your README
[](https://hysenlabs.com/projects/pytorch-rl)Was this useful?