Qwen-VLA puts a README and an assets folder where the model would normally be
The official repository of Qwen-VLA
At a glance
- What is it?
- An announcement repository for a unified vision-language-action model built on a Qwen3.5-4B backbone and a 1.15B flow-matching action decoder. The numbers are complete and the pretraining ablation is the strongest part of them, but there is no code, no weight, no licence file and no release tag here.
- Who is it for?
- Read this repository as a claim with a table attached, not as a release. What it offers is a specific architecture in brief, an eight-column simulation comparison between two variants of the same model, a real-robot comparison against two named specialists on ALOHA, and an ablation that isolates the pretraining stage as the source of most of the gain.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 169 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
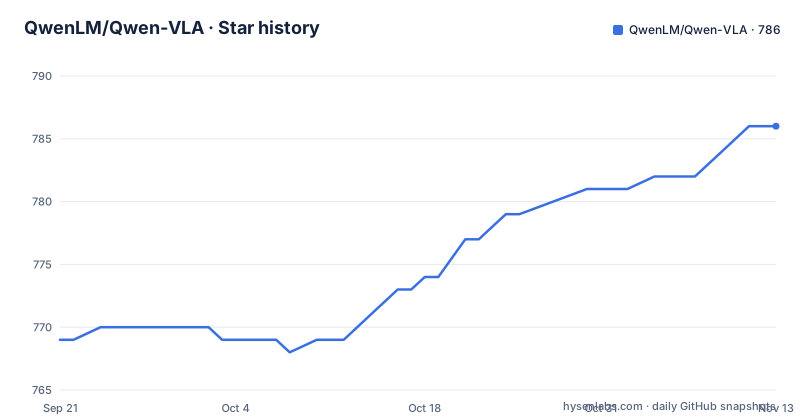
- QwenLM/Qwen-VLA786 ★ · +17
| Repository | 2026-09-21 | 2026-11-13 |
|---|---|---|
| QwenLM/Qwen-VLA | 769 | 786 |
17 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The repository is a README and an assets directory
The entire top level of this repository is two entries: a README file and an assets directory. There is no source tree, no configuration, no notebook, no licence file and no documentation beyond that one file. The platform metadata carries no language and no licence value either, which for a repository with no code is not an oversight so much as a description of what the artefact is: an announcement.
Everything the announcement points at lives elsewhere. Three links sit at the top: a technical report on arXiv under the identifier 2605.30280, a blog post on the vendor's own site, and a demo video hosted as an object in a cloud storage bucket. A fourth link is the issues tracker, introduced as the place to post questions. There are no GitHub releases, so no tag names a checkpoint, and the most recent push to the default branch was on 2026-05-29.
For a robotics model that means the practical sequence is: read the tables here, then go find the paper, then wait. Whether the weights arrive on a model hub under what licence is not something this repository answers, and the absence of a licence file is the part that matters most for anyone planning around it.
A 4B backbone and a 1.15B decoder replace per-platform output heads
The architecture is described in two sentences. Qwen-VLA is built on a Qwen3.5-4B vision-language backbone plus a 1.15B DiT flow-matching action decoder. Manipulation, navigation, egocentric action modelling and trajectory prediction are all cast into one shared action-and-trajectory prediction space rather than living in separate task-specific heads.
The consequence claimed for that choice is embodiment handling. Embodiment-aware prompt conditioning means one set of weights serves multiple robot platforms, and switching between embodiments requires changing a text prompt. No per-platform output head has to be trained, retrained or shipped, which is the practical argument: a policy that needs a new head per body is a policy that needs engineering per body.
The training recipe is described as progressive, with four stages: large-scale action pretraining, multimodal continued pretraining, supervised fine-tuning, and reinforcement learning. The stated purpose is to bridge the gap between discrete vision-language tokens and continuous action trajectories, which is the real difficulty in this family of models. A language model emits tokens; a robot arm has to emit where the gripper goes next.
Whether the flow-matching decoder is what makes one shared space workable, or whether the shared space is what makes the flow-matching decoder sufficient, is not something the document takes a position on.
The pretraining stage is what the real-robot numbers rest on
The real-robot table is the most informative part of the document, because it ablates Qwen-VLA against itself. On the ALOHA bimanual platform, four rows are reported: two per-task specialists, GR00T N1.6 and π0.5, fine-tuned independently, and Qwen-VLA-aloha with and without pretraining.
In-domain averages: 28.6 for GR00T N1.6, 71.6 for π0.5, 48.5 for Qwen-VLA-aloha without pretraining, and 83.6 with it. Out-of-distribution averages follow the same ordering at 25.4, 41.5, 36.2 and 76.9.
Put those together and the architecture argument becomes secondary. The same model, the same platform and the same evaluation move 35 points in-domain and 41 points out-of-distribution on the strength of one training stage. The gap between Qwen-VLA-aloha without pretraining and π0.5 is 23 points in-domain and 5 points out-of-distribution, meaning the fine-tuned specialist is ahead in both before pretraining and behind in both after it. Whatever the unified design contributes, it is not visible separately from the data.
That is worth stating plainly because the alternative reading is not available. There is no Qwen-VLA-aloha row trained on the ALOHA tasks from scratch without the wider embodied pretraining, and no per-task Qwen-VLA variant, so the design cannot be isolated from the recipe in this table.
One column goes to the specialist and the table marks it
The claim in the highlights is that a unified generalist matches or outperforms specialists fine-tuned independently per benchmark. The ALOHA tables mostly support that, and where they do not, the document does not hide it.
In-domain, Qwen-VLA-aloha with pretraining takes five of six columns: 96.2 on Pick and Place, 92.3 on Table Cleaning, 98.7 on Bowl Stacking, 87.2 on Bowl Pick and Place, and 61.5 on fine-grained manipulation. On Towel Folding it scores 65.4 against π0.5's 80.8, and that is the one cell in either table where the specialist's number is the bolded one. The average still favours Qwen-VLA at 83.6 to 71.6, so a single soft skill does not overturn the summary, but it is exactly the kind of column where cloth handling differs from rigid-object manipulation and where a deformable-grasp specialist would be expected to win.
Out-of-distribution, Qwen-VLA with pretraining leads every column: 88.5 on colour, 76.9 on instance, 53.8 on position, 80.8 on background and 84.6 on instruction change, against π0.5's 57.7, 61.5, 19.2, 26.9 and 42.3.
The weakest number anywhere in the document is GR00T N1.6's 3.8 on position out-of-distribution, which is the kind of figure that normally gets left out of a comparison table.
The simulation table compares two variants of one model and no specialist
The manipulation and navigation table has eight columns and two rows, and both rows are Qwen-VLA. The base variant scores 90.8 on LIBERO, 40.4 on RoboCasa-GR1, 64.3 on Simpler-WidowX, 64.3 on RoboTwin-Easy, 66.4 on RoboTwin-Hard, 61.7 on R2R OS, 53.8 on R2R SR and 55.1 on RxR SR. The instruct variant scores 97.9, 56.7, 73.7, 86.1, 87.2, 69.0, 57.5 and 59.6 on the same eight.
The instruct variant is higher in every column, and the largest movements are on the RoboTwin pair, where Easy goes from 64.3 to 86.1 and Hard from 66.4 to 87.2. The two navigation columns move least, which fits the stated framing that manipulation and navigation are handled jointly rather than as separate skills.
What the table does not contain is any specialist baseline. The claim about matching or outperforming per-benchmark specialists is not demonstrated anywhere in the simulation results; it is demonstrated once, on ALOHA, in the real-world section. So the largest table in the document establishes an internal comparison between two checkpoints of the same model, and the external comparison lives in a table with five columns and six rows.
The out-of-distribution table follows the same shape: base at 25.3, 21.1 and 37.4, instruct at 32.0, 26.6 and 39.5, with no third-party row.
Out-of-distribution means two different things in two rows
Two out-of-distribution results are reported and the footnotes define them differently, which is worth keeping straight.
SimplerEnv-OOD is fine-tuned solely on simple pick-and-place and then evaluated on unseen spatial and visual tasks. The shift is within a task family the model was trained on, testing whether it generalises across object poses and appearances rather than across skills.
DOMINO is a zero-shot evaluation on dynamic manipulation with moving objects, using no dynamic training data. The shift is across task families: the model has never seen the dynamics it is being asked to handle.
Those are different claims and the numbers are not comparable with each other. SimplerEnv reports one metric, a success rate of 32.0 for the instruct variant. DOMINO reports two, a success rate of 26.6 and a metric labelled MS at 39.5, and what MS stands for is not written down in the file.
A reader comparing 32.0 against 39.5 would be comparing two different definitions of success on two different kinds of shift. The document is careful to footnote both conditions, which is more than most results sections do, and it does not gloss the zero-shot condition for DOMINO.
The citation block stops partway through the author list
The last section asks readers to cite the work and supplies a BibTeX entry. The entry opens with a `@misc` key, carries the full paper title, and then runs through a long list of authors that stops mid-name, at an initial letter, and never closes the record. There is no year field, no closing brace, no arXiv identifier inside the entry.
So the citation cannot be copied out of this file. Copying it yields a BibTeX record that will not compile, and anyone who needs a working reference has to go to the arXiv entry or the blog post for the author list and the date.
The licence situation is the same shape. There is no licence file in the repository and no licence value in the platform metadata. For a project that publishes no code here that is defensible, but for the model itself it leaves the terms unstated, and the technical report linked at the top is where a reader would have to look for them.
Both gaps point the same way. This repository is a signpost, and it is a signpost with two missing signposts at the end of it.
Editorial conclusion
Read this repository as a claim with a table attached, not as a release. What it offers is a specific architecture in brief, an eight-column simulation comparison between two variants of the same model, a real-robot comparison against two named specialists on ALOHA, and an ablation that isolates the pretraining stage as the source of most of the gain. What it does not offer is anything you can run: no weights, no code, no licence, no checkpoint names, and a citation block that stops partway through its author list. Anyone planning to build on Qwen-VLA has to resolve two questions this repository cannot answer: where the weights will be published and under what terms. The technical report and the blog post linked at the top are where those answers would have to come from, and the blog link is the more likely of the two to have them.
Frequently asked questions
What is Qwen-VLA?
A unified vision-language-action generalist model built on a Qwen3.5-4B vision-language backbone and a 1.15B DiT flow-matching action decoder. It casts manipulation, navigation, egocentric action modelling and trajectory prediction into one shared prediction space, with no per-platform output heads, and is trained with a progressive recipe covering action pretraining, multimodal continued pretraining, supervised fine-tuning and reinforcement learning.
Is the Qwen-VLA code or model weights available in this repository?
No. The repository contains a README file and an assets directory, with links to a technical report, a blog post and a demo video hosted elsewhere. There are no releases, no tags, and no install instructions, and the most recent push to the default branch was on 2026-05-29.
Which benchmarks does Qwen-VLA report results on?
For manipulation and navigation: LIBERO, RoboCasa-GR1, Simpler-WidowX, RoboTwin Easy and Hard, and the R2R and RxR navigation suites. For out-of-distribution: SimplerEnv-OOD and DOMINO. For real robots: ALOHA bimanual tasks in-domain and out-of-distribution, compared against GR00T N1.6 and π0.5 as per-task specialists.
How does Qwen-VLA support different robot embodiments?
Through embodiment-aware prompt conditioning. One set of weights serves multiple platforms, and switching embodiments requires only changing a text prompt, with no per-platform output head to train. The document does not say which embodiments are supported or how many.
What licence was Qwen-VLA released under?
The repository does not say. There is no licence file at the top level and the platform metadata carries no licence value. The document links to a technical report and a blog post instead, which is where the terms would have to be found.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen-vla)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen-vla)Was this useful?