Qwen3.8-Flash-Next ships 125B parameters so you can read the Qwen4 design
Qwen3.8-Flash-Next is the foundation model developed by Qwen Team, Alibaba Group.
At a glance
- What is it?
- Qwen3.8-Flash-Next is an open-weight multimodal MoE model from the Qwen Team at Alibaba, published as an early look at the architecture Qwen4 will be built on. It activates 6B parameters per token out of a 125B main model plus a 51B n-gram embedding table, and the page says training cost about one ninth of Qwen3.7-Plus.
- Who is it for?
- Take this checkpoint if you want to read the Gated DeltaNet, Qwen Sparse Attention and Gated Residual design before it hardens into Qwen4, or if you want a single model that runs through transformers serve, SGLang, llama.cpp, mlx-vlm and Unsloth. Skip it if you need a stable production model with a named license and tagged releases, because this repository has neither.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 79 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
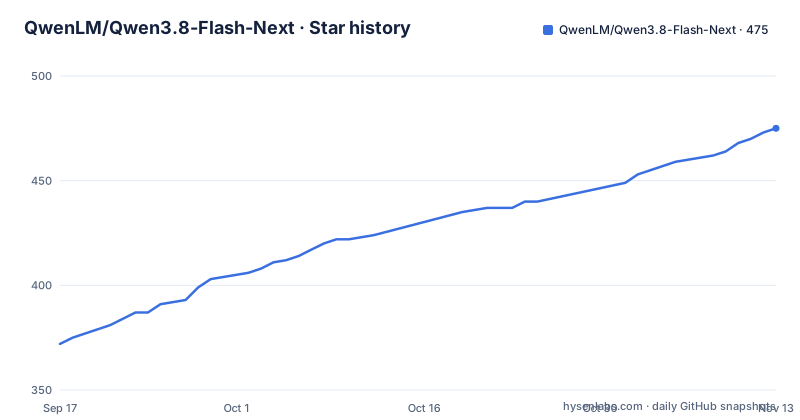
- QwenLM/Qwen3.8-Flash-Next475 ★ · +103
| Repository | 2026-09-17 | 2026-11-13 |
|---|---|---|
| QwenLM/Qwen3.8-Flash-Next | 372 | 475 |
103 Stars in the last 57 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The weights are open because the architecture is the announcement
The stated reason for publishing Qwen3.8-Flash-Next is not capability, it is disclosure. The release opens the weights of a multimodal MoE model that also serves as an early preview of the architecture used in Qwen4, and the README says outright that the architectural changes are being released early so the community can examine them before the full Qwen4 family is built on top of them.
This is a repeated move for the team rather than a one-off. Qwen3.8-Flash-Next plays the same role that Qwen3-Next played for Qwen3.5. The hybrid Gated DeltaNet plus Gated Attention design introduced at that point has since been used across the Qwen3.5, Qwen3.6, Qwen3.7 and Qwen3.8 series, so the preview is not a sketch. It is a design that already survived four generations of shipping before anyone was asked to read it.
The repository matches that framing. The entire tree is two files, README.md and tech_report.pdf. There are no tagged releases on the repository, and the page names no license. What you are downloading is a research artifact with a paper attached, not a versioned product with a changelog.
The News section carries one entry: 2026-08-26, the release date, with a pointer to the qwen.ai blog post. Benchmarks are delegated to that blog rather than printed here, so the page carries architecture claims and no scores.
Gated DeltaNet compresses history, Qwen Sparse Attention picks what survives
Attention is the first of four changes, and it is a hybrid of two mechanisms rather than a replacement. Gated DeltaNet compresses the history efficiently, which is the linear-recurrent half of the design and the part that keeps long context from costing attention over every previous token.
Qwen Sparse Attention, abbreviated QSA, is the other half. It uses a compressed lightweight indexer to select the important context at micro-block granularity, and the claimed effect is a substantial reduction in the cost of attention on long sequences. The two halves solve different problems: one decides how history is carried forward cheaply, the other decides which blocks of that history are worth spending full attention on now.
Micro-block granularity is the detail that matters for anyone sizing hardware. Selecting at the level of whole tokens would make the indexer's own bookkeeping comparable to the attention it saves. Selecting at block granularity is what lets the index stay small enough to be cheap, which is presumably why the design uses a compressed indexer rather than exact scoring over the whole context. The page does not publish a speedup figure for either mechanism, so the practical test is your own context length.
Both mechanisms belong to the same lineage. The Gated DeltaNet plus Gated Attention hybrid was introduced with Qwen3-Next and has since been carried through the Qwen3.5, Qwen3.6, Qwen3.7 and Qwen3.8 series, so this is the fourth model built on it rather than the first.
The residual stream widens into four branches behind a dynamic gate
The residual change is called Gated Residual, or GR, and it is the one with the most architectural consequence for anyone writing their own training loop. The residual stream widens into four branches, and a dynamic gate controls reads and writes. The stated purpose is stronger cross-layer information flow and better training stability.
Four branches is a structural claim, not a hyperparameter. A conventional residual stream is a single wide vector passed from layer to layer; widening it into four parallel paths gives the network four distinct routes for a representation to take, and the gate decides per token and per layer which routes are written to and which are read from. Whether that helps or hurts a given workload is not something the page answers, because no ablation is printed.
The pairing of this change with the attention hybrid is worth noting. Gated DeltaNet and Qwen Sparse Attention both operate on the sequence axis, deciding what flows forward, while Gated Residual operates on the layer axis, deciding how depth is used. A model that changes both at once makes it harder to attribute a behaviour change to either, which is one reason the paper exists alongside the weights.
So is the fact that the scaling law was refitted for the new architecture, which the README mentions under optimization. A refitted law is a claim that the old parameter-to-capability relationship no longer holds, and it is another piece of evidence that this is a new architecture wearing a familiar name.
51B of the parameters are an n-gram table that can sit in host memory
The parameter budget is split in a way that has direct consequences for deployment. Qwen3.8-Flash-Next has a 125B-parameter main model, supplemented by an additional 51B in N-gram embeddings, with 6B parameters activated per token. So roughly 176B parameters ship, and 6B are touched for any given token.
N-gram Embedding works by looking up a table using the local context, which scales model capacity with very little extra computation. That is the trick behind the extra 51B: instead of growing the transformer, grow a table keyed on recent context.
The part that matters operationally is what comes next. The embedding table can be offloaded to host memory and overlapped with model computation through asynchronous prefetching. On a machine where 176B parameters do not fit in device memory, this is what makes the model loadable at all: the largest single structure does not have to be resident on the accelerator, and its fetches are hidden behind the matmuls already in flight.
Six billion active parameters per token is also the number to hold on to when reading any claim about speed. The sparse routing means the compute per token is set by the active parameters, not the total, and 6B is a size that fits the kind of consumer and workstation hardware the README's local runtime section targets.
The cost claim is one ninth of Qwen3.7-Plus, and the numbers live in the blog
One comparison is made against a named model, and it is the only one on the page. Compared with Qwen3.7-Plus, Qwen3.8-Flash-Next substantially reduces both training and inference cost, with training taking only about 1/9 as much, and the README pairs that with a claim of superior capabilities in coding and office tasks. Nothing else is compared, and no third-party model is mentioned.
The optimizer behind that figure is the Muon optimizer, used for training and refined around three specific points: orthogonalization accuracy, the division of labour between Muon and AdamW, and the splitting of fused parameters. The scaling law was refitted for the new architecture as part of the same work. Those three refinements are where a reproduction attempt should look first, because a Muon implementation with different orthogonalization behaviour is not the same trainer.
No benchmark table appears here. Evaluation results are reported in the Qwen3.8-Flash-Next blog on qwen.ai, and the repository's second file, tech_report.pdf, is the other candidate. The coding and office task claim is therefore not checkable from this page alone, and the "about" in 1/9 suggests the authors are not claiming an exact multiple.
For context on the repository itself: it is not archived, and the last push was on 2026-08-27, one day after the 2026-08-26 release date in the News section.
Two hubs and four local runtimes, each asking for different files
Weights come from one of two places, and the choice is made by network access rather than preference. The Hugging Face Hub carries the model under the ID `Qwen/Qwen3.8-Flash-Next`, and most frameworks will fetch it automatically by that ID. For users who cannot reach the Hub, the README recommends ModelScope, with `modelscope download` or `git clone` as the manual routes. Supported frameworks can be pointed at ModelScope with environment variables: `SGLANG_USE_MODELSCOPE=true` or `VLLM_USE_MODELSCOPE=true`.
Four local runtimes are named, and each needs a different artifact. transformers is the model-definition framework and now ships serving, so the shortest path to an API is one command, with continuous batching and the OpenAI-compatible endpoint on port 8000:
transformers serve Qwen/Qwen3.8-Flash-Next --port 8000 --continuous-batchingllama.cpp supports the model for text and vision, but you look for files ending in GGUF on the Hub, so the runnable form is a converted quantization rather than the original checkpoint. On Apple Silicon, mlx-vlm covers vision and text; the original checkpoints are compatible and can be converted, and ready-to-use quantized versions exist with names ending in MLX. Unsloth provides a local UI to run and train the model, with a guide for its quants.
The pattern across all four is the same. The official checkpoint is what the Hub serves; every convenient local runtime wants a derivative of it.
The deployment section ends mid-sentence after the SGLang command
The last section of the page is Deployment, and it promises more than it delivers. It says Qwen3.8-Flash-Next is supported by multiple inference frameworks and names three: SGLang, vLLM, and TokenSpeed. Only SGLang is shown before the page cuts off, immediately after the line promising an OpenAI-compatible API.
The SGLang invocation is the most demanding configuration on the page and the only place the hardware requirement becomes concrete. It spreads the model over four devices, asks for a 262144 token context length, and names the parsers that let an OpenAI-shaped client understand Qwen reasoning output and tool calls:
sglang serve --model-path Qwen/Qwen3.8-Flash-Next --port 8000 --tp-size 4 --context-length 262144 --reasoning-parser qwen3 --tool-call-parser qwen3_coder`--tp-size 4` is tensor parallelism across four GPUs, and `--context-length 262144` is a quarter of a million tokens. Together they are a demonstration of the model's ceiling rather than a starting configuration, and nothing on the page tells you what to lower them to.
What vLLM and TokenSpeed are configured with is not shown. For vLLM the page has already given you the switch that redirects its downloads to ModelScope, which implies it is one of the supported frameworks, but the serve command is not there to copy. The hosted options are a separate matter: QwenCloud claims first-class support with OpenAI and Anthropic compatible specifications, QwenWork runs it as the new Standard mode, and Qwen Code is an open-source agent in the terminal built around Qwen models.
Editorial conclusion
Take this checkpoint if you want to read the Gated DeltaNet, Qwen Sparse Attention and Gated Residual design before it hardens into Qwen4, or if you want a single model that runs through transformers serve, SGLang, llama.cpp, mlx-vlm and Unsloth. Skip it if you need a stable production model with a named license and tagged releases, because this repository has neither. Before downloading 51B parameters of embedding table plus 125B of main model, check what --context-length 262144 costs on the tensor parallelism you actually have.
Frequently asked questions
How many parameters does Qwen3.8-Flash-Next activate per token?
6B per token, out of a 125B-parameter main model plus an additional 51B of N-gram embeddings. The main model is a mixture of experts, so the active count, not the shipped total, sets the compute per token.
How do I download the Qwen3.8-Flash-Next weights?
From the Hugging Face Hub under the model ID Qwen/Qwen3.8-Flash-Next, either automatically by ID or with huggingface download or git clone. If you cannot reach the Hub, the README recommends ModelScope, and supported frameworks can be pointed at it with SGLANG_USE_MODELSCOPE=true or VLLM_USE_MODELSCOPE=true.
Can I run Qwen3.8-Flash-Next on an Apple Silicon Mac?
mlx-vlm supports it for vision and text on Apple Silicon. The original checkpoints are compatible and can be converted, and ready-to-use quantized versions are on the Hugging Face Hub with names ending in MLX.
Where are the benchmark numbers for Qwen3.8-Flash-Next?
Not on this page. Evaluation results are reported in the Qwen3.8-Flash-Next blog on qwen.ai, and the repository carries a tech_report.pdf next to the README. The page itself states only that coding and office capability is superior to Qwen3.7-Plus.
How do I serve Qwen3.8-Flash-Next behind an OpenAI-compatible API?
The transformers path is a single command with continuous batching, and the API is served at http://localhost:8000/v1. For more control the page shows an SGLang command with tensor parallelism of 4, a context length of 262144, and the qwen3 reasoning and qwen3_coder tool call parsers.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-8-flash-next)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-8-flash-next)Was this useful?