Qwen3-Coder needs a new tokenizer for tool calling, and its requirement list pins nothing
Qwen3-Coder is the code version of Qwen3, the large language model series developed by Qwen team.
At a glance
- What is it?
- Qwen3-Coder is the coding line of the Qwen family, announced in three sizes including one built for local development and coding agents. Two details on the page decide whether it works at all for that use: the special tokens and their identifiers were changed for consistency with the base series, so the new tokenizer must be used, and the tool parser the readme says is required lives in specific inference engines rather than in the model. The repository itself holds no licence file, no code at the top level, and a five-line requirement list with nothing pinned.
- Who is it for?
- Qwen3-Coder fits a team that wants an open-weight coding model to drive an existing agent harness, with local weights rather than an API, and that is prepared to track the hosting organisation's checkpoints as they are republished. It does not fit anyone hoping for a licence in the repository to tell them what they may do with the weights, because there is none, and it does not fit a deployment whose serving stack is already fixed to an engine the readme does not name.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
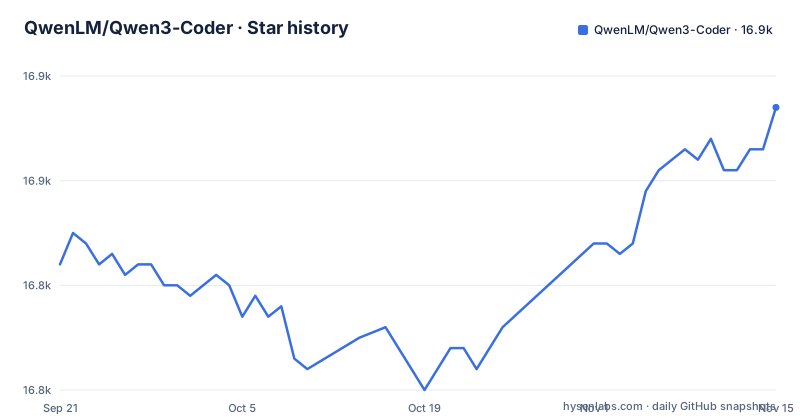
Star history
- QwenLM/Qwen3-Coder16,857 ★ · +15
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| QwenLM/Qwen3-Coder | 16.8k | 16.9k |
15 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Tool calling breaks silently on an old tokenizer
There is an important callout on the page, and it is the operationally decisive part. It states that the function calling relies on a new tool parser present in two named inference engines, and that both the special tokens and their corresponding identifiers were updated in order to keep consistency with the base series, ending with an instruction to make sure the new tokenizer is used. Consequence: tool calling depends on using the updated tokenizer, not one you already had.
The tool parser lives in the serving stack, not in the weights
The same callout names the two engines that carry the parser. Consequence: whether function calling works is a property of your inference server as much as of the model, and it depends on a feature in a specific project's build rather than on anything the checkpoint contains. That inverts the usual upgrade question: you are not just choosing a model version, you are choosing a serving stack that happens to implement a particular wire format.
The requirement file names five packages and pins none of them
The requirements list is five bare names: a tensor library, a transformers library, an accelerator library, a safe-tensor library and a serving engine. Consequence: nothing is pinned, including the serving engine whose parser the readme calls required. Two people setting up on different days get different stacks, and the feature the model depends on may or may not be present in whichever version resolved. For a repository whose entire integration story is a parser inside one of those packages, an unpinned requirement list is the one file where it does the most damage, and it is five lines long.
Three sizes are announced and the repository belongs to one of them
The announcement names three checkpoints, two instruction-tuned models at very different sizes and one described as an open-weight model designed for coding agents and local development, built on a base with a hybrid attention and mixture-of-experts architecture. Consequence: the third is a different product from the other two and it is the one the repository is organised around. What the top level holds is a technical report as a PDF, a demo directory, an evaluation directory, a finetuning directory and a requirements file. Someone arriving for the smaller instruction-tuned checkpoint finds a repository whose contents describe a different model, with no code and no changelog to orient them.
One context length is native and the larger one is an extension
The features section claims native support for 256 thousand tokens and says the figure can be extended up to a million using a context-extension technique. Consequence: the million-token number is not what the model natively handles. It is produced with Yarn, and the readme states it in a subordinate clause rather than in the headline. The basic information section then repeats only the native figure, which is the number to plan against. A repository-scale task that genuinely needs the longer window is relying on the extension.
The function call format is described as specially designed
The same feature list says the models support the main agent platforms and that they feature a specially designed function call format. Consequence: combined with the tool parser note, the serving side needs the matching parser, while the readme names Qwen Code, CLINE and Claude Code among the platforms it supports.
The 358-language claim is demonstrated by a list that stops mid-alphabet
The basic information says the models support 358 coding languages, and the demonstration is a collapsible block containing a literal list of language names.
No licence, no code, and no way to tell a stale checkout from a current one
The top level of the repository holds a readme, a gitignore, a technical report, an assets directory, a demo, examples, a finetuning directory, an evaluation directory and the requirements file. There is no licence file, no contributing guide, no code of conduct and no code at the top level, and the repository publishes no releases. Consequence: this is a pointer to model hubs rather than a piece of software, so an upgrade means pulling a different checkpoint rather than installing a version, and the readme tells you to search the hosting organisation for checkpoints whose names begin with a given prefix. With no licence file, check the model pages for what the weights may be used for, which is a different question from whether they can be downloaded.
Editorial conclusion
Qwen3-Coder fits a team that wants an open-weight coding model to drive an existing agent harness, with local weights rather than an API, and that is prepared to track the hosting organisation's checkpoints as they are republished. It does not fit anyone hoping for a licence in the repository to tell them what they may do with the weights, because there is none, and it does not fit a deployment whose serving stack is already fixed to an engine the readme does not name. Before deploying, install the tokenizer that ships with the checkpoint rather than one you already had, confirm your inference engine carries the required tool parser, and expect to pick a precision variant yourself rather than having one chosen for you.
Frequently asked questions
Is the Qwen3-Coder free to use?
The models are described as open-weight and are downloadable from Hugging Face and ModelScope, and there is a hosted chat as well as a browser demo. The repository itself contains no licence file, so what you may do with the weights is not settled by anything in the code repository so check the licence terms on the model pages.
How much does Qwen3-Coder cost?
The readme emphasises inference cost rather than price, describing the model intended for local development as obtaining strong coding and agentic capabilities with significantly lower inference costs, which is a per-token statement about the model rather than a price list. Running it locally costs whatever hardware you already have.
Can I run Qwen code locally?
Yes, that is what the model intended for coding agents and local development is described as being designed for, and the requirement list is short because it names a tensor library, a transformers library, an accelerator library, a safe-tensor library and a serving engine. The readme also points at a separate command-line project and at two third-party agent platforms that the model supports.
how to install qwen3 coder
There is no package to install from this repository. The readme tells you to search the model hosting organisation, or its regional mirror, for checkpoints whose names begin with a given prefix, and its table lists variants, including instruction-tuned and base forms, a quantised eight-bit form and a quantised GGUF form, all with the same native context length.
Is Qwen 3 good at coding?
The readme positions the series as agentic rather than merely competent at code, describing it as the most agentic code model to date and claiming results comparable to a named commercial model among open models on agentic coding and browser-use tasks. It also says the models retain their strengths in mathematics and general capability from the base model.
how to install qwen3 coder in ollama
The repository has no Ollama packaging at the top level. It publishes a GGUF variant alongside the others, which is the format such runners typically consume, and it points at two named agent platforms it says the model supports.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-coder)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-coder)Was this useful?