Qwen3-TTS: five 12Hz checkpoints, and only two of them take instructions
Project brief: Qwen3-TTS is an open-source series of TTS models developed by the Qwen team at Alibaba Cloud, supporting stable, expressive, and streaming speech generation, free-form voice design, and vivid voice cloning.
At a glance
- What is it?
- Qwen3-TTS is Qwen's Apache-2.0 speech generation family: five 12Hz checkpoints that differ in size, in whether they accept style instructions, and in whether they can be fine tuned. The model table is the whole decision, and the streaming latency number is thinner than it looks.
- Who is it for?
- Qwen3-TTS fits teams that need local streaming speech, a three second cloning path, or instruction driven voice design, and the 0.6B and 1.7B split is a real size choice. It is a poor fit if you need per dialect guarantees, or style control on the smaller custom voice checkpoint, and it is not a ComfyUI drop in.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
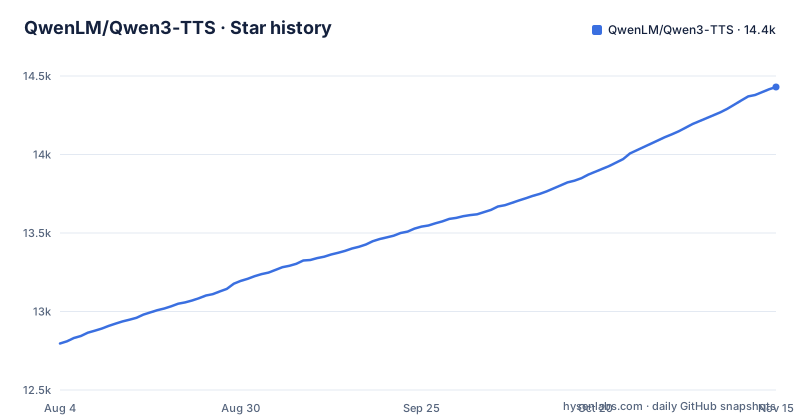
- QwenLM/Qwen3-TTS14,430 ★ · +1,634
| Repository | 2026-08-04 | 2026-11-15 |
|---|---|---|
| QwenLM/Qwen3-TTS | 12.8k | 14.4k |
1,634 Stars in the last 103 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Five 12Hz checkpoints, and only two of them take instructions
The release is five checkpoints, and they are not interchangeable. Qwen3-TTS-12Hz-1.7B-VoiceDesign turns a text description into a voice. Qwen3-TTS-12Hz-1.7B-CustomVoice holds nine premium timbres and takes an instruction to steer style across them. Qwen3-TTS-12Hz-0.6B-CustomVoice has the same nine timbres but an empty Instruction Control cell, and the two Base checkpoints, 1.7B and 0.6B, leave style and instruction control blank altogether. Every row lists the same ten languages, so language is not a way to choose between them. For a reader, the split matters more than the parameter counts: picking the 0.6B for speed and expecting the prompt driven behaviour of the 1.7B CustomVoice runs into an empty Instruction Control cell. There is also no GitHub release to pin, so a version lock has to name a Hugging Face or ModelScope model id rather than a tag.
Cloning starts at three seconds, and the sample rate is unstated
The Base checkpoints describe 3-second rapid voice clone from user audio, and that sentence is the entire statement of what the input may be. The Base rows also carry an empty Instruction Control cell. The documented way out is fine tuning, because Base is the pair marked as usable for fine tuning other models.
transformers==4.57.3 turns the install into a resolver problem
Packaging is where friction appears first. The distribution is qwen-tts at version 0.1.1, it requires Python 3.9 or newer, and the classifiers run through 3.13. Two dependencies are pinned by exact version, transformers==4.57.3 and accelerate==1.12.0, while gradio, librosa, torchaudio, soundfile, sox, onnxruntime, and einops are left open. A machine that already carries transformers for another model has to downgrade or refuse, and librosa, torchaudio, soundfile, sox, and onnxruntime each pull their own native pieces, so a clean virtual environment is the low risk path. One console script is registered, qwen-tts-demo mapped to qwen_tts.cli.demo:main, and the top level finetuning/ directory sits outside the qwen_tts package with no entry point, so fine tuning is not reachable from an installed command. The last push to main is dated 2026-03-17, and the version in that tree is 0.1.1.
Weights download at first model load, so there is no offline install
Weights are fetched when a model loads, not when the package installs. Loading through the qwen-tts package or through vLLM pulls the weights automatically based on the model name, so the first inference call needs network access and a writable disk. When the runtime is not conducive to downloading during execution, the documented path moves the files into a local directory with ModelScope.
# Download through ModelScope (recommended for users in Mainland China)
pip install -U modelscope
modelscope download --model Qwen/Qwen3-TTS-Tokenizer-12Hz  --local_dir ./Qwen3-TTS-Tokenizer-12Hz
modelscope download --model Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice --local_dir ./Qwen3-TTS-12Hz-1.7B-CustomVoice
The tokenizer is a separate download from any checkpoint, so even a minimal clone setup carries two model directories.
The 97ms figure names no hardware and no latency boundary
The stated end to end synthesis latency is as low as 97ms, and it is easy to read more into it than the text supports. The streaming design is a Dual Track hybrid architecture where a single model serves both streaming and non streaming generation, and the claim is that the first audio packet arrives after a single character is input. The overview attaches no hardware to the number.
Ten languages, but the timbres and the dialects are never enumerated
Coverage is stated as ten major languages, Chinese, English, Japanese, Korean, German, French, Russian, Portuguese, Spanish, and Italian, plus multiple dialectal voice profiles, and the same ten appear in every row of the model table. The nine premium timbres in the CustomVoice checkpoints are described only as combinations of gender, age, language, and dialect, so the set of voices you can select out of the box is nine timbres rather than one per language or per dialect. The notes also claim markedly improved handling of noisy input text.
Design then clone is documented but has no example script
The Python usage is split into four flows, Custom Voice Generation, Voice Design, Voice Clone, and Voice Design then Clone, with tokenizer encode and decode sitting beside them as a separate path. The combined flow is the one with nothing behind it. The examples directory holds four files, test_model_12hz_base.py, test_model_12hz_custom_voice.py, test_model_12hz_voice_design.py, and test_tokenizer_12hz.py, and none of them covers describing a voice and then cloning it, so that path has to be assembled from the two single step examples. Running locally means the Python package or the vLLM route named in the table of contents, while a hosted DashScope API path is there for people who would rather not hold the weights at all, which is the only option in these docs that is a service instead of code in the repository.
Editorial conclusion
Qwen3-TTS fits teams that need local streaming speech, a three second cloning path, or instruction driven voice design, and the 0.6B and 1.7B split is a real size choice. It is a poor fit if you need per dialect guarantees, or style control on the smaller custom voice checkpoint, and it is not a ComfyUI drop in. Before committing, check that your environment can take the transformers==4.57.3 and accelerate==1.12.0 pins, that the machine can serve weights through a load time download, and that the language and dialect you care about sit inside the nine timbres or are reachable by fine tuning from a Base checkpoint.
Frequently asked questions
What is Qwen3 TTS?
A series of speech generation models from the Qwen team at Alibaba Cloud, released on 2026.1.22 in 0.6B and 1.7B sizes, built on the Qwen3-TTS-Tokenizer-12Hz codec and covering voice clone, voice design, and style control across ten languages.
Is Qwen3 TTS open source?
Yes. The repository is Apache-2.0, the primary language is Python, and the code ships as the qwen-tts package at version 0.1.1 requiring Python 3.9 or newer.
Is Qwen3 TTS free?
The repository is Apache-2.0 and the weights are hosted on Hugging Face and ModelScope. Inference cost is yours, either in your own hardware or on the hosted DashScope API if you take that route instead.
how to install qwen3 tts locally
The distribution is qwen-tts 0.1.1 on Python 3.9 or newer and it pins transformers==4.57.3 and accelerate==1.12.0. The README has an Environment Setup section, and for manual weight download it gives pip install -U modelscope.
how to use qwen3 tts locally
Choose one of the five 12Hz checkpoints, load it through the qwen-tts package or vLLM so the weights download on first use, and drive it from Python. The package registers qwen-tts-demo as its single console script, and four example scripts sit under examples/.
how to install qwen3 tts in comfyui
Nothing in the repository targets ComfyUI. The top level entries are .github/, .gitignore, LICENSE, MANIFEST.in, README.md, assets/, examples/, finetuning/, pyproject.toml, and qwen_tts/, so a ComfyUI install means running the package yourself behind a custom node that you write.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- Local speech with llamadart: giving Llama Village a voicedev.to · Oct 14, 2026 · 30 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/qwenlm-qwen3-tts)Star history chart for your README
[](https://hysenlabs.com/projects/qwenlm-qwen3-tts)Was this useful?