Object-Detection-Metrics solves the XML conversion problem and points at its own successor
Most popular metrics used to evaluate object detection algorithms.
At a glance
- What is it?
- A Python library that computes the PASCAL VOC detection metrics from plain bounding box arrays instead of the XML files the official Matlab script insists on. Its own README tells you a newer version exists that covers all COCO metrics, other file formats, a user interface and a video metric.
- Who is it for?
- Use this library when your detector already hands you bounding boxes and you want VOC precision-recall and average precision numbers without writing a conversion layer, because that is precisely the gap it was built to close. Do not pick it for COCO work, for video, or for anything expecting a graphical tool, since the project itself routes all three elsewhere.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
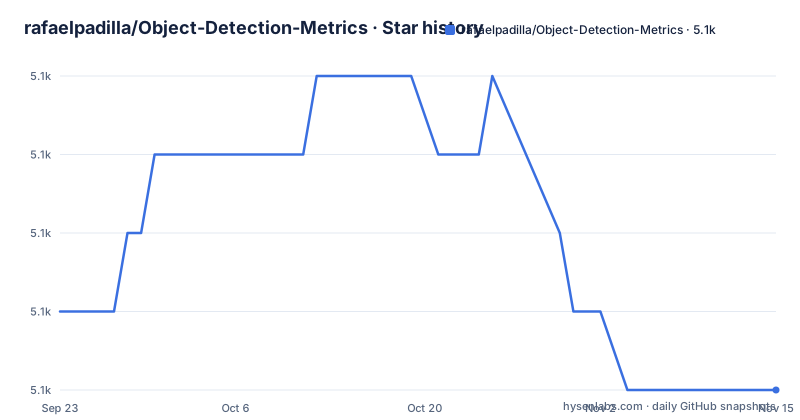
Star history
- rafaelpadilla/Object-Detection-Metrics5,101 ★ · -1
| Repository | 2026-09-23 | 2026-11-15 |
|---|---|---|
| rafaelpadilla/Object-Detection-Metrics | 5.1k | 5.1k |
-1 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Plain bounding boxes in, VOC numbers out, no XML conversion
The problem this project names is not a missing metric but a missing agreement. Different papers and different implementations pick different definitions of detection accuracy, and online competitions each keep their own. When you want to evaluate on a dataset that is not the competition's own, the documented advice is to implement the metrics yourself, and a wrong or different implementation produces different and biased results. The fix chosen here is to make the input boring: ground truth bounding boxes and detected bounding boxes, with no changes to your detection model and no converting to XML or JSON. The official PASCAL VOC evaluator wants XML files and code changes before it will read anything else, so the practical audience is anyone who already has arrays and does not want a conversion script in the middle of an experiment. The project claims its implementations were carefully compared against the official ones and return exactly the same results, which is the property that makes such a library worth trusting over another homegrown version.
Each competition ships an evaluator with its own input contract
Reading the competition list explains why a neutral library exists at all. PASCAL VOC offers a Matlab script and uses the precision x recall curve and average precision as its metrics, but that script reads ground truth boxes from XML files, so applying it to another dataset means editing the code. Projects that already implement the VOC metrics still impose their own format: Faster-RCNN expects detected boxes converted into the shape it uses, and the Tensorflow framework carries its own VOC evaluation implementation. COCO takes a different approach again, documenting 12 metrics for characterizing a detector and providing Python and Matlab code to check scores before submission, with results still having to be converted into the format the competition requires. The Google Open Images Dataset V4 Competition uses mean average precision over 500 classes. The ImageNet Object Localization Challenge is the outlier: it defines an error per image from the class and the overlapping region, and totals it as the average of the minimum errors across the test images. Picking a metric without picking an evaluator is where the disagreement starts.
The README opens by telling you to use a different repository
The first content in this README is a warning, and it is worth reading before anything else. A newer version of the tool is available at another repository, and the differences named there are specific: the new version includes all COCO metrics, supports other file formats, provides a user interface to guide the evaluation process, and presents the STT-AP metric for evaluating object detection in videos. That list covers every direction in which this repository is thin. Here the documented metrics are the PASCAL VOC ones, organized as a precision x recall curve, average precision, 11-point interpolation, and interpolation over all points. There is no GUI to speak of and no video metric. So the honest framing is that this is a focused, small library for one metric family, and its author has already pointed you elsewhere if your problem is broader. Publishing that notice at the top instead of hiding it in a release note is unusual and saves anyone from building on the narrower tool when the successor covers their case.
Dependencies are pinned to versions from 2018 and 2019
There is no packaging metadata to rely on here, so the dependency list is the requirements file and it is pinned exactly:
certifi==2026.10.19
cycler==0.10.0
kiwisolver==1.1.0
matplotlib==3.1.3
numpy==1.22.0
pyparsing==2.4.6
PyQt5==5.12.3
PyQt5-sip==4.19.18
PyQtWebEngine==5.12.1
python-dateutil==2.8.1
six==1.14.0
tornado==6.5.9
opencv-python==4.8.1.78
Most pins are old, though certifi==2026.10.19, tornado==6.5.9 and opencv-python==4.8.1.78 are newer. matplotlib is there to draw the curve, numpy does the arithmetic on the boxes, and opencv-python handles image work, but the Qt bindings at 5.12.x and six at 1.14.0 belong to a period when those were routine installs. That is the practical risk to weigh before you start: the library itself is small, yet satisfying this list on a current interpreter may require older wheels or unpinned upgrades, and any change you make to these versions is a change to a set the author verified. Treat the pins as a record of what was tested rather than as a specification you must reproduce, and expect to loosen them in a virtual environment of your own.
Sample data sits in parallel ground truth and detection folders
The top-level layout shows how a run is organized, and the folder names are the documentation:
.github/   .gitignore   LICENSE   README.md   _init_paths.py   aux_images/
detections/   detections_rel/   groundtruths/   groundtruths_rel/   lib/
message.txt   paper_survey_on_performance_metrics_for_object_detection_algorithms.pdf
pascalvoc.py   requirements.txt   results/   samples/
There are two sample runs, samples/sample_1 and samples/sample_2, and each appears to need ground truth boxes, detected boxes, relative-coordinate variants of both, auxiliary images, and somewhere to write results. Four parallel data directories rather than one suggests the library distinguishes absolute from relative box formats internally, which matters because the competitions differ on that point and this is exactly the kind of detail that produces a mismatched score. lib holds the library code and pascalvoc.py the entry point you run.
No release since 2019, though commits arrived in 2026
Version history and commit history have drifted apart. The two releases are v0.1 in June 2018 and v0.2 in January 2019, and the last push to the master branch was on 25 October 2026, so work has continued without new tags. That gap is the honest maintenance picture: nothing here is archived, but there is also no packaged artifact to install, so you are working against a branch. The research around the code is more current than the tags. The project asks that you cite a comparative analysis of object detection metrics published in Electronics in 2021, volume 10, number 3, article 279, with a DOI of 10.3390/electronics10030279, and a survey on performance metrics for object detection presented at the 2020 IWSSIP conference, pages 237 to 242. Reading the paper rather than the code is the better way to settle a definition dispute, because the disagreements this library exists to remove are settled there. The license is MIT.
Editorial conclusion
Use this library when your detector already hands you bounding boxes and you want VOC precision-recall and average precision numbers without writing a conversion layer, because that is precisely the gap it was built to close. Do not pick it for COCO work, for video, or for anything expecting a graphical tool, since the project itself routes all three elsewhere. Before adopting, read the successor repository linked at the top of the README, check whether the pinned dependency versions still install on your interpreter, and decide whether you want the 11-point or the all-points interpolation, since the two give different numbers for the same detections.
Frequently asked questions
What is a good IoU score?
The project defines Intersection Over Union as a measure based on the Jaccard Index that evaluates the overlap between two bounding boxes, requiring a ground truth box and a predicted box, and applying it tells you whether a detection counts as a true positive or not.
What does accuracy 1.0 mean?
On agreement with official tools, the README says its implementations were carefully compared against the official implementations and the results are exactly the same. It also explains that a wrong or different implementation is what creates different and biased results in the first place.
What metrics does Object-Detection-Metrics implement?
It implements the PASCAL VOC object detection metrics, organized as a precision x recall curve, average precision, 11-point interpolation, and interpolation over all points. The README states these are the metrics used by the current PASCAL VOC challenge.
Does Object-Detection-Metrics include COCO metrics or a user interface?
Not here. The README states that a newer version of the tool exists which includes all COCO metrics, supports other file formats, provides a user interface to guide the evaluation process, and presents the STT-AP metric for object detection in videos.
How do I run Object-Detection-Metrics on my own detections?
The library expects ground truth bounding boxes and detected bounding boxes as simple input, so you avoid converting your results to XML or JSON the way the official PASCAL VOC Matlab script requires. Sample runs are provided as samples/sample_1 and samples/sample_2; groundtruths/, detections/, their _rel variants and results/ sit at the repository root.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rafaelpadilla-object-detection-metrics)Star history chart for your README
[](https://hysenlabs.com/projects/rafaelpadilla-object-detection-metrics)Was this useful?