FastF1 for Python: DataFrames for F1 data, one cache layer, tight version pins
FastF1 is a python package for accessing and analyzing Formula 1 results, schedules, timing data and telemetry
At a glance
- What is it?
- FastF1 wraps results, schedules, timing and telemetry into extended Pandas DataFrames and caches every request. The install is a single pip line. The version pins, the undocumented cache and the browser gap are what a production script has to plan around.
- Who is it for?
- Adopt FastF1 if you want Formula 1 results, schedules, timing and telemetry as Pandas DataFrames and are willing to work inside the Python 3.10 and dependency boundaries its manifest sets out. Leave it if you need browser notebooks without following a guide maintained in another repository, or if you need to publish alongside the championship's marks, because the project grants neither.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 21, 2026, and from our analysis. They are not legal advice.
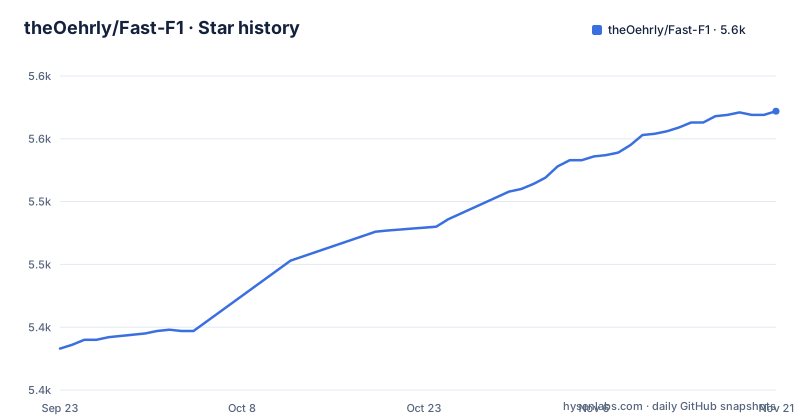
Star history
- theOehrly/Fast-F15,572 ★ · +189
| Repository | 2026-09-23 | 2026-11-21 |
|---|---|---|
| theOehrly/Fast-F1 | 5.4k | 5.6k |
189 Stars in the last 59 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
pip install fastf1, and what the wheel leaves out
The install section names pip as the recommended path and does not get fancier than this:
pip install fastf1conda-forge carries the same package, so a conda environment needs no separate build:
conda install -c conda-forge fastf1A wheel or a source distribution can also be taken straight from PyPI. The official documentation lives at docs.fastf1.dev.
Two build targets decide what actually reaches you. The wheel carries the package alone, and the source distribution adds the extras:
[tool.hatch.build.targets.wheel]
include = [
  "fastf1/**",
]
exclude = [
  "fastf1/tests/**",
  "fastf1/testing/**",
][tool.hatch.build.targets.sdist]
include = [
"fastf1/**",
"requirements/**",
"examples/**"
]The wheel ships neither the examples nor the requirements files, while the source distribution includes both. If you installed a wheel from PyPI expecting an example next to the module, that absence is the build configuration, not a mistake on your side.
The version number is a git tag, not a line in the manifest
The manifest marks the version as dynamic and points hatch at the repository history, so the number you import is read from a tag rather than typed into a file you can edit. Recent tags are v3.9.0 on 2026-10-24, v3.9.1 on 2026-11-02 and v3.9.2 on 2026-11-02. The last push to main was on 2026-11-02, the same day as the newest release.
A clone of main can still differ from the released wheel: a change that lands on main before its tag is cut will be in your checkout and absent from your dependency resolution. Pin a tag for anything you plan to run twice.
The classifiers name Python 3.10 through 3.14 and requires-python is set to >=3.10, so an older interpreter fails at install time rather than at import time. That is the kinder of the two failures, and it is the only version policy the repository states outright.
Every API request goes through a cache with no documented location
Caching is listed as a feature: all API requests are cached so scripts run faster. `requests-cache>=1.3.0` is a hard dependency and `platformdirs` sits beside it, the library a Python package normally uses to resolve a writable per-user directory. Nowhere in the install section or the manifest is the cache location given, or a purge, refresh or expiry switch.
That silence bites the moment a script becomes a pipeline. Code that has to reflect the newest session needs an explicit answer about the cache, and the README and manifest do not give one.
History and telemetry arrive through different services
Two data paths sit behind one import. Current and historical results come through the Ergast compatible jolpica-f1 API, and the project states full support for it. Timing data, telemetry and session results are a separate listed feature, and the manifest also lists `websockets>=10.3` and `signalrcore`.
Nothing in the install notes names the service behind timing and telemetry, so the split stays visible in your own code and you own the error handling on both halves.
Four numeric dependencies, each pinned from both sides
Every numeric dependency is bounded on both ends:
dependencies = [
  "cryptography",
  "matplotlib>=3.8.0,<4.0.0",
  "numpy>=1.26.0,<3.0.0",
  "pandas>=2.1.1,<3.0.0",
  "platformdirs",
  "pydantic",
  "pyjwt",
  "python-dateutil",
  "requests>=2.30.0",
  "requests-cache>=1.3.0",
  "scipy>=1.11.0,<2.0.0",
  "signalrcore",
  "rapidfuzz",
  "timple>=0.1.6",
  "websockets>=10.3"
]
`requests`, `requests-cache`, `timple` and `websockets` carry a floor but no ceiling. Seven more entries, including `cryptography`, `pydantic` and `rapidfuzz`, are bare names with neither bound at all. Where the ceilings exist, they are the compatibility policy: a major numpy or pandas release can change the array and dtype behaviour a data shaping library sits directly on top of. The cost lands on whoever installs, because a resolver that wants a newer numpy than you expected has to backtrack, and a shared environment pinned past one of those ceilings turns `pip install fastf1` into a conflict.
The manifest documents its own maintenance burden in comments. The minimum Python version also has to be changed in the test matrix, and the minimum package versions also has to be changed in `requirements/minver.txt`. Both live outside pyproject.toml, so both are easy to forget. If you are judging whether a future major release will still fit your stack, `requirements/minver.txt` and the test matrix are the two places holding the answer.
Pyodide support points at a guide in another repository
Browser support gets one paragraph in the install section. FastF1 should be mostly compatible with Pyodide and other WASM based environments, the same paragraph says this is not extensively tested, and it says installation and usage need additional steps. The steps are not in this project. They live in f1datajunkie/jupyterlite-fastf1, an external repository, with the discussion in issue 667.
So that single sentence carries two claims of different weight. A wheel that imports in a browser is a compatibility statement. A guide maintained by somebody else, which this project links to, is an acknowledgement that the browser path is unfinished.
For you the consequence is narrow but real. If your work has to run in a notebook with no native build step, you are depending on a guide outside this repository and on a WASM build of a dependency set pinned for a normal interpreter. That external repository is where the guide and more information live, so read it before you design around it rather than after.
The examples tree is the closest thing to a tutorial
The repository root is small enough to read in one screen:
docs/
examples/
fastf1/
requirements/
pyproject.toml
pytest.ini
conftest.py
What teaches you the library is the examples/ tree, split into general, lap_times, results_strategy, standings and telemetry, plus a GALLERY_HEADER.rst that suggests those examples feed a documentation gallery. There is no usage file at the root, and examples/ is not part of the wheel, so a plain `pip install fastf1` leaves you with an import and a documentation site.
That division has a cost. Each of the five directories implies a different kind of question about the data, and the order that would make sense to someone new to Formula 1 data is not the order of the directories. Working out which example answers your question means opening the documentation rather than reading a file list.
Judging upkeep from dates beats adjectives here. The last push to main was on 2026-11-02, the same day as the newest tag, v3.9.2.
Formula One Licensing B.V. keeps the marks
The project closes with a notice worth reading before you build anything visible. FastF1 and its website are unofficial and not associated in any way with the Formula 1 companies, and F1, FORMULA ONE, FORMULA 1, FIA FORMULA ONE WORLD CHAMPIONSHIP and GRAND PRIX are trade marks of Formula One Licensing B.V.
That paragraph is not filler on a data library. A dashboard, a blog post or a paper showing championship results beside the series name is making a trademark decision, and this project hands you the data without granting any right to the branding. If you ship something public, that question is yours to answer, and nothing in the repository answers it for you.
The repository also names an R package, f1dataR on CRAN, that wraps FastF1, and sends questions about it to that package's own maintainers. The practical consequence: a bug you meet through the R wrapper will not be fixed by an issue against the Python project, and the two drift apart as the Python side moves. Establish which side your problem is actually on before spending an afternoon of debugging time on the wrong repository.
Editorial conclusion
Adopt FastF1 if you want Formula 1 results, schedules, timing and telemetry as Pandas DataFrames and are willing to work inside the Python 3.10 and dependency boundaries its manifest sets out. Leave it if you need browser notebooks without following a guide maintained in another repository, or if you need to publish alongside the championship's marks, because the project grants neither. Before the first run, confirm that the version you pinned matches the tag you think is current, and decide what your pipeline does with the request cache when a session has to be live.
Frequently asked questions
How do I install fastf1?
The install section gives two commands: `pip install fastf1` as the recommended path, and `conda install -c conda-forge fastf1` as an alternative. A wheel or a source distribution can also be downloaded from PyPI. The manifest requires Python 3.10 or newer.
How do you use FastF1 to get F1 data?
Everything comes back as extended Pandas DataFrames, with custom functions attached to those objects and Matplotlib integration for plotting. Current and historical results come from the Ergast compatible jolpica-f1 API, and timing data, telemetry and session results are covered too. Worked examples sit in the examples/ directory, split into general, lap_times, results_strategy, standings and telemetry.
What is FastF1?
FastF1 is a Python package for accessing and analyzing Formula 1 results, schedules, timing data and telemetry. It is MIT licensed, its documentation is at docs.fastf1.dev, and it states that it is unofficial and not associated in any way with the Formula 1 companies.
What API does FastF1 use for F1 data?
For current and historical F1 data, the project states full support for the Ergast compatible jolpica-f1 API. The dependency list also pins `requests-cache>=1.3.0`, so all API requests are cached, and it also lists `websockets>=10.3` and `signalrcore`. The install notes do not name the service behind timing and telemetry.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/theoehrly-fast-f1)Star history chart for your README
[](https://hysenlabs.com/projects/theoehrly-fast-f1)Was this useful?