RLtools builds from one g++ line, and its backend choice is a macro you have to know about
The Fastest Deep Reinforcement Learning Library
At a glance
- What is it?
- RLtools is a C++ reinforcement learning library with TD3, PPO, multi-agent PPO and SAC, aimed at running training loops and inference on hardware from a laptop M1 to microcontrollers. Its quick start is a single compiler invocation, its linear algebra backend is selected by a compile-time flag, and its benchmark results exist as charts rather than as numbers in the page.
- Who is it for?
- RLtools fits someone who needs a training loop and an inference binary in the same C++ tree, and who wants the option of running a small policy on a microcontroller rather than a GPU runtime.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 7 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
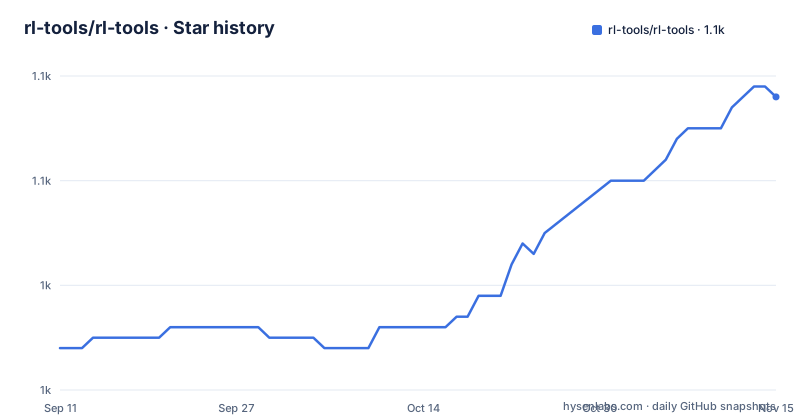
- rl-tools/rl-tools1,058 ★ · +24
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| rl-tools/rl-tools | 1k | 1.1k |
24 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The quick start is one compiler line and skips the build system
There is no install step in the quick start. You clone the repository and compile a single example file directly:
g++ -std=c++17 -O3 -ffast-math -I include src/rl/zoo/l2f/sac.cppThat produces `./a.out`, which takes one argument, and the page is explicit that the number is the seed, so `./a.out 1337` runs the learning-to-fly quadrotor example with that seed. Results are then served with `./tools/serve.sh`, and you open `http://localhost:8000` and navigate to the ExTrack interface to watch the quadrotor fly.
The three flags are the whole performance story for a first build: C++17, optimization level 3, and fast-math, with the include path pointing at the header directory. That the repository also carries a CMakeLists.txt, a cmake directory and a tests tree is worth knowing, because it means the library has a real build system while the advertised first run deliberately bypasses it.
The linear algebra backend is a macro, and nothing picks it for you
Two lines in the quick start decide what your arithmetic runs on. On macOS you append `-framework Accelerate -DRL_TOOLS_BACKEND_ENABLE_ACCELERATE`, which the page pairs with roughly four seconds on an M3. On Ubuntu you install `libopenblas-dev` with apt and append `-lopenblas -DRL_TOOLS_BACKEND_ENABLE_OPENBLAS`, paired with roughly six seconds on a Zen 5.
Both are compile-time switches with distinct names, and neither is auto-detected. That is the design consequence worth internalizing: a build that omits the flag gets whatever the default backend is, not a fallback that notices Accelerate or OpenBLAS is installed. For a library whose pitch is speed, the fastest configuration is the one you have to read the page to find.
The same manual approach shows up in the examples. CUDA is not a global option but a separate source file per algorithm, so choosing it means choosing which example you compile rather than setting an environment variable for the library.
The benchmarks are charts, so the headline claim has no number attached
The project's one-line description calls this the fastest deep reinforcement learning library, and the page presents three benchmark charts. The first compares training Pendulum swing-up across different RL libraries, run separately for PPO and for SAC. The second compares the same task across different devices, using SAC against RLtools. The third is the unusual one: inference frequency for a two-layer network with 64 units in each layer, measured across different microcontroller types and architectures.
What the page does not contain is a single number from any of them. The comparisons are images with captions, so there is no table to read, diff or cite, and the superlative in the description has nothing in the text to support it.
The one timing that is written down comes with its hardware attached: a result described as trained in 18 seconds on a 2020 MacBook Pro with M1, using TD3. Every caption on the page repeats that machine, which makes the claim legible rather than general. The third-party trail is separate: a paper titled Learning to Fly in Seconds, an arXiv entry, and coverage in IEEE Spectrum.
CUDA examples exist for two of the four algorithms
The algorithm table pairs each method with example files, and the paths make the hardware coverage plain. TD3 has Pendulum, Racing Car, MuJoCo Ant-v4 and Acrobot, all CPU-shaped paths. PPO has Pendulum, Racing Car, MuJoCo Ant-v4 on CPU, and a separate CUDA file for Ant-v4. SAC has a CPU Pendulum, a CUDA Pendulum and Acrobot. Multi-agent PPO has exactly one entry, the Bottleneck environment.
So a CUDA path exists for PPO and for SAC, and neither appears in the TD3 row or the multi-agent row. Anyone planning to train a TD3 policy on a GPU from this repository will find no example to copy, which is a different situation from the library being unable to do it.
The environments themselves are a small, legible set: Pendulum and Acrobot as the teaching pair, Racing Car and MuJoCo Ant-v4 as the more realistic ones, the learning-to-fly quadrotor from the zoo, and Bottleneck as the multi-agent case. The Ant-v4 version identifier is stated in the table, which matters because MuJoCo environment revisions have changed reward and observation shapes before.
Your own environment lives in a different repository
The getting started section is thin by design and says so, pointing at the documentation's Getting Started page as the more thorough guide. The more useful pointer is the second one: to implement your own environment, the page sends you to a separate repository, rl-tools/example.
That split is the practical fact for anyone extending the library. The algorithm implementations, the environments shipped here and the example scaffold are three different places, and the page's own framing is that RLtools focuses on the learning side so you can concentrate on model optimization and business logic.
Around the library the project runs several front ends: a live demo in the browser, a zoo at zoo.rl.tools, a studio at studio.rl.tools, documentation at docs.rl.tools, and a Discord server. The paper behind the work is on arXiv as 2306.03530.
The documentation is C++ notebooks kept in their own repository
Documentation is not markdown here. It is described as C++ notebooks, published at docs.rl.tools and runnable locally so you can edit and re-run them:
docker run -p 8888:8888 rltools/documentationThe container prints a link in the CLI, of the form `http://127.0.0.1:8888/...`, and that printed address, not a fixed path, is what you open.
Two details are worth noting. The notebooks live in the rl-tools/documentation repository rather than beside the source, on a branch named master while the library itself is on main, which is why the launch badges point at a separate tree. And the chapter list includes a Python interface notebook, so the documentation covers binding the library from Python as well as using it from C++.
There are Binder and Colab links for the same notebooks, which is the cheapest way to look at the interface without building anything.
The newest tag is eleven months older than the newest commit
Three releases are visible: v2.0.0 on 2024-11-19, v2.1.0 on 2025-10-14, and v2.2.0 on 2025-10-23. The repository is not archived, its last push is dated 2026-09-16, and the license is MIT.
Read together, those dates say the library kept receiving work for about eleven months after its newest tag. If you are pinning a version, you are pinning something older than the tip of the branch, and the gap between them is not described anywhere in the page.
Two downstream projects are listed as built on it, each with its own repository and paper: quadrotor system identification with motor delays, and the learning-to-fly work that produced the 18 second claim. Both come from the same laboratory, which is also where the peer-reviewed venue for this line of work would be. The tooling conventions in the tree, a .gdbinit and an .lldbinit alongside a .vscode directory, point at the same audience: people debugging a training loop in a native toolchain.
Editorial conclusion
RLtools fits someone who needs a training loop and an inference binary in the same C++ tree, and who wants the option of running a small policy on a microcontroller rather than a GPU runtime. Verify four things first: which BLAS backend you compile against, since Accelerate and OpenBLAS are macros and nothing detects them for you; whether the algorithm you want has a CUDA example, since only SAC and PPO list one; where your environment implementation lives, since a custom environment is a different repository; and which version you are pinning, because the newest tag is eleven months older than the newest commit. Treat the speed claims carefully: the numbers live in charts, and the training time quoted on the page comes with an explicit hardware caveat.
Frequently asked questions
What is RLtools?
It is a C++ deep reinforcement learning library, MIT licensed, implementing TD3, PPO, multi-agent PPO and SAC with examples for Pendulum, Racing Car, MuJoCo Ant-v4, Acrobot, a learning-to-fly quadrotor and a multi-agent Bottleneck. The project site is rl.tools and the documentation is at docs.rl.tools.
How do I build and run an RLtools example?
Compile one file with `g++ -std=c++17 -O3 -ffast-math -I include src/rl/zoo/l2f/sac.cpp`, then run `./a.out 1337` where the number is the seed, then run `./tools/serve.sh` and open http://localhost:8000 to reach the ExTrack interface. No install step is needed for that path.
Does RLtools need BLAS or a GPU?
The linear algebra backend is selected at compile time. On macOS append `-framework Accelerate -DRL_TOOLS_BACKEND_ENABLE_ACCELERATE`, and on Ubuntu install libopenblas-dev and append `-lopenblas -DRL_TOOLS_BACKEND_ENABLE_OPENBLAS`. CUDA examples are listed for SAC on Pendulum and PPO on MuJoCo Ant-v4.
What benchmarks does RLtools publish?
Three charts: Pendulum swing-up comparing RL libraries for PPO and for SAC separately, Pendulum swing-up across different devices, and inference frequency for a two-layer 64 unit network across microcontroller types and architectures. The results are shown as images rather than as numbers in the text.
How do I implement my own environment with RLtools?
The page sends you to a separate repository, rl-tools/example, and to the Getting Started page in the documentation, which it describes as the more thorough guide. The environments bundled here, such as Pendulum, Acrobot, Racing Car and MuJoCo Ant-v4, sit alongside that scaffold rather than inside it.
How do I run the RLtools documentation locally?
Run `docker run -p 8888:8888 rltools/documentation` and open the link the CLI prints, of the form http://127.0.0.1:8888/... The docs are C++ notebooks maintained in the separate rl-tools/documentation repository, and Binder and Colab links to the same notebooks are provided.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rl-tools-rl-tools)Star history chart for your README
[](https://hysenlabs.com/projects/rl-tools-rl-tools)Was this useful?