OnnxStream: fitting SDXL into 298 MB with tiled decoding
Lightweight inference library for ONNX files, written in C++. It can run Stable Diffusion XL 1.0 on a RPI Zero 2 (or in 298MB of RAM) but also Mistral 7B on desktops and servers. ARM, x86, WASM, RISC-V supported. Accelerated by XNNPACK. Python, C# and JS(WASM) bindings available.
At a glance
- What is it?
- A C++ inference library designed to reduce memory use through streamed weights, selective quantization and tiled VAE decoding. Its SDXL example trades substantial latency for a reported 298 MB memory footprint.
- Who is it for?
- OnnxStream is for someone who has to run a model where the memory is the constraint, a Pi Zero 2 or a browser tab, and who would rather wait than run out of RAM. Check three things first.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 150 days ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
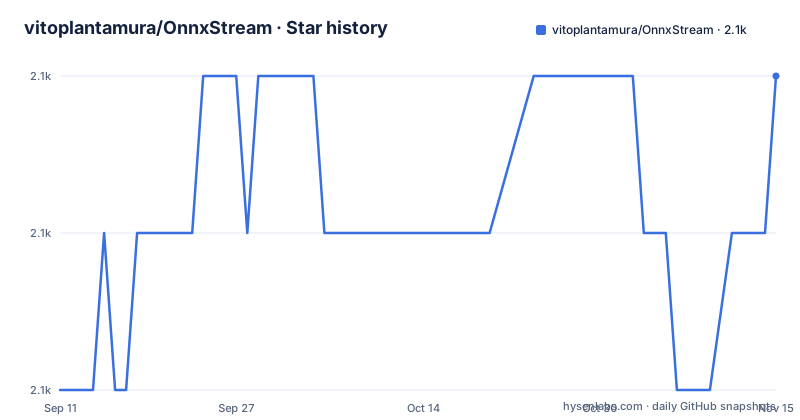
- vitoplantamura/OnnxStream2,089 ★ · +2
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| vitoplantamura/OnnxStream | 2.1k | 2.1k |
2 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The engine and the weights are two separate things
The central design decision is a class called `WeightsProvider`, and everything else follows from it. The inference engine does not know where the model weights come from. It asks a provider, and a provider is any subclass of that base class.
Because the boundary is drawn there, a provider can do anything, including loading from an HTTP server without reading or writing anything to disk. That is what the word Stream in the name refers to. It is not streaming inference in the token-by-token sense.
Three providers ship by default. `DiskNoCache` reads weights from disk without caching, `DiskPrefetch` prefetches, and `Ram` holds them in memory. The first two are the interesting ones for the project's stated goal, because they trade RAM for reads.
Everything else in the library follows the same principle of being replaceable at the edge. The top-level entries are small: source, examples, assets, a Dockerfile and a directory with an ONNX-to-text tool whose purpose the page never explains.
The benchmark is memory, and the latency cost is stated up front
The comparison claim is specific. OnnxStream is said to consume up to 55 times less memory than ONNX Runtime, with a latency increase of between 50 and 200 percent, measured on CPU with a good SSD and referencing the Stable Diffusion 1.5 transformer.
Both halves of that sentence are the point. A memory ratio on its own would be worth little, and the admission of a latency cost in the same breath is what makes the trade legible.
The framing paragraph before it explains the choice. Major machine learning frameworks and libraries are described as focused on minimising inference latency or maximising throughput, both at the cost of RAM usage. This library inverts that priority on purpose, and the author says so directly rather than dressing it up.
That decision has consequences downstream. Attention slicing and quantization get their own section in the index, because on a machine with 512MB of RAM and no swap the only way to fit a model is to stop holding intermediate results all at once. It also explains why the examples spend so much of their text on what could not be made to fit.
Tiled VAE decoding reduces the SDXL memory peak
OnnxStream reports running SDXL 1.0 in less than 300 MB of RAM. To reduce memory for the UNet on a Raspberry Pi Zero 2, the project applies UINT8 dynamic quantization to a selected subset of large intermediate tensors.
The VAE decoder needs a different approach. According to the project, full FP32 decoding consumes 4.4 GB, while FP16 arithmetic overflows and UINT8 quantization gives poor image quality. The project therefore uses tiled decoding: it splits the latent tensor into overlapping pieces, decodes them separately, and blends the results. The README reports that this reduces memory consumption to 298 MB and says the blended output is indistinguishable from full decoding.
These are project-reported measurements for its example, not a guarantee for every model, image size or configuration.
Eleven hours for ten steps, against twenty six minutes
The timings are given against a reference point, which makes them usable.
For SDXL, a ten step image with Hugging Face's Diffusers takes 26 minutes on a 12-core PC with 32GB of RAM. The same ten steps on a Raspberry Pi Zero 2 through this library take about 11 hours. The minimum recommended VRAM for SDXL is given as typically 12GB, against typically 8GB for SD 1.5.
The SD 1.5 example tells the same story at smaller scale. The page reports an image generated on a Pi Zero 2 in about 1.5 hours, and the text shows that number was itself revised down from about 3 hours after compiling with a maximum speed option. Keeping the earlier figure struck through is useful: it is a real measurement of what a compiler flag bought.
What the page does not give is any figure for the other models in its index. TinyLlama 1.1B and Mistral 7B, YOLOv8, Whisper, and the Turbo variant of SDXL are all listed without a memory number or a timing in what is visible here. The index is broader than the measured section, so treat the two 1.5 and 11 hour numbers as the only benchmarks that are actually stated.
Two releases, and the newest one is from January 2024
The release list has two entries and both of them are Windows artefacts. v0.1 is named for a Windows build with weights included, published 2023-07-17. v0.2, published 2024-01-14, is named for a Windows build carrying a chat application with TinyLlama 1.1B and Mistral 7B and optional cuBLAS support.
So there has been no tagged release in about two and a half years. The news list tells you what happened instead. It runs to a Python and C# binding for the library in September 2025, a Whisper WebAssembly demo in the browser in April 2025, WebAssembly support with a YOLOv8 demo in September 2024, the LLM chat application in January 2024, SDXL Turbo in December 2023 and SDXL base in October 2023.
The last commit to the repository is 2026-06-18 and it is not archived, so the work continues without releases. For a library whose consumers tend to build from source, that is workable. For anyone who installs from a release, there is nothing newer than the January 2024 chat application.
The two bindings are described in one news line and then not discussed further on the page, even though a Python or C# binding is what most people would want.
A licence the metadata cannot identify
The repository records no licence in its metadata, and the tree contains a licence file. Those two facts do not agree, and the page does not resolve the disagreement, so neither does this description.
That matters more here than for a typical repository. OnnxStream asks you to fetch or self host model weights, compile from source on one of five platforms, and in the documented Docker flow mount the current directory into the container so weights and results are written there. A licence question is not academic for a library you are embedding.
What is clear from the page is the licensing posture of the models rather than the library. The examples are other people's models: Stable Diffusion from the CompVis repository, SDXL exported through the Hugging Face Diffusers library, YOLOv8, Whisper, TinyLlama and Mistral. Each carries its own terms, and the page links to the model sources rather than restating their licences.
The default branch is `master` rather than `main`, which dates the repository's configuration to an earlier era of GitHub defaults.
The container is two Ubuntu stages and one copied binary
The Dockerfile is short enough to read in full, and its comments carry the usage. Building is `docker build -t sd .`, and running is a single command with flags for where the models live, where the result goes, how many steps, and a turbo flag:
sudo docker run -t -i --init -v .:/current sd --models-path /current --output /current/result.png --steps 1 --turboThe mount is the design. Weights and the generated image are read from and written to the current directory on the host, which is what makes a container usable for a diffusion model at all: you do not have to bake gigabytes into an image.
The build itself is two stages on Ubuntu, with the version as a build argument. The first installs the ordinary build tools, copies the source in, and builds with CMake in release mode. The second installs only curl, copies the resulting binary across, and makes it the entry point. No runtime libraries beyond curl survive into the final image.
Beyond the container, the index names the platforms the build guide covers, including Termux and FreeBSD, the four architectures in the repository description, and XNNPACK as the acceleration path.
Editorial conclusion
OnnxStream is for someone who has to run a model where the memory is the constraint, a Pi Zero 2 or a browser tab, and who would rather wait than run out of RAM. Check three things first. Which part of your model is the heavy part, because the library's whole design targets the transformer and not every submodel. Whether a quantization option exists for it, since the SDXL decoder example shows what happens when there is none. And whether you can live inside the latency the project accepts, stated as a fifty to two hundred percent increase over ONNX Runtime, with an eleven hour figure for a ten step SDXL image on the smallest supported machine.
Frequently asked questions
What is OnnxStream and what is it built for?
A small C++ inference library for ONNX models, written specifically to minimise memory consumption rather than inference latency. It runs Stable Diffusion XL 1.0 in under 300MB of RAM on a Raspberry Pi Zero 2, and Mistral 7B on desktops and servers, with ARM, x86, WASM and RISC-V support.
How does OnnxStream compare with ONNX Runtime?
The page states it can consume up to 55 times less memory than ONNX Runtime with a 50 to 200 percent increase in latency, measured on CPU with a good SSD and referencing the Stable Diffusion 1.5 UNET. The trade of memory for time is deliberate.
What are the default WeightsProvider classes?
DiskNoCache, DiskPrefetch and Ram, all derived from WeightsProvider. That base class decouples the inference engine from wherever weights come from, so a custom provider can prefetch, cache or stream them from an HTTP server without loading or writing anything to disk.
Why does the SDXL example need 4.4GB when the headline says 300MB?
The transformer is quantized with UINT8 dynamic quantization on a subset of large tensors to fit in 300MB, but SDXL's VAE decoder is four times the size of SD 1.5's and takes 4.4GB in FP32, overflows in FP16 and is too lossy at UINT8. The page links to at least one external solution.
How long does OnnxStream take to generate an image?
For SDXL a ten step image takes about 11 hours on a Raspberry Pi Zero 2, against 26 minutes with Hugging Face Diffusers on a 12-core PC with 32GB of RAM. A Stable Diffusion 1.5 image on the Pi took about 1.5 hours, revised down from 3 after compiling with a maximum speed option.
Which platforms can OnnxStream be built on?
The build guide covers Linux, Mac, Windows, Termux and FreeBSD, with ARM, x86, WASM and RISC-V named in the repository description and XNNPACK as the acceleration path. There are browser demos for YOLOv8 and for Whisper.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vitoplantamura-onnxstream)Star history chart for your README
[](https://hysenlabs.com/projects/vitoplantamura-onnxstream)Was this useful?