RPent ships version 0.0.0 as pre-alpha, and its planner column is other people's coding agents
RPent: Agentic Infrastructure for the Physical World
At a glance
- What is it?
- RLinf/RPent is a framework for embodied agents that uses recursive interaction with the physical world instead of prescribing a foundation model, and its architecture is visible in one table: the planner column is three checkmarks, two of which are commercial coding agents, while the action primitives are frozen vision-language-action models. The packaging tells a different story from the page, with a version of 0.0.0, a pre-alpha classifier and no deep learning framework in the dependency list at all.
- Who is it for?
- This is an orchestration framework rather than a model, and the dependency list is the proof: there is no deep learning library in it at all, because the action models run inside the simulators and on the robots while the framework coordinates them. If that is the layer you need, the design is sound and the component boundaries are clearly documented.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
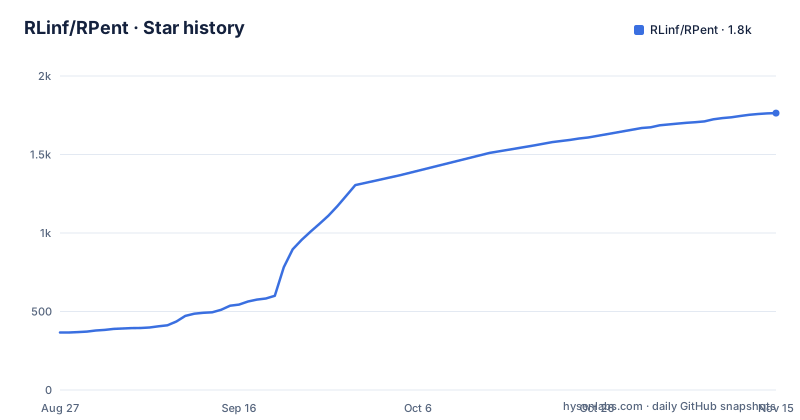
- RLinf/RPent1,764 ★ · +1,398
| Repository | 2026-08-27 | 2026-11-15 |
|---|---|---|
| RLinf/RPent | 366 | 1.8k |
1,398 Stars in the last 80 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The package says 0.0.0 and pre-alpha, the page talks about deployment
The packaging metadata is precise and it is not flattering. The project version is 0.0.0, which is the value a package carries when nobody has decided what its first release is. The development status classifier is the second rung on a scale the file itself documents in comments, pre-alpha, with the remaining rungs listed above it as alpha, beta and production.
There is also a hardware classifier, and it is narrow: a specific CUDA major and minor version, 12.4. The Python requirement is bounded on both sides, from 3.10 up to but not including 3.13.
Now put those next to the rest of the page. The leaderboard claims a comparison against reference methods on four suites. The audience section addresses end users of deployed embodied agents and tells them they can install the framework with the relevant real-robot extensions and run predefined tasks out of the box with no machine learning expertise required. None of that is incompatible with pre-alpha, but a reader who takes the page at face value and then installs 0.0.0 will have a different experience than the wording suggests.
The planner column is two other companies' coding agents
The feature matrix has four columns and the first one answers the architectural question. The agentic planner column carries three entries and all three are supported: a coding agent, another coding agent, and a custom planner you write yourself, with the documentation linking to a page on adding one.
Read across a row and the design becomes clear. The framework does not contain a planner of its own. It drives an off-the-shelf coding agent as the high-level reasoning step, and it hands that agent action primitives produced by frozen vision-language-action models.
The dependencies make that literal. Two of the runtime requirements are agent SDKs published by those same vendors, one at a fairly loose floor and the other pinned at a beta release. So a robotics framework's planner layer now has a release cadence it does not control, and one of those two dependencies is itself pre-release.
The first publication's title says the same thing in different words: steering frozen models into reliable manipulation primitives through memory-guided agents.
The one printed leaderboard result is not RPent's own
The leaderboard section introduces itself by naming four things it compares: two related benchmark suites, one simulator with a fifty-target subset, and one suite scored on a conversion metric. It also carries the caveat that rankings apply to the methods and evaluation coverage shown.
Then exactly one result is printed on the page. It is labelled with the coding-agent planner and a model name, at low reasoning effort, and it reads 92.63 percent overall, 741 out of 800, across all eight suites of the harder benchmark.
That is a baseline row: a reference configuration on someone else's model, not the framework scored against its own planners, and the numbers a reader would want to see, the framework against the frozen models it wraps, are not on the page. The link text mentions separately frozen long and spatial, object and goal memory batches, which suggests the full leaderboard breaks the aggregate down by memory condition, and that breakdown lives elsewhere.
For a project whose central claim is that memory-guided composition lifts success rates, the memory batch breakdown is the number that matters, and it is the one not printed.
The only quantified claim is a forty percent speedup
The news list runs from July to September 2026 and every entry is dated and linked to a documentation page. Exactly one of them carries a number: a non-reasoning mode that reduces average execution time by about forty percent.
That is a useful number and a narrow one. It measures wall-clock execution against a mode you can switch on, and it says nothing about whether the tasks are solved as often. A forty percent saving is worth having in a loop that runs many steps, and it is also the kind of figure that gets quoted without the caveat that the comparison mode is doing less work per step.
The rest of the list is dates and links: a leaderboard, single-arm and dual-arm robot extensions, one simulator with a new manipulation model, an exploration mode for one benchmark suite, and a second simulator with a different model for dual-arm work. That cadence, several additions a month, tells you the framework is moving quickly, and it is also why the version number being 0.0.0 is a little surprising.
Two action models carry no support mark, and one robot name is cut off
The action primitive column is split into two families and the marks are not even between them. Under the vision-language-action heading, three models are supported, each linking to the simulator page that covers it. Under the world-action-model heading, two more are named with no support mark at all.
The same pattern runs through the other two columns. Three simulators are supported and one is listed without. On real hardware, two robot extensions are supported, both of them the same arm in single-arm and dual-arm form, and two further entries are listed without, one of which is a second arm platform and the other of which is cut off mid-token in the table as it appears.
Read as a whole, the matrix is honest: three planners fully supported, three action models supported out of five, three simulators out of four, and two real robots out of at least four. A project in pre-alpha with checkmarks only where things work is a better document than one with checkmarks everywhere.
Four console commands name the subsystems
The entry points tell you how the framework is divided. There is the main command, a memory command, a command that checks the language model connection, and one called the flywheel.
The flywheel is the interesting name. It is the word the framework's own abstract reaches for when it describes continuous interaction, reflection and adaptation, and giving that loop its own command line entry suggests it is something you run, watch and intervene in rather than something that only happens inside the main loop.
The memory command being separate is the other signal. Memory is treated as its own surface with its own tooling rather than as a detail of the agent, which matches the leaderboard's emphasis on memory batches and the first publication's framing of memory-guided agents.
The connectivity check being a command rather than a startup assertion is a small kindness. It means the first thing to try when a planner does not respond is a dedicated command, not a stack trace from inside a framework.
The reinforcement learning extra installs from a branch
The optional extras are two groups. The test group is ordinary: coverage, a test runner, a timeout plugin for it, a configuration library and an environments library, which is the usual sign that the test suite drives simulated environments.
The second group is one entry, and it is not a version number. It is a direct reference to a git repository at a branch named for a release series. An install of that extra resolves the branch at the moment you install, so two people installing the same wheel from the same day can get different code, and a later install can change behaviour without anything in the package changing.
That may well be deliberate, since the two projects appear to be released together and branch pinning is a normal way to track an integration. It is still the one dependency in the file that cannot be reproduced.
One other dependency in the list carries an upper bound below its next major version, and it is the protocol client library rather than a model or a runtime. Everything else in the file is a floor or completely unpinned.
Robot and calibration code sits at the repository root
The tree is laid out by role rather than by layer. A single source directory holds the framework, and two directories at the root sit beside it: one for calibration tooling and one for robot integrations.
Calibration having its own top-level directory is the detail that matters for the real-hardware story. Any arm you deploy on has to be told where it is and how it is mounted, and this framework treats that as first-class code rather than as deployment configuration.
There are also two agent configuration directories and two agent instruction files at the root, plus contributing guides in two languages, which is the shape of a project that uses coding agents in its own development loop and expects its contributors to as well.
What is not in the tree is any model weight, any simulator binary, and any deep learning runtime. Consistent with a dependency list that contains no model framework, everything expensive lives outside the repository.
Editorial conclusion
This is an orchestration framework rather than a model, and the dependency list is the proof: there is no deep learning library in it at all, because the action models run inside the simulators and on the robots while the framework coordinates them. If that is the layer you need, the design is sound and the component boundaries are clearly documented. Two things to weigh before committing. The maturity signals contradict the marketing: version 0.0.0, a pre-alpha classifier, and a leaderboard whose single printed result is a reference configuration rather than the framework's own. And the planner layer is built on two other vendors' agent products, one of them pinned at a beta release, so your agent framework now inherits their release cadence. For a robotics team, read the leaderboard pages rather than the page summary, because the summary shows one number and the pages are said to carry suite-level results with frozen memory batches.
Frequently asked questions
What is RLinf/RPent?
An open framework for embodied agents, expanded from the name Recursive Physical Agent, built around recursive interaction with the physical world rather than around a single foundation model. It coordinates a high-level reasoning step with robot action primitives, and it is Apache-2.0 licensed with the package version recorded as 0.0.0.
Which planners and action models does RPent support?
Three planners are marked supported: two commercial coding agents and a custom planner you implement yourself. Under action primitives, three frozen vision-language-action models are supported while two world-action models are listed without a support mark. The simulator column has three supported entries and one without, and the real-world column has two supported robot extensions with others listed unsupport.
What does RPent's leaderboard measure?
It compares against reference methods on two related benchmark suites, one simulator with a fifty-target subset, and one suite scored on a conversion metric. The single result printed on the page is labelled with the coding-agent planner and a model name at low reasoning effort, at 92.63 percent overall, 741 of 800, across eight suites of the harder benchmark.
Is RPent ready for production use?
The packaging says pre-alpha, at version 0.0.0, with a classifier pinned to one CUDA release. The page separately addresses end users of deployed agents and says they can install the framework with the relevant robot extensions and run predefined tasks with no machine learning expertise, so the two statements sit in the same document.
What console commands does RPent install?
Four. One runs the framework, one for memory, one that checks the language model connection, and one called the flywheel for the self-improvement loop. An optional extra also pulls a related reinforcement learning framework straight from a git branch rather than a released version.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rlinf-rpent)Star history chart for your README
[](https://hysenlabs.com/projects/rlinf-rpent)Was this useful?