subtitle-translator says keys never touch a server and depends on a server SDK
Translate a whole season of subtitles in one pass - .srt/.ass/.vtt/.lrc, 120+ languages, 27 LLM providers, timing untouched.
At a glance
- What is it?
- A browser subtitle batch translator whose headline privacy claim is undercut by an official DeepL Node SDK in its dependencies and a built-in CORS relay that works out of the box, while its Dockerfile documents its own cache mount as useless in continuous integration.
- Who is it for?
- subtitle-translator is worth using for a season of subtitles if you want batch throughput, per-file failure isolation and a timeline that cannot be corrupted, and the structural separation is a genuinely good design choice rather than a prompt asking a model nicely. Four things to check first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
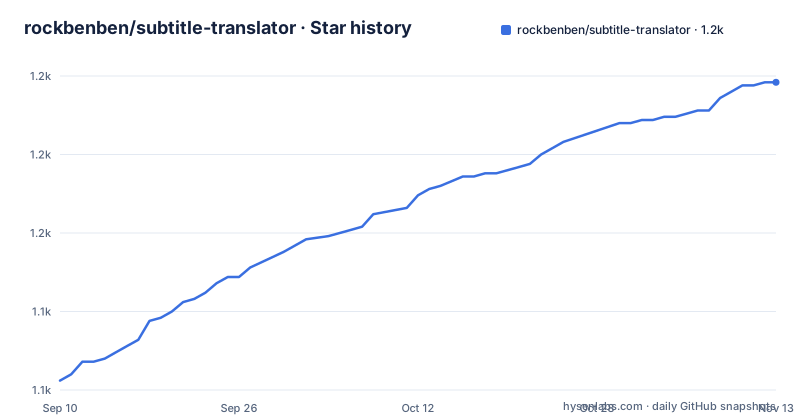
Star history
- rockbenben/subtitle-translator1,198 ★ · +95
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| rockbenben/subtitle-translator | 1.1k | 1.2k |
95 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The privacy claim and the dependency list do not agree
The file makes three separate privacy statements. Everything runs locally in your browser and subtitle content and API keys never touch a server. The project is private by design and fully client-side. And language model requests go directly from your browser to the API endpoint you configure.
Then it admits an exception in the gateway section. Providers walled off from browsers by CORS can be routed through an API relay, and the built-in relay works out of the box.
So out of the box, for every provider that a browser cannot call directly, your API key and your dialogue pass through a relay worker that somebody else deployed. The file does tell you how to change that: a relay address setting in API settings points every relayed provider at your own deployment of the relay worker. But the default is the hosted one, and the default is what a first-time user keeps.
The dependency list makes the same point from a different angle. Among the runtime dependencies is the official DeepL client library for Node, which is a server-side SDK for an API that browsers cannot call. For the highest-rated engine in the comparison table, something server-shaped is unavoidable, and the dependency manifest says so.
The timeline guarantee is structural, and its one documented limit is ASS styling
This is the part of the design that is right, and it is right for a specific reason: the guarantee is enforced by what is not sent.
Timecodes, cue numbers, ASS headers and WebVTT cue identifiers are extracted in the browser, and only dialogue text goes to the engine. The file's phrasing is that the timeline physically cannot be touched. There is no instruction asking the model to preserve timestamps and no post-hoc repair pass, because the model never sees a timestamp. Reassembly happens locally, by position.
The parsers are correspondingly careful about what counts as dialogue. WebVTT note, style and region blocks are skipped rather than translated, which stops metadata being sent to a translation engine as if it were a line of speech. The subtitle parser can also strip cues and timing entirely and export clean text, which is a separate feature that shares the same split.
The limit is in the styling, not the timing. For ASS files the file says line-leading position tags are restored automatically and complex inline effect tags are simplified. So the timing survives an ASS round trip and the animation does not. For SRT and WebVTT sources you can export ASS with separate styles for the original and the translation, which is the cleaner path if you need two languages on screen.
The zero-setup engines are the two lowest-rated entries in the table
The comparison table rates eight traditional engines on quality and stability and lists a free tier for each. The top of the quality column is a five-star engine that needs an account and gives you a monthly character allowance. The two entries that need no configuration at all are rated three stars for quality and three for stability, and both are described as free and rate-limited.
The file is direct about which is which: those two are the zero-setup defaults, and each is the other's fallback.
So the first-run experience is the weakest configuration available, chosen because it needs no account rather than because it translates well. Both are free endpoints without configuration, which also means neither has a service level you can point at when it stops working, and rate-limited free endpoints stop working without notice as a matter of course.
The middle of the table is where the interesting choices are. One is free and self-hostable, one is self-hostable through a local model runner and rated four stars for both quality and stability, and one draws on a cloud quota from a model provider. The cloud entry gets two million characters a month for a first year, which is a promotional figure that stops being true in month thirteen and is worth checking before you plan a season around it.
The cache claim is about a limit the browser enforces anyway
One feature bullet says unlimited caching, with translations stored locally and no browser storage size limit, and adds that refreshing the page does not lose translated files.
The second half is true and useful. The first half is not, in the sense a browser developer means it. The storage the file is describing is IndexedDB, and browsers enforce a quota on it per origin, sized as a share of free disk and subject to eviction when the user is short of space. There is no unlimited storage in that API. What the feature delivers is a very large allowance and persistence across reloads, which is genuinely more than most web tools offer.
The dependency list explains why a browser storage library is a runtime dependency at all. There are two of them: one general-purpose IndexedDB wrapper and a small key-value wrapper built on it. Two is one more than a project needs for a single cache.
It also has a consequence for the command line. The file says the terminal tool uses the same engine, the same parsers and the same cache, so something has to read and write that browser-origin storage from Node, which is presumably why a browser storage wrapper appears in the server-side dependency list rather than in development dependencies.
The command line is a TypeScript file, not an installed command
The file advertises a command line that drives the same engine headlessly, and the feature list gives the invocation: a package script, run through a package manager, that runs the same engine, parsers and cache from a terminal.
What that script actually is, from the package manifest, is a TypeScript file under the scripts directory, executed by a TypeScript runner that is a development dependency. There is no binary entry in the manifest, so nothing lands in your path and nothing is installed globally. To run it you need the repository, its dependencies installed, and the runner available.
That is a reasonable arrangement for the person who cloned the project and a poor one for a script you want to call from a shell on another machine. It also means the headless path is only as current as your checkout, which for a tool whose value is staying in step with browser changes in subtitle formats is not a small thing.
What the shared cache buys is worth naming too. Reusing the browser cache from the terminal means a translation done in one surface is free in the other, which is the whole point of a local-first tool. The cost is that a headless run inherits the browser's storage model in an environment that has no browser.
A build flag decides whether the API calls are local, and it is fixed at build time
The Dockerfile sets three environment variables before the build step. One disables build telemetry. One marks that this is a container build. The third is prefixed for public exposure, which in this framework means its value is inlined into the client bundle when the application is built rather than read from the environment when the container starts.
That flag points the application at its own local API. It is the difference between a self-hosted deployment that calls a service you run and one that does not, and it is compiled in.
The practical consequence is that this is not a runtime switch. Changing it means editing nothing in your compose file or environment and rebuilding the image, because the value the browser sees was substituted into the JavaScript at build time. For an operator who expects to toggle behaviour with an environment variable, that is a surprise, and the Dockerfile does not call it out.
It is worth reading alongside the build platform comment in the same file, which is unusually long. The build stage is pinned to the runner's native architecture so that a multi-architecture build does not re-run the install and the build of hundreds of packages under emulation, which the comment says can stretch from minutes to hours or hang outright.
The Dockerfile explains why its own cache mount does nothing in CI
The most valuable text in this repository is a comment explaining that one of its own optimisations is useless where it looks useful.
The build mounts a package-manager cache directory during install. The comment above it says this only helps when you rebuild locally, because the build system does not preserve cache mounts in the hosted CI cache by default, quoting the documentation's own wording. So in CI the mount neither carries over between builds nor helps within one build, because the install runs once either way. The comment says not to expect it to save any downloads.
Then it names what does work: the pipeline's own cache directives, which hit at the layer level when the manifest and lockfile are unchanged, so the install does not execute at all. And it adds the thing you would otherwise have to rediscover, which is the extra machinery needed if you genuinely want the package cache reused in CI.
The pinned build platform is explained the same way, with the causal chain made explicit: emulation is expensive, so pin the platform, which is only safe if the artefact is architecture-independent, which is guaranteed by an exclusion list in the application config and enforced by the next step.
Three comments, each stating a cost, a cause and a consequence. Rare in a Dockerfile.
An assertion exists to catch the exact failure the platform pinning could cause
The last build step is a guard, and it is the reason to trust the comment above it.
It fails the build if the standalone output directory does not exist. It then fails if any native binary file appears anywhere inside that directory, printing a message that names the configuration setting responsible and telling you to check the exclusion list.
The comment above the guard explains the reasoning in full. Pinning the build platform is only valid while the artefact is architecture-independent. If that assumption ever breaks, the build stays green and you ship an image for one architecture containing binaries for another, and it fails at run time instead of build time. The comment gives a concrete future cause: image optimisation being switched on later and the image-processing library being traced back into the output.
So the repository contains a self-fulfilling pair: an optimisation with a stated precondition, and a check that fails the build when the precondition stops holding. That is the pattern most multi-architecture builds skip.
The governance files are the weaker part of this repository. The root has no changelog, no contributing guide and no security policy, for a project that asks users to paste paid API keys into a page and, by default, route some of them through a hosted worker.
Editorial conclusion
subtitle-translator is worth using for a season of subtitles if you want batch throughput, per-file failure isolation and a timeline that cannot be corrupted, and the structural separation is a genuinely good design choice rather than a prompt asking a model nicely. Four things to check first. Change the relay address before you connect a paid key, because providers that block browser requests go through a built-in relay that works out of the box, and that default means your key and your dialogue pass through somebody else's worker until you point it at your own deployment. Expect the two zero-setup engines to be the weak ones, since the file rates them lowest for both quality and stability and describes them as rate-limited, while the highest-rated option needs an account. Do not rely on the cache surviving a long season indefinitely, because the browser enforces a per-origin quota whatever the file says. And if your subtitles are ASS with animation or karaoke, check the file first, since complex inline effect tags are simplified on the way through.
Frequently asked questions
How does subtitle-translator keep my timecodes safe?
Timecodes, cue numbers, ASS headers and WebVTT cue identifiers are extracted in your browser, and only dialogue text is sent to the translation engine, so the model never sees the timeline and reassembly happens locally by position. WebVTT note, style and region blocks are skipped rather than translated as dialogue.
Is subtitle-translator really client-side?
The readme says everything runs in the browser and that API keys never touch a server, but it also says providers blocked by browser CORS are routed through a relay whose built-in deployment works out of the box, and the dependency list includes the official DeepL client library for Node. The file tells you to point the relay address setting at your own deployment of the relay worker.
Which translation engines does subtitle-translator support?
Eight traditional machine translation engines and 27 language model providers and gateways, made up of seventeen named providers, nine named gateways and any OpenAI-compatible custom endpoint. The two engines that need no configuration are rated lowest in the table for both quality and stability and are described as free and rate-limited, and each is the other's fallback.
Does subtitle-translator have a command line?
Yes, invoked as a package script that runs the same engine, parsers and cache from a terminal. The package manifest implements it as a TypeScript file executed through a TypeScript runner, with no installed command entry, so it needs the repository and its dependencies rather than a global install.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rockbenben-subtitle-translator)Star history chart for your README
[](https://hysenlabs.com/projects/rockbenben-subtitle-translator)Was this useful?