ICM shares one SQLite file across eighteen tools and hides its vector runtime
Permanent memory for AI agents. Single binary, zero dependencies, MCP native.
At a glance
- What is it?
- A memory layer for coding agents with three separate memory models and a single database every configured tool reads. Its package-manager build silently drops semantic search, and its maintainer says the focus is elsewhere.
- Who is it for?
- Use ICM if your problem is re-explaining context every time you switch agents, since one shared database fixes that more cleanly than per-tool memory would, and start with keyword search because that path needs no runtime at all. Before you rely on vector recall, check which build you installed, since the package-manager build omits the runtime and falls back to keywords in non-interactive contexts like hooks and CI.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
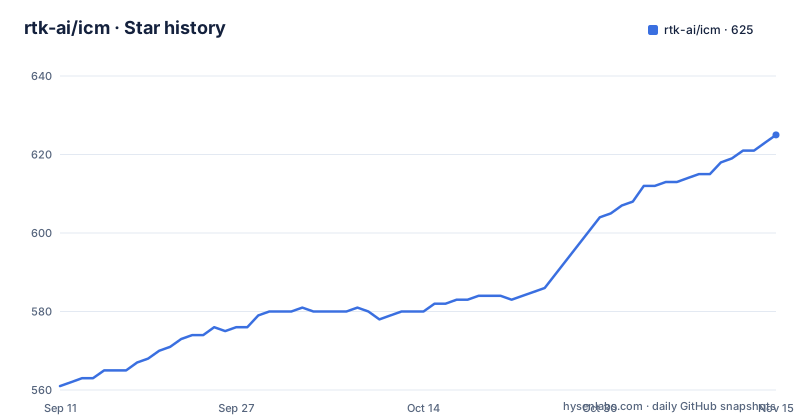
- rtk-ai/icm625 ★ · +64
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| rtk-ai/icm | 561 | 625 |
64 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Memories forget, memoirs do not, and feedback is separate
The diagram names three models rather than one, and they differ in how they lose information. Memories are stored and recalled with temporal decay by importance: critical memories never fade, low-importance ones decay on their own, and you filter them by topic or keyword. Memoirs are the opposite: permanent knowledge graphs where concepts are joined by typed relations, with three named examples being a dependency relation, a contradiction relation and a supersession relation, filtered by label. Feedback is a third channel rather than a fourth kind of memory: it records corrections when a prediction turns out wrong, and the stated use is to search past mistakes before making new predictions. The design point is that the three answer different questions. Memories answer what happened recently, memoirs answer how concepts relate, and feedback answers what to avoid repeating.
The integration is one file at a standard path
The claim the project leads with is that you stop re-explaining context when you switch tools, and the mechanism is deliberately minimal. Every tool you configure with the init command reads and writes the same SQLite database, stored at the operating system's standard location for application data, with one path given for Linux, one for macOS and one for Windows. The consequence is that a store from one tool is immediately visible to the others, a recall from any tool searches the same corpus, and topics are global rather than partitioned per tool. So the integration cost is one file that several unrelated programs agree to open. The topic names in the examples are ordinary English slugs rather than identifiers, which is what makes them shared: a decisions prefix for one project, a preferences topic, and an errors-resolved topic that a later session searches after hitting a similar problem.
Per-project isolation scopes the database and nothing else
If sharing everything is too coarse, three switches narrow it. You can pass an explicit database path, set an environment variable, or use the init command with a per-project flag. The per-project mode writes a project-local configuration file at the git root, so every command run from inside the project picks up the isolated database automatically without a flag on each call. Each distinct path is an independent corpus, which is the property that makes the choice meaningful. The detail worth knowing is what per-project does not change. Global settings, meaning the configured tool list and the installed hooks, are unaffected; only the database is scoped. So a per-project install still rewrites the same eighteen tools configuration files, it just points them at a different file to read and write. That is a reasonable design if you want one set of integrations and many memory corpora.
The package-manager build has no vector runtime, and it says so
Keyword search works immediately. Semantic search needs an inference runtime, and whether you have one depends on how you installed. The prebuilt release archives and the install script bundle it, so there is nothing to do. The package-manager build ships without it, because that build runs in a sandbox with no network access, and it offers a one-time download on first use in a terminal:
# Explicitly enable semantic search (downloads onnxruntime ~7 MB, one time)
icm embeddings download

# Check the runtime state
icm embeddings status
If you decline, or if you are in a context with no terminal prompt at all, which the documentation names as an MCP server, a hook, or continuous integration, the tool stays keyword-only until you run the download explicitly. If you already have a runtime, you can point an environment variable at a library of a specific minor version. The sizes are not symmetric: roughly seven megabytes on the four Unix targets and roughly sixty-five on Windows, because the Windows artefact is a different package format.
Eighteen tools, and the table shows twelve different shapes
One command configures eighteen tools, and the integration table shows how little that sentence means. Most entries get an MCP server and a CLI instructions file, but the configuration file itself differs per tool: a JSON file in the home directory for some, a TOML file for one, a path under the platform application-support directory for the editor, and a storage location inside the editor for two more. Hook counts vary from none to five, and one tool's hooks are explicitly opt-in with an issue reference attached, which tells you that integration was added ahead of full support. Two tools get slash commands instead, two get rule files, and the rest get nothing beyond the server and the instructions file. Two entries have no MCP at all, relying on the CLI path. So the real shape of this feature is a twelve-row table of heterogeneous edits to other people's configuration files, presented as a single command.
The release profile trades unwind safety for size
The build profile is worth reading because the choices are deliberate and visible. Optimisation is on, link-time optimisation is on, the code generation unit count is set to one, panics abort, and symbols are stripped. The two that change behaviour rather than size are the single codegen unit, which serialises compilation in exchange for better cross-unit optimisation, and the panic setting. Aborting on panic removes the unwinding machinery, which makes the binary smaller and the failure path faster, but it removes the ability to catch a panic. Any dependency that recovers from a panic rather than letting it propagate will behave differently. Neither is wrong for a single binary distributed as a release archive, and both are things to know before you file a crash report, because an aborting binary leaves you with no stack. Debug builds are unaffected.
Two embedding backends, selected per workspace member
The dependency list carries comments that are really design notes, and two of them explain the whole distribution story. The embedding library is declared with its default features switched off specifically so that each workspace member picks its own runtime backend: one member wants a static build that downloads binaries, another wants dynamic loading so the crate can be built inside a package manager's isolated environment, and an issue number is attached to that split. A model hub dependency is then added back per feature rather than globally. The second comment is narrower. The archive library is pulled in because the runtime artefact on Windows ships as a zip rather than a tarball, and that artefact uses exactly one compression method, so the dependency exists solely to read that one file. Between them the two comments explain why a single static binary and a package-manager build have different dependency graphs, which is the underlying reason for the semantic search gap in the previous section.
The maintainer says the focus is on a different repository
The status note at the top of the documentation is unusually direct, and it is about maintenance rather than quality. The project is pre-1.0 and under active development, breaking changes can land in any minor release, and the hook and MCP configuration formats may shift. The maintainer then adds the qualification that matters for adoption: they use it daily as their primary memory layer, and describe it as experimental in API stability rather than in day-to-day usefulness. Those are different claims and the second is the one to test. The cadence claim is the part to plan around. Their stated focus is currently on a different repository, this one's updates are merged on a best-effort cadence, and issues and pull requests may take longer to review than usual. The licence ships as-is with no warranty, and the one operational rule given is to run the read-only uninstall check before any destructive operation.
Editorial conclusion
Use ICM if your problem is re-explaining context every time you switch agents, since one shared database fixes that more cleanly than per-tool memory would, and start with keyword search because that path needs no runtime at all. Before you rely on vector recall, check which build you installed, since the package-manager build omits the runtime and falls back to keywords in non-interactive contexts like hooks and CI. And read the maintenance note before adopting it: the maintainer states their focus is on a different project and that updates here land on a best-effort cadence.
Frequently asked questions
What is RTK for AI?
The README links to it as the maintainer current focus and does not describe it further. What it does describe is ICM itself: permanent memory for AI agents, distributed as a single binary with no dependencies and speaking the Model Context Protocol natively.
What does an RTK proxy do?
The README does not say. It links to the other repository in the maintenance note as the maintainer current focus, and the rest of the document covers ICM rather than that project.
How do I install ICM?
Five routes: a package manager tap, a quick install script for macOS and Linux that verifies a checksum, a PowerShell equivalent for Windows, a from-source install of the command line crate, and a Nix flake. Re-running the same command upgrades; a version flag pins a release.
What is the difference between memories and memoirs in ICM?
Memories are episodic and decay over time by importance, so critical ones never fade while low-importance ones fade, and they are filtered by topic or keyword. Memoirs are permanent knowledge graphs of concepts joined by typed relations and filtered by label.
Does ICM need semantic search to work?
No. Keyword search works out of the box. Semantic search needs an inference runtime that the prebuilt binaries bundle but the package-manager build omits, and in non-interactive contexts such as hooks or CI the tool stays keyword-only until the runtime is downloaded explicitly.
How do I keep ICM memory separate per project?
Use the per-project init flag, which writes a project-local configuration file at the git root so commands inside the project use a local database automatically. Global settings such as the configured tools and hooks are unaffected; only the database is scoped.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rtk-ai-icm)Star history chart for your README
[](https://hysenlabs.com/projects/rtk-ai-icm)Was this useful?