DeepAgent's headline demo states that its API responses are simulated
[WWW‘26 Oral🔥] DeepAgent: A General Reasoning Agent with Scalable Toolsets
At a glance
- What is it?
- DeepAgent is a research agent from a university group, published as a conference oral, that argues against predefined reasoning loops and compresses its own context when exploration stalls. The page is unusually candid about the one thing that would let a reader overrate it: the tool responses in its main demonstration are written by a language model, and the same kind of simulator is part of how the agent is trained.
- Who is it for?
- Read this as a paper with code attached, which is what it is, and which is a reasonable thing to be. The argument against fixed reasoning loops and the memory folding mechanism are both interesting, and the fact that the authors put the simulation caveat in italics on the front page rather than in a footnote is a good sign about how they will report the rest.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
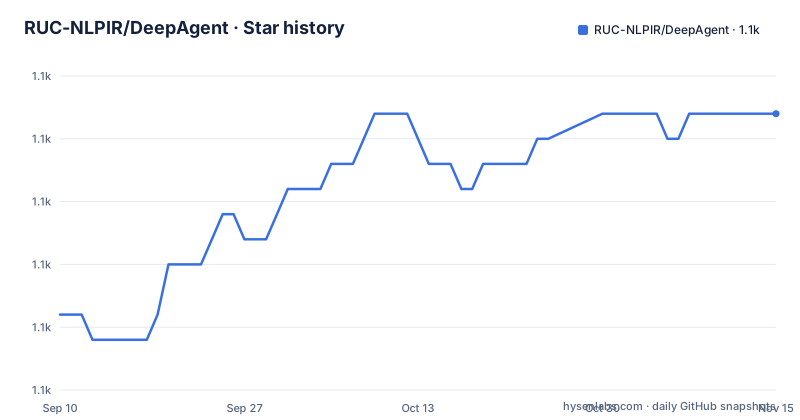
Star history
- RUC-NLPIR/DeepAgent1,146 ★ · +8
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| RUC-NLPIR/DeepAgent | 1.1k | 1.1k |
8 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The main demonstration simulates the tool responses
The first thing on the page is a demonstration of a general agent task searching a toolset of more than sixteen thousand real-world APIs. Underneath the video there is a note, in italics, saying that because some of the APIs in that benchmark are unavailable, the API responses in the demonstration are simulated by a language model in order to show the system's normal functionality.
Read carefully, that removes the number from the demonstration. What the video shows is the agent finding an appropriate tool in a large catalogue and reasoning over the sequence of calls. What it does not show is the tools returning anything.
The disclosure is in the right place and phrased in the right way, and it is worth saying that plainly before criticising anything else on the page. Most projects of this kind would have shipped the video without the note, and a reader would have taken the sixteen thousand figure as a demonstrated capability.
The consequence is narrower than it first looks. A demonstration with simulated responses can still support a claim about tool selection and about the shape of the reasoning, because that is what is being simulated around. It cannot support a claim about handling a real API that times out, returns a schema error, or answers with something the agent has to reject. Nothing else on the page addresses that case.
The benchmark with sixteen thousand APIs is the one you cannot run
The general tool use evaluation is built from four benchmarks, and the tool counts run from tens to over ten thousand, which is the point the paper is making about scale.
The largest is the one with the sixteen thousand real-world APIs requiring multi-step, multi-tool reasoning. The second has seventy-three APIs across three hundred and fourteen human-annotated dialogues. The third simulates REST applications with two concrete services of fifty-four and forty tools. The fourth is the interesting one: nearly four thousand tools that are locally executable, where the task requires three to seven sequential calls.
So the evaluation of scalability splits in two. One half is real services, some of which are not available, which is why the demonstration had to simulate them. The other half is simulated services that always answer.
The locally executable benchmark is the harsher test per call and the more artificial one, because a tool that always responds with well-formed output teaches an agent a world in which that is true. Neither half is wrong; both are necessary, since real APIs are the only source of realistic failure and are also the only half you cannot depend on. The honest summary is that the scale claim is supported by simulated tools and the realism claim by unavailable ones, and the page does not claim otherwise.
Downstream tasks are separate: a text embodied household environment, a web shopping environment, a general assistant benchmark, and an exam suite.
The agent decides when to compress its own context
The second contribution is a mechanism for long interactions, called memory folding. When the agent faces a problem it can trigger a fold that compresses its interaction history into a structured schema and then restarts its reasoning from the condensed version. The page describes this as taking a breath.
The schema has three parts. A high level log of key events, decisions and completed sub tasks. The working part, holding the most recent information including the current sub goal and near term plans. And a tool part that consolidates tool interactions so the agent can learn from them.
What deserves attention is who decides. The trigger is autonomous: the agent folds when it judges it should, not when a scheduler or a token limit says so. And the stated purpose is to prevent getting stuck on an incorrect exploration path, which is precisely the moment when the history is most confusing and the original constraints are furthest from view.
So the failure mode is specific and worth naming. A fold that drops the constraint that mattered, at the moment the constraint mattered most, produces an agent that confidently restarts on a wrong premise. The page describes the schema and the trigger but says nothing about how much is retained, how many folds are permitted, or what is protected from being compressed. For a research artefact that is a reasonable amount to leave out, and for anyone building on it, those three questions are the ones to ask.
One simulator serves both the training and the demonstration
The third contribution is a training method, an end-to-end reinforcement learning approach for general tool use, with two named parts. The first is a tool simulator built from a language model, which stands in for real APIs so training is stable and efficient. The second is an attribution step that assigns fine-grained credit to the tokens that invoked the correct tool, which gives a sharper learning signal than crediting the whole trajectory.
Put the training method next to the demonstration note and the pattern is clear. The same idea, a language model standing in for a tool, is load-bearing in both places: it makes training feasible because a real API is slow, flaky and rate limited, and it makes the demonstration possible because some of the real ones are down.
That is coherent engineering. It also means there is no independent check anywhere on the page. A policy trained against a simulator learns that simulator's behaviour, including the ways in which it is more predictable than a real service, and the demonstration cannot be used to audit that, because it was made with the same kind of component.
The attribution step is the part a reader can reason about most easily. Crediting the invocation tokens rather than the whole trajectory is the right instinct for tool use, where a long trajectory is mostly waiting and a single wrong call ruins it. Whether the credit assignment survives a multi-step task where the right tool depends on an earlier call is what the ablation would answer, and there is no ablation on the page.
Thirty dependencies, one of them pinned, and nothing to install
The installation section is a conda environment and a requirements file:
conda create -n deepagent python=3.10
conda activate deepagent

cd DeepAgent-main
pip install -r requirements.txt
That file is worth reading as an artefact.
It lists about thirty packages and exactly one of them carries a version bound. Everything else is unpinned, including the model library, the transformer library, the sentence embedding library, the client libraries for three hosted services, and the document parsers. A research repository pinning nothing is common; a research repository pinning exactly one thing is a signal that somebody hit a break once.
There are also three overlapping pairs. Two PDF parsers, two office document libraries, and two fuzzy matching libraries where one of them depends on the other. Plus a large inference engine and an embodied benchmark environment as install-time requirements, neither of which an inference deployment needs and both of which are large.
The gap below that is the real one. The repository root has eight entries and none of them is a packaging file: no pyproject, no setup file, no environment definition. So the project cannot be installed as a package, only entered as a source directory.
And the install instructions change directory into a name with a suffix that a git clone does not produce. A clone gives you the repository name; a ZIP download gives you the name plus a suffix. The documented path assumes the ZIP, on a page whose own links point at a hosted repository.
No releases, no tests, and six months of silence
The news log is four entries and reads like a launch, because it is one. The codebase and the paper were released on the same day in late October 2025. The paper was featured as the top daily paper of the following day. It was accepted as an oral paper at a web conference in January 2026, which is where the description's claim comes from.
Then nothing. The last push to the default branch is dated 2026-04-13, and the newest news entry is from January. The repository publishes no releases at all, so there is no version to install and no way to tell one state of the code from another.
The root is worth enumerating for what is missing rather than what is in it: a licence, the readme, and six directories for configuration, data, documentation, figures, requirements and source. There is no test directory. For a project whose headline capability is that it can be pointed at an unfamiliar toolset of thousands of entries and pick the right one, a test suite would be the natural place to demonstrate that, and there is not one in the tree.
The datasets are published on a model hub under a personal account while the code sits under the research group's organisation. Splitting them like that is easy to do and easy to forget, and it means the two halves of a citation do not share an owner.
Most of the demand for the name is somebody else's product
The last thing worth saying is about finding this at all.
The queries attached to this repository are dominated by questions that are not about it. They ask what a DeepAgent is and how good it is, and they also ask how much a DeepAgent costs per month, whether it is free, and what an Abacus DeepAgent is. There is a commercial product of that name, and the pricing questions are about it.
The rest splits between integration questions about a specific orchestration library, a specific command line agent and a specific graph framework, plus questions about whether this tool has a user interface, a command line, or a JavaScript version. Those may be people evaluating it. The pricing questions are people looking for something else entirely.
That has a practical consequence for anybody who lands here. The name is contested enough that a reader who finds the repository by search is a minority case. The reliable identifiers are the paper identifier, the conference page and the dataset link, and a citation that wants to be unambiguous should use those rather than the product name.
It is also the pattern that makes this repository worth reading. A well-known name, a paper with a real contribution and a codebase released the same afternoon, with no version, no tests and no packaging.
Editorial conclusion
Read this as a paper with code attached, which is what it is, and which is a reasonable thing to be. The argument against fixed reasoning loops and the memory folding mechanism are both interesting, and the fact that the authors put the simulation caveat in italics on the front page rather than in a footnote is a good sign about how they will report the rest. Three things to know before you build on it. The simulated responses mean the demonstration cannot tell you whether the agent survives a real API returning an error, and nothing else on the page speaks to that. The memory folding is triggered by the agent at the moment its history is least legible, so the failure mode to worry about is losing the constraint that mattered. And there is nothing to pin: no releases, no packaging file, no tests directory, and a requirements list with a single version bound across thirty packages.
Frequently asked questions
What is DeepAgent?
It is a research agent that performs autonomous thinking, tool discovery and action execution in a single reasoning process, departing from predefined loops of reasoning, acting and observing. It comes from a university research group, its paper appeared as an oral at a web conference in January 2026, and the code and datasets were released in October 2025.
Does DeepAgent really call sixteen thousand APIs in its demonstration?
No. The page states that some of the APIs in that benchmark are unavailable and that the API responses in the demonstration are simulated by a language model, in order to show the system's functionality. The demonstration therefore shows tool selection and the reasoning loop rather than real API results.
What is memory folding in DeepAgent?
A mechanism the agent can trigger on its own to compress its interaction history into a structured schema and restart its reasoning from a condensed version, described as a way to avoid getting stuck on an incorrect exploration path. The memory has three parts: a high level log of events and decisions, the current sub goal with near term plans, and a consolidated log of tool interactions.
How is DeepAgent trained?
With an end-to-end reinforcement learning method for general tool use. It uses a language model based tool simulator that stands in for real APIs so training is stable and efficient, plus a tool call advantage attribution step that assigns fine-grained credit to the tokens that invoked the correct tool.
What do I need to install to run DeepAgent?
A conda environment on Python 3.10 and the requirements file, which lists about thirty packages with a single version bound and includes an inference engine, a benchmark environment, two PDF parsers and two fuzzy matching libraries. The repository has no packaging file, so the project is entered as a source directory rather than installed.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ruc-nlpir-deepagent)Star history chart for your README
[](https://hysenlabs.com/projects/ruc-nlpir-deepagent)Was this useful?