ParseBench is published by the team whose product takes first, second and fourth
ParseBench - A Document Parsing Benchmark for AI Agents
At a glance
- What is it?
- About two thousand human-verified pages of real insurance, finance, and government documents, split into five dimensions chosen because each one breaks a different kind of agent workflow. The metrics are specific, the dataset is on a public hub, and the inclusion rules are stated up front. The thing to weigh as you read the table is that three of the top ten entries come from the organisation that publishes the benchmark.
- Who is it for?
- Use it if you are choosing a parser for an agent that has to read a value out of a table, since that is the failure mode the benchmark was built around and the per-dimension scores show where a provider is weak. Read the leaderboard with the ownership in mind, and discount it accordingly.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
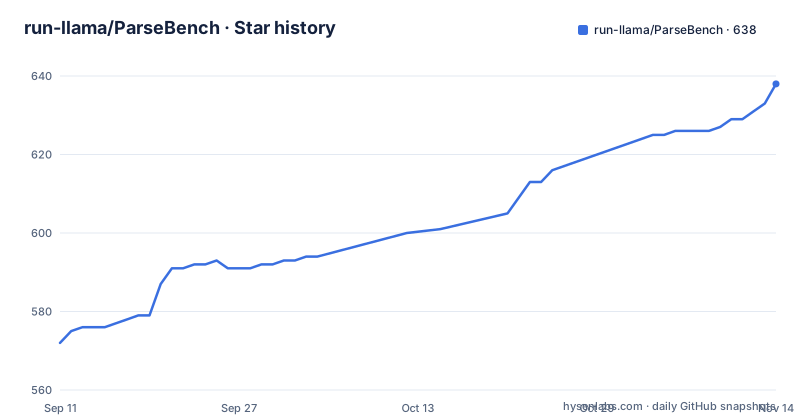
- run-llama/ParseBench638 ★ · +66
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| run-llama/ParseBench | 572 | 638 |
66 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The maintainer's own product holds three of the top ten places
The organisation that publishes the benchmark also sells a parsing product, and that product appears three times in the table: first, second, and fourth, with the top score at just over ninety and the fourth at just over eighty. The best entry from any other provider sits in third place, roughly nine points behind the leader. Everything else in the table is grouped by category rather than by vendor: a commercial startup group, a proprietary vision-language group, and an open-weight group. Nothing about the methodology is hidden. The scores, the per-page costs, the raw data as a comma-separated file at the repository root, and a sortable version on the project site are all public, and the leaderboard block in the README sits between markers that indicate it is generated. What the ownership means is that you should read the ordering as a starting hypothesis rather than a result.
The cost column mixes measured prices with blanks
Each row carries a per-page cost, which is the most useful column and the least rigorously defined. Commercial entries have figures from under half a cent to more than sixteen, and the relationship to score is not monotonic: the seventh-placed entry costs nearly three times the leader and scores slightly lower, while the fourth-placed entry is the cheapest of the top ten at under four tenths of a cent. Two rows show a dash instead of a number, and both are open-weight or self-hosted entries, where the per-page cost exists but depends on hardware you choose. So the column mixes a measured marginal price with a value the reader has to supply, and an em dash reads as free rather than as unknown. Cost is the dimension a procurement decision turns on, and it is the one the benchmark measures least rigorously.
One model appears twice, and reasoning effort is worth three tenths of a cent
Two rows are the same proprietary model at different reasoning effort, and comparing them is the most informative pair in the table because everything else is confounded by model and vendor. The higher-effort configuration scores better on every single sub-metric and costs three tenths of a cent more per page. One sub-metric is identical between them, which suggests the formatting ruleset saturates for this model regardless of effort. The broader pattern is that the effort setting moves scores by a point or two rather than transforming them, at a cost premium of roughly twenty percent. For anyone choosing a configuration, that is a more actionable finding than the ranking: effort buys a modest improvement at a proportional price, and the chart and layout dimensions are where it helps most.
The inclusion rules exclude anything needing a framework change
Three criteria decide who appears. The model or service must be reachable through open weights or a self-serve sign-up. The full run has to finish in roughly single-digit hours. And the provider must not require custom framework changes, with concurrency adjustable to whatever the provider recommends. That third rule is the consequential one. It is a reasonable definition of fairness, since a bespoke integration makes the comparison about the harness rather than the parser, and the harness clearly does work to adapt providers fairly. It also means the products built for exactly the enterprise layouts this benchmark measures are structurally unable to enter, which is the same population that a large insurance or finance buyer would actually shortlist.
Two thousand pages, reused unevenly across five dimensions
The dataset table is the part worth studying, because the design choices are legible in the counts. Getting the harness installed is two lines, and the choice between them is which providers you intend to run:
pip install "parse-bench[runners]"          # every provider SDK
pip install "parse-bench[llamaparse]"       # or just one, e.g. llamaparse / openai / anthropic / google
Beyond that, what the table shows is worth studying, because the design choices are legible in the counts. The stated unique total is just over two thousand pages across just over one thousand two hundred documents, and the five dimensions add up to more than that because two of them share the same underlying text documents and are scored with different rule sets. The reuse is uneven in a way that affects interpretation. The text dimensions have roughly one page per document, so they measure many short documents. Charts has more than five pages for every document, and tables and layout sit in between. The rule counts are even more uneven: over a hundred and forty thousand for faithfulness, sixteen thousand for layout, under six thousand for formatting, under five thousand for charts, and none at all for tables, which uses a continuous metric instead of discrete rules.
Three markdown parsers in one metric harness
The dependency list explains the rule counts. Alongside a tree-edit-distance library used for the table metric, the harness depends on three separate markdown parsers, an HTML sanitiser, two HTML parsers, a transliteration library, two string-similarity libraries, and a fuzzy-matching library. That is a lot of overlapping normalisation machinery, and it is there because rule-based scoring needs to compare text that has been through different pipelines and still agree on what a heading or a list item is. The risk is that two of those parsers disagree about the same document, which turns a parser's output error into a normalisation artefact and vice versa. The table metric itself gets an optional accelerator that compiles the edit-distance computation ahead of time, with the explicit promise that scores are identical either way.
The leaderboard exists twice, once in prose and once as a file
The README table sits inside start and end markers with a note that it shows the top ten by overall score and points elsewhere for the rest, and a machine-readable version of the same data is committed at the top of the repository. That is the right shape for a benchmark: humans read the table, tools read the file, and the markers make it clear the table is generated rather than maintained by hand. Two consequences follow. Anyone who wants the full field has to leave the repository, since ten of a hundred and eighty-plus pipelines is a small sample, and the sample is the interesting part. And a published score in the table is a claim about a specific run on a specific dataset version, with no run identifier, date, or configuration recorded alongside it in the file.
Three releases in three hours, then nothing for four weeks
The release history is three patch versions published inside a three-hour window on one day, followed by a month of commits with no further release. The repository is clearly active, since the last push was the day before this, but the packaged versions stopped moving. For a harness whose value depends on staying aligned with the services it calls, that gap matters more than it would for a library: providers rename pipelines, change model identifiers, and adjust their request shapes, and those changes break runners rather than producing a deprecation warning. The version is also declared dynamic in the packaging metadata rather than written down, and the package requires a recent Python floor and supports only two interpreter versions, so the surface for something to drift is small but the cost when it does is a confusing failure.
Editorial conclusion
Use it if you are choosing a parser for an agent that has to read a value out of a table, since that is the failure mode the benchmark was built around and the per-dimension scores show where a provider is weak. Read the leaderboard with the ownership in mind, and discount it accordingly. What survives that discount is the dataset design, which is the reusable asset here: the five dimensions, the public split, and the rule counts are all published, so you can score a parser the same way rather than trusting a vendor's chart.
Frequently asked questions
What is ParseBench?
A benchmark for evaluating how well document parsing tools convert PDFs into structured output that an AI agent can act on. It covers about two thousand human-verified pages from real enterprise documents in insurance, finance, and government, organised around five capability dimensions, each targeting a failure mode that breaks production agent workflows.
What are the five dimensions ParseBench scores?
Tables, scored with a metric combining grid similarity and record matching over 503 pages; Charts, scored on exact data point extraction over 568 pages; Content Faithfulness, covering omissions, hallucinations, and reading-order violations over 506 pages; Semantic Formatting over 476 pages; and Visual Grounding, scored as an element pass rate over 500 pages. The dataset totals 2,078 unique pages and 1,211 documents.
How do I run ParseBench myself?
Install the package with every provider extra, or a single provider extra, or sync from a checkout with the runners extra, and put the API key for the tool you want to evaluate in an environment file, which the command line loads automatically on startup. An optional extra adds a compiled table metric that is faster on large tables and produces identical scores.
How many pipelines can ParseBench evaluate?
More than 180, listed in the documentation or queryable from the command line. The paper baselines are 21 of them, and the pipeline names encode the model variant, with separate entries for reasoning effort levels and for thinking enabled versus disabled on the same underlying model.
Who can appear on the ParseBench leaderboard?
The rules require public accessibility through open weights or a self-serve API, a full run finishing in roughly single-digit hours, and no custom framework changes needed to run the provider. Entries are grouped by category, from the maintainer's own product through commercial startup APIs and proprietary vision-language models to open weights, and each row carries sub-scores plus a per-page cost.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/run-llama-parsebench)Star history chart for your README
[](https://hysenlabs.com/projects/run-llama-parsebench)Was this useful?