Scraper: every example unwraps, and Send sits behind a feature flag
HTML parsing and querying with CSS selectors
At a glance
- What is it?
- scraper is a thin Rust interface over Servo's html5ever and selectors crates for parsing HTML and querying it with CSS selectors. Its examples are short and readable, and none of them shows an error path or a thread.
- Who is it for?
- scraper is the right crate when the parser has to agree with a browser about malformed markup, because the html5ever and selectors pair is the same code path Firefox uses rather than a regex dressed up as a parser. Read the fragment and document examples first, since the difference decides whether implied html and head elements appear in your output.
- Can I use it commercially?
- Yes. ISC is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
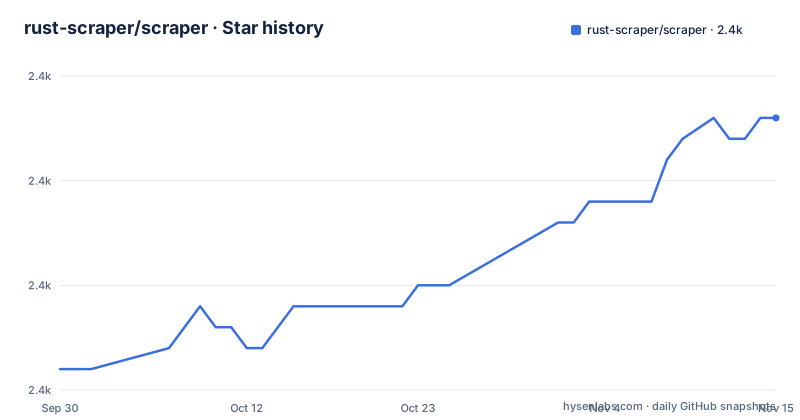
Star history
- rust-scraper/scraper2,433 ★ · +12
| Repository | 2026-09-30 | 2026-11-15 |
|---|---|---|
| rust-scraper/scraper | 2.4k | 2.4k |
12 Stars in the last 46 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
parse_document fills in the elements the input never mentioned
Two entry points do different things to the same markup. The document parser is given a string with a doctype, a meta charset and a title:
use scraper::Html;

let html = r#"
    <!DOCTYPE html>
    <meta charset="utf-8">
    <title>Hello, world!</title>
    <h1 class="foo">Hello, <i>world!</i></h1>
"#;

let document = Html::parse_document(html);
The fragment parser is handed a bare heading with no surrounding page at all. That distinction is not cosmetic, because a document is normalised into a full tree whether or not the input spelled it out. The clearest evidence on the page is the DOM editing example further down, which feeds in a string containing no head element at all and then asserts on a document that has gained an empty one. Fragment parsing is what the remaining examples use, and it leaves the markup as given.
text() hands back one borrowed piece per text node
Extracting text is not a single string operation. The method returns an iterator whose items are the individual text runs inside the matched element:
use scraper::{Html, Selector};

let fragment = Html::parse_fragment("<h1>Hello, <i>world!</i></h1>");
let selector = Selector::parse("h1").unwrap();

let h1 = fragment.select(&selector).next().unwrap();
let text = h1.text().collect::<Vec<_>>();

assert_eq!(vec!["Hello, " , "world!"], text);
Two entries come back for one heading, and the first keeps its trailing space, because the run ends where the italic tag begins. Nothing on the page joins them, so a caller who wants one clean string has to collect and concatenate the pieces itself. The lifetime of those pieces is tied to the fragment, which is why the vector is built inside the same scope as the parse.
html() returns the element, inner_html() returns only what is inside it
Serialising a match comes in two shapes, and the difference shows up in the first characters of the result:
assert_eq!("<h1>Hello, <i>world!</i></h1>", h1.html());
assert_eq!("Hello, <i>world!</i>", h1.inner_html());
The first keeps the matched tags in the output and the second drops them, so a caller who round-trips a subtree has to choose which of the two shapes survives. Together with the text behaviour above, a single element has three distinct extraction modes, and the page gives one assert line for each. Attributes are read separately again, and the lookup returns an Option so a missing attribute and an empty one are told apart:
use scraper::{Html, Selector};

let fragment = Html::parse_fragment(r#"<input name="foo" value="bar">"#);
let selector = Selector::parse(r#"input[name="foo"]"#).unwrap();

let input = fragment.select(&selector).next().unwrap();
assert_eq!(Some("bar"), input.value().attr("value"));
The attribute is matched by putting it inside the selector itself rather than by filtering afterwards, so the element reference points at the tag and the value comes off it. The element name, by contrast, goes through value().name(), which is how the nested example checks that every match really is an li.
Every snippet unwraps, so no failure path is ever shown
Selector parsing and element lookup are both wrapped in unwrap() in every example on the page, including the two-line fragment case:
use scraper::Selector;
let selector = Selector::parse("h1.foo").unwrap();
The same pattern repeats wherever a selection is read, with `.next().unwrap()` on the iterator. The consequences for anyone extending these snippets are concrete: a selector string that does not parse, or a document in which the selector matches nothing, ends the program at that line instead of producing a value to inspect. Nothing here returns a Result, and the page names no error type, so a caller who needs to survive bad input has to add the match handling around these calls rather than follow the pattern being demonstrated. Nested selection is shown the same way, walking from a ul to its li children and asserting on each element name. The compound selector in the parsing section is the only place a class and a tag are combined, and it is compiled once and reused, which separates the cost of parsing a selector from the cost of running it across a document.
DOM edits need node ids collected before the sink takes the document
Removing an element is not a method on the selected element. The example reaches for the html5ever tree builder and scraper's own sink type:
use html5ever::tree_builder::TreeSink;
use scraper::{Html, Selector, HtmlTreeSink};

let html = "<html><body>hello<p class=\"hello\">REMOVE ME</p></body></html>";
let selector = Selector::parse(".hello").unwrap();
let mut document = Html::parse_document(html);
let node_ids: Vec<_> = document.select(&selector).map(|x| x.id()).collect();
let tree = HtmlTreeSink::new(document);
for id in node_ids {
    tree.remove_from_parent(&id);
}
let document = tree.finish();
assert_eq!(document.html(), "<html><head></head><body>hello</body></html>");
The ordering is the mechanism worth noticing. Constructing the sink consumes the document, so the ids have to be collected into a vector first while the document is still queryable, and the sink is what gives the document back. That final assert also shows the parser adding a head element to markup that had none.
Sharing a tree between threads turns on the atomic feature
The threading note is the only part of the page that talks about the underlying string type. html5ever uses Tendril as its reference counted string, and the default is the thread-local form, which the page describes as not Send. Enabling a feature flag switches it to the atomic counting version, which implements Send:
[dependencies]
scraper = { version = "0.27.0", features = ["atomic"] }
That declaration pins the version as well as the feature, so the snippet matches the current tag rather than whatever a reader resolves. Nothing else on the page touches concurrency: there is no Send or Sync example, no channel or thread spawn, and no note about which types in the API are affected, only the string representation underneath. The note is also the only place a dependency is written at all, so the examples themselves assume an existing project rather than showing what a manifest looks like.
A one-member workspace, and four months between the last tag and the last push
The repository is a workspace with a single member, so the root manifest is a workspace declaration rather than a package one:
[workspace]
resolver = "2"

members = ["scraper"]
Everything else sits beside it: an editorconfig, a gitignore, a committed Cargo.lock, a LICENSE, and the scraper directory itself, with a .github directory holding the workflow the page badges point at. The licence is ISC and the documentation home is docs.rs. Three tags are listed, v0.25.0 in December 2025, v0.26.0 in March 2026 and v0.27.0 in May 2026, roughly a quarter apart at first. Master was then pushed on 21 September 2026, four months after that tag, so the published crate and the branch have been apart for longer than any of the gaps between the three releases.
Editorial conclusion
scraper is the right crate when the parser has to agree with a browser about malformed markup, because the html5ever and selectors pair is the same code path Firefox uses rather than a regex dressed up as a parser. Read the fragment and document examples first, since the difference decides whether implied html and head elements appear in your output. Two things on the page will bite anyone extending these snippets: every call unwraps, so a selector that fails to parse or matches nothing panics rather than returning an error, and moving a parsed tree to another thread means turning on the atomic feature in the dependency declaration. That declaration also pins 0.27.0, the tag from May 2026, while master has moved on since, so copy the version from your own lockfile instead.
Frequently asked questions
What is the Scraper crate for?
HTML parsing and querying with CSS selectors. It provides an interface to Servo's html5ever and selectors crates for browser-grade parsing and querying.
What is the difference between Html::parse_document and Html::parse_fragment in Scraper?
Parsing a document normalises the input into a full tree, adding implied elements such as an empty head, while parsing a fragment leaves the given markup as it is.
How do I make Scraper values usable across threads?
Enable the atomic feature, which switches html5ever's Tendril strings from the thread-local form to the atomic counting version that implements Send.
Does Scraper return an error when a selector matches nothing?
The page shows no error path. Every example calls Selector::parse with unwrap and reads selections through .next().unwrap(), so both a selector that fails to parse and an empty match stop the program.
How do I remove an element with Scraper?
Collect the matching node ids first, then build an HtmlTreeSink from the document, call remove_from_parent on each id, and call finish to get the document back.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rust-scraper-scraper)Star history chart for your README
[](https://hysenlabs.com/projects/rust-scraper-scraper)Was this useful?