doc-to-lora installs with a curl pipe and loads a checkpoint with weights_only=False
Hypernetworks that update LLMs to remember factual information
At a glance
- What is it?
- Sakana AI's reference implementation of Doc-to-LoRA, a hypernetwork that internalizes a context into a pretrained model, with a Gradio demo, two experiment pipelines and a dependency list that pins five versions. The install is two shell commands and the demo checkpoint is unpickled in the unsafe mode.
- Who is it for?
- This is a research reference implementation, and it is written like one: two shell commands, two experiment pipelines, a Gradio demo, and no releases. Four things to check before you build on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 152 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
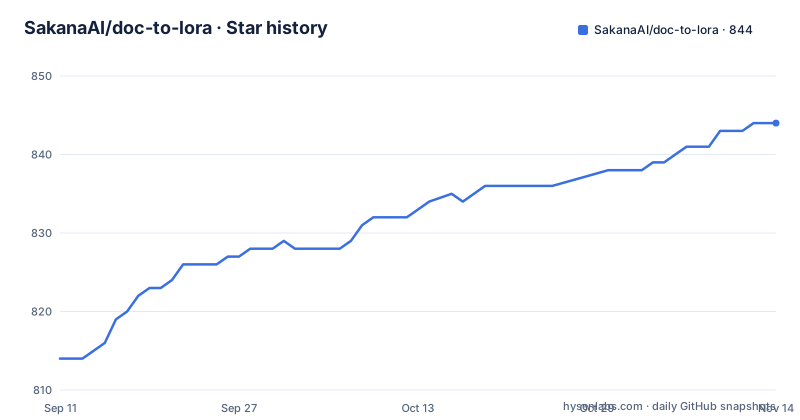
- SakanaAI/doc-to-lora844 ★ · +30
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| SakanaAI/doc-to-lora | 814 | 844 |
30 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Installation is a piped curl followed by an undocumented script
The entire installation section is two lines:
curl -LsSf https://astral.sh/uv/install.sh | sh
./install.sh
The first line fetches the uv package manager installer over the network and executes it in the current shell, with no checksum and no review step. The second is a script in this repository, and the README does not say what it does, what it installs or what it writes.
So the toolchain choice is stated plainly: uv, which then appears in every other command as `uv run`. That is a reasonable choice for a research repo where the lockfile is the contract, and `uv.lock` is at the top level, but it is worth reading `install.sh` before running it, and worth knowing that the first line already executed code you did not read.
The demo checkpoint is loaded with weights_only=False
The Python API example is short enough to read closely, and one line in it is worth stopping on:
checkpoint_path = "trained_d2l/gemma_demo/checkpoint-80000/pytorch_model.bin"
state_dict = torch.load(checkpoint_path, weights_only=False)
`weights_only=False` is the mode where torch restores the full Python object graph from the file, which is how pickle-based checkpoints can execute code on load. The default in current torch releases is the safe mode, so this line opts out of it deliberately, and the file it points at is one the previous step downloaded from Hugging Face:
uv run huggingface-cli login
uv run huggingface-cli download SakanaAI/doc-to-lora --local-dir trained_d2l --include "*/"
Read those two steps together and the trust chain is clear. Log in, download, then unpickle. Fine for your own checkpoint, which is what step 80000 of the Gemma demo presumably is, and not something to point at a directory somebody else produced. The snippet is also cut off mid-line, at `tokenizer = get_tokenizer(model.base_model.name`, so the rest of the loading sequence is not shown.
The distribution is ctx-to-lora 0.0.1 with an empty description
Three names are in play. The repository and the paper are Doc-to-LoRA, abbreviated D2L. The importable package is `ctx_to_lora`. The distribution in pyproject.toml is `ctx-to-lora`, at version 0.0.1, with the description field left empty.
The license is the one uncomplicated thing: MIT, with a `LICENSE` file at the top level. The citation points at the Forty-third International Conference on Machine Learning for 2026, by Rujikorn Charakorn, Edoardo Cetin, Shinnosuke Uesaka and Robert Tjarko Lange, with the paper on arXiv as 2602.15902 and an OpenReview forum id given in the BibTeX block. The paper title itself is written as Lo{RA} in that block, to stop the name being case-folded by a bibliography tool.
Python 3.10 or later is required. And there are two build files: a pyproject.toml with a setuptools build backend, plus a setup.py that reads the README and hands it to setup() as the long description. The second one is a metadata shim left over from the older build path, not a second build system in use.
One experiment downloads its data, the other generates it
Both experiment pipelines are driven the same way: run `uv run $PATH_TO_SCRIPT` from the repository root, and run the numbered scripts in order. The differences are in the table.
The main experiment is `scripts/main_exp/`, with `0-download_data.sh` for data prep, `1-train.sh` for training and an `eval/*.sh` glob for evaluation, and the note that downloading data is the fast path while regenerating is only for when you need fresh synthetic data. Evaluation scripts reproduce the main paper metrics.
The NIAH experiment is `scripts/niah/`, with `0-gen_data.sh`, `1-train.sh` and a single `2-eval.sh`, and the note that data generation only has to happen once. So one pipeline fetches and one generates, and one evaluates through a glob while the other names a single script. Small thing, but it decides whether you can point an evaluation at one variant.
The self-generated data viewer is a third entry point, `uv run webui/self_gen_viewer.py`, documented separately in `webui/SELF_GEN_VIEWER.md`.
Five exact pins, and pre-commit listed as a runtime dependency
The dependency list is the biggest object in the repository. Five entries are exact-pinned: `transformers==4.51.3`, `deepspeed==0.17.1`, `accelerate==1.6.0`, `datasets==3.6.0` and `vllm==0.8.5.post1`. A sixth carries a floor rather than a pin, `gradio>=4.40.0`, and the Hugging Face hub is bounded below as well. Everything else floats, including `peft`, `wandb`, `kagglehub`, `kaggle`, `google-cloud-storage` and `bitsandbytes`.
Two of those are worth noting for what they imply. `kagglehub` and `google-cloud-storage` mean the data path runs through Kaggle and a cloud bucket, and `wonderwords`, `inflect` and `fasttext-wheel` are the vocabulary tools that synthetic data generation needs. `llmlingua` is a context compression library, which suggests the pipeline compresses long inputs somewhere. `rouge-score` alongside `torchmetrics` tells you the evaluation is partly summarization-style.
The smell is `pre-commit`. It appears in `project.dependencies` rather than an optional dev group, and there is also a `.pre-commit-config.yaml` at the top level, so the hook runner ships in the runtime environment of every install.
The pyright exclude list names five other projects
The pyright configuration tells you what has been sitting next to this code. Twenty directories are excluded from type checking, and five of them are other research projects: EditingLlama, icae_v2, lm-evaluation-harness, llm-comparator and LongBench. The rest are ordinary local state, outputs, caches, checkpoints and generated tasks.
A tool that has been run beside five sibling codebases usually grew from experiments that got folded in. That is not a criticism, but it does mean the tree carries a trace of the project's history rather than a clean boundary.
Two settings then soften the tooling further. `typeCheckingMode` is `off`, so pyright is configured to check nothing. And the ruff configuration sets `select = ["F401"]`, meaning remove unused imports, while `ignore = ["E", "F"]` includes the F prefix that F401 belongs to. Ruff applies ignore after select, so those two lines cancel and the effective rule set is empty. Line length is set to 88 and the isort profile is black, so the formatting intent survives even though the lint rules do not.
No releases, and three root directories the README never explains
The GitHub release list is empty. Weights come from the Hugging Face organization instead, through the `huggingface-cli download` line quoted earlier, and the download uses `--include "*/"`, which selects every subdirectory in the repository rather than a named checkpoint folder. There is no size filter, so what lands in `trained_d2l` is whatever the Hugging Face repository holds.
At the top level sit `data/`, `examples/`, `assets/`, `configs/`, `chat_templates/`, `demo/`, `webui/`, `scripts/`, `src/`, plus `train.py`, `run_eval.py`, `watcher.py`, `accelerate_config.yaml`, `uv.lock` and the two build files. The README covers `demo/`, `webui/` and `scripts/`. It says nothing about `data/`, `examples/`, `watcher.py` or `run_eval.py`.
The one demo entry point is `uv run demo/app.py`, and the interactive web build it serves is published separately at pub.sakana.ai. The last push recorded for the repository is 2026-06-15, four months before this snapshot, with no tag attached to it.
Editorial conclusion
This is a research reference implementation, and it is written like one: two shell commands, two experiment pipelines, a Gradio demo, and no releases. Four things to check before you build on it. Trust in the install, since the first command pipes a remote script into a shell and the second is an undocumented `install.sh`. Trust in the checkpoint, since the demo path runs `torch.load(checkpoint_path, weights_only=False)` on a file pulled from Hugging Face, which is arbitrary code execution by design and only safe for a checkpoint you produced. Version pinning, since transformers, deepspeed, accelerate, datasets and vllm are all exact-pinned while `peft`, `wandb`, `kagglehub` and the rest float. And scope, since the convenience Python API handles non-batched inputs only, batched inference lives in `src/ctx_to_lora/modeling/hypernet.py`, and `watcher.py`, `data/` and `examples/` at the repository root are not described anywhere in the README. The paper is arXiv 2602.15902, and the last push was 2026-06-15.
Frequently asked questions
How do I install doc-to-lora?
Run `curl -LsSf https://astral.sh/uv/install.sh | sh` to get uv, then `./install.sh` from the repository root. Every other command in the README uses `uv run`, and Python 3.10 or later is required.
Where do the pre-trained doc-to-lora models come from?
From Hugging Face. You log in with `uv run huggingface-cli login` and then `uv run huggingface-cli download SakanaAI/doc-to-lora --local-dir trained_d2l --include "*/"`. The repository itself has no GitHub releases.
Does the doc-to-lora Python API support batched inference?
Not the convenience interface, which the README flags as supporting non-batched inputs only. Batched inference is in `src/ctx_to_lora/modeling/hypernet.py`. Loading goes through `ModulatedPretrainedModel.from_state_dict` with `train=False` and `use_sequence_packing=False`, followed by `model.reset()`.
Which experiments ship with doc-to-lora?
Two. `scripts/main_exp/` with `0-download_data.sh`, `1-train.sh` and an `eval/*.sh` glob whose evaluation scripts reproduce the main paper metrics, and `scripts/niah/` with `0-gen_data.sh`, `1-train.sh` and `2-eval.sh`. Both are run with `uv run` from the repository root, in order.
What name does doc-to-lora install under?
`ctx-to-lora`, version 0.0.1, with imports under `ctx_to_lora`. The project and paper call the method Doc-to-LoRA, abbreviated D2L, and the license is MIT.
Does the doc-to-lora README explain what LoRA is?
No. It states what the system is, hypernetworks that update a pretrained model so it internalizes a context, and points to the paper on arXiv as 2602.15902 and the ICML 2026 citation. The mechanism itself is not described in the README.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sakanaai-doc-to-lora)Star history chart for your README
[](https://hysenlabs.com/projects/sakanaai-doc-to-lora)Was this useful?