llm-wiki-agent: query answers filed back as pages, and a security pin in the wrong file
A personal knowledge base that builds and maintains itself. Drop in sources — Claude (or Codex/Gemini) reads them, extracts knowledge, and maintains a persistent interlinked wiki. Works with Claude Code, Codex, OpenCode, Gemini CLI. No API key needed.
At a glance
- What is it?
- SamurAIGPT/llm-wiki-agent is a coding agent skill that ingests documents and maintains a self-referential markdown wiki, where the dependency pin that avoids a compromised library lives in a requirements file the project metadata never reads, four supported agent runtimes get slash commands for only one, and query answers are written back into the corpus with no marker distinguishing them from source text.
- Who is it for?
- Use it if you want an agent to hold a growing corpus on your own disk, and read it as a personal workflow rather than a system. Two things to know before you trust the output.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
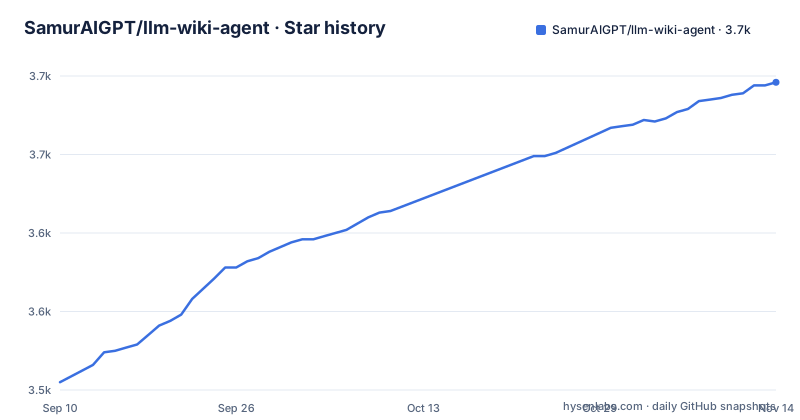
- SamurAIGPT/llm-wiki-agent3,696 ★ · +191
| Repository | 2026-09-10 | 2026-11-14 |
|---|---|---|
| SamurAIGPT/llm-wiki-agent | 3.5k | 3.7k |
191 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Query answers get filed back into the wiki, so the corpus writes into itself
The README describes a persistent wiki with a fixed set of directories, and it prints the layout with one-line descriptions:
wiki/
├── index.md          catalog of all pages — updated on every ingest
├── log.md            append-only record of every operation
├── overview.md       living synthesis across all sources
├── sources/          one summary page per source document
├── entities/         people, companies, projects — auto-created
├── concepts/         ideas, frameworks, methods — auto-created
└── syntheses/        query answers filed back as wiki pages
graph/
├── graph.json        persistent node/edge data (SHA256-cached)
└── graph.html        interactive vis.js visualization — open in any browser
Five of those lines matter for understanding what the thing does.
The index is a catalog of all pages, updated on every ingest. The log is an append-only record of every operation, which is the one part of the design that is unambiguously sound. The overview is a living synthesis revised on every ingest. Sources get one summary page each. Entities and concepts are auto-created.
And the last directory is the one to look at: query answers filed back as wiki pages.
So when you ask the wiki a question, the answer is not just returned to you. It is written into the corpus, as a page, in a directory that later ingests and queries will read. The wiki is not read-only over your sources; it is a fixed point that accumulates its own outputs.
The directory split is a partial mitigation, because a page under sources and a page under syntheses are in different places, and a reader of the file tree can tell them apart. What the README does not say is whether the overview synthesis draws on both. The overview is described as a synthesis across all sources, and if syntheses are among what it draws on, then a claim the model generated is one ingest later feeding the next round of synthesis, with no marker in the text distinguishing it from something a document said.
That is the structural decision here, and it is what makes the tool compound. It is also the decision to be careful about, and the README does not raise it once.
The pin that guards a compromised version lives in a file the metadata never reads
There are two dependency declarations in this repository and they do not contain the same things.
The project metadata declares two dependencies. One is a markdown conversion library with all of its optional extras, the other is a progress bar. Both are version-ranged.
A separate requirements file declares two different ones. One is a language model gateway, the other is a graph library. And above them is a three-line comment: a specific pair of versions of the gateway were compromised in a supply chain attack in March 2026, the requirement is pinned past that range, and the reasoning links to an issue in this repository.
So the security response to a compromised dependency exists, is well written, cites its evidence, and lives in a file that the project metadata does not reference.
This matters because the project metadata is what tooling reads. It is what a resolver sees, what an editor's language server sees, what a scanner enumerates when it asks what this thing depends on. The two libraries the pin is protecting are absent from it entirely, and so is the pin.
The requirements file is a perfectly reasonable place for a runtime pin, and plenty of projects keep one and a metadata file side by side. The problem is not duplication, it is division. One of the two lists is complete and the other is not, and the incomplete one is the one a scanner reads.
The fix is to move two lines. The comment deserves to be where the resolver will see it, because the thing it warns about is precisely the thing a resolver will try to install.
Four agent runtimes, four instruction files, and slash commands for one of them
The install section is the shortest thing in this README and the most revealing. It gives a launch command per agent:
claude      # reads CLAUDE.md + .claude/commands/ (slash commands available)
codex       # reads AGENTS.md
opencode    # reads AGENTS.md
gemini      # reads GEMINI.md
Four runtimes, and the comments say which instruction file each one reads. One reads its own file plus a commands directory. Two read a shared agents file. One reads its own file again.
So the repository carries three instruction files at the top level plus a commands directory. That is a deliberate commitment to four different agent tools, and the tree confirms it.
What it does not commit to is a uniform interface. One of the four gets four slash commands, and the README says so in as many words: those commands are specific to that tool, and the other agents use the natural language triggers, which it says work identically.
Work identically is the claim to examine. The slash commands are named after the operations: ingest, query, lint, build graph. The natural language equivalent is a set of example phrases, four of them, all of them phrased as sentences with a leading verb. An agent that has read the instruction file will produce a reasonable response to those, and a reasonable response is not the same as a command with defined arguments. The lint example in the README shows an arrow followed by a quoted finding, which reads like output; but lint is defined as finding orphans, contradictions and gaps and suggesting sources, which is reasoning rather than a lookup, so that line is illustrative of the shape of a good answer rather than a thing the tool guarantees.
For a user on one of the three agents without slash commands, that difference is the whole ergonomics of the tool, and it is described in half a sentence.
The project metadata still says Your Name and ships an empty description
The metadata file names the project, pins a version, and then stops halfway through its own schema.
The description field is an empty string. The author field is a literal placeholder: the name Your Name and the address you at example dot com, with no space after the comma.
Neither of those breaks anything, because of the next line. The build section sets package mode to false, which tells the tool not to build or install this project as a package. There is no distribution channel to publish the metadata to, and nothing consumes the author field.
So the metadata file is not a published artifact. It exists to configure the repository's own tooling: the dependency ranges, the interpreter floor, and the build backend. And in that role the placeholder author is only untidy.
What is worth noting is the combination. A reader who opens this file to answer the question that actually matters, which is what does the project need installed, gets a two-item list that is not the whole answer. The other two dependencies are in a different file. The version is 0.1.0, which given the feature set and the absence of any tagged release is accurate rather than embarrassing.
The interpreter floor is the one line with teeth in it: greater than or equal to 3.10 and below 3.14. That excludes the current interpreter outright, so on a machine with the newest Python the tool cannot be installed as declared. Whether that upper bound is a deliberate compatibility statement or a leftover from the template it started as, nothing in the repository says.
There is no package mode, no release, and a graph that may need a network to render
Three things about the packaging, in ascending order of how much they matter.
Package mode is off, so there is no installable artifact. That is correct for this project and its install section says as much: clone the repository and open it in an agent, with no Python setup required. The agent does the work. A clone is the distribution format.
There are no GitHub releases either. So there is no tag to pin, no changelog, and no version that means anything except the 0.1.0 in a metadata file that is not published. For a tool whose value is accumulated state, that is more defensible than it sounds, because a user who has built a wiki over six months is not going to update it anyway. But it does mean nobody can tell which version of the instruction files, or the graph code, a given wiki was built with.
The graph is the part to look at. The layout says the HTML visualisation is interactive, built on a network visualisation library, and openable in any browser. Whether that works offline depends on something the README does not say: whether the library is bundled into the file or fetched from a content delivery network at view time.
For a tool whose entire pitch is local files on your disk, a generated HTML file that needs to reach the internet to render is a mismatch. And the project is otherwise scrupulous about locality: ingest is a local read, the wiki is local markdown, the cache is a local hash file. The graph is the one output that might not be.
The same directory holds a JSON file of node and edge data, cached by content hash. That file is the portable one. The HTML is the convenient one. Nothing tells you which survives being emailed to someone.
The only worked example is about CJK text, for a tool that ingests twelve formats
The README advertises a wide intake: markdown, PDF, DOCX, PPTX, XLSX, HTML, plain text, CSV, JSON, XML, reStructuredText and EPUB, with non-markdown files converted automatically at ingest time by an external tool, so there is no separate conversion step.
That is twelve formats and a conversion dependency, and it is a real convenience. It also means the hard part of the tool is somebody else's problem: the converter handles the formats, and the agent handles the extraction, and the interesting failure modes live in between.
The repository has one example directory. It is named for CJK text, meaning Chinese, Japanese and Korean. So the single worked example in a project that ingests twelve document formats is about the rendering of non-Latin scripts.
That is a defensible choice. CJK text is where entity extraction misbehaves, where tokenisation assumptions break, and where a wiki built from sources can quietly lose information at the boundaries between scripts. If you had to pick one example to prove the pipeline handles real documents, that is a good pick.
It is also the pick that says least about the other eleven formats. A spreadsheet with merged cells, a slide deck where the argument is in the speaker notes, a PDF whose table is the point: none of those are exercised by the one example that exists. The README's format list is a capability claim; the example is a correctness claim, and they cover different ground.
What would cost nothing is a second example directory per format family, since ingest is a single natural language sentence.
Every related project belongs to a different account than the repository
The README has a Related Projects section with four entries. Each is a repository, each has a one-line description, and each description positions the project as something to pair with this one.
All four are under a single account, and it is not the account this repository lives in.
The repository is under one owner. The supply chain advisory comment in the requirements file links to an issue under that same owner. And the four related projects are under a different one.
This is not, on its own, a problem. People maintain work under several accounts, forks move, organisations get renamed. A reader following those four links lands on four real projects that appear genuinely adjacent to this one, and that is what the section is for.
It is worth noticing for two reasons. The first is that a reader assessing how much of this ecosystem is one person's work is being asked to notice it themselves, from four URLs, with no sentence saying so. The second is that the section's framing is additive: these are described as things that add to or pair with your knowledge base pipeline, not as forks or alternatives or prior art. There is no prior art section at all, which for a tool in this space is a real omission, since the problem space is crowded and the README names none of it.
The descriptions are also all written in the second person, telling the reader what they get. Your knowledge base pipeline. Pair with wiki agent for research plus visual output. That is a consistent voice, and it is the voice of a project selling an ecosystem rather than documenting one.
The markdown extension on the converter pulls in every optional dependency it has
Twelve input formats are converted by one external library, and the dependency declaration asks for that library with all of its optional extras enabled.
For a converter, optional extras are the reasonable place to put the per-format dependencies. A library that reads spreadsheets needs a spreadsheet library; one that reads presentations needs a presentation library. Bundling them into the base install would force them on everyone, which is the right thing for a converter to avoid.
So asking for all of them is the correct choice for this project. If you drop a PDF in, the converter is already installed. If you drop an EPUB in next month, it is already installed. There is no first-run surprise where a format fails because you did not install the extra.
The cost is on the other side of that trade. Every clone that installs dependencies gets converters for twelve formats whether or not they will ever be used, which means a substantial dependency tree for a workflow where most people will ingest markdown and nothing else. The README says no Python setup is needed, which is true in the sense that nothing has to be configured, but the install is not small.
The version ranges are worth noting too. The converter is held below its next minor, and the progress bar is held below its next major. Both are sensible. Neither has an upper bound at the version level for the second one, so a future major cannot be picked up without editing the metadata, which is the conservative choice.
What is not documented anywhere is what happens when the converter fails on a file. Ingest is one natural language sentence to the agent. If a PDF is malformed, a password-protected, or is actually a scanned image with no text layer, the README gives you no error to expect and nothing to retry.
Editorial conclusion
Use it if you want an agent to hold a growing corpus on your own disk, and read it as a personal workflow rather than a system. Two things to know before you trust the output. Query answers are written back into the wiki as pages, so a claim the model generated becomes an input to the next synthesis, and nothing in the tree marks which pages came from your documents. And the supply chain pin for the compromised gateway version sits in the requirements file rather than the project metadata, so tooling that reads the metadata sees neither that dependency nor that warning. Treat the wiki as a research notebook you can audit, not as a source of record.
Frequently asked questions
What is the LLM wiki and what does it do?
It is a coding agent skill. You drop source documents into a raw directory and tell the agent to ingest them; the agent reads them, extracts knowledge and maintains a persistent interlinked wiki of markdown pages. The README's summary is that you never write the wiki yourself.
Which coding agents does llm-wiki-agent work with?
Claude Code, Codex, OpenCode and the Gemini CLI. The README gives a launch command for each and says which instruction file each reads: one reads its own file plus a commands directory, two read a shared agents file, and one reads its own file. Only Claude Code gets slash commands.
What file formats can llm-wiki-agent ingest?
Markdown, PDF, DOCX, PPTX, XLSX, HTML, TXT, CSV, JSON, XML, RST and EPUB. Non-markdown files are converted automatically at ingest time by an external tool, so there is no separate conversion step.
What does llm-wiki-agent write out?
A wiki directory with an index catalog updated on every ingest, an append-only operation log, a living overview revised on every ingest, one summary page per source, auto-created entity and concept directories, and a syntheses directory where query answers are filed back as wiki pages. Alongside it, a graph directory with cached node and edge data and an HTML visualisation.
Do I need an API key to use llm-wiki-agent?
The README says no, in the repository description and again in the install section, which states no API key or Python setup is needed. Its requirements file does include a language model gateway library, which normally needs a credential.
What dependencies does llm-wiki-agent declare?
Two in the project metadata: a markdown conversion library with all optional extras, and a progress bar. Two more in a separate requirements file: a language model gateway and a graph library, with a comment pinning the gateway past a version range reported compromised in March 2026.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/samuraigpt-llm-wiki-agent)Star history chart for your README
[](https://hysenlabs.com/projects/samuraigpt-llm-wiki-agent)Was this useful?