BrowserAI: four inference engines behind one call, and package metadata pointing at another repo
Run local LLMs like llama, deepseek-distill, kokoro and more inside your browser
At a glance
- What is it?
- A browser library for running quantized language, speech and audio models locally, whose published manifest points its repository, issues and homepage at a different GitHub organization, whose JSON schema example sits under a duplicated heading, and whose dependency list carries OCR and document libraries the feature list never mentions.
- Who is it for?
- BrowserAI is worth a look if you are building something that must not send user text to a server, because the privacy argument is structural rather than promised: the models load in the page, run on WebGPU, and keep working after the initial download. The four engine paths also mean you can pick between a WebGPU runtime, an ONNX runtime and a WASM runtime for the same generateText call.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 118 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
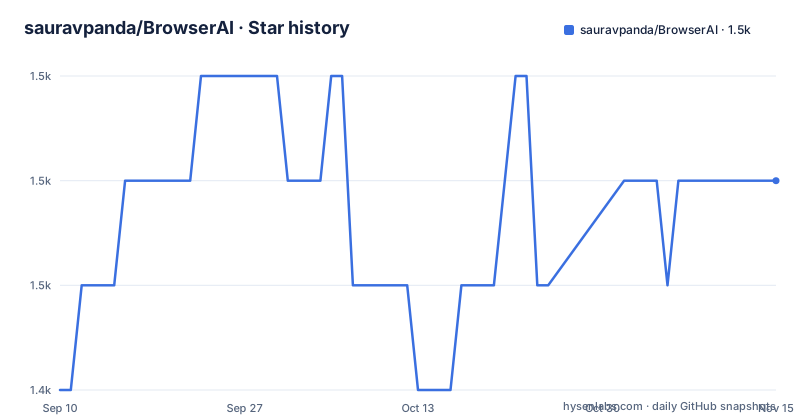
- sauravpanda/BrowserAI1,451 ★ · +2
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| sauravpanda/BrowserAI | 1.4k | 1.5k |
2 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The manifest points at a different GitHub organization
The package is published as @browserai/browserai, and inside its manifest three fields point somewhere other than where you are reading this. The repository URL is git+https://github.com/Cloud-Code-AI/BrowserAI.git, the bugs URL is an issue tracker under that same organization, and the homepage field is a readme anchor in that repository rather than the project site.
The repository hosting the code is under a different owner. That gap has three practical consequences. A bug report filed from an installed copy lands in another organisation's tracker. A clone URL copied out of the manifest gets a different tree than the one you npm-installed. And a documentation link that resolves through the manifest's homepage lands on a repository that may not be the one being maintained.
None of that makes the library unusable, and it is the kind of thing that happens when a project is developed under a company name and published from a personal account. It is worth knowing before you file anything, and worth patching in your own fork if the published metadata matters to you.
Four engines, one generateText call, and an implicit engine choice
The API surface is deliberately small. You construct a client, load a model with an optional quantisation and a progress callback, then call generateText and read the first choice's message content:
import { BrowserAI } from '@browserai/browserai';

const browserAI = new BrowserAI();

// Load model with progress tracking
await browserAI.loadModel('llama-3.2-1b-instruct', {
  quantization: 'q4f16_1',
  onProgress: (progress) => console.log('Loading:', progress.progress + '%')
});

// Generate text
const response = await browserAI.generateText('Hello, how are you?');
console.log(response.choices[0].message.content);
The same call serves a WebGPU runtime, an ONNX runtime and a WASM runtime, which is the design claim: swapping the backend does not rewrite the calling code.
What is not explicit is which engine you got. The engine is chosen by the model name you ask for, and the naming only distinguishes one of them. The WASM path uses suffixed names, so a Flare variant of a model is requested under its own name, and the documentation even notes that generation is the same API as the other engines. The WebGPU and ONNX paths, by contrast, list the same Llama 3.2 1B instruct model under both of their own headings with no suffix, so the identifier alone does not tell you which runtime you will get.
Two smaller conveniences sit in the same surface: generation accepts either a plain string or an array of role and content objects for a system prompt, and an adapter can be loaded from a URL afterwards, which is a LoRA path pointed at a safetensors file.
The WASM engine is a separate package by the same author
The engine list is not four implementations inside one repository. The manifest depends on a package scoped to the author, which is the WASM engine for GGUF models, alongside the WebLLM package for the WebGPU path and the ONNX runtime for the Transformers path.
That split has consequences for anyone auditing what ships. The version of the WASM engine is whatever the caret range resolves to at install time, so two installs of the same BrowserAI version can run different engine builds. The same applies to the WebLLM runtime, which is the component doing the actual inference work on the GPU path, and to the ONNX runtime underneath the Transformers path.
The LoRA adapter example deserves a separate note because of where the weights come from. Adapter loading takes a URL and fetches a safetensors file, which means the model you are fine tuning at inference time can be hosted anywhere. That is a feature when you control the host and a supply chain question when you do not, and nothing in the example indicates a checksum or a pinned revision.
A types-only package sits in runtime dependencies, and OCR is in the tree but not in the features
The runtime dependency list contains one entry that should be in development dependencies: a types package for the PDF library. Type declarations ship nothing at runtime, so this adds install weight and a phantom dependency rather than functionality, and it suggests the list was assembled without pruning.
Three more entries have no counterpart in the feature list. A PDF parser, a Word document converter that reads document files into HTML, and a JavaScript OCR engine are all declared dependencies. The features section talks about text generation, speech recognition, text to speech and audio source separation, and the example folders cover chat, voice, text to speech, audio separation, schema output, a database demo, a realtime chat demo, a benchmark and one directory named as work in progress. Nothing in either place ingests a PDF, a Word file or an image of text.
So the shipped capability surface and the installed capability surface are different sets. Either document ingestion is on the way and unannounced, or these three dependencies are leftovers. The dependency list is the only place the claim appears.
The JSON schema example is filed under the same heading as the chat example
The examples section has two consecutive subsections with the identical title, both called chat with a system prompt. The first one is what the title says: a client is created, a chat model is loaded, and generateText receives an array of a system role and a user role asking what WebGPU is.
The second one is not that at all. It asks the model to list three colours and wraps the request in a json_schema describing an object with a colours array whose items have name and hex string fields, then pairs it with a response_format of a JSON object type. That is the structured output example, wearing the wrong heading.
It is a small thing, and it is the kind of small thing that costs a reader a minute because the second block looks like a mistake until you notice the schema. The structured output path is worth understanding properly, since the feature list advertises generation with JSON schemas and the schema is where the constraints on your own output format live.
Audio separation ships as its own export path with its own quality knobs
Source separation is not part of the main entry point. It is imported from a dedicated subpath, and the manifest backs that with a second export block carrying its own pair of ES module and CommonJS builds and its own separate type declarations for both module systems.
The engine object takes a configuration on load and exposes a separate call that takes an audio buffer plus two tuning parameters:
import { DemucsEngine } from '@browserai/browserai/demucs';

const engine = new DemucsEngine();
await engine.loadModel({ /* htdemucs config */ });

// Separate an AudioBuffer into stems
const result = await engine.separate(audioBuffer, {
  shifts: 1,        // Time-shift augmentation passes (higher = better quality, slower)
  overlap: 0.25,    // Segment overlap ratio
});

// result.sources contains: drums, bass, other, vocals (each as AudioBuffer)
const vocals = result.sources['vocals'];
The shifts parameter is the number of time-shift augmentation passes, with an inline comment saying higher is better quality and slower, and overlap is the segment overlap ratio. The result is an object whose sources are keyed by stem, with drums, bass, other and vocals as the four keys for the shipped model.
The text to speech example has its own small blemish, since the comment introducing the Web Audio playback code sits on the same line as the closing brace of the previous statement. The example still works, but it is the second place in these examples where a formatting slip survived, and both are in the block a newcomer copies first.
The WebGPU list runs to eight billion parameters, and the roadmap promises RAG
The model catalogue is where expectations and reality diverge most. The WebGPU list has 21 entries, and among them are an eight-billion-parameter Llama distill and a seven-billion-parameter Qwen distill, alongside four embedding models at different sizes and a spread from a 135M model to a 3B instruct model. Running a multi-billion-parameter model in a browser is a download and a memory question, not just an inference question.
The ONNX path lists five models: one text model, three speech recognition sizes from tiny to small, and the text to speech model. The WASM path lists four small GGUF variants with quantisation tags. The audio path lists one four-stem model. So the engine with the longest list is also the one with the least variety of task, and the smallest model, at 135M, appears under both the WebGPU and WASM lists.
The roadmap is further ahead than the feature list. A foundation phase names simplified model initialisation, basic monitoring and metrics, a simple retrieval implementation and developer tooling. An advanced phase names hybrid search, auto-chunking, source tracking and deeper observability, and the roadmap text on view stops partway through the word performance. Meanwhile the shipped features mention only a built-in database for storing conversations and embeddings, and an example folder for benchmarks exists with no published numbers.
Editorial conclusion
BrowserAI is worth a look if you are building something that must not send user text to a server, because the privacy argument is structural rather than promised: the models load in the page, run on WebGPU, and keep working after the initial download. The four engine paths also mean you can pick between a WebGPU runtime, an ONNX runtime and a WASM runtime for the same generateText call.
Four things to check first, all of them visible in the repository rather than buried. The manifest's repository, issues and homepage fields name a different GitHub organization than the repository publishing it, so an npm bug report and a clone URL both lead somewhere else. The Flare engine is a separate package by the same author, and adapter loading takes a URL, which means fetching weights you did not build. The dependency list includes a PDF parser, a Word document converter and an OCR engine that neither the feature list nor the example folders cover. And the structured output example is filed under the same heading as the chat example, so the documentation reads as duplicated until you read the code inside it.
If you do adopt it, pin the version. The manifest is at 2.2.0, matching the most recent release in April 2026, with the previous tags from 2025, and the last push is dated 21 July 2026.
Frequently asked questions
Which GitHub repository does the BrowserAI npm package point to?
Its manifest names Cloud-Code-AI/BrowserAI for the repository, the issues tracker and the homepage, which is a different organization from the repository publishing the code. Bug reports and clone URLs taken from an installed copy lead there.
Which inference engines does BrowserAI support?
Four: a WebGPU runtime, an ONNX runtime for transformer models, a WASM runtime for GGUF models that ships as a separate package by the same author, and the audio separation engine on its own export path.
Does BrowserAI need a server or an API key at runtime?
The stated design is that all processing happens locally in the browser, that there are no server costs, and that it keeps working without internet after the initial download. The examples contain no network calls other than loading models and an optional adapter URL.
Can BrowserAI produce structured JSON output?
Yes, through a json_schema passed with generateText plus a response_format of JSON object type. The worked example lives under a duplicated heading in the documentation, which makes it look like a copy of the chat example until you read the schema.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sauravpanda-browserai)Star history chart for your README
[](https://hysenlabs.com/projects/sauravpanda-browserai)Was this useful?