imbalanced-learn: the narrow sklearn-compat pin, the extras, and the test command gap
A Python Package to Tackle the Curse of Imbalanced Datasets in Machine Learning
At a glance
- What is it?
- imbalanced-learn gathers the re-sampling techniques used on datasets with strong between-class imbalance and stays compatible with scikit-learn. Releases are recent and the license is MIT, but the install surface has three rough edges worth reading before you pin it: a compat dependency held below 0.2, a prose dependency list that does not match pyproject.toml, and a documented test command with no Makefile behind it.
- Who is it for?
- Use imbalanced-learn when your classifiers need re-sampling and your environment already clears Python 3.10 with NumPy 1.25.2 or newer. Do not adopt it on the strength of its prose alone: read pyproject.toml instead of the dependency paragraph, expect the resolver to hold at sklearn-compat below 0.2, and be ready to drive tests through pytest and pre-commit directly because the make coverage line has no target behind it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 139 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
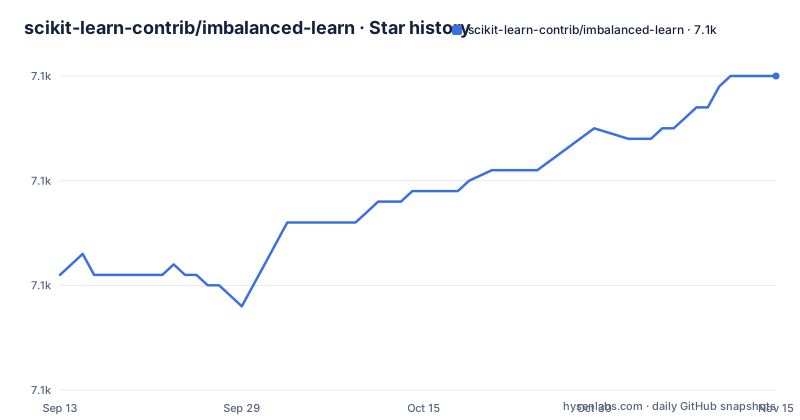
Star history
- scikit-learn-contrib/imbalanced-learn7,140 ★ · +19
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| scikit-learn-contrib/imbalanced-learn | 7.1k | 7.1k |
19 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Re-sampling techniques split into over, under, combine, and ensemble
The package gathers the re-sampling techniques commonly used on datasets that show strong between-class imbalance, and it is built to sit next to scikit-learn rather than replace it. The example tree is the clearest map of scope. examples/ holds subfolders named over-sampling, under-sampling, combine, ensemble, evaluation, model_selection, pipeline, datasets, applications, and api. That is ten separate topic areas, and evaluation, model_selection, and pipeline each get their own folder, which tells you the project treats measuring and wiring the samplers as work in its own right rather than an appendix. The implemented algorithms are documented in the user guide at imbalanced-learn.org/stable/user_guide.html, and the README sends readers there instead of enumerating methods, so the folder names are where you learn what families exist.
sklearn-compat is held below 0.2 and drags the whole stack
pyproject.toml installs six runtime packages, and one of them is far narrower than the rest: sklearn-compat>=0.1.6,<0.2. scikit-learn itself is free to move inside its major version (>=1.4.2,<2), and every other pin carries an upper bound at the next major: numpy>=1.25.2,<3, scipy>=1.11.4,<2, joblib>=1.2.0,<2, threadpoolctl>=2.0.0,<4. The compat layer is the exception, because a single digit separates it from the next release line. For a reader that means the resolver can hold the whole install back, or fail it, the day a 0.2 shows up upstream, and it means the practical ceiling on your scikit-learn version is decided by a package that versions independently of scikit-learn. Dependency audits and lockfile reviews should treat this pin as the tightest constraint in the tree.
Python 3.10 through 3.14, and NumPy stops before 3
requires-python is >=3.10, and the classifiers name 3.10, 3.11, 3.12, 3.13, and 3.14. That floor is the first thing to check on an older interpreter, because a 3.9 environment gets no install at all rather than a warning. Upper bounds do the same job on the numeric stack: NumPy must stay under 3, SciPy under 2, joblib under 2, threadpoolctl under 4, and scikit-learn under 2. A team tracking NumPy aggressively will meet that ceiling before the package itself moves, and a pre-locked environment can sit at a combination no later release is free to widen. The declared Development Status is 5 - Production/Stable, the Operating System classifier is OS Independent, and the Intended Audience is Science/Research, so nothing in the metadata narrows it to one platform.
The version number is read from imblearn/VERSION.txt
The version is not written into pyproject.toml. The project declares version and readme as dynamic, then resolves version from the file imblearn/VERSION.txt and readme from README.rst, and it builds through setuptools.build_meta with setuptools>=71 and setuptools_scm[toml]>=8 in the build requirements. Two consequences follow. A checkout missing the package directory cannot produce a version at all, so any packaging step that copies pyproject.toml without the source tree fails at metadata time rather than at import time. And the installation text still tells contributors to clone the repository and run the setup.py file, while there is no setup.py in the top level listing. Contributors who follow that sentence literally will hunt for a file the repository no longer has.
The prose dependency list and the installed list differ
The installation notes name five requirements: Python, NumPy, SciPy, scikit-learn, and Pytest, with minimums of 3.10, 1.25.2, 1.11.4, 1.4.2, and 7.2.2. What pip resolves from pyproject.toml is numpy>=1.25.2,<3, scipy>=1.11.4,<2, scikit-learn>=1.4.2,<2, sklearn-compat>=0.1.6,<0.2, joblib>=1.2.0,<2, and threadpoolctl>=2.0.0,<4. Pytest appears in the documentation but not in the install requirements, and joblib and threadpoolctl install without appearing in the documentation at all. Pandas, Tensorflow, and Keras are named as optional for working with dataframes and with TensorFlow and Keras models, while Matplotlib and Seaborn are listed as what the examples need. For anyone building a locked, reproducible, or audited environment, pyproject.toml is the list to trust and the paragraph is only a starting point.
The docs extra drags in Tensorflow and Pandas
Optional dependency groups include dev, docs, linters, and optional. The docs group is not a lean documentation toolchain: it carries pandas>=2.0.3,<3 and tensorflow>=2.16.1,<3 alongside matplotlib, seaborn, memory_profiler, numpydoc, sphinx>=8.0.2,<9, sphinx-gallery, sphinxcontrib-bibtex, sphinx-copybutton, pydata-sphinx-theme, and sphinx-design. The dev group is only ipykernel, ipython, and jupyterlab. Linters are pinned exactly, black==23.3.0 and ruff==0.14.2, frozen versions that any formatting change will move. Installing the docs group to read the user guide locally therefore means installing Tensorflow as a side effect.
The documented test command is make coverage
The Testing section says that after installation you can use pytest to run the test suite, and then shows one line: make coverage. There is no Makefile in the top level listing, which holds .coveragerc, conftest.py, build_tools/, maint_tools/, doc/, examples/, imblearn/, pixi.lock, and pyproject.toml. A contributor who copies that line meets a missing target and has to hunt for the real entry point, while the sentence directly above names pytest as the runner. Contributors are also advised to install pre-commit and run pre-commit install before opening a pull request, and .pre-commit-config.yaml at the root is where those hooks come from. The gap is small, but it sits on the exact path a new contributor walks first.
Four install paths, and the editable one turns off isolation
There are four ways in, and the documented ones are:
pip install -U imbalanced-learn
conda install -c conda-forge imbalanced-learn
From a clone the sequence is git clone the repository, cd imbalanced-learn, then pip install . For development there is pip install --no-build-isolation --editable ., which drops the build isolation layer and therefore asks for setuptools>=71 and setuptools_scm[toml]>=8 to be present in the interpreter you are working in. Pre-commit, which the project advises before any pull request, installs as its own pair of commands. The cost differs per route: PyPI and conda hand you a fixed resolution, the clone builds from source against whatever your environment already holds, and only the editable route makes local edits take effect without reinstalling.
Editorial conclusion
Use imbalanced-learn when your classifiers need re-sampling and your environment already clears Python 3.10 with NumPy 1.25.2 or newer. Do not adopt it on the strength of its prose alone: read pyproject.toml instead of the dependency paragraph, expect the resolver to hold at sklearn-compat below 0.2, and be ready to drive tests through pytest and pre-commit directly because the make coverage line has no target behind it. If your platform cannot absorb a package that releases on its own schedule rather than scikit-learn's, check that before you commit a pin.
Frequently asked questions
How do I install imbalanced-learn using pip?
Run pip install -U imbalanced-learn, or conda install -c conda-forge imbalanced-learn for the conda-forge build. A source install is three steps: clone the repository, cd imbalanced-learn, then pip install .
What is imbalanced learn?
It is a Python package offering re-sampling techniques commonly used in datasets showing strong between-class imbalance. It is compatible with scikit-learn, is part of the scikit-learn-contrib projects, and is MIT licensed.
How do I install imbalanced-learn in a Jupyter notebook?
The dev optional dependency group holds ipykernel, ipython, and jupyterlab, which covers the notebook stack. The package itself installs with pip install -U imbalanced-learn and needs Python 3.10 or newer.
How can I balance an imbalanced dataset?
The documented route is re-sampling the dataset to offset the imbalance, and the implemented algorithms are written up in the user guide at imbalanced-learn.org/stable/user_guide.html. The reasoning is that most classification algorithms perform optimally only when the number of samples in each class is roughly the same.
How do I fix imbalanced classes?
The answer the project gives is its family of re-sampling techniques, grouped in the examples tree as over-sampling, under-sampling, combine, and ensemble. Installation documentation, API documentation, and examples are published at imbalanced-learn.org/stable/.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/scikit-learn-contrib-imbalanced-learn)Star history chart for your README
[](https://hysenlabs.com/projects/scikit-learn-contrib-imbalanced-learn)Was this useful?