llm-wiki compiles knowledge once instead of re-deriving it
A skill for building a personal knowledge base based on Karpathy's llm-wiki methodology, supporting multiple platforms.
At a glance
- What is it?
- llm-wiki is a Skill and monorepo that turns scattered material into a linked knowledge base you maintain through an AI CLI, with a graph engine shared by an offline HTML export and a workbench still in development. Its own feature list is where the engineering is: confidence labels on every claim, optional extractors that stay off until asked for, and a workbench that describes its local access checks in detail.
- Who is it for?
- Adopt this if you re-read the same sources repeatedly and want the synthesis to live somewhere you maintain rather than something you recompute per question. Do not adopt it expecting the workbench: that half is described as in development and aimed at developers, while the Skill form is the stable one.
- Can I use it commercially?
- Not without permission. GitHub finds no licence file in the repository, and without a licence all rights are reserved by default: you may read the code but not reuse it. Check the README, or ask the authors, before using it.
- Is it still maintained?
- Yes. The repository last received commits 111 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
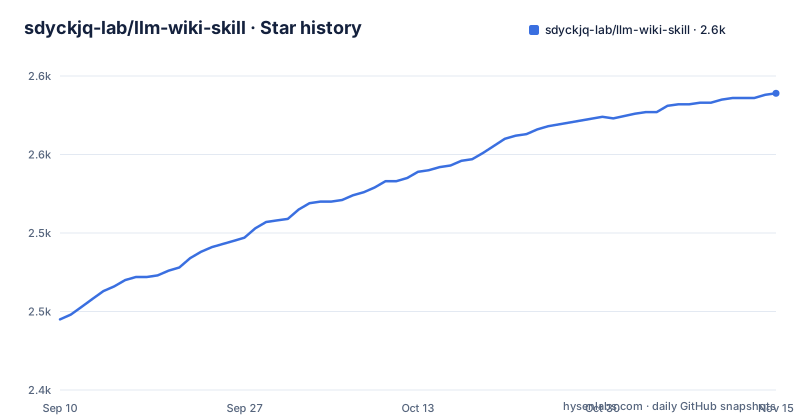
- sdyckjq-lab/llm-wiki-skill2,589 ★ · +144
| Repository | 2026-09-10 | 2026-11-15 |
|---|---|---|
| sdyckjq-lab/llm-wiki-skill | 2.4k | 2.6k |
144 Stars in the last 66 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two front ends, one knowledge base format
The repository is a monorepo with two ways in, and the design point is that both read and write the same format.
The Skill form is described as the mature and stable one. You hand the repository link to an AI coding tool, Claude Code, Codex, OpenClaw or Hermes, it installs itself, and you maintain the knowledge base from inside that tool's conversation.
The workbench form lives under `workbench/` and is explicitly in development. It is a locally run knowledge base workbench built around a conversation, with an interactive knowledge graph built in, currently aimed at developers who start it with a development command, with a desktop application promised for later.
What ties them together is a single graph engine package. The offline HTML that the Skill produces and the graph view inside the workbench are described as two outputs of the same engine, which is why a change to graph behaviour shows up in both without the two surfaces having separate implementations.
That split is also the honest scope statement. One form is something you install and use, the other is something you run while it is being built.
Compile once, maintain afterwards
The claim in the quick start is short enough to be the thesis of the project: knowledge is compiled once and then maintained continuously, instead of being re-derived from the original documents every time you ask a question.
The feature list explains what that means mechanically. Processing is two steps, analysis first and generation second, with long content going through a two step chain and short content taking a simplified path. A `purpose.md` file gives the agent direction when it is organising or querying. Initialization is zero configuration, one sentence produces a complete knowledge base with the directory structure, templates and a research direction page.
Then there is validation between the steps. A script checks the format of what came out of the analysis, and the description of it is blunt: the model cannot produce incomplete data even if it tries. That is the mechanism that makes a compiled knowledge base trustworthy, because the failure mode of a summarising model is not usually a refusal, it is a plausible summary that quietly omits half the source.
Material routing is handled by domain. Extraction is chosen based on the URL, so a link to a video platform and a link to a blog do not go through the same code path.
Optional extractors stay off until you ask for them
The source table is split into three tiers, and only the first is installed by default.
The core tier is documents you already have: PDF, Markdown, text, HTML, and plain text pasted in. The README says these are digested directly with no add-on required.
The optional tier is web content: articles, posts on X or Twitter, WeChat public accounts, YouTube and Zhihu. These are extracted automatically when the adapters are present, and the documented fallback when extraction fails is a prompt to paste the material yourself.
The manual tier is one platform, a Chinese short video and note site, which currently supports manual paste only.
The install flag that decides which tier you get:
bash install.sh --platform claude --with-optional-adaptersThat flag is worth pausing on. The default install prepares the knowledge base main line only, and the optional extractors have to be enabled deliberately. For a tool whose output is a knowledge base you will later trust, that is a reasonable default: the fewer network extractors installed as local code, the smaller the surface between a page on the internet and a page in your notes.
Four platform flags, four entry documents
Installation is one script with a platform argument, and the four values map to four different tools.
bash install.sh --platform claude
bash install.sh --platform codex
bash install.sh --platform openclaw
bash install.sh --platform hermes
Each platform has its own entry document rather than one shared set of instructions: a `CLAUDE.md` for one, an `AGENTS.md` for another, and a `README.md` for each of the remaining two. The root carries those instruction files as well, alongside a `SKILL.md`, and the platform directories repeat the pattern.
After installation on one of them there is a companion command, `/llm-wiki-upgrade`, so the skill can update itself from inside the conversation rather than by re-running the script.
Context injection is handled by a hook. A `SessionStart` hook is what makes the agent aware of the knowledge base at the start of every session, which is the piece that makes a compiled knowledge base actually get used rather than sitting there unread.
The repository root also carries a `setup.sh` beside the installer and an `install.ps1` for Windows, so there are three install scripts for one Skill. The documentation the README points at for each platform is in those platform directories, not in the root.
Four confidence labels are the review surface
One feature in the table is more useful than the rest, and it is a single line: confidence annotation with four labels.
Every claim in the knowledge base carries one of EXTRACTED, INFERRED, AMBIGUOUS or UNVERIFIED. The stated purpose is that you can see at a glance which material needs checking. That is the difference between a knowledge base and a pile of summaries, and it costs the model nothing to emit.
Around that sit the structural features. Pages are generated as entity pages, topic pages and material summaries, and they are linked to each other with double bracket bidirectional links, so the structure is written down rather than implied by naming.
Two more features are about keeping the base current. A cache keyed on a SHA256 hash deduplicates material, updates on write and has a self healing safety net, described as a guarantee that a weaker model will not miss the cache. And conversation crystallisation turns valuable parts of a conversation directly into knowledge base pages, which is the shortest path from something you just learned to something you can find again.
The analysis formats are named too: a deep report, a comparison table and a timeline.
The workbench spends more words on its boundaries than its features
The workbench preview table is unusual because so many of its rows are about refusing things.
Local access protection says that local configuration, conversations, pages, graph events, files and state operations are only opened to a workbench that passes both an origin check and a startup credential check. Reliable startup says the backend listens only on the local machine, that a failed start does not replace existing credentials, and that a restart rotates them and restores the last knowledge base. Retrieval log privacy says the default logs keep only the session, the knowledge base, trigger state, result information and stable failure states, and explicitly do not keep user questions or recoverable derived content.
The request boundary row says the front end only sends registered combinations of method and entry point, and that a list of artifacts and downloads rejects non-compliant numbering.
The graph identity row is the one with a subtle detail: an invalid detail view must not carry a local absolute path into the offline file. That is a real constraint, because an exported HTML file that contains your home directory leaks it to whoever you send the file to.
None of this is a feature a user sees, and all of it is the difference between a local tool and one that will eventually meet a network.
One drawing strategy, one fallback path, one measured baseline
The graph engine section is written like an engineering log rather than a feature list.
Sigma with Graphology is the main route for both the global view and community reading. The DOM and SVG implementations are kept only as a fallback, a comparison and an exception path, and are no longer extended as the main path for community reading. A shared drawing strategy produces density, node display, label and relationship budgets, the stable skeleton, community hierarchy and label direction from one set of rules, computed once per update, and the older toolbox and early wash templates are described as retired.
Failure is handled explicitly. When the shared result fails, both the workbench and the offline graph clear the old content and show a message; only a failure of Sigma itself falls back to DOM or SVG, and the stated goal is never to leave a half usable result behind.
There is also a performance baseline, described with more precision than most projects manage: production graphs of one thousand nodes and isolated graphs of one, five and ten thousand nodes, each measured three times with hover preview, storing the median, compared later by a fixed formula, with other rendering experiments explicitly excluded from the Sigma specific gate.
That is what a project does when it intends to replace its own renderer and does not want to argue about it later.
Two toolchain files, three installers, one empty version
The root listing is a monorepo root, and a few entries explain how it is put together.
There are two toolchain version files, a `.mise.toml` and a `.nvmrc`, and the manifest requires Node 22.19.0 or newer. There are three install scripts, `install.sh`, `install.ps1` and `setup.sh`. There are four instruction files at the top level for the tools the Skill targets, plus `CONTEXT.md`, `CONTEXT-MAP.md` and a `TODOS.md`, and directories for `designs/`, `deps/`, `docs/`, `tests/`, `scripts/` and `assets/`.
The manifest is worth reading closely. It is private, its version is `0.0.0`, and it declares the license as MIT, while the root listing contains no LICENSE file even though the README links one. So the license is declared in the manifest and referenced in the README but not present as a file at the root.
Its workspaces are the workbench server, the workbench web app and everything under `packages/`, while the scripts refer to workspace packages under two different scopes: one set named with an agent suffix for the server and web, another set without it for shared contracts and the graph engine. The dev dependencies list contains exactly one entry, a runner used to start the server and web processes together, which tells you everything else lives in the workspace packages rather than at the root.
The last push was on 2026-07-27, the repository is not archived, and it publishes no GitHub releases.
Editorial conclusion
Adopt this if you re-read the same sources repeatedly and want the synthesis to live somewhere you maintain rather than something you recompute per question. Do not adopt it expecting the workbench: that half is described as in development and aimed at developers, while the Skill form is the stable one. Three things to check before you install. Whether the optional web extractors are acceptable, since they are off by default and adding them pulls in more code that runs locally. Where your material actually ends up, because the README is explicit that prompts, selected citations, retrieved fragments and generated output can be sent to whichever model provider you configured. And the confidence labels, because EXTRACTED against INFERRED against UNVERIFIED is the difference between a knowledge base you can trust and one you have to re-check line by line.
Frequently asked questions
What does llm wiki do?
It is a Skill and monorepo that turns scattered material into a linked knowledge base you maintain through an AI coding tool. The stated core difference is that knowledge is compiled once and then maintained, rather than re-derived from the original documents on every query.
How do I install llm-wiki?
Run the install script with a platform flag: bash install.sh --platform claude, or codex, openclaw or hermes, then ask your agent to initialize a knowledge base. Optional web extractors are not installed by default and are enabled by adding --with-optional-adapters to the same command.
What does llm-wiki send to my model provider?
Knowledge base files and offline graph artifacts are kept on your machine, but when an agent answers or digests something, the prompt, the selected citations, the retrieved fragments, the tool output and the generated artifacts may be sent to the model provider you configured. The API key is not written into llm-wiki's own configuration.
Which sources can llm-wiki ingest?
PDF, Markdown, text, HTML and pasted plain text are digested directly with no add-on. Web articles, X and Twitter posts, WeChat public accounts, YouTube and Zhihu are extracted automatically when the optional adapters are installed, with a manual fallback when extraction fails, while one Chinese note platform currently supports manual paste only.
Is the llm-wiki workbench finished?
No. The Skill form is described as mature and stable, while the workbench under workbench/ is in development and aimed at developers who start it locally, with a desktop application planned. Both read and write the same knowledge base format and share one graph engine.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sdyckjq-lab-llm-wiki-skill)Star history chart for your README
[](https://hysenlabs.com/projects/sdyckjq-lab-llm-wiki-skill)Was this useful?