SpecForge: one training command with configuration recipes
Train speculative decoding models effortlessly and port them smoothly to SGLang serving.
At a glance
- What is it?
- A framework for training speculative decoding draft models so they drop into one serving stack. The design is a single typed entry point whose configuration lives entirely in the config path, which is elegant until you notice there is a second directory named configs and a benchmark script at the root.
- Who is it for?
- SpecForge fits a team already serving with one stack and wants to train its own draft models rather than adopt someone else's checkpoint, and the portability claim is the reason to look at it. Four things to settle first.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
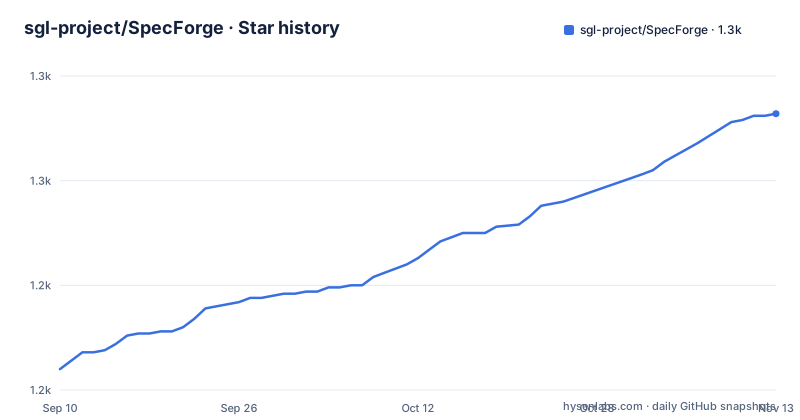
- sgl-project/SpecForge1,282 ★ · +122
| Repository | 2026-09-10 | 2026-11-13 |
|---|---|---|
| sgl-project/SpecForge | 1.2k | 1.3k |
122 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One training command selects a configuration recipe
Every method in the table is trained by the same command, and that is the framework's central design decision.
specforge train --config examples/configs/online/disaggregated/external/qwen3-8b-eagle3-disaggregated.yamlThe path selects a YAML recipe organized by feature mode, topology and service ownership, with model and method reflected in its filename. The actual settings are in the file: its model, data, training and deployment sections specify the run. Adding a drafting method does not add an entry point, and the file says so explicitly: there are no method-specific Python training entry points.
The last segment of the path decides who runs the services. Under an external recipe, the framework supervises the producer and consumer on one trainer node while the user or a scheduler owns the transfer service and the serving stack. Under a managed-local recipe, those services are started on the local host as well.
Parallelism is split the same way. Online target parallelism belongs to the serving framework, while a named configuration section owns the trainer's data parallelism and the offline process groups for one specific method.
The directory structure makes recipes easier to find, but the selected file’s contents and external environment determine the run. Review the YAML and validation output instead of inferring all settings from its path.
Three dependency manifests for three kinds of accelerator
The packaging tells you more about who runs this than the overview does.
The default project file pins three packages exactly: the deep learning framework at one specific version, the transformers library at another, and the serving framework at a third. Everything else in that list floats, including the dataset library, the accelerator library, the tracking library and the tensor serialisation library. Python 3.11 or newer is the floor.
Then there are two more manifests at the repository root, one project file for a second accelerator vendor and a requirements file for a third. A framework that pins its deep learning framework to an exact version and ships three dependency specifications is making a statement about hardware breadth, and the honest reading is that two of those three configurations are the ones its authors do not develop on every day.
The optional groups are thin in an informative way. One covers fused attention and its build helper. One covers a fused kernel library. One covers a single data tooling package. And the development group contains one entry, a pre-commit configuration tool, in a repository that has a test directory, a pre-commit configuration file of its own, and an import-sorting configuration.
So there is no declared test tool in the project's dependencies at all. That is not a criticism so much as a signal that this repository is run and verified somewhere other than through its packaging.
Unsupported combinations are rejected instead of falling back
One sentence in the file describes the framework's failure philosophy, and it is worth more than the feature list.
Unsupported combinations of method and topology are rejected during configuration validation or during run assembly, and the stated alternative to that is falling back to an older trainer.
So the framework was built in a world where a training run that silently used different code than you asked for was normal, and someone decided otherwise. Given the alternative on offer, the choice is not a close call: a research framework that quietly trains your draft model with last month's trainer produces numbers you cannot attribute.
Validation applies to the actual configuration and supported combination, not simply to the recipe’s directory name.
What is not said anywhere is what the rejection looks like. There is no error message in the visible text, no list of valid combinations, and no statement of how many combinations are supported. That information is in a linked guide described as the supported method and topology matrix, which is the right place for it and not the same as having it in the repository.
Two directories named configs, and one method's benchmark at the root
The top-level listing is where this repository stops looking like a framework and starts looking like a working setup.
There is a package directory, a test directory, a scripts directory, a documentation directory, a datasets directory, and a set of examples. There is also a directory named configs at the root, sitting alongside the configs directory the documentation always points at inside the examples tree.
Nothing in the visible file explains what the root one holds. Every config path quoted is under the examples directory, so either the root directory is a cache the runs write to, or it is a second set of configurations for a purpose the file does not mention.
The root also contains a benchmark script whose name identifies one specific method, sitting next to a benchmarks directory that presumably holds the rest. One method's measurement harness at the top level and everyone else's in a subdirectory is the kind of asymmetry that survives because the person who wrote it needed it in the working directory and nobody tidied up.
Two more entries deserve a mention. There is a patches directory, which means the repository applies modifications to code it does not own, and those patches are a maintenance obligation that no documentation here describes. And there is a manifest file controlling what gets packaged, plus an import-sorting configuration and an editor container definition.
The speedup is a dashboard link, and the versions live in blog posts
Two numbers anchor the file's pitch, and neither is verifiable from the repository.
The first is speed: up to four times, and the claim is carefully attributed. It is the combination of the pre-trained model bundle and the serving stack together, not the training framework alone. The evidence offered is a documentation link, a performance dashboard anchored on that same documentation page, and a model collection. Nothing in the repository is a benchmark result.
The second is version. The news section announces version 0.2.0 in one month and version 0.3.0 in another, each alongside a phase of the model bundle. The repository publishes no releases.
So the version numbers a user is told about exist only in blog posts, and the package version is resolved at build time by reading a plain text file from the repository root. There is no tag to check out, no release to download, and nothing that ties a published checkpoint to a commit.
The news timeline itself is the best evidence in the file for the maintenance claim, and it is a good one: twelve dated entries from mid-2025 to mid-2026, including a first release with checkpoints, a mention that the framework powered the draft model for a flagship open model, a flagship project listing, two bundle phases, and monthly additions of methods and an optional loss. The claim that the code runs out of the box is the one thing in the overview that a reader cannot check, and the timeline is the argument for it.
Three ways to reach the documentation, on two hostnames
A small detail that will cost someone an afternoon: the file links its documentation three ways, on two different hostnames.
The badge row at the top links a documentation site on one suffix. The overview paragraph tells you to check the documentation, and links a second site on a different suffix. The repository's own declared homepage uses the second suffix as well. And the two guides for training are linked as relative paths into the repository rather than to either site.
So a reader following the badge lands on one host, a reader following the prose lands on another, and a reader looking for the training matrix ends up in the repository's documentation directory instead. All three may work; none of the three is the same address, and the file does not explain the difference.
The relative links are the useful case, because the method and topology matrix is the document that tells you which combinations are supported, and having it in the repository means it can be read, searched and reviewed as part of the code rather than fetched from a site that can change.
The model bundle's three resources are also split across a documentation page, an anchor on that page, a model collection, and an archived chat channel link. An archived chat link in a project README is a support surface that no longer exists, which is a small thing to fix and a small thing to notice.
Seven methods, two optional losses, and uneven example coverage
The method table is the substance of the repository, and reading it as data rather than as a list is worthwhile.
Seven methods are named. Two are variants of feature-based autoregressive drafting, one of those adding an attention drift term, and one is a parallel version of the same idea. Three descend from block-parallel drafting: the base one, one adding grouped dynamic convolution with top-k path selection, and one adding a recurrent correction on the logits. The seventh is confidence-scheduled semi-autoregressive generation.
The optimisation column has entries for two losses and blanks for the rest, which tells you the table distinguishes an optional objective from a required one, and that four of the seven methods have no such option listed.
The example coverage is uneven in a way that is probably honest. One method has three configurations spanning online, offline colocated and offline disaggregated. One has four, including a managed-local recipe with a named server and parallel-count configuration. One has two, and both use a smaller four-billion-parameter model while the rest use eight billion, which suggests the newer method was validated on something cheaper first. Two methods have exactly one configuration each.
One configuration in the table is for a 27-billion-parameter mixture of experts with three billion active, which is the only example in the file that is not a dense model of the same size. So the table quietly ranges from a small draft experiment to an early-architecture model, and only the smaller end is covered by every topology.
Editorial conclusion
SpecForge fits a team already serving with one stack and wants to train its own draft models rather than adopt someone else's checkpoint, and the portability claim is the reason to look at it. Four things to settle first. That the draft you train is worth training, because the headline speedup is attributed to the model bundle plus the serving stack together and is evidenced by a dashboard on the documentation site rather than by anything in the repository. That you can reproduce your own run, since the version is read from a plain text file and there are no published releases to pin, even though the news section names two release numbers. That your accelerator is one of the three the dependency manifests cover, because the default manifest pins three packages exactly and leaves the rest floating. And that you read the selected YAML configuration and the supported method/topology matrix: the directory names organize examples, while settings such as model, training strategy and deployment mode live inside the file. Unsupported combinations are rejected rather than silently falling back.
Frequently asked questions
What is SpecForge?
The SGLang team's framework for training speculative decoding draft models, built so a trained draft can be ported to SGLang serving without extra work. It covers seven drafting methods through a single typed training command and supports online disaggregated training plus colocated and disaggregated offline training in one runtime.
Which speculative decoding methods does SpecForge support?
Seven: two variants of feature-based autoregressive drafting, one of which adds an attention drift term, a parallel version of that, two block-parallel variants, one adding grouped dynamic convolution with top-k path selection and one adding a recurrent logit correction, and a confidence-scheduled semi-autoregressive method. Two optional losses are listed, one for the feature-based method and one shared by the block-parallel pair.
How do I run a SpecForge training job?
With one command taking a config path, where the path under the examples directory encodes feature mode, topology and online service ownership. An external recipe leaves the transfer service and serving stack to you or to a scheduler; a managed-local recipe starts them on the local host. There are no method-specific Python entry points.
What does installing SpecForge require?
Python 3.11 or newer, with exact pins on the deep learning framework, the transformers library and the serving framework, and floating versions for everything else in the default manifest. The repository root carries two more dependency manifests for two other accelerator vendors, and optional groups for fused attention, a fused kernel library and data tooling.
Does SpecForge publish releases, and what speedup does it claim?
It publishes no GitHub releases, even though the news section announces version 0.2.0 and version 0.3.0; the package version is read at build time from a version file in the repository root. The speedup claim is up to four times, attributed to a pre-trained model bundle used together with the serving stack rather than to the training framework, with the evidence on a dashboard in the documentation.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/sgl-project-specforge)Star history chart for your README
[](https://hysenlabs.com/projects/sgl-project-specforge)Was this useful?