GPT-SoVITS: 5 seconds to a voice sample, four install routes, and a Docker image that lags the code
GPT-SoVITS is a few-shot voice cloning and TTS WebUI that fine-tunes a speaker's voice from one minute of audio and supports zero-shot synthesis from a five-second sample.
At a glance
- What is it?
- RVC-Boss/GPT-SoVITS is a few-shot text-to-speech and voice conversion toolkit wrapped in a Gradio WebUI, installable through conda scripts or NVIDIA Docker images. The rough edges sit in the environment: dependency ceilings that collide with other projects, a Mac path that trains on CPU on purpose, and an image release cycle slower than the repository.
- Who is it for?
- GPT-SoVITS fits a person who already owns a CUDA machine and is willing to own the environment, since the four Docker services all use the NVIDIA runtime and the Lite image leaves out the ASR and UVR5 models. Skip the Mac GPU path, where the project itself routes training to the CPU, and skip the published image if you need the current code.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
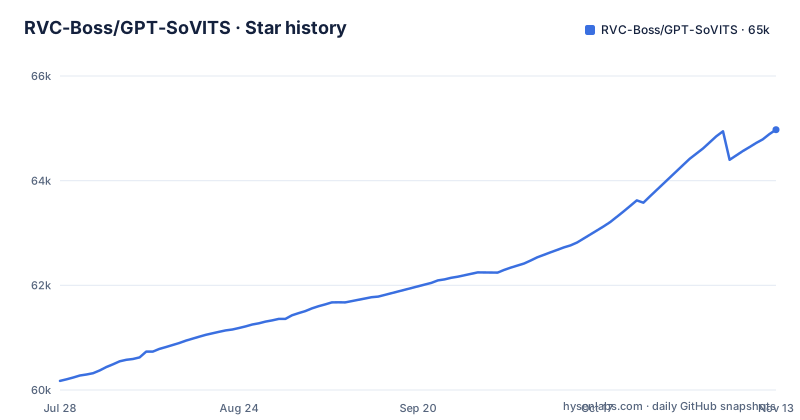
- RVC-Boss/GPT-SoVITS64,973 ★ · +4,800
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| RVC-Boss/GPT-SoVITS | 60.2k | 65k |
4,800 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Zero-shot asks for 5 seconds, few-shot asks for 1 minute of your voice
Three modes sit behind the same WebUI. Zero-shot TTS takes a 5-second vocal sample and turns text into speech immediately, with no training step. Few-shot TTS fine-tunes on about 1 minute of training data for closer voice similarity. Cross-lingual inference speaks a language other than the one in the training audio, and the project names the set it supports: English, Japanese, Korean, Cantonese and Chinese.
Around those modes the WebUI carries the work that normally consumes a project's setup afternoon: voice accompaniment separation, automatic training set segmentation, text labeling, and Chinese ASR. The segmentation and labeling tools are the reason a one-minute dataset is achievable at all, because the raw recording still has to be cut into utterances and transcribed before a model sees it.
install.sh takes a device and a source, and Windows also ships a 7z package
Every platform starts from the same conda environment on Python 3.10. On Linux the device and source choices are explicit:
conda create -n GPTSoVits python=3.10
conda activate GPTSoVits
bash install.sh --device <CU126|CU128|ROCM|CPU> --source <HF|HF-Mirror|ModelScope> [--download-uvr5]
The source flag decides where weights come from, which matters when the default host is slow or unreachable. macOS runs the same script with a shorter device list:
bash install.sh --device <MPS|CPU> --source <HF|HF-Mirror|ModelScope> [--download-uvr5]Windows has a PowerShell entry point with its own flag spelling:
pwsh -F install.ps1 --Device <CU126|CU128|CPU> --Source <HF|HF-Mirror|ModelScope> [--DownloadUVR5]Or skip all of it: download the integrated package and double-click go-webui.bat, the route the project reports testing with win>=10. Either way FFmpeg must be present, through conda, apt or brew, or as ffmpeg.exe and ffprobe.exe placed in the repository root on Windows.
On a Mac the project routes training to the CPU deliberately
The macOS section carries a note worth reading before you buy hardware. Models trained with GPUs on Macs result in significantly lower quality than those trained on other devices, so the project is temporarily using CPUs instead. The macOS install script accepts MPS or CPU as a device value, and the tested environments table lists Apple silicon twice: Python 3.9 with PyTorch 2.5.1, and Python 3.11 with PyTorch 2.7.0.
The table is the compatibility contract, and it holds nine rows: Python 3.10 and 3.11 on PyTorch 2.5.1 with CUDA 12.4, Python 3.11 on PyTorch 2.7.0 with CUDA 12.8, Python 3.9 on PyTorch 2.8.0dev with CUDA 12.8, Python 3.12 on PyTorch 2.7.1 with CUDA 11.8 and with CUDA 12.8, the two Apple silicon rows, and Python 3.9 on PyTorch 2.2.2 on CPU. The install scripts take the device values CU126, CU128, ROCM, MPS and CPU, so the CUDA 12.4 and 11.8 rows have no matching flag.
Five ports, an nvidia runtime and shm_size 16g decide the container run
docker-compose.yaml at the repository root defines four services: GPT-SoVITS-CU126 and GPT-SoVITS-CU128 with everything, and GPT-SoVITS-CU126-Lite and GPT-SoVITS-CU128-Lite with reduced dependencies and functionality. You start one by name:
docker compose run --service-ports <GPT-SoVITS-CU126-Lite|GPT-SoVITS-CU128-Lite|GPT-SoVITS-CU126|GPT-SoVITS-CU128>Each service publishes five ports, 9871 through 9874 plus 9880, declares runtime: nvidia, sets is_half=true in its environment and asks for shm_size 16g. That last value is not decoration: on Windows with Docker Desktop the default shared memory is small and can cause unexpected behavior. is_half is the one environment variable the project documents, and it enables fp16 to cut memory use on a GPU that supports it.
Lite also mounts two weight directories as volumes, tools/asr/models and tools/uvr5/uvr5_weights, so the models survive a container rebuild. The Dockerfile achieves the same for pretrained models and G2PWModel by deleting the copies baked into the image and symlinking them into /workspace/models at startup. Every service mounts the current directory over /workspace/GPT-SoVITS, so the files on your disk take precedence over the ones in the image.
The image release cycle is slower than the repository, and Lite ships no models
The Docker guidance opens by explaining the gap: the code base develops rapidly while the image release cycle is slower, so you should check Docker Hub for the newest tags, pick one for your environment, and pull the latest code into the project root before using an image. Building from the Dockerfile locally is offered as the way to get current changes. The consequence is that a container and a checkout can disagree, and because compose mounts your working directory over /workspace/GPT-SoVITS, the code you read is not necessarily the code the image was built from.
Lite carries a second cost. The Lite image does not include the ASR models or the UVR5 models. You can fetch the UVR5 models yourself, while the program downloads the ASR models as it needs them, so a first run on a machine without a route to the model host stalls until it can reach one.
One more detail in the compose file: it declares version: "3.8" in its schema header, the older file format, while the documented run command uses the docker compose plugin form rather than docker-compose.
requirements.txt puts ceilings on numpy, gradio, pydantic and peft
The dependency file is where an existing environment breaks. numpy<2.0 and librosa==0.10.2 sit near the top, and the ceilings matter more than the pins: gradio<5, peft<0.18.0, pydantic<=2.10.6, torchmetrics<=1.5, ctranslate2>=4.0,<5 and transformers>=4.51,<5. A neighbouring project that needs a newer Gradio, or that fine-tunes with a newer PEFT release, cannot share this environment..
The same file decides what gets installed per machine. onnxruntime is requested only on aarch64 or arm64 platforms and onnxruntime-gpu only on x86_64 or AMD64, python_mecab_ko is skipped when sys_platform is win32, and opencc arrives with --no-binary=opencc, which forces a source build instead of a wheel. That last line means a compile step wherever no prebuilt option exists.
The manual route explains its own ordering: extra-req.txt is installed with --no-deps first, then requirements.txt, a sequence that only makes sense if extra-req holds packages whose own dependencies must not be pulled in.
The README quotes 0.014 on a 4090 and 0.526 on an M4 CPU
Inference speed is one of the few places the project publishes numbers, and it does so defensively. RTF for GPT-SoVITS v2 ProPlus is given as 0.028 tested in a 4060Ti, 0.014 in a 4090, where 1400 words produce roughly 4 minutes of audio in 3.36 seconds of inference, and 0.526 in an M4 CPU. The README then asks readers not to dismiss GPT-SoVITS for slow inference and points at a Hugging Face space running on half an H200 for trying high-speed inference without the hardware.
Read the two ends of that range together and the hardware gap is the entire story. The M4 CPU figure is more than thirty times the 4090 figure, and both describe the same v2 ProPlus build, so nothing about the model changes between them. If your plan is interactive generation on a laptop, the number to plan against is the CPU one.
webui.py, api.py, api_v2.py and two notebooks are the entry points
Four entry points sit at the repository root and which one you want depends on what you are building. go-webui.bat and go-webui.ps1 start the WebUI on Windows, webui.py is the same interface from source, api.py and api_v2.py are the HTTP surface..
For a first look without a machine of your own there are Colab-WebUI.ipynb and Colab-Inference.ipynb in the repository root, the Hugging Face demo space, and an AutoDL Cloud Docker route offered specifically for users in China. Documentation is published in five languages, English, Simplified Chinese, Japanese, Korean and Turkish, with the user guide hosted outside the repository and an English changelog beside the README.
The repository is MIT licensed.
Editorial conclusion
GPT-SoVITS fits a person who already owns a CUDA machine and is willing to own the environment, since the four Docker services all use the NVIDIA runtime and the Lite image leaves out the ASR and UVR5 models. Skip the Mac GPU path, where the project itself routes training to the CPU, and skip the published image if you need the current code. Before starting, check that your Python sits in the tested 3.9 to 3.12 range and that the ceilings in requirements.txt, numpy below 2.0 and gradio below 5, do not collide with anything else in the environment.
Frequently asked questions
how to install gpt-sovits
Create a conda environment on Python 3.10, then run install.sh on Linux or macOS with a device and source flag, or install.ps1 through PowerShell on Windows. Windows users can instead download the integrated package and double-click go-webui.bat, and FFmpeg has to be available in all cases.
what is gpt sovits
GPT-SoVITS is a few-shot voice conversion and text-to-speech project served through the GPT-SoVITS-WebUI. Zero-shot mode uses a 5-second vocal sample, few-shot fine-tuning uses about 1 minute of training data, and cross-lingual inference supports English, Japanese, Korean, Cantonese and Chinese.
is gpt sovits free
The repository is released under the MIT license. Trying it costs nothing before you install anything: the project points at a Colab notebook, a Hugging Face demo space and an AutoDL Cloud Docker option for users in China, alongside the local conda and Docker routes.
how to use gpt-sovits
Start the interface with go-webui.bat on Windows or webui.py from the repository root, then pick a mode: zero-shot from a 5-second sample, or few-shot after segmenting, labeling and transcribing a recording with the built-in ASR tools. Users in China are pointed to a separate AutoDL Cloud Docker option for the full functionality online.
how to use gpt sovits api
The repository root carries api.py and api_v2.py alongside webui.py and config.py. The docker-compose.yaml services publish five ports, 9871 through 9874 plus 9880, and the Dockerfile exposes the same five, with runtime: nvidia enabled.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/rvc-boss-gpt-sovits)Star history chart for your README
[](https://hysenlabs.com/projects/rvc-boss-gpt-sovits)Was this useful?