Kindly Web Search MCP Server: search results with the answers attached
Kindly Web Search MCP Server: Web search + robust content retrieval for AI coding tools (Claude Code, Codex, Cursor, GitHub Copilot, Gemini, etc.) and AI agents (Claude Desktop, OpenClaw, Hermes, etc.). Supports Serper, Tavily, and SearXNG.
At a glance
- What is it?
- A Python MCP server that pairs a multi-provider web search with per-site content handlers for StackExchange, GitHub, Wikipedia and arXiv, plus a headless Chromium loader for everything else. Its value is in the retrieval layer rather than the search ranking, and its weak points are the dependency floors it re-resolves on every start and the character ceilings that decide how much of a thread survives.
- Who is it for?
- Kindly earns its place when your agents work from search results and your hard failures live in a comment thread rather than in a documentation page, because the handlers target exactly those sources and the character budgets are sized to hold a full StackExchange answer or a paper body. Skip it if every lookup you need lands on a known documentation domain, where a plain scraper plus one API key is less machinery to maintain.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 27 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
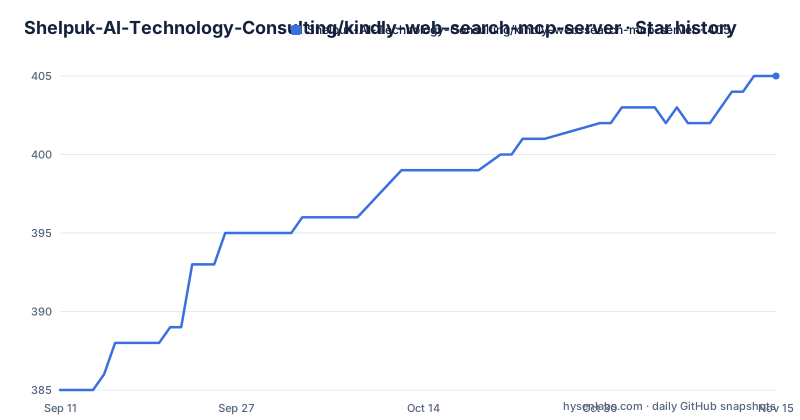
- Shelpuk-AI-Technology-Consulting/kindly-web-search-mcp-server405 ★ · +20
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| Shelpuk-AI-Technology-Consulting/kindly-web-search-mcp-server | 385 | 405 |
20 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
web_search carries page_content, so the follow-up scrape is optional
Two tools are exposed and nothing else. `web_search(query, num_results=3)` returns the top results as `title`, `link`, `snippet` and `page_content`, where the page content is Markdown and marked best-effort. `get_content(url)` returns `page_content` for a single address, also best-effort. The default result count of three is baked into the signature rather than left to configuration, so a client asking for more has to pass its own number.
The reason `page_content` sits inside the search result is the problem the project sets out to solve. A title, a URL and a snippet leave the useful half of a thread behind, so an assistant has to make a second call to fetch the page, and the project notes that when it does, most scrapers return either incomplete content or the entire page including navigation panels and ads. Carrying the extracted body in the first response is meant to remove that second hop. Both fields are labelled best-effort, which is the project's own hedge on how much of the page survives extraction.
Six handlers are tried in order before Chromium sees a URL
Every URL goes through a fixed priority chain and the first handler that recognises it wins, so the choice is made from the address rather than from anything the caller passes. Priority one is StackExchange through the StackExchange API, covering StackOverflow and the rest of the network. Two and three are GitHub Issues and GitHub Discussions, both through the GitHub GraphQL API. Four is Wikipedia through the MediaWiki Action API. Five is arXiv through the Atom API with the PDF converted to Markdown. Six is everything else, handled by a universal HTML loader built on headless Chromium.
The first five all use `httpx[socks]` as the HTTP client and all of them honour `HTTP_PROXY`, `HTTPS_PROXY` and `ALL_PROXY` over HTTP and SOCKS5. Only the Chromium path has no proxy row in that table, which matters for anyone whose network reaches the public internet through a proxy. What the specialised handlers buy is the conversation rather than the page: the project describes the return as questions, answers, comments, reactions and metadata in a single call.
Eight provider keys sit behind one fixed selection order
At least one search provider key is required, and the order is not negotiable by configuration. The example environment file states it as a comment and then lists one variable per provider:
# Selection order is: Serper -> SerpBase -> Tavily -> SearXNG -> Sofya -> You.com -> Serply -> apifare.
SERPER_API_KEY=
# SerpBase (Google results, https://serpbase.dev)
SERPBASE_API_KEY=
TAVILY_API_KEY=
# Sofya web search (https://sofya.co)
SOFYA_API_KEY=
# You.com web search (https://you.com/platform/api-keys)
YDC_API_KEY=
# Serply (Google results, https://serply.io)
SERPLY_API_KEY=
APIFARE_TOKEN=
Seven of the eight take a key. SearXNG is the exception and takes an address instead, through `SEARXNG_BASE_URL`, with a self-hosted instance given as the example. It also carries its own request settings that no other provider has: `SEARXNG_LANGUAGE=en-US`, `SEARXNG_CATEGORIES=general`, `SEARXNG_ENGINES=google,bing`, `SEARXNG_TIME_RANGE=day`, `SEARXNG_SAFESEARCH=1`, plus an optional user agent, a headers JSON blob and `SEARXNG_TIMEOUT_SECONDS=30`. Someone running their own instance gets engine and time-range control that a hosted key cannot offer.
Character budgets differ by source, and a comment ceiling cuts GitHub threads
The output limits are where the retrieval behaviour becomes concrete, and they are not uniform:
STACKEXCHANGE_MAX_CHARS=20000
GITHUB_MAX_CHARS=20000
GITHUB_MAX_COMMENTS=50
WIKIPEDIA_MAX_CHARS=50000
ARXIV_MAX_CHARS=50000
ARXIV_MAX_PAGES=30
StackExchange and GitHub get twenty thousand characters each, while Wikipedia and arXiv get fifty thousand, and arXiv additionally walks up to thirty pages. The GitHub figure carries a second limit that is easy to miss: `GITHUB_MAX_COMMENTS=50` caps comment depth independently of the character budget, so a thread whose answer arrives in comment fifty one is cut even when the token budget is nowhere near spent. `GITHUB_TOKEN` is described as recommended to avoid rate limits, which lifts the API side but not that comment ceiling. StackExchange has its own `STACKEXCHANGE_KEY` for higher quota and `STACKEXCHANGE_FILTER=withbody`, which asks for answer bodies inside the first response rather than leaving them to a follow-up. `WIKIPEDIA_USER_AGENT` and `ARXIV_USER_AGENT` exist for polite identification and default to a contact string you are expected to replace.
The uvx path re-resolves every dependency on each start
The dependency policy is written out at length in the packaging metadata, and its argument is about the install path rather than about the packages. The comment in `pyproject.toml` says the documented install path, given as `uvx --from git+https://...`, re-resolves every bound from PyPI on each start and ignores any lock file, so a breaking major version can arrive with no commit here, no CI run and no alert. The first signal is a user whose server stops starting.
The guard that answers this pins ten bounds, each ceiling set to the next major of the version it was verified against and each floor set to that version's minor series, for nine of the ten. `mcp` is the exception: its floor stays at the older `>=1.25`, the oldest release verified against this server, because raising it to `>=1.29` under the nine-package rule would fail `test_mcp_requirement_still_allows_supported_version`. The bounds come from section 10.2 of `.system_design/TEST_SUITE.md` and are asserted in both directions by `tests/test_dependency_constraints.py`. Verification is dated 2026-09-06, against CPython 3.13 and 3.14, and the comment notes that neither interpreter is resolved by any wired CI leg. The repository also keeps a `requirements-ratchet.txt` at the top level.
Chromium is a base image dependency rather than an optional extra
The container path shows how much weight the fallback loader carries. The image starts from `python:3.13-slim`, matching the `requires-python = ">=3.13"` floor in the packaging metadata, and installs the browser and two supporting packages:
RUN apt-get update && apt-get install -y --no-install-recommends \
        chromium \
        ca-certificates \
        fonts-liberation \
    && rm -rf /var/lib/apt/lists/*
Both `CHROME_BIN` and `CHROME_PATH` are pointed at `/usr/bin/chromium`. A comment in the file says these are the headless browser dependencies for the nodriver-based universal HTML loader, and that chromium is driven directly over CDP with no webdriver needed. So the browser is not a pip extra that can be skipped on a machine that only needs StackExchange answers; it is a system package in the shipped image. The rest of the image copies only `pyproject.toml`, `README.md` and `src`, installs the package with pip, creates an unprivileged user with uid 10001, and starts `mcp-web-search`. Runtime knobs are small: `LOG_LEVEL=WARNING` writing to stderr to keep stdio clean, `KINDLY_DIAGNOSTICS=0`, and `FASTMCP_HOST` and `FASTMCP_PORT` defaulting to `127.0.0.1` and `8000` when you run HTTP or SSE instead of stdio.
No published releases, so 0.1.9 in the metadata is the only version marker
The repository has no GitHub releases, which leaves the version string in `pyproject.toml` as the only place a number is recorded. That file reads `version = "0.1.9"`, with hatchling as both build backend requirement and backend, and a description of the package as an MCP server for Serper web search plus content retrieval. Judging activity from the repository record, the last push landed on 2026-09-28, the repository is not archived, and one issue is open.
The layout suggests where the effort goes. Three separate coverage files sit at the root, `.coveragerc`, `.coveragerc-gate` and `.coveragerc-subprocess`, next to a `.requirements/` directory and the ratchet file. A `.system_design/` directory holds the document the dependency bounds cite, and `tests/` and `scripts/` sit alongside `src/`. `SECURITY.md`, `.dockerignore`, `.gitattributes` and `funding.json` round out the top level, and there is a single example script, `examples/script_run_mcp_tools.py`, for driving the tools from Python rather than through a client.
Editorial conclusion
Kindly earns its place when your agents work from search results and your hard failures live in a comment thread rather than in a documentation page, because the handlers target exactly those sources and the character budgets are sized to hold a full StackExchange answer or a paper body. Skip it if every lookup you need lands on a known documentation domain, where a plain scraper plus one API key is less machinery to maintain. Before you depend on it, pin the provider keys you actually intend to use, raise GITHUB_MAX_COMMENTS if a decision sits in comment fifty one, and check that mcp >=1.25 resolves on your interpreter, since the documented uvx path reinstalls from PyPI on each start and reads no lock file.
Frequently asked questions
What tools does kindly-web-search-mcp-server expose?
Two. `web_search(query, num_results=3)` returns top results as `title`, `link`, `snippet` and `page_content`, and `get_content(url)` returns `page_content` for a single address. Both are described as Markdown and best-effort.
Does kindly-web-search-mcp-server need Chromium installed?
The shipped container image installs it, with chromium, ca-certificates and fonts-liberation from the Debian package sources and both `CHROME_BIN` and `CHROME_PATH` set to `/usr/bin/chromium`. It is used by the nodriver-based universal HTML loader and driven directly over CDP, with no webdriver.
What Python version does kindly-web-search-mcp-server need?
`requires-python` is `>=3.13` in `pyproject.toml`, and the Dockerfile builds from `python:3.13-slim`. The dependency verification in the packaging metadata covers CPython 3.13 and 3.14.
Why does kindly-web-search-mcp-server ask for a GITHUB_TOKEN?
It is optional but described as recommended to avoid rate limits, since GitHub Issues and Discussions both go through the GitHub GraphQL API. A separate limit applies regardless of the token: `GITHUB_MAX_COMMENTS` defaults to 50.
How many characters does kindly-web-search-mcp-server return from a source?
The defaults are 20000 for StackExchange, 20000 for GitHub, 50000 for Wikipedia and 50000 for arXiv, with arXiv also walking up to `ARXIV_MAX_PAGES=30`. Every one of these is an environment variable and can be raised.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shelpuk-ai-technology-consulting-kindly-web-search-mcp-server)Star history chart for your README
[](https://hysenlabs.com/projects/shelpuk-ai-technology-consulting-kindly-web-search-mcp-server)Was this useful?