MCP Local RAG keeps the index, the embeddings and the queries on your machine
Local-first RAG server for developers. Semantic + keyword search for code and technical docs. Works with MCP or CLI. Fully private, zero setup.
At a glance
- What is it?
- mcp-local-rag is a TypeScript MCP server that indexes PDF, DOCX, Markdown and text files locally and answers queries with semantic retrieval plus a keyword boost. No API key, no Docker, no Python and no external database, at the cost of a first-run embedding model download of about 90 MB.
- Who is it for?
- Adopt MCP Local RAG when the documents cannot leave the machine, since parsing, embeddings, storage and search all run locally and hybrid retrieval still catches API names and error codes. Do not adopt it to index source code, spreadsheets or scanned figures, because file ingestion does not cover those.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
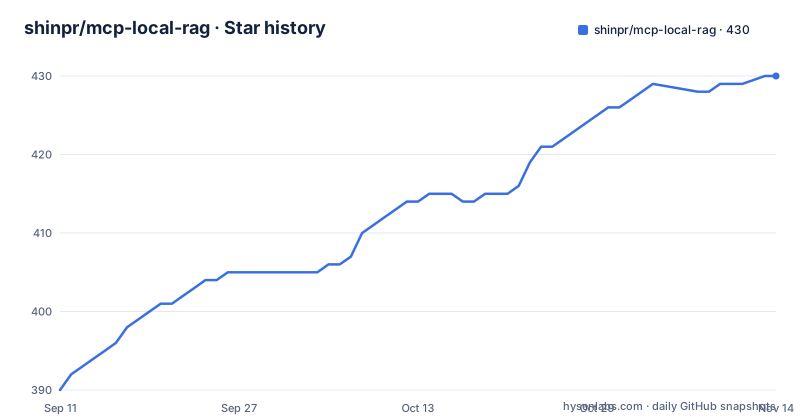
- shinpr/mcp-local-rag430 ★ · +40
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| shinpr/mcp-local-rag | 390 | 430 |
40 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
BASE_DIR is the document root and the security boundary
The server reads one directory and nothing else. You point it at a folder with the BASE_DIR environment variable, and that same variable is described as the security boundary for file operations: MCP file paths have to be absolute and have to stay inside a configured document root. There is no home-directory sweep and no default mount.
What runs inside that boundary is parsing, embeddings, storage and search. After the initial model download, text ingestion and search work offline, which is the reason the project exists: some document sets cannot be sent to a hosted embedding service because of confidentiality or organizational policy, and a local index keeps them searchable without adding a per-query API cost. The stated requirements are Node.js 22 or later, internet access on the first use to fetch the npm package and the embedding model, and a directory of documents. No API key, Docker, Python or external database is required.
Ingestion covers PDF, DOCX, TXT and Markdown, either file by file or by syncing a directory.
Registering the stdio server means four different config shapes
mcp-local-rag speaks the standard MCP protocol over a local stdio server, so registering it is a matter of describing a command and its environment in whatever format the client expects. Claude Code takes a single command:
claude mcp add local-rag --scope user --env BASE_DIR=/absolute/path/to/your/documents -- npx -y mcp-local-ragCodex reads a TOML table instead, at ~/.codex/config.toml:
[mcp_servers.local-rag]
command = "npx"
args = ["-y", "mcp-local-rag"]

[mcp_servers.local-rag.env]
BASE_DIR = "/absolute/path/to/your/documents"
Cursor keeps its own JSON shape in ~/.cursor/mcp.json, with the environment under an env key:
{
  "mcpServers": {
    "local-rag": {
      "command": "npx",
      "args": ["-y", "mcp-local-rag"],
      "env": {
        "BASE_DIR": "/absolute/path/to/your/documents"
      }
    }
  }
}
OpenCode's file at ~/.config/opencode/opencode.json, or opencode.jsonc, uses mcp with a type of local and an environment object. Four formats for one stdio command is the friction in this project, and it is worth expecting to write the block by hand.
The first sync downloads about 90 MB before ingestion starts
After registering the server you restart the client and ask it to build the index. That first sync downloads the default embedding model, about 90 MB, and may take 1 to 2 minutes before ingestion even starts; later runs read the local cache.
Sync itself is asynchronous. `sync_start` reconciles the index with all configured roots or a single path, ingests new and changed files, skips byte-identical files and removes entries for files that no longer exist. It returns a `jobId` immediately, and the client polls `sync_status` until the state becomes `succeeded` or `failed`. Nothing in the README suggests a streaming progress log, so a client that waits for the wrong signal will look stuck.
Two details decide what a later sync can change. A changed PDF keeps the visual profile it was indexed with, and `sync_start` cannot change it. Setting `STORE_IMAGES=true` stores supported PDF and DOCX images for new or changed files selected by sync, while unchanged files stay skipped, so switching image storage on does not backfill an existing index.
Keyword reranking is what keeps API names out of the miss pile
Pure semantic retrieval is good at intent and bad at identifiers. Technical documents live on exact strings, and the project's answer is a hybrid query: `query_documents` combines semantic similarity with keyword matching so a query can hit both a concept and a literal API name, class name or error code. The stated reason for the split is that semantic search alone can miss those identifiers, and keyword reranking keeps the terms visible without giving up natural-language retrieval.
That is also the difference in approach from a hosted embedding service. Sending chunks to an external provider buys quality you can call over a network and charges per query, and it puts the documents somewhere you may not be allowed to put them. This server keeps parsing, embedding and search on the machine, which is cheaper per query and private, at the cost of owning the model download and the disk.
Results come back with the text, the source path, a title, the chunk index, a relevance score and any images stored on that chunk. Over MCP each image comes back as an image content block paired with its result identity, while the CLI adds an `images` array to its own output.
Chunking follows topic boundaries and keeps code blocks whole
Documents are split at topic boundaries rather than fixed character counts, and Markdown code blocks stay intact inside a chunk. For technical material that is the difference between a retrievable snippet and a fragment that cuts a function signature in half, and it is why `read_chunk_neighbors` exists as its own tool: from a hit you can pull the surrounding chunks back instead of accepting whatever the single match contained.
The terminal path uses the same index as the server. The CLI takes the current directory as its document root by default, so running both commands from one directory is what keeps them pointed at the same default index; set BASE_DIR and DB_PATH explicitly when you want them somewhere else.
npx mcp-local-rag ingest ./docs/
npx mcp-local-rag query "authentication API"
The remaining tools are inventory and repair: `list_files` shows supported files and their ingestion state, `ingest_file` adds or replaces one file, `delete_file` removes an indexed file or an `ingest_data` item, and `status` reports index and search status. Re-ingesting a path replaces its existing chunks rather than appending to them.
Excel, PowerPoint, images and source code are refused by file ingestion
The supported-input table is short, and the gaps are stated rather than implied. PDF, DOCX, TXT and Markdown go in through file ingestion or a directory sync. HTML is different: fetching a page is not built into the server, so an MCP client has to fetch the HTML itself and hand it to `ingest_data`, which cleans it with Readability and converts it to Markdown. Plain text and Markdown already held in memory go the same way, with a stable source identifier.
Excel, PowerPoint, standalone images and source-code file extensions are not supported by file ingestion at all. A code-oriented assistant is the obvious audience for this server, and the repository it indexes has to be documentation rather than source. PDFs are the one place images matter: they can optionally use a local vision model to describe figures, and the project is explicit that this is neither OCR nor image search.
One operational detail is easy to miss: only one sync job record is kept by the server process, a newer job replaces a finished record, and restarting the server discards what was left.
MIT licensed, pre-1.0, and built on a pnpm workspace
The package is mcp-local-rag at version 0.20.0, MIT licensed, authored by Shinsuke Kagawa, and published with just dist and skills in its files array. Releases came fast through September and October 2026: v0.19.0 on 2026-09-20, v0.19.1 on 2026-09-22 and v0.20.0 on 2026-10-01, which is also the date of the last push to the repository. Nothing here is version 1.0 yet.
The internals show what the project is made of. Keywords name lancedb, transformers and huggingface, and the scripts cover a plain tsc build, a tsx dev entry, a vitest run on the cpu device, a separate test:perf target for read-neighbor performance, and three WebGPU test paths that run the ingest, search and embedding integration suites on a different device. A repository laid out with pnpm-lock.yaml and pnpm-workspace.yaml is worth knowing about when you clone it to read the source, since the documented install path is npx against the published package.
There is a skills directory in the tree as well, and it ships in the tarball, so the MCP client can pick up guidance for the tools alongside the server itself.
Editorial conclusion
Adopt MCP Local RAG when the documents cannot leave the machine, since parsing, embeddings, storage and search all run locally and hybrid retrieval still catches API names and error codes. Do not adopt it to index source code, spreadsheets or scanned figures, because file ingestion does not cover those. Verify first that `npx -y mcp-local-rag` completes its first sync on your hardware, because that sync is where the embedding model download and the wait before ingestion starts land.
Frequently asked questions
How do I use RAG locally with mcp-local-rag?
Register `npx -y mcp-local-rag` as a local stdio MCP server with BASE_DIR set to your document directory, restart the client and ask it to build the index. The first sync downloads the default embedding model, about 90 MB, and may take 1 to 2 minutes before ingestion starts; later runs use the local cache.
Is MCP needed for RAG with mcp-local-rag?
No. The CLI exposes the same index as the server, so `npx mcp-local-rag ingest ./docs/` and `npx mcp-local-rag query "authentication API"` work without an MCP client. The CLI uses the current directory as its document root by default, and you can set BASE_DIR and DB_PATH explicitly instead.
Which file types can MCP Local RAG index?
File ingestion accepts PDF, DOCX, TXT and Markdown. HTML is not fetched for you: a client fetches the page and passes the HTML to `ingest_data`, which cleans it with Readability and converts it to Markdown. Excel, PowerPoint, standalone images and source-code file extensions are not supported by file ingestion.
Where does MCP Local RAG keep its index and can it read outside my folder?
BASE_DIR is the document root and the security boundary for file operations. MCP file paths must be absolute and must stay inside a configured document root, and the CLI uses the current directory as its root by default unless you set BASE_DIR and DB_PATH yourself.
Does MCP Local RAG need an API key or a hosted embedding service?
No API key, Docker, Python or external database is required. Document parsing, embeddings, storage and search run on your machine, and after the initial model download text ingestion and search work offline.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shinpr-mcp-local-rag)Star history chart for your README
[](https://hysenlabs.com/projects/shinpr-mcp-local-rag)Was this useful?