Shrine: two plugins for the form redisplay, and a docs image on Node 8.11.4
File Attachment toolkit for Ruby applications
At a glance
- What is it?
- shrinerb/shrine is a Ruby file attachment toolkit whose minimal setup is nine lines of initializer and three plugins, two of which exist only to make a file survive a form redisplay, and whose Dockerfile copies a docs path the repository does not have.
- Who is it for?
- Adopt it if you want a single attachment column, a plugin system you load piecemeal, and storage you can swap from local disk to S3 or Cloudinary without restructuring your models, and read the website rather than the README because the README is a happy path plus links.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 10 days ago.
- What is it written in?
- Mainly Ruby, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
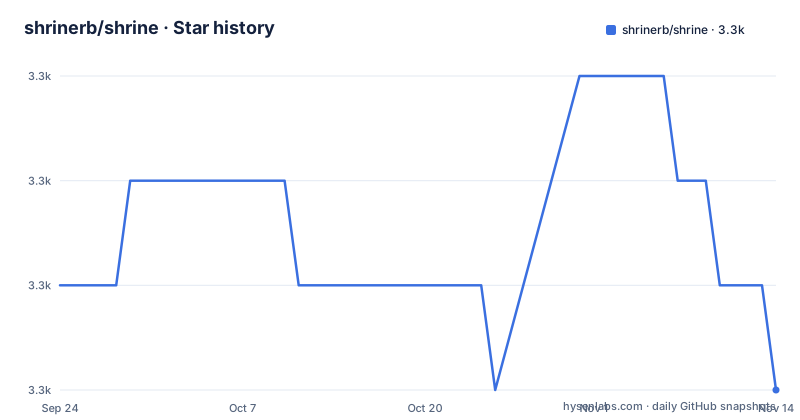
- shrinerb/shrine3,283 ★ · -1
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| shrinerb/shrine | 3.3k | 3.3k |
-1 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The Dockerfile copies ./docs while the repository has a directory called doc
The repository listing has eighteen top level entries and one of them is doc/, singular. The Dockerfile copies ./docs, plural. There is no docs directory in the listing, so the second COPY in the image build refers to a path that does not exist in the tree as published.
That is the kind of mismatch that either means the documentation directory was renamed at some point and the Dockerfile was not, or means the Dockerfile was written against a different branch layout and nobody rebuilt the image. Either way it is a copy of the file system, not a glob and not a wildcard, so it fails loudly at build time rather than producing an image with missing content.
It is a small thing on its own, and it is worth naming mostly because of where it sits. A README that is essentially a happy path plus thirty link definitions sends you to a documentation site hosted out of this repository. If the build for that site does not match the tree, the failure surfaces to whoever is setting up a preview, not to whoever is installing the gem, and the person hitting it has no reason to suspect a directory name.
The other top level entry with no counterpart in the README is SELF_CONTAINED_EXAMPLE.md, which nothing in the visible documentation links to. Between that file and the doc/ naming, the repository has drifted a little away from its own front page.
The documentation image pins Node 8.11.4 and installs with a bare yarn install
The whole Dockerfile is ten lines. It builds FROM node:8.11.4, sets the working directory to /app/website, exposes ports 3000 and 35729, copies the docs and website directories, runs yarn install, and finishes with a CMD of yarn start.
Node 8.11.4 is a specific old point release, and it is the entire runtime for the documentation site. Pinning a base image that precisely is defensible for reproducibility and is how you get a documentation toolchain that still installs. It is also a toolchain choice made before most of the current JavaScript ecosystem existed, and nothing in the file says whether that was deliberate.
The install step is a plain yarn install with no frozen lockfile and no version of yarn pinned anywhere in the file. So the image is pinned at the operating system level and unpinned at the package manager level, which is the least useful combination if you are trying to make a documentation preview reproducible: the base layer will not drift, and the dependencies will.
The exposed ports deserve a question. 3000 is the conventional port for a JavaScript web server. 35729 is not a port anyone picks for a website; it is the port that Ruby's WEBrick server binds by default. Its presence in an EXPOSE line suggests the website's start script may be shelling out to something Ruby, or that the line was copied from a configuration that had that history. Either way, nothing in the repository explains it.
Two of the three plugins in the minimal setup exist to survive a form redisplay
The installation is one command:
bundle add shrineThen an initializer that requires the gem, declares two storages and loads three plugins:
require "shrine"
require "shrine/storage/file_system"

Shrine.storages = {
  cache: Shrine::Storage::FileSystem.new("public", prefix: "uploads/cache"), # temporary
  store: Shrine::Storage::FileSystem.new("public", prefix: "uploads"),       # permanent
}

Shrine.plugin :activerecord           # loads Active Record integration
Shrine.plugin :cached_attachment_data # enables retaining cached file across form redisplays
Shrine.plugin :restore_cached_data    # extracts metadata for assigned cached files
Read the three plugin lines together and two of them are not about storage or about an ORM. :activerecord loads the Active Record integration. :cached_attachment_data is described as enabling retention of the cached file across form redisplays. :restore_cached_data extracts metadata for assigned cached files.
So of the three plugins in the shortest possible working configuration, one wires up the ORM and the other two exist to handle a single situation: a user submits a form, something fails validation, the form is rendered again, and the file they already picked has to survive the round trip. A library that did not stage uploads through your own application would not need either plugin.
That design is visible in the form itself, where a hidden field carries the cached data next to the file field:
<%= form_for @photo do |f| %>
  <%= f.hidden_field :image, value: @photo.cached_image_data, id: nil %>
  <%= f.file_field :image %>
  <%= f.submit %>
<% end %>
The hidden field posts the cached data, the file field posts the bytes, and the two plugins keep them consistent across the redisplay. The id: nil on the hidden field is there so it does not emit a second DOM id for the same attribute.
The attachment is one text or jsonb column, and jsonb is the one that wants an index
There is no join table and no attachment model. The README's instruction is to add a column named after the attachment to the table you want to attach files to, so an image attachment on a photos table becomes an image_data column.
The generator is shown with a text type and a comment offering the alternative:
$ rails generate migration add_image_data_to_photos image_data:text # or :jsonbSo the default is a serialised text blob, with jsonb offered as the other option. And the README attaches one instruction to that option: if you use jsonb, consider adding a gin index for fast key value pair searchability within image_data.
That single sentence tells you the trade. Shrine stores enough structured data per attachment that you can query inside the column, and the moment you want to do that, the column stops being an opaque blob and becomes something you index. A text column gives you the simplest migration and no query surface. A jsonb column gives you queryability and a second thing to maintain.
What you get in the column follows from the setup rather than from the schema: a cache key, a store key, the extracted metadata that the validation feature checks against, and the MIME type and size information that the metadata plugin fills in. That is why restore_cached_data has to extract metadata for assigned cached files, because a cached file that arrives back from a redisplayed form has to carry the same metadata a freshly uploaded one would.
cache and store are two prefixes inside one public directory
The initializer declares two storages and the difference is a prefix string. Both are FileSystem storages rooted at public. The cache storage uses the prefix uploads/cache and is annotated as temporary. The store storage uses the prefix uploads and is annotated as permanent.
That is the whole of the staging model in the minimal configuration. A file arrives, goes to the cache, and the attachment points at it. When it is promoted it moves to the store location. Because both live under the same public directory, the prefix is the only thing separating them, and the cache is deliberately the more specific path so that the permanent tree does not have to be enumerated to find the temporary one.
Two things follow that the short example does not spell out. The first is that public is a web-served directory, so with this configuration uploaded files are reachable by URL before they are promoted, which is normal for this shape of setup and worth knowing if the cache holds anything you would not want served. The second is that promotion is a move between prefixes on the same volume, so it is cheap, and so is any operation that has to read the cached copy again.
The same two-storage shape is what the storage highlights generalise. Disk, AWS S3, Google Cloud and Cloudinary are described as alternatives, and the initializer is the only place in the visible documentation where you see which one is in use. Swapping to a cloud backend means changing these two lines and, in the direct upload cases, changing how the browser is told where to send bytes.
The Rails demo lives in another maintainer's repository
The Links table has one row for demo code and it offers two things: a Roda demo at the relative path /demo, and a Rails demo at a github.com repository belonging to someone else.
The repository listing does contain a demo directory, so the Roda example is in the project. The Rails example is not. The link points at a separate repository under a different account, which means the reference implementation for the most common Ruby web framework is maintained outside the framework's own tree, on a different cadence, and with no relationship to the gem's release process.
That matters more here than it would elsewhere, because the setup instructions in the README are Rails instructions. They use bundle add, config/initializers, a Rails migration generator, form_for, and a controller inheriting from ApplicationController. The documented path is the Rails path. The runnable Rails example is somewhere else. So the fastest way to see the thing working in the framework you probably use is to leave this repository and follow a link out of it.
The demo directory itself is substantial. Alongside app.rb, config.ru, config, db, jobs, lib, models, routes, test, uploaders and views, it carries its own Gemfile, its own Rakefile and its own README, which is the shape of a self-contained application rather than a snippet.
The link table is where the multi maintainer reality shows
Shrine is presented as one toolkit, and the link definitions at the bottom of the README quietly show how many people that takes. Two of the storage integrations named in the highlights live outside the project's own organisation: Google Cloud storage points at a repository under the renchap account, and Hanami points at hanami-shrine under katafrakt. Cloudinary and the ROM and Mongoid integrations sit in the shrinerb organisation but in separate repositories.
Image processing goes one step further out. ImageMagick and libvips are both linked through the image_processing gem maintained by janko, in separate documentation pages for each. The resumable upload story points the same way, with S3 multipart uploads handled by janko's uppy-s3_multipart and the tus protocol by janko's tus-ruby-server. Roda itself is credited to jeremyevans and Refile to the refile organisation.
The Inspiration section is explicit about the lineage. Shrine was heavily inspired by Refile and Roda: from Refile it takes the idea of backends, here renamed storages, plus the attachment interface and direct uploads; from Roda it takes the extensible plugin system that the modular design highlight depends on.
The plugin system is therefore not incidental to the design, it is inherited. And a plugin system whose plugins are distributed across half a dozen maintainers is a different maintenance story from a monolith, which is the trade the modular design highlight is buying. The comparison page linked from the first paragraph is where the argument for that trade is made; the link table is where the cost is visible.
No GitHub releases, no open issues, and three places to ask a question
The release situation is empty. The repository publishes no GitHub releases at all, and there is a CHANGELOG.md at the top level instead. For a gem that has been around long enough to have a CHANGELOG, a Rakefile, a gemspec and a wiki, that means the version history lives in the changelog and in the gem itself rather than in the forge.
The issue tracker is empty too, at zero open issues against 3285 stars and 277 forks. For a project with three community surfaces, an empty tracker means either that questions are not landing there or that they are landing and closing, and the repository gives no way to tell which.
Those three surfaces are worth naming because they are not the same thing. There is the wiki at the repository, the GitHub Discussions forum, and a separate Discourse instance at discourse.shrinerb.com. A bug goes to the tracker, a question can go to either forum, and backgrounding library support is a wiki page listing compatible libraries rather than a documented list on the main site.
None of that is a complaint so much as a map. A reader deciding whether to adopt this needs to know that the durable documentation is the website, the durable questions are the Discourse instance, and the version history is a markdown file in the repository rather than a list of tags.
Editorial conclusion
Adopt it if you want a single attachment column, a plugin system you load piecemeal, and storage you can swap from local disk to S3 or Cloudinary without restructuring your models, and read the website rather than the README because the README is a happy path plus links. Two things to check before you commit: the gem has no GitHub releases, so pin and track versions through the changelog, and remember that the minimal configuration stages uploads under your public directory, which means cached files are web reachable before promotion. Skip it if you want a single maintainer to own the whole stack, since the storage, ORM, processing and resumable upload integrations span about half a dozen repositories.
Frequently asked questions
How do I install the Shrine Ruby gem?
Run bundle add shrine, then add config/initializers/shrine.rb requiring shrine and shrine/storage/file_system. Declare Shrine.storages with a cache and a store FileSystem rooted at public, load the :activerecord plugin along with :cached_attachment_data and :restore_cached_data, and add a <name>_data column to the table you are attaching to.
What does Shrine keep in the database column?
One column named after the attachment, such as image_data on a photos table, generated as text or as jsonb. The setup recommends a gin index if you choose jsonb, for fast key value pair searchability inside the column.
Which image processors does Shrine work with?
ImageMagick and libvips, and both are reached through the separate image_processing gem rather than through Shrine itself, with one documentation page per processor. Thumbnails can be generated eagerly at upload time or on the fly when they are requested.
Which ORMs and object stores does Shrine integrate with?
Sequel, ActiveRecord, ROM, Hanami and Mongoid for persistence, and disk, AWS S3, Google Cloud and Cloudinary for storage. Some of those integrations live in other maintainers' repositories, including shrine-google_cloud_storage under the renchap account and hanami-shrine under katafrakt.
How does Shrine compare to other file attachment libraries?
The README names Paperclip, CarrierWave, Dragonfly, Refile and Active Storage as similar libraries and points at a dedicated Advantages of Shrine page for the comparison. It also records that Shrine was heavily inspired by Refile and Roda.
What runtime builds the Shrine documentation site?
A Dockerfile based on node:8.11.4. It sets the working directory to /app/website, exposes ports 3000 and 35729, copies ./docs and ./website, runs yarn install and starts with yarn start. The repository listing has a doc directory rather than a docs one.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/shrinerb-shrine)Star history chart for your README
[](https://hysenlabs.com/projects/shrinerb-shrine)Was this useful?