simple-statistics: no dependencies, eight dev tools, and a readme that hard-codes its own version
simple statistics for node & browser javascript
At a glance
- What is it?
- This is a JavaScript statistics library whose main claim is that it has no dependencies and whose secondary claim is that the source is meant to be read. Both hold up. What is interesting is the machinery around a library that small: a transpiler for a browser nobody develops for any more, a type checker configured twice, a random number generator so the tests are deterministic, and a release script that rewrites the documentation to keep two hard-coded version numbers in step.
- Who is it for?
- Use it when you want a small, readable statistics implementation you can inspect, and pin the version rather than following the readme's snippets, because both browser examples in that document carry a hard-coded release number. Two things to weigh.
- Can I use it commercially?
- Yes. ISC is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly JavaScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
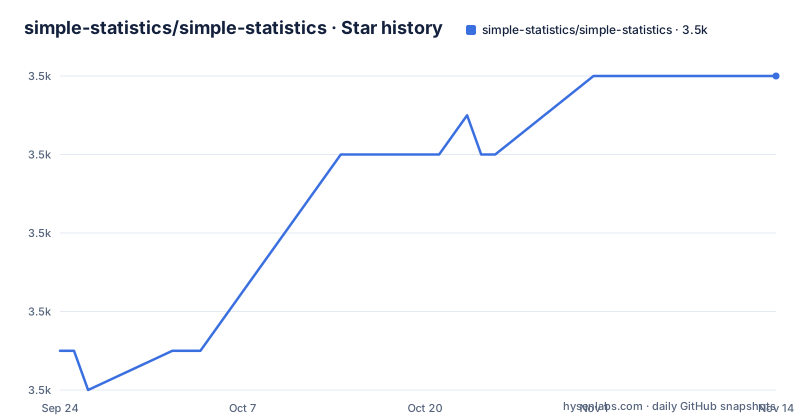
- simple-statistics/simple-statistics3,528 ★ · +7
| Repository | 2026-09-24 | 2026-11-14 |
|---|---|---|
| simple-statistics/simple-statistics | 3.5k | 3.5k |
7 Stars in the last 51 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme hard-codes its own version twice, and a script rewrites it
The browser installation instructions in this readme contain a version number, in two separate snippets, and both are the current release.
The first loads the minified bundle from a content delivery network with the version in the path. The second imports a named export from the same service with the version in the path and a query parameter that asks for the module build.
That is the kind of detail documentation rots on, and this project has a mechanism for it rather than a habit. The repository uses a changesets workflow for releases, and the versioning script runs the changesets version step and then a second step that rewrites the readme.
So the two numbers in those snippets are not maintained by hand, they are substituted at version time. That is a better arrangement than most, and it has an interesting consequence: the readme's browser instructions are correct by construction, and the interesting part is not the version but the two different files the two routes serve.
The plain script tag loads the minified bundle:
<script src='https://unpkg.com/[email protected]/dist/simple-statistics.min.js'>
</script>
The module route loads the untranspiled source entry, which is why the readme tells you that feature is still experimental in that service and describes it as bleeding-edge.
A git-protocol remote URL in a manifest touched this year
One line of the manifest is a small time capsule.
The repository field for the package uses the original git protocol address rather than the https one, the form that hosting providers stopped accepting several years ago. It is the kind of line that survives because nothing reads it: package managers do not use the repository field to fetch, they only display it on the package page.
It is a harmless line, and it is worth mentioning only because it illustrates what happens to a mature library's metadata. The author field is current and the version field is current, the last commit arrived days ago, and the address a human would copy from the package page to clone the project uses a protocol that no longer works.
Everything else in that block is conventional. There is a separate author, a description of one word and a half, and a list of what the published package contains: the source directory, the built output, the licence, and the two entry files.
The published list is the one to note, because it includes both the source directory and the built output. A consumer installs the source and the bundles, and the manifest's own entry fields decide which one they get.
The every-browser promise rests on a transpiler that stopped moving
The readme says the library is designed to work in all modern browsers, explicitly including the oldest one, as well as in Node.
The mechanism behind that claim is in the development dependencies: a transpiler plugin whose major version is one, added to a Rollup build alongside a minifier plugin.
That transpiler is the piece to look at. It is a Babel-era code transformer that has not seen a release in years, and it is in the dependency list of a project whose most recent commit is from this autumn. So the oldest-browser support in the readme is carried by a component that no longer gets fixes, while the current tooling around it, the bundler, the linter, and the type compiler, is all recent.
That is a coherent position if you read it as a maintenance boundary. The bundle that exists for the oldest browser is frozen, and everything new is built for current engines. But the readme does not draw that line, and a reader deciding whether to ship the bundle has to work it out from a version number in a development dependency.
The package ships three bundle formats, and the readme's oldest-browser route is one of the three.
The no-dependency promise is real, and the whole toolchain is a dev dependency
A library that says it has no dependencies can usually be taken at its word, and in this case a count confirms it.
There are eight development dependencies and no runtime ones. A formatter and linter, a release workflow tool, the transpiler and minifier plugins for the bundler, a documentation generator, a deterministic random number generator, the bundler itself, and the type compiler.
Eight tools for a statistics library is a lot, and each one answers a real question: the linter replaces two tools with one, the release tool is what rewrites the readme, the doc generator lints the documentation comments as part of linting, the bundler produces the three published formats, and the type compiler runs twice with different flags because one pass skips library type checks and the other enforces the modern module resolution rules.
The deterministic random number generator is the most interesting of the eight. Statistical functions are exactly the kind of code that cannot be tested with random inputs, so a seeded generator in the development dependencies is how the test suite gets stable results.
It is a common pattern in a small library: the runtime is clean and the toolchain is not, and the cost of that is borne by anyone forking.
Tests share one process, and the type checker runs twice
The test command is a chain, and reading it tells you what the project considers part of being correct.
Running the tests runs the linter first. The linter has its own pre-step, which invokes the type compiler twice: once skipping the checks inside installed type definitions, and once with no skips and with the modern module and module-resolution settings forced on.
The linter has a post-step too, which runs the documentation tool over the source. So comments in the source are linted, which is the point of a library written to be read: a wrong description is a defect.
Then the tests themselves run on Node's built-in test runner, against the test directory, with process isolation explicitly switched off. That flag is the interesting one. Isolation off means every test file shares a single process, which is a choice you make when a module holds state you want to keep across cases, or when the alternative is a runner that is slower to start than the code under test.
Adding deterministic randomness on top of that gives a suite whose results do not change between runs, which is the only way to test that a mean is a mean.
A Flow config and a TypeScript config in the same root
The root listing contains two type systems' worth of configuration, and only one of them is current.
There is a TypeScript configuration and a hand-written declaration file, the type compiler is the modern one, and the manifest points its types field at the declaration file. That is the live setup.
Beside it is a configuration file for a different type checker, one that predates TypeScript's adoption as the default for a JavaScript project. Nothing in the scripts invokes it: the pre-lint step calls the TypeScript compiler twice and nothing else, and the lint step calls the other tool.
So the Flow configuration is a fossil. That is normal for a project of this age and it costs nothing at build time, but it does mean a contributor looking for the type rules will find two answers and have to work out which one the scripts use.
The file naming in the same directory is equally inconsistent. Three documents are in upper case, one is in lower case with underscores between the words, and the configuration files follow three different conventions: one uses a leading dot with a camel case name, one uses a leading dot with a name, and one has no leading dot at all.
None of this is a functional problem. It is a description of a project whose housekeeping has been added to over a decade rather than reset.
Three bundle formats, three field names pointing at one of them
The manifest's entry points are the most technically dense part of the file, and they are the reason the readme has two browser routes.
There is a main field for the CommonJS consumer, a module field for the bundler consumer, and a types field for the compiler. Those are the three you would expect.
Then there are three more names, the browser field, the unpkg field, and a universal module field, and all three point at the same file: the minified bundle.
So the package publishes a CommonJS build, an ES module build, and a minified universal bundle, and it advertises the universal one under three different field names for three different consumers. The content delivery network reads its own field and the bundlers read the other two.
An exports map then wraps the whole thing with a condition per format plus the package manifest itself, which is the modern way to say the same thing with precedence rules.
The result is a small library whose packaging expresses every distribution format it has ever needed, including the two that exist specifically for the oldest browser in its support statement.
Editorial conclusion
Use it when you want a small, readable statistics implementation you can inspect, and pin the version rather than following the readme's snippets, because both browser examples in that document carry a hard-coded release number. Two things to weigh. The promise of working in every browser is delivered by a transpiler that no longer receives updates, so treat the modern-browser path as the tested one. And the toolchain is wide for the size of the library, so a fork inherits a bundler, two type configurations, two linters, and a release script that edits the documentation.
Frequently asked questions
what is simple statistics
In this repository it is a JavaScript library implementing descriptive, regression, and inference statistics, with no runtime dependencies, written in a style meant to be read as well as run, and usable from Node, from a bundler, from Deno through its npm compatibility layer, or from a script tag in a page.
What are simple statistics?
Here the phrase is the name of that library. The readme describes it as a JavaScript implementation of descriptive, regression, and inference statistics, implemented in literate style with no dependencies and designed to work in every modern browser as well as in Node.
Is basic statistics a difficult class?
That is a question about a course rather than about this repository, which is a library. What it does carry is a list of other statistics libraries, a benchmarks directory in the tree, and a link to published benchmarks in the readme.
What are the 5 basic concepts of statistics?
The repository does not enumerate concepts. What it does is ship implementations across the three families named in its opening line, being descriptive, regression, and inference statistics, and it documents the Node, bundler, Deno, script tag, and browser module routes separately from the feature list.
How do I use simple-statistics without a bundler?
Two documented routes. A script tag loading the minified bundle from a content delivery network, where the library always becomes a global under one fixed name that you may reassign, or the experimental module query parameter on the same service, which serves the untranspiled source and is described in the readme as bleeding-edge.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/simple-statistics-simple-statistics)Star history chart for your README
[](https://hysenlabs.com/projects/simple-statistics-simple-statistics)Was this useful?