Four runtimes and an empty heading inside Spring AI Alibaba DataAgent
Spring AI Alibaba DataAgent
At a glance
- What is it?
- DataAgent answers questions with SQL, runs model-written Python in a container, and renders ECharts reports. Its quick start is precise about four runtimes and a MySQL superuser import, while the sandbox limits, the vector store, the MCP wiring and the knowledge model all live in five Chinese docs the page only names.
- Who is it for?
- DataAgent fits teams already inside the Spring AI Alibaba ecosystem who want a browser UI over natural-language SQL and can supply their own configuration for models, vector store and knowledge. Teams wanting a library, or a stack without Docker, MySQL 5.7, Node 22 and pnpm 11, will find the prerequisites heavier than the payoff.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 56 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
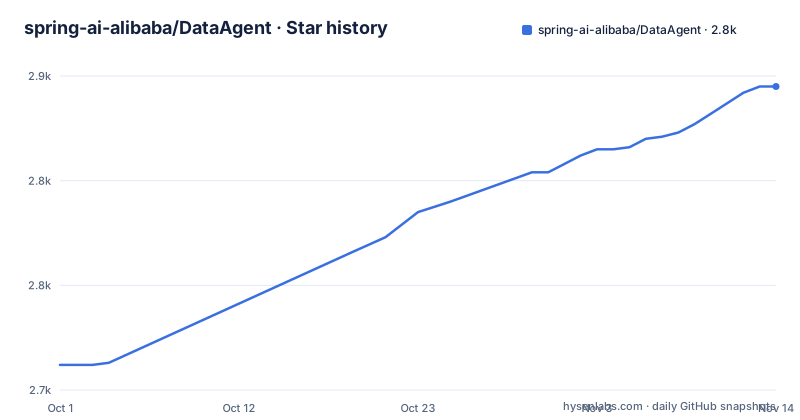
- spring-ai-alibaba/DataAgent2,845 ★ · +133
| Repository | 2026-10-01 | 2026-11-14 |
|---|---|---|
| spring-ai-alibaba/DataAgent | 2.7k | 2.8k |
133 Stars in the last 44 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The project structure heading opens, closes, and never reaches the banner links
The banner block links five anchors: project overview, core features, quick start, documentation, and joining the community. Nine top-level headings follow it, and three of those nine are absent from that list, among them `项目结构`, the project structure section, plus the license line and the star history block. The structure heading is the awkward one, because the next line is already another heading, so nothing sits between the two. The layout does show up in the repository root: `data-agent-frontend-nuxt/` and `data-agent-management/` as the two application modules, then `docs/`, `docker-file/`, `CI/`, `img/`, `.github/`, `pom.xml`, `mvnw`, `mvnw.cmd`, `Makefile`, `LICENSE`, `SECURITY.md` and two contributing guides. Two empty centered div blocks also sit above the first heading. Readers get the shape of the project from the file list, not from the section meant to describe it.
Four runtimes are pinned, and Docker waits for the first Python step
The environment list has five entries with exact floors: JDK 17+, MySQL 5.7+, Node.js 22+, pnpm 11+, and Docker, which is marked as required only when the workflow needs to execute Python steps. That condition is the one worth reading twice, because the feature table describes the analysis path as running generated code in a container per task, so a text-to-SQL-only trial can leave Docker out and the first real analysis cannot. Node 22 and pnpm 11 belong to the frontend alone, and that frontend is a development server rather than a packaged artifact. MySQL is the only database named anywhere, and its schema file sits inside the backend module's own resources directory rather than in a top-level `db/` folder. No Spring AI Alibaba version appears either, even though the opening line says the agent is built on Spring AI Alibaba Graph and links to the parent project, so which framework build you get is decided by the Maven reactor, not by the page.
The one runnable block imports the schema as the database superuser
The entire quick start is one fence with three numbered steps:
# 1. 导入数据库
mysql -u root -p < data-agent-management/src/main/resources/sql/schema.sql

# 2. 启动后端
./mvnw -pl data-agent-management spring-boot:run

# 3. 在另一个终端启动前端
cd data-agent-frontend-nuxt
pnpm install && pnpm dev
The import path points into the backend module, `data-agent-management/src/main/resources/sql/schema.sql`, and the account is `root`, handed over on the command line with `-p`. Nothing narrower is named for the trial, and no later step loads rows, sample data or a demo agent. The backend starts through the Maven wrapper with `-pl`, which restricts the run to that single module rather than the whole reactor, and the frontend is told to run in another terminal, so two processes plus a database are the minimum working shape. The page then hands off explicitly, saying detailed installation and configuration is in `docs/QUICK_START.md`, and the last step is a browser pointed at `http://localhost:3000` and the first data agent.
The sandbox row names four mechanisms and not one number
The feature table is where the real claims sit, and its Python analysis cell is the densest: execution goes through Spring AI Alibaba Sandbox in a container per task, with PEP 723 dynamic dependencies, resource limits, failure retries and automatic cleanup. Four mechanisms, zero values. No memory ceiling, no timeout, no retry count, no cleanup window, and no statement of what the container can reach, which matters when the code inside it was written by a model and the same workflow holds a database login. The reporting row is compressed in the same way, claiming results are aggregated into HTML or Markdown reports carrying ECharts charts, while the feedback row claims a human-in-the-loop mechanism that lets a user intervene at the plan generation stage. The opening paragraph frames all of this as moving past plain Text-to-SQL toward deep analysis and multi-dimensional chart reports. Every specific is delegated to `docs/ADVANCED_FEATURES.md`, which the documentation table credits with the SAA Python sandbox and dynamic dependencies.
OpenAI-compatible models and any vector database, none of them named
The introduction claims full compatibility with the OpenAI interface specification for chat and embedding models, plus the ability to attach any vector database, and it offers Qwen and Deepseek as example services for either private deployment or a mainstream provider. The table adds a built-in model registry that switches between LLMs and embedding models at runtime, and RAG retrieval over business metadata and a glossary of terms to raise SQL accuracy. Not one model identifier, base URL, environment variable name or vector store name appears on the page. Extension is assigned elsewhere too: the developer guide covers adding a vector store or a model, the advanced features file covers custom hybrid retrieval, and `docs/KNOWLEDGE_USAGE.md` explains three kinds of knowledge, semantic models, business knowledge and agent knowledge. For any team picking this up, that configuration is the actual work, and none of it is on the page.
MCP for Claude Desktop and API keys, both deferred to one file
Native MCP support is claimed twice. The introduction says the project works as an MCP server and integrates into Claude Desktop and other MCP-capable tools, and the table entry says it follows the protocol and serves as a Tool Server exposing NL2SQL and agent management capabilities. No server configuration accompanies either claim: no transport, no command line, no port, no environment block. The neighbouring row promises a full API key lifecycle with fine-grained permission control, again with no key format, no header name, no endpoint and no rotation policy. Both land on the same destination, `docs/ADVANCED_FEATURES.md`, which the documentation table describes as covering API key invocation and MCP server configuration. That second one carries more weight than a footnote, because API key invocation is what makes the agent callable from outside the Nuxt frontend, so it is the integration surface for every consumer the browser UI does not cover.
Release candidate seven, and a branch pushed two months past its own tag
The three most recent releases are 1.0.0-rc7 published 2026-07-29, 1.0.0-rc6 on 2026-07-17, and 1.0.0-rc5 on 2026-03-12. Only the newest carries a prefix in its release title, `v1.0.0-rc7`, and none of the three tags carries one, so the naming changed between rc6 and rc7 in a single place. The main branch took its last push on 2026-09-20, close to two months after rc7 appeared, and no newer release is listed, which means the branch you clone is ahead of the newest tag you can install. The repository is not archived, the default branch is `main`, and the license is Apache-2.0 with the `LICENSE` file at the root. The page calls the system enterprise grade while the newest published tag is still a release candidate, a naming mismatch rather than a defect. The counters read 2712 stars, 645 forks and 162 open issues, and the page says nothing about how those issues are handled.
Housekeeping files, a Makefile made of includes, and an empty contributor grid
The root carries `SECURITY.md`, `CONTRIBUTING-zh.md`, `CONTRIBUTING-en.md` and both Maven wrapper scripts, and the community section links the Chinese and English guides as the place to learn the pull request flow. The `Makefile` is one target that re-invokes make with four CI includes and then makes your requested goal depend on it:
_run:
	@$(MAKE) --warn-undefined-variables \
		-f CI/make/common.mk \
		-f CI/make/java.mk \
		-f CI/make/linter.mk \
		-f CI/make/tools.mk \
		$(MAKECMDGOALS)

.PHONY: _run

$(if $(MAKECMDGOALS),$(MAKECMDGOALS): %: _run)
The `$(if ...)` line is the whole trick: whatever goal you type is rewritten to depend on `_run`, so the four CI makefiles load first and any target passes through them. Two loose ends sit on the rendered page. The contributors block is an anchor pointing at the GitHub contributors endpoint with nothing inside it, so the grid renders empty, and the star history entry is a link with empty alt text whose address ends in a bare `&Date` parameter. The community entry itself is the DingTalk group `154405001431`, named as the first DataAgent user group, followed by a note that some accounts cannot join it for security reasons and that applying with a different account is acceptable when circumstances allow.
Editorial conclusion
DataAgent fits teams already inside the Spring AI Alibaba ecosystem who want a browser UI over natural-language SQL and can supply their own configuration for models, vector store and knowledge. Teams wanting a library, or a stack without Docker, MySQL 5.7, Node 22 and pnpm 11, will find the prerequisites heavier than the payoff. Read the five files under `docs/` first, since the README names no vector store, no model identifier and no sandbox limit. Then check whether `1.0.0-rc7` still describes what `main` serves, and import the schema with an account narrower than `root`, because model-written Python runs inside the same workflow.
Frequently asked questions
What does spring-ai-alibaba/DataAgent need installed before its quick start can run?
JDK 17 or newer, MySQL 5.7 or newer, Node.js 22 or newer and pnpm 11 or newer, plus Docker whenever the workflow has to execute a Python step. After the schema import, the backend runs through the Maven wrapper and the frontend serves the UI on port 3000.
Which database account does the DataAgent quick start use to load its schema?
It imports `data-agent-management/src/main/resources/sql/schema.sql` through `mysql -u root -p`, so the documented path assumes a MySQL 5.7+ server and a superuser login typed on the command line. No narrower database user is named on the page, and no step loads sample rows after the schema.
Does the DataAgent README name the vector databases and models it supports?
It does not. The page claims compatibility with the OpenAI interface specification for chat and embedding models and says any vector database can be attached, naming Qwen and Deepseek as example services, but it prints no model identifier, no database list, no base URL and no environment variable name.
How does Spring AI Alibaba DataAgent execute the Python code it generates?
Through Spring AI Alibaba Sandbox, in a container per task, with PEP 723 dynamic dependencies, resource limits, failure retries and automatic cleanup. Those four mechanisms are named without any limit value, retry count or cleanup window, and the page does not state what the container can reach.
Has Spring AI Alibaba DataAgent reached a stable release yet?
No. The newest release is 1.0.0-rc7, published 2026-07-29, after 1.0.0-rc6 on 2026-07-17 and 1.0.0-rc5 on 2026-03-12. The main branch recorded its last push on 2026-09-20, so the branch runs ahead of the newest published tag.
Where is the DataAgent MCP server configured for use with Claude Desktop?
Not on the repository page. It states that the project follows the Model Context Protocol and can act as a Tool Server exposing NL2SQL and agent management, then points readers to `docs/ADVANCED_FEATURES.md`, which is named in the documentation table but not reproduced in the README.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spring-ai-alibaba-dataagent)Star history chart for your README
[](https://hysenlabs.com/projects/spring-ai-alibaba-dataagent)Was this useful?