spring-data-elasticsearch: a Java library whose only Node manifest builds the documentation
Provide support to increase developer productivity in Java when using Elasticsearch. Uses familiar Spring concepts such as a template classes for core API usage and lightweight repository style data access.
At a glance
- What is it?
- The Spring Data module for the Elasticsearch search engine, offering an operations client and a repository layer over documents, with a compatibility matrix, a build guide and a client-configuration example all delegated to external documentation. Its feature list has four grammatical errors in six lines, its Maven snippets declare one repository id twice, and the repository root carries a Node manifest that exists purely to build the docs.
- Who is it for?
- Use this when you want Spring's repository abstractions and object mapping over an Elasticsearch cluster rather than driving the client directly, and treat it as a Spring Data module rather than an Elasticsearch library, since its value is the mapping and query derivation rather than anything engine-specific. Three things to check first.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Java, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
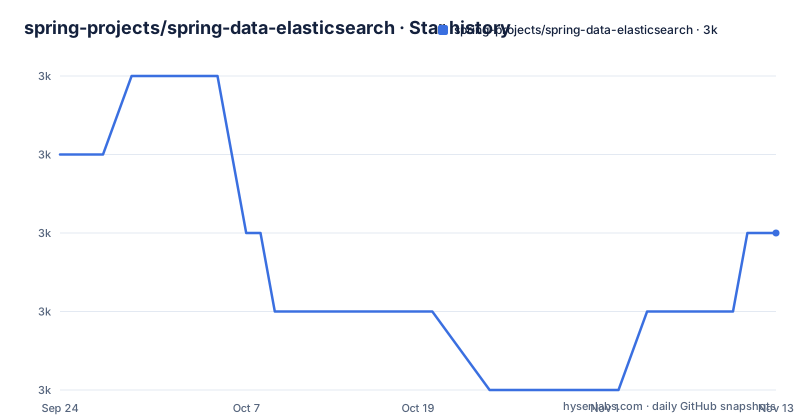
- spring-projects/spring-data-elasticsearch2,960 ★ · -1
| Repository | 2026-09-24 | 2026-11-13 |
|---|---|---|
| spring-projects/spring-data-elasticsearch | 3k | 3k |
-1 Stars in the last 50 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
A Java library whose only Node manifest builds the documentation
The root of a Java library carries a Node manifest, and it does not exist for the library.
It declares six dependencies, all of them documentation tooling: a static site generator, two of its extensions, a tabs extension for the documentation markup, and two Spring-provided extensions for that markup.
So building the reference documentation needs a Node toolchain, while building the library needs a JDK and Maven. Two toolchains in one repository, and the project page never mentions the Node one. A contributor who wants to fix a documentation typo needs to discover that a Node manifest exists at all.
The versions are the more interesting part. Five of the six are prerelease builds, three of them alphas and one a beta. Only the Spring-provided markup extension sits on a stable release. And all six are pinned to exact versions with no range.
Pinning documentation tooling exactly is the right instinct, because a docs build that drifts between machines is a nuisance. Pinning it to prerelease builds is the other half of that trade: the reference documentation anyone builds locally depends on packages the maintainers have not declared stable, and there is no range to widen if one of them turns out to be broken for your platform.
The manifest itself has a dependencies block and nothing else, no scripts and no separate development dependencies. So there is no command in it to run anything, and documentation tooling is declared as though it were a runtime requirement of the project.
Two Maven repository blocks declare one id and one name
The page offers Maven configuration in three flavours: the release, a release candidate, and a snapshot. Each ships a repository declaration beside the dependency, and the two non-release ones are where the problem is.
The candidate version uses a suffix pattern and points at the milestone repository. The snapshot version uses a different suffix and points at the snapshot repository. That much is right.
But both repository blocks declare the same identifier and the same human-readable name, while their addresses differ:
<repository>
  <id>spring-snapshot</id>
  <name>Spring Snapshot Repository</name>
  <url>https://repo.spring.io/milestone</url>
</repository>
That is a genuine defect in the snippet rather than a stylistic quibble. Maven identifies a repository by that identifier, so a build file containing both blocks, which is exactly what someone moving between the candidate and snapshot channels might assemble, has two repositories claiming one name at two addresses. Which one wins is not something the page says.
The labelling compounds it. In the first block the name says Snapshot while the address is the milestone one, so the label and the target disagree before the duplicate identifier is even reached.
Practical advice is small: take one block and edit it rather than pasting both.
Four grammatical errors in six feature bullets
The feature list is six lines long, and four of them have agreement or article problems. One describes a class and its implementations with a singular verb. One reads as though an ES client instances were being configured. A pair of articles in the same line does not agree with the noun it introduces.
The governance sentence directly above them says the project is lead and maintained by the community, where the participle should be past tense.
None of this changes behaviour. All of it sits in the first screen a visitor reads, on a project whose stated purpose is developer productivity, and the pattern suggests a list written once and carried between releases rather than revised.
The rest of the document supports that reading. Four of the five markup documents in the repository root cover continuous integration, support, testing and contributing. The page links only to the contributing one. The other three exist in the repository and are unreachable from the front page, so a contributor looking for how the project is tested or supported has to find those files by browsing.
There is a parallel gap in the other direction. The page's own help section routes questions to a chat room on a third-party platform while routing bugs to the issue tracker on the code host, so the two support channels are on different services, and neither is the documentation.
The upshot is that the visible page is maintained and the documents behind it are not.
The getting-started sample shows none of the Elasticsearch-specific parts
The teaser is a repository interface extending the narrowest Spring Data interface, with two derived query methods, and a service that clears the index, saves one object and queries it back:
public interface PersonRepository extends CrudRepository<Person, Long> {

  List<Person> findByLastname(String lastname);

  List<Person> findByFirstnameLike(String firstname);
}
Two things a reader needs are absent. There is no document annotation on the entity, no index name and no field mapping, so nothing in the example shows how an object becomes a document. That mapping is one of the two things the project names as its key functional areas, so the single most specific thing about this module is the thing the sample omits.
And the interface chosen is the base CRUD one rather than the Elasticsearch-specific or the paging and sorting one, so none of the module's own search surface appears either. The two derived queries are plain Spring Data derivation, which is the one part of the example that would look identical in any other Spring Data module.
The first operation in the service is a delete-all. In a getting-started sample that is a reasonable way to make the following save meaningful. It is also the first thing a reader runs against whatever index they configured.
Client configuration has its own heading and no content beyond a link to external documentation. So the connection settings, which is where Elasticsearch deployments usually differ, are entirely off-page.
The compatibility matrix is named and then delegated
One section is titled Compatibility Matrix. Its whole content is a sentence saying that the compatibility between this project, the Elasticsearch client drivers and the Spring Boot versions can be found in the reference documentation.
So the heading names the artefact and the body sends you elsewhere for it. That is a defensible division for a project whose compatibility surface spans three independently versioned things and would go stale on a page. It is also the fact most people arrive looking for, since choosing a version is the first decision anyone makes.
What the page does give is the release shape. There is a stable line, two milestones of the next version, and a patch, with the two most recent published about ninety seconds apart on the same morning. That is the standard pattern of shipping a maintenance patch and opening the next milestone in one go, and it tells you a 6.x line is in progress.
The build requirements show the same mixture of current and historical detail. A JDK of 17 or above is needed for the main branch, and JDK 8 is needed for branches up to and including a release whose version is now two majors behind. Both statements are true and only one of them describes anything you would build.
The same pattern appears in the Maven requirement: building with a system Maven rather than the bundled wrapper needs a version released in 2018, which is old enough that most current distributions no longer ship it.
Two project addresses point at a corporate domain
The code of conduct section asks that unacceptable behaviour be reported to a mailbox at a corporate domain. The contributing section asks that a contributor's agreement be signed through a web form on the same domain.
Both belong to the company whose acquisition this project came through, rather than to the project's own hosting or its own issue tracker. That is what an inherited link looks like: operational, still resolving, and pointing somewhere that no longer corresponds to the thing you are contributing to.
Neither is a security concern, which is worth saying plainly. The contributor agreement form is a signature gate and the conduct mailbox is a reporting address. But a reader who clicks through to check who operates the project finds a corporate domain in two of the four places the page sends them, and the mismatch between that and the project's own URLs is a small signal that the operational documentation was never fully migrated.
The rest of the help section does point at first-party destinations: the reference documentation, the API documentation, the issue tracker, and a chat room on a third-party platform. So the page routes you to project infrastructure for technical questions and to a corporate domain for the two procedural ones.
The reporting-issues section adds one more small oddity. It asks that code and stack traces pasted into issues be wrapped in Markdown backtick fences, which is a different convention from the markup the project uses for its own documentation. Both conventions appear in the same file, because the escape syntax needed to write a literal fence in the documentation markup is exactly what that instruction is about.
Documentation in AsciiDoc, discussions in Markdown, one licence named oddly
The project's documents are written in AsciiDoc, and that choice is visible in the source rather than inferred.
Every code sample on the page is delimited by four dashes with a language attribute on the line above, rather than by backticks. That is the correct form for the markup, and it is why the examples read as attributed source blocks instead of fences. The page also has to escape a literal run of backticks when it wants to show one, which is why the issue-reporting section can tell you to wrap code in Markdown fences: the same escaping problem, solved in both places.
So documentation and issue tracker disagree about formatting conventions by design. That is a reasonable outcome of keeping prose and discussion in different formats, and it costs nothing except the occasional translation.
What the markup choice does buy is small and real: the project's own documentation can be read in the format it is about.
Two other root-level details. The licence file carries a plain text extension rather than the conventional bare name, while the repository metadata declares the same Apache licence the project is known by. And alongside the contributing document the root holds separate documents for continuous integration, support and testing, none of which the page links, so the practical documentation for running and verifying the project is reachable only by browsing the repository.
Editorial conclusion
Use this when you want Spring's repository abstractions and object mapping over an Elasticsearch cluster rather than driving the client directly, and treat it as a Spring Data module rather than an Elasticsearch library, since its value is the mapping and query derivation rather than anything engine-specific. Three things to check first. The compatibility between this module, the client drivers and Spring Boot lives in external documentation, so establish that pairing before choosing a version. The getting-started sample shows none of the mapping or search surface specific to this module, so plan to read the reference for how documents are annotated. And if you maintain the docs, note that the documentation toolchain is pinned to prerelease packages and is not mentioned on the project page.
Frequently asked questions
What is spring-data-elasticsearch?
It is the Spring Data module providing integration with the Elasticsearch search engine. Its two key areas are a POJO centric model for working with documents and an easy way to write a repository style data access layer, using familiar Spring concepts such as an operations class and repository interfaces with derived query methods.
Which versions of spring-data-elasticsearch are compatible with Spring Boot and the Elasticsearch client?
The page does not list them. It has a section titled Compatibility Matrix whose content is a sentence directing you to the reference documentation for the compatibility between this project, the client drivers and Spring Boot versions.
What do I need to build spring-data-elasticsearch from source?
A JDK of 17 or above for the main branch, and the bundled Maven wrapper. If you use a system Maven instead you need version 3.5.0 or above. Branches up to and including release 4.4 require JDK 8.
How do I add the spring-data-elasticsearch Maven dependency?
Declare the group and artifact with your version. For a release candidate use a suffix pattern against the milestone repository, and for the newest snapshots use a snapshot suffix against the snapshot repository. Note that both repository blocks on the page declare the same id and name for different addresses.
Why does a Java library repository contain a package.json?
It exists for the documentation build rather than the library. It declares six Antora and AsciiDoc documentation dependencies, five of them prerelease releases. The library itself builds with a JDK and Maven, and the project page does not mention the Node toolchain.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/spring-projects-spring-data-elasticsearch)Star history chart for your README
[](https://hysenlabs.com/projects/spring-projects-spring-data-elasticsearch)Was this useful?