Stanza: Stanford's neural NLP pipeline for 60+ languages, with models fetched at first use and a CoreNLP bridge
Stanford NLP Python library for tokenization, sentence segmentation, NER, and parsing of many human languages
At a glance
- What is it?
- stanfordnlp/stanza is the Stanford NLP Group's Python library for tokenization, sentence segmentation, tagging, NER and dependency parsing. It downloads per-language neural models on demand and can also drive the Java CoreNLP software. GitHub shows no licence, while setup.py declares Apache 2.0.
- Who is it for?
- Stanza suits researchers and engineers who want accurate Universal Dependencies parsing, NER and tokenization across many languages, or the biomedical and clinical English models, and who can accept model downloads and a PyTorch install. It is a poor fit for a locked-down environment with no first-run network access, or for anyone who needs a clear licence field on GitHub.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
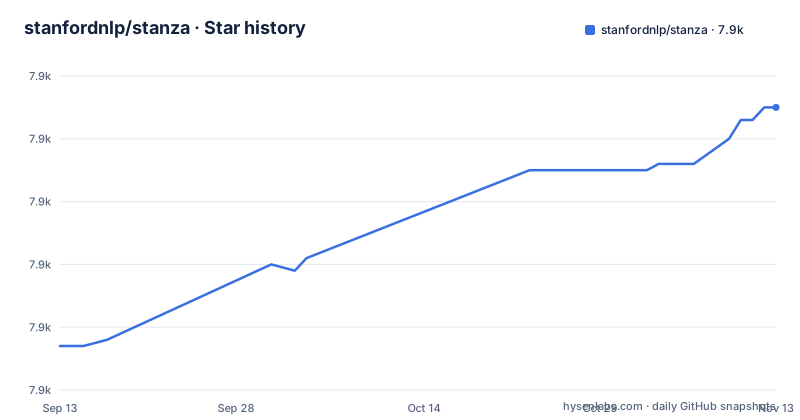
- stanfordnlp/stanza7,915 ★ · +38
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| stanfordnlp/stanza | 7.9k | 7.9k |
38 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The first Pipeline call needs the network because models are downloaded per language
A Stanza pipeline is built from language-specific neural models, and those are not bundled in the pip package. The getting-started example downloads them with stanza.download and then creates a default English pipeline:
>>> import stanza
>>> stanza.download('en')       # Optional: pre-download English models (Pipeline can auto-download if needed)
>>> nlp = stanza.Pipeline('en') # This sets up a default neural pipeline in English
>>> doc = nlp("Barack Obama was born in Hawaii. He was elected president in 2008.")
>>> doc.sentences[0].print_dependencies()
The download is marked optional because the Pipeline can fetch models itself when needed. The consequence is that a container or CI job without internet access fails on first use unless you ran the download step beforehand and kept the files. Pre-download in a build stage, then run offline. Release v1.13.0 is described as using huggingface_hub for downloads, so the download route depends on that service being reachable.
A ConnectionError is handled with a proxies dictionary passed to download
If you hit requests.exceptions.ConnectionError, the README's fix is to pass a proxies dictionary to the download call:
>>> import stanza
>>> proxies = {'http': 'http://ip:port', 'https': 'http://ip:port'}
>>> stanza.download('en', proxies=proxies)  # Optional: pre-download English models (Pipeline can auto-download if needed)
>>> nlp = stanza.Pipeline('en')             # This sets up a default neural pipeline in English
The proxy is given to the download step, not to the Pipeline. That order matters on a corporate network: download once with the proxy configured, then construct the Pipeline, which will find the files already present. The README gives the proxy form as a template with ip:port placeholders, so substitute your own address.
The output is a Universal Dependencies parse with heads and relations
The last command prints the words of the first sentence, the index of the word that governs each one in the Universal Dependencies parse, called its head, and the dependency relation between the words. The sample output begins with the tuple for Barack, head 4, relation nsubj:pass, then Obama, head 1, relation flat.
So the result is a Document object holding sentences and words, and not just a list of tokens. The latest release notes are headed Updated for UD 2.18, which indicates the models track the Universal Dependencies treebank versions. If you compare output across Stanza versions, expect labels and tokenization decisions to follow the treebank update, and pin the version in a research project.
Installation: pip is the recommended route, and Anaconda skips Python 3.10
The README says Stanza supports Python 3.6 or later and recommends pip, which also resolves dependencies such as PyTorch 1.3.0 or above:
pip install stanzaTo upgrade an existing install, the command is pip install stanza -U. The Anaconda route is:
conda install -c stanfordnlp stanzaThe README adds that, for now, installing through Anaconda does not work for Python 3.10, and tells Python 3.10 users to use pip. Installing from source means cloning the repository and running pip install -e . inside it. The stated minimums of Python 3.6 and PyTorch 1.3.0 are lower bounds in the text, so check the version of PyTorch your pip actually resolves before you build a GPU image.
CoreNLP access means Java software sits behind part of the library
Besides the neural pipeline, the library offers access to the Java Stanford CoreNLP software from Python. The CoreNLP client is mostly written by Arun Chaganty, and Jason Bolton spearheaded merging the two projects. The demo folder also includes notebooks for beginners, dependency visualization and NER visualization, plus conllu sample files for English, Arabic and Japanese. It includes corenlp.py, Stanza_CoreNLP_Interface.ipynb, semgrex.py and ssurgeon_script.txt, and the README asks users of the Semgrex or Ssurgeon parts to cite the GURT paper on them.
The consequence is that features built on CoreNLP depend on a Java installation and a CoreNLP download, which the pure pip install does not give you. Decide early which path you need. The neural pipeline alone is a Python and PyTorch dependency. The CoreNLP bridge adds a second runtime.
Biomedical and clinical English packages are separate models with their own citation
The README highlights a collection of biomedical and clinical English model packages for syntactic analysis and named entity recognition on biomedical literature and clinical notes. Their documentation is on a dedicated Biomedical models page, and if you use them the README asks you to cite the Stanza Biomedical Models description paper in addition to the main ACL 2020 system demonstration paper.
The earlier getting-started example builds the default English pipeline with stanza.Pipeline('en'), so the biomedical packages are a separate choice that you make from the documentation page, which lists the exact package names. Choose by the domain of your text, and cite both papers if you publish results that use the biomedical models. The two papers differ: the ACL 2020 system demonstration describes the toolkit, and the Journal of the American Medical Informatics Association article describes the biomedical and clinical English packages.
The licence field is blank on GitHub, while setup.py says Apache 2.0
GitHub reports the licence as NOASSERTION. The setup.py file declares license='Apache License 2.0', and its classifiers list the project as Development Status 4 - Beta. The repository also has a LICENSE file and a SECURITY.md.
For a company, the practical step is to read LICENSE and the model licences rather than relying on the metadata. The recent releases are v1.15.0 on 2026-10-01, v1.14.0 on 2026-07-15, described as security fixes and lemmatizer efficiency updates, and v1.13.0 on 2026-06-18. The last push was on 2026-11-01. Maintenance is currently led by John Bauer. Report issues through the GitHub tracker after checking the FAQ page on the project site.
Editorial conclusion
Stanza suits researchers and engineers who want accurate Universal Dependencies parsing, NER and tokenization across many languages, or the biomedical and clinical English models, and who can accept model downloads and a PyTorch install. It is a poor fit for a locked-down environment with no first-run network access, or for anyone who needs a clear licence field on GitHub. Before adopting it, pre-download your models, confirm the Apache 2.0 declaration in setup.py meets your legal review, and keep CoreNLP's Java requirement in mind.
Frequently asked questions
What is Stanza?
Stanza is the Stanford NLP Group's official Python library. It runs accurate NLP tools on 60+ languages, including tokenization, sentence segmentation, NER and parsing, and can access the Java Stanford CoreNLP software from Python.
How do I use Stanza?
Install it with pip install stanza, optionally run stanza.download('en'), create nlp = stanza.Pipeline('en'), then call nlp on a string and inspect doc.sentences. Models can also be downloaded automatically by the Pipeline.
What is the latest Stanza release?
The newest release listed is v1.15.0 on 2026-10-01, titled Updated for UD 2.18. Before it came v1.14.0 with security fixes and lemmatizer efficiency updates.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/stanfordnlp-stanza)Star history chart for your README
[](https://hysenlabs.com/projects/stanfordnlp-stanza)Was this useful?