supabase-py is a workspace monorepo whose ci target rewrites your files before it runs a single test
Python Client for Supabase. Query Postgres from Flask, Django, FastAPI. Python user authentication, security policies, edge functions, file storage, and realtime data streaming. Good first issue.
At a glance
- What is it?
- Six Supabase Python packages in one uv workspace, each with its own Makefile and its own containerised test infrastructure, requiring two different container tools. The root Makefile declares five phony targets and defines nine, the directory names differ from the published distribution names, and the readme documents development rather than use.
- Who is it for?
- supabase-py is worth reaching for when you are working on the Supabase Python client itself, or when you want one repository that holds the postgrest, auth, storage, realtime and functions clients together with their tests. Three things are worth knowing before you start.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
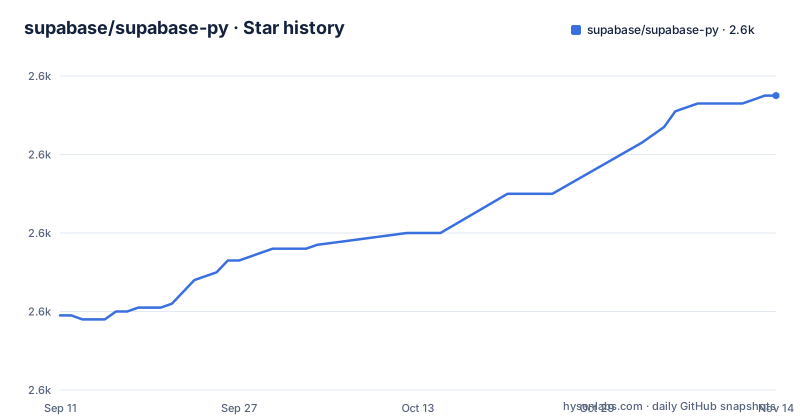
- supabase/supabase-py2,635 ★ · +56
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| supabase/supabase-py | 2.6k | 2.6k |
56 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Six directories, six distribution names, and no usage example
The repository is a monorepo of six packages, and the mapping between folders and published names is not one to one. The workspace members are directories, src/realtime, src/functions, src/supabase, src/storage, src/postgrest and src/auth. What gets installed is named differently: realtime-py, supabase_functions, supabase_auth, storage3 and postgrest sit beside supabase itself. The sources table in the manifest is what wires the two together, redirecting each distribution name at its workspace member, which means an import name and the directory it lives in can diverge without anything breaking. The readme is a development document throughout. It contains no client construction, no query and no authentication call; the two usage links it offers are blog posts about OAuth in a Flask app and about loading data with Python.
make ci depends on a lint step that rewrites the files it checks
The root ci target is declared as depending on two things: the ruff target and the tests of every package. The ruff target is not a check, it is a fixer. It runs ruff check with the fix flag and then ruff format, both through uv run, so invoking the test suite also rewrites source files in place and reformats them. That ordering is invisible in the readme, which describes make ci as running all tests of all packages the same way CI does. For a contributor it means an unstaged change can appear during a test run, and for anyone bisecting a failure the diff you were looking at may not be the diff on disk afterwards. The readme does offer make install-hooks, which writes make ruff into the local pre-commit hook so some of this happens before a commit instead of during a test.
Five phony targets declared, nine rules defined, and eight copies of help
The phony declaration at the top of the root Makefile names ci, default, clean, start-infra and stop-infra. One of those, default, has no rule anywhere in the file. Meanwhile five rules that do have recipes are absent from the declaration: help, publish, mypy, ruff and install-hooks. A rule that is not declared phony can be shadowed by a file of the same name, which is the ordinary reason to declare it, and a name declared without a rule does nothing. The help target is the interesting one. It is written as a second double-colon rule after almost every other target, so make help is assembled from nine separate recipes concatenated in file order rather than from one list, and each target therefore carries its own one line description next to the code that implements it.
Four packages need containers, and they need two different container tools
The start-infra target names four packages explicitly, realtime, storage, auth and postgrest, with a comment above it admitting that not all packages have infrastructure and that the ones that do are instantiated by hand for now. Two packages, functions and supabase, have no entry at all. The tools required are split the same way: docker is needed for the postgrest and auth test containers, and the Supabase CLI is needed for the storage and realtime test containers. So a full local run of the suite expects two container runtimes from two different projects on the machine, plus uv and make. The readme adds a note that starting the infrastructure is not a prerequisite for running the tests, which leaves the reason unstated, and a stop-infra target with the same four package list.
uv or nix, and an activate command that only works on one platform
Two environments are supported and both are described. The preferred one is uv, on the grounds that the readme gives as the reason that it is currently the only tool that understands the workspace setup. The setup is three commands:
git clone https://github.com/supabase/supabase-py.git
cd supabase-pyuv venv supabase-py
source supabase-py/bin/activate
uv syncThe activate line assumes a POSIX layout, with the interpreter under bin, and no Windows equivalent is given even though the tree carries a devcontainer definition. The second environment is a nix shell, supplied through flake.nix and flake.lock, and the readme claims a generated python executable with the whole workspace's dependencies because it is derived from the root pyproject.toml through uv2nix. That is the more complete path by its own description, and it is the one offered as nix develop to anyone who already has nix installed.
The lint policy keeps legacy typing on purpose and ignores five rules
The ruff configuration is short enough to read in full and makes several deliberate choices. Six rule families are selected, pycodestyle, Pyflakes, pyupgrade, bugbear, isort and a return annotation subset, while flake8-simplify is selected in the file and then commented out. Five rules are ignored by name, including two pyupgrade rules, UP006 and UP035, which are the ones that rewrite typing.List and typing.Dict into their builtin equivalents, and the setting below them, keep-runtime-typing, exists to preserve runtime typing even where a file imports annotations from the future module. So the old style of typing is being kept on purpose rather than by oversight. E402 is ignored too, which is the rule about module level imports appearing after other code, a pattern a package doing lazy imports needs. The target version is pinned at py39.
A release tag cut one second after the push it ships
Three releases are visible, and the newest one lines up with the branch in a way worth noting. v2.32.0 is dated 2026-10-02 at 19:18:35, and the most recent push to the default branch main is dated 2026-10-02 at 19:18:34, one second earlier. So the tag and the last commit belong to the same moment. Behind that, v2.31.0 is dated 2026-06-04 and v2.30.1 is dated 2026-05-29, leaving a four month gap between the two most recent releases. Versioning is automated rather than manual: a release-please manifest and a release-please configuration sit at the root next to a changelog, which is what allows six packages in one repository to carry independent version numbers. Two more root files belong in that inventory, an SDK parse ignore list and an SDK compliance specification, both of them about matching generated clients to a published surface.
Editorial conclusion
supabase-py is worth reaching for when you are working on the Supabase Python client itself, or when you want one repository that holds the postgrest, auth, storage, realtime and functions clients together with their tests. Three things are worth knowing before you start. Running the suite changes your working tree, because the ci target depends on a lint step that fixes and reformats in place, so commit or stash before invoking it. Setting up the full suite needs both docker and the Supabase CLI, because two packages use one and two use the other. And if you are looking for usage rather than for development, this readme has none: it points at the documentation site and two blog posts, while everything it explains is about building the packages from source.
Frequently asked questions
What is the difference between PostgreSQL and Supabase?
This repository is the Python client side rather than an explanation of the platform. What it shows is that the Supabase Python surface is six separate packages, including a postgrest client for querying Postgres alongside separate clients for authentication, storage, realtime and functions.
What is Supabase and why use it?
The readme does not argue for the platform. It describes this repository as a Python monorepo for the Supabase libraries and points to the Supabase documentation site as the reference, with two usage articles covering OAuth in a Flask app and loading data from Python.
How do I install the supabase Python client?
The readme documents development setup rather than installation for users: clone the repository, create a virtual environment with uv, run uv sync, then make ci. Package installation for end users is covered on the Supabase documentation site, which the project homepage points at.
Which SQL dialect does supabase-py speak?
The repository does not state one. What it contains is a postgrest client among its six packages, and its own wording describes querying Postgres, with no mention of SQL syntax anywhere in the readme or the manifest shown.
Which database is best with Python?
Nothing in this repository compares databases. Its scope is six Supabase client packages and their tests, and the only storage layer it names beyond those is whatever Postgres the postgrest client talks to.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/supabase-supabase-py)Star history chart for your README
[](https://hysenlabs.com/projects/supabase-supabase-py)Was this useful?