Minions: A Protocol for Splitting Long Contexts Between Local and Cloud Models
Big & Small LLMs working together
At a glance
- What is it?
- HazyResearch's Minions is a Python demonstration of a communication protocol where a small on-device model reads long context locally and a frontier cloud model handles the reasoning. It targets cost reduction on long-context tasks, with the trade-off that the protocol, not a single model, becomes the thing you have to get right.
- Who is it for?
- Adopt Minions if you have long-context workloads where the bulk of the tokens are context rather than instructions, and you already run a local model server such as ollama or lemonade. Do not adopt it if your task is short-prompt reasoning, if you cannot run a local model at all, or if you need a stable released API rather than a research demonstration.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 8 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
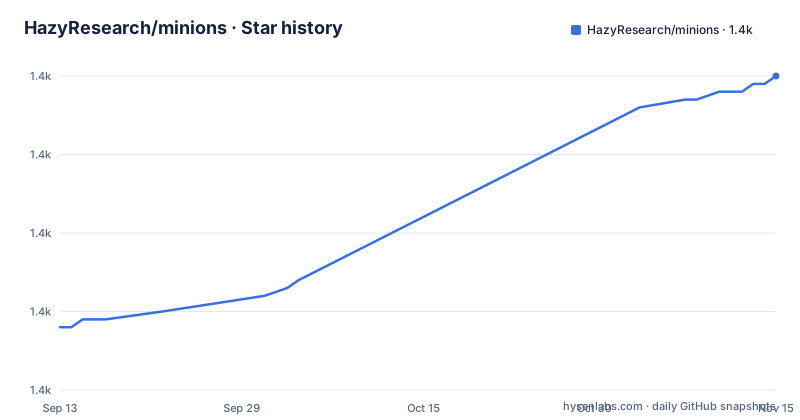
- HazyResearch/minions1,390 ★ · +32
| Repository | 2026-09-13 | 2026-11-15 |
|---|---|---|
| HazyResearch/minions | 1.4k | 1.4k |
32 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The cost problem Minions is built around
Sending a long document to a frontier model costs money proportional to the context length, and most of that context is input the model reads rather than output it produces. Minions starts from the observation that reading is a different job from reasoning. The README describes it as "a communication protocol that enables small on-device models to collaborate with frontier models in the cloud", with the stated goal that "by only reading long contexts locally, we can reduce cloud costs with minimal or no quality degradation". The target user is someone with a long-context task (document question answering, summarization over large inputs, retrieval-heavy chat) who has a machine capable of running a small local model and a cloud API key. It is not aimed at people who want a single model to do everything, and it is not a hosted service. The repository is a demonstration of the protocol described in the linked paper, so the audience is engineers willing to read code and wire up components rather than install a finished product.
How the local and cloud halves divide the work
The architecture is a split between a local model server and a cloud provider. The local side runs one of three supported servers: lemonade, ollama, or tokasaurus. The README ties each to hardware: ollama for machines without NVIDIA or AMD GPUs, lemonade for local AMD CPUs, GPUs, or NPUs, and tokasaurus for NVIDIA GPUs where the Minions protocol benefits from higher throughput. The cloud side is reached through API keys for at least one provider, with OpenAI and TogetherAI named in the setup instructions. The protocol itself is the part that is not fully specified in the README: the repository points to the paper and blogpost for the details of how the two models communicate. What is visible in the code structure is that the minions package exposes clients (including a LlamaCppClient) and that the demo application, a WebGPU app, and a CLI are separate entry points. There is also a secure variant, described as an end-to-end encrypted local-remote protocol and chat system, with its own README under secure/. The practical consequence of this layout is that the local model is not a fallback; it is a participant whose output feeds the cloud model. If the local model reads the context badly, the cloud model reasons over a bad summary, and the failure is silent.
Getting it running: the actual commands
The README gives a three-step setup. First, clone and install the package in editable mode:
git clone https://github.com/HazyResearch/minions.git cd minions pip install -e .
Optional extras are installed with bracketed syntax: pip install -e ".[mlx]" for MLX-LM, pip install -e ".[secure]" for Secure Minions Chat. The README states the tested configuration is Mac and Ubuntu with Python 3.10 to 3.11, and explicitly notes that Python 3.13 is not supported. That constraint matters because a default python3 on a recent system may be 3.13, in which case the install will fail and the fix is a separate environment, for example conda create -n minions python=3.11.
Second, install a local model server. For ollama, the README points to the download page and notes that Flash Attention can be enabled with launchctl setenv OLLAMA_FLASH_ATTENTION 1, followed by an app restart on Mac. For lemonade, installation is via the linked installer, and the README warns that the server must be launched and that lemonade does not support the Minion-CUA protocol at this time. For tokasaurus, pip install tokasaurus.
Third, set an API key for at least one cloud provider. The README links to OpenAI and TogetherAI key pages but the truncated material does not show the exact environment variable names, so check the source before assuming them. Azure OpenAI is covered in a separate miscellaneous section.
Where the protocol breaks down
The clearest limitation is stated in the README itself: lemonade does not support the Minion-CUA protocol at this time. If your hardware pushes you toward lemonade (AMD APUs, NPUs) and your workload needs that protocol, the supported path is closed. A second limitation is the Python version floor and ceiling. The README says 3.10 to 3.11 were tested and 3.13 is unsupported, which means the project lags the interpreter most new machines ship with. That is a maintenance signal, not a bug, but it shapes where you can deploy. A third issue is that the interesting part, the protocol, lives in a paper rather than in the README. The repository demonstrates it; it does not document the message format, the stopping conditions, or what happens when the local model's reading is wrong. For an engineer deciding whether to adopt, that means the README is enough to install and run the demo but not enough to reason about failure modes without reading the source. Finally, the cost argument only holds when context dominates. If your prompts are short, you pay the local model's latency and complexity for no token savings.
How this differs from routing and from local-only inference
The obvious alternative is a router: send easy queries to a small local model and hard ones to the cloud, choosing one or the other per request. Minions does not choose. Both models run on the same request, with the local model handling the long read and the cloud model handling the reasoning, which is why the README frames it as collaboration rather than routing. A second alternative is running everything locally with llama-cpp-python, which the README supports directly through LlamaCppClient, including loading GGUF models from Hugging Face with a model_repo_id and model_file_pattern. That path removes cloud cost and cloud dependency entirely, but it caps quality at whatever the local model can do, and the README's own example uses a 7B model. Minions exists because that cap is real for reasoning while being less real for reading. A third alternative is sending the full context to the cloud and accepting the bill. That is simpler and has no protocol to debug, and for occasional long-context calls it may be cheaper than the engineering time Minions requires. The difference between these options is not quality in the abstract; it is which part of the pipeline you are willing to own.
Licence, maintenance, and what the repository does not promise
The licence is MIT, which permits commercial use and modification with the usual attribution requirement. This is not legal advice; read the LICENSE file in the repository before relying on it. On maintenance, the observable facts are that the default branch is main, the last push recorded is 2026-03-12, the repository is not archived, and there are no published GitHub releases. The absence of releases is the practically important part: installation is from source with pip install -e ., which means upgrades are git pulls rather than version bumps, and there is no tagged version to pin against. The README also shows a Discord link for community support, which suggests questions go to a chat rather than an issue tracker with a triage process. For a team, the upgrade cost is therefore not just the pull; it is re-validating the local server integration and the client code against whatever changed. The inference estimator included in the repository is the one tool that helps here, since it is designed to estimate costs before you run the workload.
Who this is for, and what to check first
Minions fits teams that already run a local model server, have a long-context workload where input tokens dominate, and are willing to read the paper and the source to understand the protocol. It does not fit teams that want a drop-in library, that cannot run a local model, or that need a pinned release with a changelog. Before adopting, verify the local server against your hardware using the README's own guidance (ollama without NVIDIA or AMD GPUs, lemonade for AMD CPUs, GPUs, or NPUs, tokasaurus for NVIDIA GPUs), confirm your Python is 3.10 or 3.11, and check the source for the exact environment variable names for your cloud provider, since the truncated README does not show them. If your workload is short-prompt reasoning, the protocol adds a component without removing tokens, and the honest answer is to skip it.
Editorial conclusion
Adopt Minions if you have long-context workloads where the bulk of the tokens are context rather than instructions, and you already run a local model server such as ollama or lemonade. Do not adopt it if your task is short-prompt reasoning, if you cannot run a local model at all, or if you need a stable released API rather than a research demonstration. Before committing, verify three things: which local server your hardware supports, whether your cloud provider key is wired into the client you intend to use, and whether the inference estimator's cost model reflects your actual token mix.
Frequently asked questions
What is the Minions protocol?
It is a communication protocol that lets a small on-device model collaborate with a frontier model in the cloud. The small model reads the long context locally, so the expensive model does not, which is claimed to reduce cloud cost with minimal or no quality degradation. The repository presents itself as a demonstration of the protocol, published alongside the paper on cost-efficient collaboration between on-device and cloud language models.
Which Python versions does minions support?
The tested configuration is Mac and Ubuntu with Python 3.10 to 3.11, and the documentation explicitly says Python 3.13 is not supported. The spacy dependency carries a comment that it was worked on with 3.11 and not 3.13. Python 3.12 is neither listed as tested nor excluded. The Dockerfile is built on a Python 3.11 slim base.
What local model server does minions need?
At least one of three. Ollama if you have no NVIDIA or AMD GPU, Lemonade if you have local AMD CPUs, GPUs, or NPUs, and Tokasaurus if you have NVIDIA GPUs and are running the Minions protocol. Lemonade does not support the Minion-CUA protocol, and enabling Flash Attention in Ollama is documented with a macOS launchctl command with no Linux equivalent given.
How many dependencies does minions install?
Thirty-two hard runtime dependencies in setup.py, covering six provider SDKs, retrieval and scraping, PDF and token handling, a Flask worker server, Twilio, a paid search API, torch, and three NVIDIA or Azure attestation packages. Only one of them is version-pinned. requirements.txt in the same repository lists twenty-four with no pins at all and omits several that setup.py requires, including the Cerebras SDK and the attestation packages.
What is Secure Minions Chat?
It is a separate end-to-end encrypted chat system built on the same protocol, documented in its own README under the secure directory and installed with the secure extra. The protocol documentation also has a distinct local-remote section, and the project published a second blog post about the secure variant in May 2025, after the original post in February 2025.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/hazyresearch-minions)Star history chart for your README
[](https://hysenlabs.com/projects/hazyresearch-minions)Was this useful?