FreeLLMAPI says do not expose it to the internet, and free installs lag the catalog 30 days
7.4 billion tokens per month. 34 free LLM providers. 635 free model endpoints. All behind one /v1 endpoint, plus any custom OpenAI-compatible endpoint. Smart routing, automatic failover, encrypted keys. Personal experimentation only.
At a glance
- What is it?
- FreeLLMAPI is a TypeScript proxy that puts dozens of providers' free tiers behind one OpenAI-compatible `/v1` endpoint, with encrypted key storage, a router that fails over when a provider rate-limits, and per-key usage tracking against free-tier caps. Three facts decide whether it fits: free installs receive the model catalog as a monthly snapshot, the compose file binds to localhost on purpose, and the whole service is guarded by a single unified API key.
- Who is it for?
- FreeLLMAPI fits an individual experimenting with several providers at once, on a machine they control, who wants one client configuration instead of thirty-four and who accepts that a newly free model may take a month to appear.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
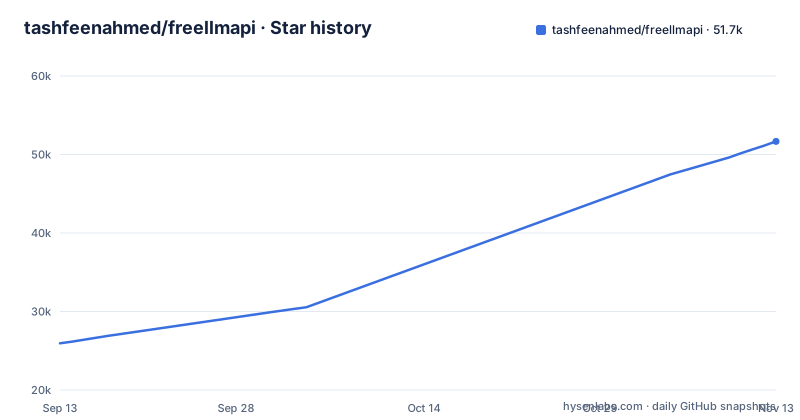
Star history
- tashfeenahmed/freellmapi51,664 ★ · +25,714
| Repository | 2026-09-13 | 2026-11-13 |
|---|---|---|
| tashfeenahmed/freellmapi | 26k | 51.7k |
25,714 Stars in the last 61 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Thirty-four rate limits collapse into one client configuration
The stated problem is arithmetic. Every serious AI lab now offers a free tier, a few million tokens a month and a few thousand requests a day, and on its own each tier is a toy, while stacked they add up to roughly 7.4 billion tokens per month across 474 model families and 635 provider endpoints. The cost of stacking them by hand is the part the README emphasises: thirty-four SDKs, thirty-four rate limits, and thirty-four places a request can fail.
FreeLLMAPI replaces that with one endpoint. You point any OpenAI client library at your local server and it routes across whichever providers you have added keys for. Behind that are three named behaviours: a router that picks the best available model for each request, a fallback to the next provider when one is rate-limited, and per-key usage tracking so you stay under every free-tier cap.
The change that matters is to your failure model. A client no longer knows which provider answered, and a rate limit from one provider becomes a routing decision rather than an error. Providers named in the README include Google, Groq, Cerebras, Mistral, OpenRouter, Cloudflare, Cohere, Z.ai, NVIDIA, HuggingFace and ModelScope, with 22 more behind them, plus a custom provider for chat, embedding, image or audio at any OpenAI-compatible endpoint such as llama.cpp, LM Studio, vLLM or a local Ollama.
The catalog is a signed feed, and free installs read it monthly
Free tiers move quickly, and the README says so: providers launch models, retire them and change quotas without notice, weekly. The project's answer is that the router updates its own model catalog from a signed feed, so new free models, quota changes and compatibility fixes land without a `git pull`.
Then the sentence that decides the free tier's usefulness. Free installs get the monthly snapshot, so a model reaches them 30 days after it joins the live feed, while premium routers get it the same day. The paid tier is priced at $19 a year, cancellable at any time.
So the trade is concrete rather than abstract. If you are chasing a newly free model because it exists, you will be a month behind on the free tier. If you are using models that have been free for a while, the snapshot is current enough and the monthly cadence costs you nothing but a delay on brand-new models.
The catalog itself is described as carrying per-model rate limits, context windows and free-token budgets, and the full always-current list lives on the project's own site, which is a separate thing from the snapshot your router installs.
The compose file says single-user and must not face the internet
The docker-compose file carries the security posture in a comment above the port mapping: bound to localhost by default, FreeLLMAPI is single-user and must not be exposed to the internet, and setting `HOST_BIND=0.0.0.0` is what reaches it from your LAN. The mapping is a variable expansion, `${HOST_BIND:-127.0.0.1}:${PORT:-3001}:3001`, so the safe value is the default and changing it is a decision.
The env example says the same thing more plainly. Open it to other devices on a trusted network, and only on a trusted network, because the proxy is single-user and guarded only by the unified API key. There is no second factor and no per-user model, so that key is the whole boundary.
Two smaller protections sit around it. The first account is created through the dashboard, and if the server is reachable from other devices, creating it also needs a one-time setup code printed in the server logs at startup while no account exists, which the env file says stops a stranger from claiming a freshly exposed install. And there is a per-client-IP request cap on the `/v1` proxy, 120 per minute by default, set to zero to disable.
The encryption key has a four-step precedence and a generated fallback
Keys are stored encrypted, and the env example is unusually explicit about how the encryption key is found, which is worth reading before you store anything real in it.
`ENCRYPTION_KEY` is required in production. Outside production it is optional, and when it is unset a key is generated and written to a file named `.encryption-key` next to the SQLite database, not inside it, with 0600 permissions. The stated precedence is the environment variable, then that key file, then a legacy key found in the old settings table, which is migrated to the file on the first boot, then a freshly generated key.
Two consequences follow. The generated fallback means a development install works with no setup, which is convenient, and it also means the key lives somewhere specific that a backup has to include. The data directory in the compose file is a single named volume mounted at `/app/server/data`, so the database and the key file travel together and a backup of one without the other is a backup of nothing usable.
The generation command is given in the same file as a comment, using Node's crypto to produce 32 random bytes as hex.
better-sqlite3 is why the build stage installs a C++ toolchain
The Dockerfile is three stages on `node:24.22.1-bookworm-slim`, and the first one installs python3, make and g++. The comment explains why: better-sqlite3 is a native module, and on slim images without a usable prebuilt binary, notably the linux/arm64 leg under QEMU, it compiles from source through node-gyp, which needs Python and a C++ toolchain. Those packages exist only in the build stages, since the runtime image copies the already-compiled modules.
The second comment is the one to keep. npm nests some production packages under the workspace instead of hoisting them, with undici living at `server/node_modules/undici`, and skipping that copy shipped images in which the HTTP(S) proxy dispatcher failed to load and every request silently went direct, cited as issue 550. So the runtime stage copies both the root `node_modules` and the server's.
That is a warning about optimising this image. The failure mode of dropping a copy is not an error message; it is a proxy that quietly stops proxying, which is exactly the bug you would not notice for a week. The compose file also adds `host.docker.internal:host-gateway` for the case where your proxy runs on the host, with a note that Docker Desktop provides that name already and plain Docker on Linux does not.
The test suite runs the project's own agent hook
The repository is a private npm workspace monorepo named `@freellmapi/monorepo` with four workspaces: shared, server, client and cli. The test script chains five things, and two of them are not application tests at all. `test:bootstrap` runs a Node test file for the development bootstrap script, and `test:hooks` runs `node --test .claude/hooks/contributing-check.test.mjs`, which is a test of a hook in the project's `.claude/` directory.
So the project tests the agent-facing part of its own contribution flow, alongside the server, CLI and client suites. The rest of the scripts are ordinary but complete: a `dev` mode that runs the server and the client together with `--kill-others-on-fail` and a `dev:lan` variant that passes `--host` to the client, a build that builds server, cli and client in that order, and five database migration commands, up, down, fresh, status and create, all delegated to the server workspace.
The desktop application has its own distribution targets, including a specific macOS x64 build, alongside Windows and Linux. At the root there is a `.nvmrc`, an `opencode.json`, a `docker-entrypoint.sh`, a `Dockerfile`, and examples for a ChatGPT client and a fetch relay worker. The documentation tree is organised into guides, with separate pages for installation, the REST API reference, clients, prompt compression and architecture internals.
Setup generators back up your agent config and launchers keep keys off disk
The compatibility list is long enough to be the reason someone adopts this. Named clients include Claude Code, Codex CLI, Gemini CLI, Aider, Cline, Roo Code, Continue, OpenCode, Goose, Qwen Code, Kilo Code, Crush, Cursor, Zed, JetBrains AI, DeepSeek Harness, AtomCode, OpenClaw and Hermes Agent, plus any OpenAI-compatible client, Anthropic SDK, Gemini SDK or Ollama-capable app. There is also a desktop app for mobile and a web dashboard for keys.
Most of the coding agents configure themselves with one command, with `npx freellmapi setup-claude` as the example command. What it does is worth noting: it reads your live catalog, backs up the existing config and merges into it.
Editorial conclusion
FreeLLMAPI fits an individual experimenting with several providers at once, on a machine they control, who wants one client configuration instead of thirty-four and who accepts that a newly free model may take a month to appear. It does not fit a shared or public deployment, since the compose file states the proxy is single-user and must not be exposed to the internet, and it does not fit someone who needs the catalog the day a provider adds a model, because the live feed is the paid tier. Before you run it, set `ENCRYPTION_KEY` rather than relying on the generated fallback, keep the data volume backup as a pair with the key file beside it, and leave `HOST_BIND` at its default unless your LAN is trusted.
Frequently asked questions
What is FreeLLMAPI?
It is a proxy that aggregates free tiers from dozens of providers, plus custom OpenAI-compatible chat, embedding, image and audio endpoints, behind a single /v1 API. Keys are stored encrypted, and a router picks the best available model for each request, fails over to the next provider when one is rate-limited, and tracks per-key usage.
How do I install FreeLLMAPI?
The README links an install and deploy guide with a Docker Compose section, and the repository ships a docker-compose.yml that builds or pulls the image, reads .env, publishes port 3001 on 127.0.0.1 by default and stores data in a named volume. There is also a desktop app published for mobile and a web dashboard served by the same server.
How do I use FreeLLMAPI?
Point any OpenAI client library at your local server and it routes across the providers you have added keys for, failing over when one is rate-limited. Coding agents configure themselves with commands such as `npx freellmapi setup-claude`.
Can I use FreeLLMAPI from an editor or IDE?
The README names Cursor, Zed and JetBrains AI among the compatible clients, alongside Continue, Roo Code, Kilo Code and Crush, and says any OpenAI-compatible client works. The generator commands cover the coding agents separately, and those back up existing config rather than overwriting it.
Official sources
Where developers are discussing it
Posts on Hacker News, dev.to and Lobsters that link to this repository, found by our scan of those communities. 0 in the last 30 days; newest first.
- FreeLLMAPI – One OpenAI-Compatible API for Multiple Free LLM ProvidersHacker News · Oct 7, 2026 · 1 points · 1 comments
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tashfeenahmed-freellmapi)Star history chart for your README
[](https://hysenlabs.com/projects/tashfeenahmed-freellmapi)Was this useful?