Embodied-AI-Guide pairs one simulation tutorial with a Chinese encyclopedia of robot learning
[Lumina Embodied AI Community] A technical guide to embodied AI - Embodied-AI-Guide.
At a glance
- What is it?
- TianxingChen/Embodied-AI-Guide, from the Lumina Embodied AI Community, is a Chinese-language knowledge base and reading index for embodied AI. Its structure is one hands-on chapter you can finish in about a week plus five reference chapters on algorithms, infrastructure, control and hardware.
- Who is it for?
- Embodied-AI-Guide is a strong starting map for Chinese-reading students and engineers who need to know what VLA, world models, teleoperation and Sim2Real mean and which chapter to read next, and its simulation-only tutorial lowers the hardware bar to one GPU with about 12GB of memory. It is a poor fit for readers who cannot read Chinese or who want a self-contained course with installable code.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- GitHub does not report a main language for this repository.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
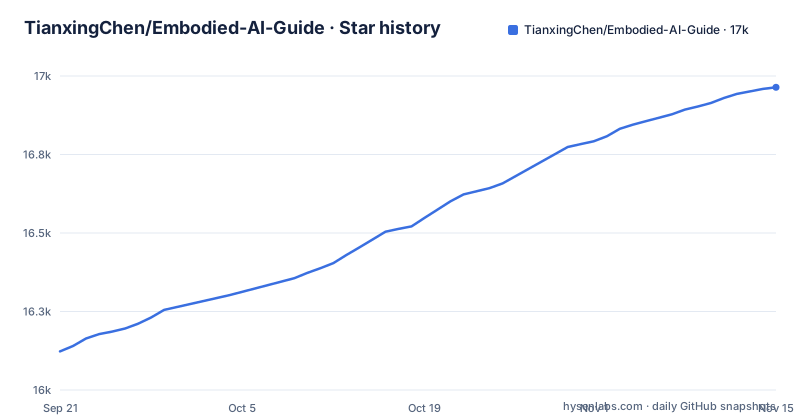
- TianxingChen/Embodied-AI-Guide16,964 ★ · +841
| Repository | 2026-09-21 | 2026-11-15 |
|---|---|---|
| TianxingChen/Embodied-AI-Guide | 16.1k | 17k |
841 Stars in the last 55 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three questions run through every chapter: data, action, measurement
The guide opens with a working definition: embodied AI is an intelligent system that perceives and acts through a physical body, gaining information through interaction with its environment, understanding problems, making decisions and carrying out actions, so that intelligent and adaptive behavior emerges.
It then makes that definition concrete in a way that frames the rest of the project. Large models already handle text and images well because the internet holds enormous amounts of ready-made data. Getting a robot to reach out and pick up a cup from a table is different: the model must output continuous actions with physical consequences, and that data cannot be scraped. Every sample has to be collected on a real machine by a person, and a mistake during collection can break things.
From this the guide derives what it calls the central tension of the field, posed as three linked questions: where does the data come from, how should actions be represented, and how do you measure whether the robot did well. These questions recur throughout the later chapters, and they are a useful lens for a newcomer. When a paper introduces a new teleoperation rig, a new action tokenizer or a new benchmark, the reader can place it against one of the three questions instead of treating each paper as an isolated result.
One hands-on thread and one panoramic map
The project describes its design as one main line plus one panoramic map. The main line is chapter 2, a practical tutorial meant to let you run the complete pipeline of a manipulation policy with your own hands within a week. The panoramic map is chapters 3 through 7, written as an encyclopedia that covers cognition material, algorithms, infrastructure, control and hardware, with the goal of helping you judge what problem each technique solves and whether it deserves a deeper look.
The recommended reading order follows from that split: run chapter 2 first, then look things up in the later chapters as your interests require. The guide says explicitly that there is no need to read it front to back.
This structure is the main reason to choose it over a plain list of papers. An awesome-list tells you what exists. Embodied-AI-Guide tries to tell you why each technique exists and gives you a working pipeline to anchor that reading. The cost is that the reference chapters are only as useful as your ability to follow their pointers out to papers and other repositories; the guide is an index and an explanation layer, not the primary source.
Your background decides which chapter you open first
A routing table sends readers to different starting points. Complete beginners and undergraduates start at chapter 2, then move through chapter 3 for context and chapter 4 for algorithms. Readers with computer vision, NLP or deep learning experience start at chapter 4, focusing on robot learning and VLA, then infrastructure in chapter 5, and only then return to chapter 2 to verify things by hand.
Those with an automation or robotics background also start at chapter 4, but the suggested path runs through chapter 3 to see the landscape, then chapter 4 to fill in learning and decision making, then chapter 5 for simulation and the data ecosystem. Hardware and embedded engineers begin with the hardware chapter, then control, then the tutorial. Readers who only want a quick sense of the industry and possible research topics start at chapter 3, with its methodology section, paper list and yearly trends.
The value of the table is that it admits different readers lack different things. A machine learning engineer does not need forward kinematics explained first, and a controls engineer does not need a primer on behavior cloning before seeing how VLA models fit in. Each gets a path that front-loads their gap.
A 20-term glossary for reading robot learning papers
Before the long chapters, the guide offers a collapsible glossary of 20 terms that appear constantly in papers. Some are the basics: manipulation versus locomotion as the two main lines of the field, a policy as the mapping from observation to action, imitation learning and behavior cloning as supervised learning from human demonstrations, and reinforcement learning as optimizing a policy through interaction and reward.
The more useful entries separate terms that newcomers tend to blur. A VLA, or Vision-Language-Action model, maps images and language instructions directly to robot actions. A VA policy uses vision only and takes no language instruction, which makes it lighter and faster than a VLA when the task is fixed. A world model learns to predict the next observation from the current state and an action. A WAM, or World-Action Model, first predicts what it will see next and then solves for the action from that prediction.
On the data and deployment side, the glossary covers teleoperation as the main way to collect real-robot data, demonstrations as complete recorded task executions, the Sim2Real gap that causes policies to lose performance when moved from simulation to reality, and Real2Sim as reconstructing real scenes in simulation to narrow that gap. The robotics entries include DoF, end-effectors, FK and IK, URDF, MPC, whole-body control and SLAM.
Simulation first, a real robot second, and a GPU budget up front
The newcomer FAQ is direct about prerequisites. You need Python, basic deep learning (being able to train a classification network is enough) and the ability to set up an environment on Linux. Robotics and control theory are not prerequisites; the guide suggests picking them up when a problem demands it, and the control chapter has its own section on how far to go.
On hardware, the answer to whether you can work in embodied AI without a robot is yes, and the guide notes most people start that way. A simulator plus public datasets can carry you from first steps to publishing papers, and chapter 2 is pure simulation. Real robots matter because they expose problems that simulation hides, such as calibration error, latency and contact uncertainty, but the guide treats that as the second step. For readers who want real hardware anyway, it names the SO-101 leader-follower arm from the LeRobot ecosystem as the lowest-cost entry.
The GPU guidance is concrete. Training lightweight policies such as ACT or Diffusion Policy fits in 16GB of GPU memory, and the chapter 2 tutorial needs about 12GB. Fine-tuning VLA foundation models such as pi0 or GR00T calls for 40GB or more, or for parameter-efficient methods such as LoRA. Plan that hardware before you start chapter 2, and treat VLA fine-tuning as a separate budget question.
Chinese-only prose and no runnable code of its own
The guide's own tagline calls it the most popular embodied AI technical guide in China, and the content is written in Chinese, so readers who do not read Chinese depend on machine translation. Glossary terms and chapter titles carry English names alongside the Chinese, which helps, but the explanations that make the guide worth reading over a paper list are the part that translation handles worst.
The repository itself is plain documents. Its top level holds a README, a LICENSE, a files/ directory and a topics/ directory, and GitHub reports no primary programming language. There is nothing to install and no package to depend on. Even the hands-on chapter runs on a simulator and public datasets set up on your own Linux machine with your own GPU, not on code shipped in this repository.
For a reader this means two things. You cannot clone the repository and run a demo from it, and when a tutorial step fails, the software that broke belongs to another project, so the fix has to come from there or from your own environment rather than from a pull request here.
Licensing is unclear and the structure was reorganized this year
GitHub labels the license NOASSERTION, which means it could not match the LICENSE file to a standard license. If you plan to translate the guide, republish chapters in course material or mirror it, read that file first rather than assuming a permissive license.
The project timeline is short and busy. It was open-sourced on 2025-03-15, passed 10,000 GitHub stars on 2025-12-18, and finished a content reorganization on 2026-01-15. A release named 2026, tagged v1.0.0, followed on 2026-02-20, and the last push to main was on 2026-10-25. Because the content was restructured, bookmarks and notes that cite section numbers from before the reorganization may not point to the same material today.
The guide sits inside the Lumina Embodied AI Community, which runs lumina-embodied.ai, a WeChat group reached through a QR code, and a contact address at [email protected]. It also links two related projects: Lumina Call for embodied AI recruiting and Datawhale's every-embodied, an introductory embodied AI tutorial. Contributions are invited through stars, shares and pull requests.
Editorial conclusion
Embodied-AI-Guide is a strong starting map for Chinese-reading students and engineers who need to know what VLA, world models, teleoperation and Sim2Real mean and which chapter to read next, and its simulation-only tutorial lowers the hardware bar to one GPU with about 12GB of memory. It is a poor fit for readers who cannot read Chinese or who want a self-contained course with installable code. Before copying or redistributing its content, read the LICENSE file, because GitHub does not detect a standard license for it.
Frequently asked questions
What exactly is embodied AI according to Embodied-AI-Guide?
Embodied-AI-Guide defines it as an intelligent system that perceives and acts through a physical body, learning from interaction with its environment to understand problems, make decisions and act.
Can Embodied-AI-Guide give an example of embodied AI?
Its example is a robot reaching out to pick up a cup from a table: the model must output continuous actions with physical consequences, learned from data that has to be collected on real machines.
What kind of AI guide is Embodied-AI-Guide?
It is a Chinese-language, encyclopedia-style knowledge base and reading index for embodied AI from the Lumina Embodied AI Community, combining a hands-on simulation tutorial with chapters on algorithms, infrastructure, control and hardware.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tianxingchen-embodied-ai-guide)Star history chart for your README
[](https://hysenlabs.com/projects/tianxingchen-embodied-ai-guide)Was this useful?