TiKV's smallest deployment is a placement driver and a store
Distributed transactional key-value database, originally created to complement TiDB
At a glance
- What is it?
- TiKV is a distributed transactional key-value store written in Rust on Raft, with the consensus state kept in RocksDB and a separate placement driver that shards data automatically. It is a graduated Cloud Native Computing Foundation project created to complement TiDB, and the placement driver is the first thing you have to run.
- Who is it for?
- TiKV fits a team that wants an ACID key-value store across commodity machines, with replication handled at region granularity and no manual placement, and that is prepared to operate a placement driver as a service in its own right. It does not fit someone who wants a single binary, because the documented minimum is a placement driver plus a store.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 2 days ago.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
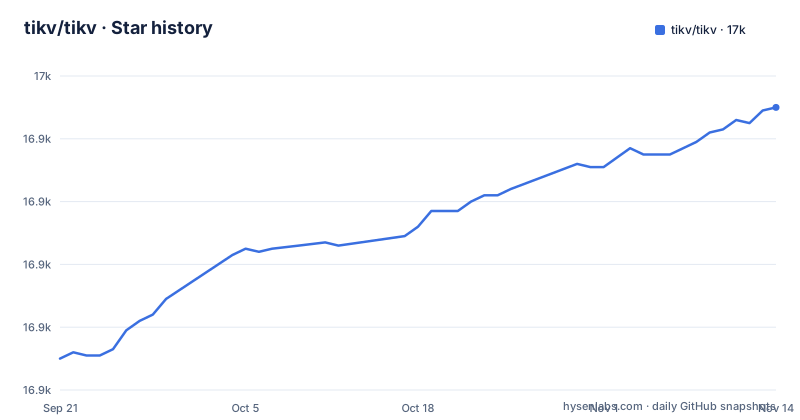
- tikv/tikv16,950 ★ · +80
| Repository | 2026-09-21 | 2026-11-14 |
|---|---|---|
| tikv/tikv | 16.9k | 17k |
80 Stars in the last 54 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Four levels of nesting, and a driver that moves regions between them
The software stack section is the paragraph to read, because it is the whole model in five lines. A region is the basic unit of key-value data movement, and each region is replicated to several nodes, those replicas forming a Raft group. A store holds a RocksDB instance inside it and writes data to local disk. A node is a physical machine holding one or more stores. And the placement driver is the cluster manager, which periodically checks replication constraints to balance load and data automatically. It also implements auto-sharding and is what enables automatic data migration. The operational consequence follows: the thing that replicates is a region, the thing that decides where a region lives is a different program, and that program has to be running before the store can do anything useful. When a node starts, its node, store and region metadata is recorded into the driver, and the status of each region and store is reported back regularly.
The minimal deployment is two processes and the file gives every flag
The binary quick start says TiKV can run separately with the placement driver, and that this is the minimal deployment required. It then lists everything, which is useful, because there is no hidden configuration layer here. You set a version variable and a platform pair, with only two operating systems and two architectures named as supported, download and extract the store and driver tarballs separately, and start the driver with a name, a data directory, client and peer URLs, an initial cluster string and a log file:
$ ./pd-server --name=pd --data-dir=/tmp/pd/data --client-urls="http://127.0.0.1:2379" --peer-urls="http://127.0.0.1:2380" --initial-cluster="pd=http://127.0.0.1:2380" --log-file=/tmp/pd/log/pd.logThen the store, pointed at the driver:
$ ./tikv-server --pd-endpoints="127.0.0.1:2379" --addr="127.0.0.1:20160" --data-dir=/tmp/tikv/data --log-file=/tmp/tikv/log/tikv.logSo the first thing you deploy is two services, and the address and port choices in that example are the ones you will inherit.
The verification client is installed from a testing index
The last step of the quick start is the one to read twice. It says to install the Python client and verify the deployment, requiring a version of Python the file states as three and a half or newer, and the command it gives installs from a test package index rather than the production one:
$ pip3 install -i https://test.pypi.org/simple/ tikv-clientThe verification itself is three calls through a raw client, connecting to the driver's endpoint and putting and getting a key. Two things follow. A pre-release client is the right thing for a smoke test and the wrong thing to keep in a service, and the version floor it states is Python 3.5. If you follow this route, treat the client as scaffolding, read the flag list for the store rather than copying the example verbatim, and remember the driver is the thing holding your metadata.
The compose cluster pulls nightly images and gives the driver forty seconds
The Docker Compose route is described as the easiest way to run a complete cluster for development and testing, three driver nodes and three store nodes, using pre-built images so nothing is compiled. Reading the compose file tells you more than the prose does. Every driver node uses a nightly image tag, so the documented easy path is unreleased builds, which is exactly how a compose cluster ends up behaving differently from your production version for reasons that are hard to see. Each node gets its own client and peer port pair, its own data volume and its own log volume, and advertises itself by container hostname with an initial cluster string listing all three peer URLs. There is a comment explaining that all driver nodes start at once to allow a proper leader election, and the health check polls the driver's health API every ten seconds with a five second timeout, ten retries and a forty second start period. The forty seconds is the leader election showing through.
The allocator is a compile-time choice and there are four of them
The manifest's feature list is unusual and it is where the operational character of this project shows. Alongside the tracing and portable and vector-instruction switches and a memory-profiling switch, there are four allocator features you pick at build time, and the container build sets a memory-profiling allocator configuration in the environment of the final image. Two more entries matter for how you test and how you contribute. A failpoint feature compiles fault-injection points into five separate crates, the failure handling, the store, the shared utilities, the storage engine and the log engine, which means a partition or a disk failure can be simulated rather than waited for. And a set of test-export hooks spans nine more crates, which is how a test can reach internals that production code does not expose.
One make target is the gate for a pull request, and it recompiles the standard library
The build file explains itself at the top, which is unusual enough to read closely. It says the rules are mostly light wrappers around cargo, that it turns on features which are not on by default in the manifest but are part of a release build, with the memory engine always added, and that it does the few key things a developer needs to understand. Those are the named rules: build, run, test, format, clippy, dev and release, where dev is described as the rule that needs to pass before submitting a pull request because it runs the tests and the static analysis. Two operational details sit in the same file. Frame pointers are enabled by default because the point is stable and reliable stack backtraces for profiling, you can turn them off with an environment variable and fall back to a different unwinder, and the file warns that enabling them means the Rust standard library gets recompiled. And the test rule runs configurations that plain cargo test does not cover.
Two release lines, a beta in the manifest, and a build file that disclaims itself
The version picture has three parts and they do not agree, which is normal for a project at this size and worth knowing before you pin. The manifest declares a nine series beta and marks the package as not published, so the crate is not the distribution route. The release tags show a seven line and an eight line both receiving maintenance releases in 2026, with the eight line ahead. And the Dockerfile in the repository opens by calling itself a minimal build environment that may be outdated, pointing at a different repository for the current version, and stating the container requirement. Around that sit the signals of a regulated-market project: a separate FIPS build file, a security directory, a dependency policy file, a fuzzing directory, an owners file with aliases, and a document naming the performance-critical path. So read the build environment as a convenience and the release tags as the versions.
Editorial conclusion
TiKV fits a team that wants an ACID key-value store across commodity machines, with replication handled at region granularity and no manual placement, and that is prepared to operate a placement driver as a service in its own right. It does not fit someone who wants a single binary, because the documented minimum is a placement driver plus a store. Before you deploy, choose a line deliberately, since two major lines are in release and the manifest sits on a beta of the next. Then read the compose file rather than reaching for the binary route, and notice that it pulls nightly images and gives the placement driver a forty second start period for leader election. And treat the in-repository build environment as a convenience, because its own header says the file may be outdated and points elsewhere for the current version.
Frequently asked questions
What are the key differences between TiDB and TiKV?
TiKV was created by the same organisation to complement TiDB, which is described as a distributed hybrid transactional and analytical database compatible with the MySQL protocol. TiKV is the storage layer underneath: a distributed transactional key-value database that offers both classical key-value interfaces and transactional interfaces with ACID guarantees, and that the two are designed to work together.
How do I run a minimal TiKV deployment?
The file says TiKV can run separately with the placement driver, and that this is the minimal deployment. You download and extract the store and driver binaries, supporting only two named operating systems and two architectures, start the driver with a name, data directory, client and peer URLs, an initial cluster string and a log file, then start the store pointed at the driver endpoint with its own address, data directory and log file.
What does the Placement Driver do in TiKV?
It is the cluster manager. It periodically checks replication constraints to balance load and data automatically, it implements auto-sharding, and it is what enables automatic data migration. Node, store and region metadata is recorded into it when a node starts, and the status of each region and store is reported to it regularly.
How does TiKV store and replicate data?
Four levels. A region is the basic unit of key-value data movement and is replicated to multiple nodes, with those replicas forming a Raft group. A store holds a RocksDB instance and writes to local disk. A node is a physical machine with one or more stores. Consensus state is kept in RocksDB, and the implementation is in Rust.
Which build features does TiKV offer?
Four allocator choices selected at build time, plus switches for portable builds, vector instructions, memory profiling and tablet-lifetime tracing. There is a failpoint feature that compiles fault-injection points into five crates, a set of test-export hooks spanning several more, and a vendored TLS option whose comment explains the interaction with the gRPC build.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tikv-tikv)Star history chart for your README
[](https://hysenlabs.com/projects/tikv-tikv)Was this useful?