Perspective: a streaming pivot grid that runs in the browser or on top of your own database
A data visualization and analytics component, especially well-suited for large and/or streaming datasets.
At a glance
- What is it?
- Perspective is a data grid, pivot table and charting component built on a streaming query engine that runs in the browser through WebAssembly or server-side in Python, Node and Rust, and it can also sit in front of DuckDB, ClickHouse, PostgreSQL or Polars. The limits show up wherever a view configuration cannot express what you actually need.
- Who is it for?
- Adopt Perspective when a report has to stay live while rows keep arriving and one view configuration must work in a browser tab and on a server. Skip it if your report leans on hand-written SQL that uses features of your own database, since the README describes virtual servers as translating view configurations into native queries.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Rust, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
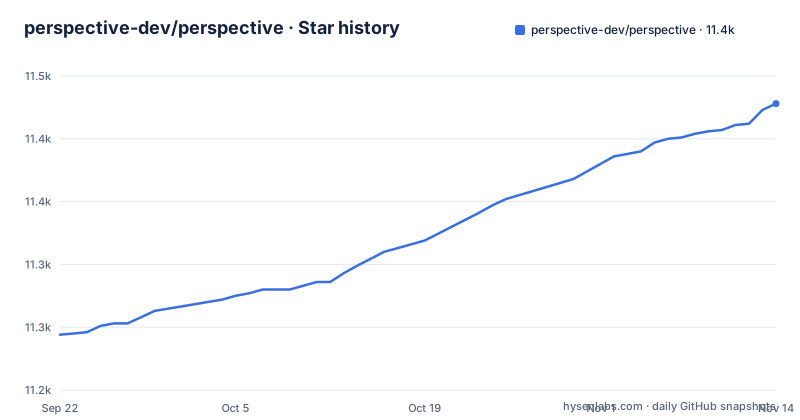
- perspective-dev/perspective11,428 ★ · +184
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| perspective-dev/perspective | 11.2k | 11.4k |
184 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
One view config, four engines, and a WebSocket in between
A single Client API reaches an engine in-process, in a Web Worker, or remotely over WebSocket, and behind all three sits the same C++ query engine compiled for WebAssembly, Python and Rust. Server-side deployments pick a transport from examples/python-aiohttp, examples/python-starlette, examples/python-tornado and examples/rust-axum, and the Python distribution ships handlers as perspective.handlers.aiohttp, perspective.handlers.starlette and perspective.handlers.tornado.
What stays constant across those choices is the view configuration: columns, filters, aggregates and layout, assembled by drag and drop in the viewer Custom Element, sent to whichever engine answers, and returned as the rows and series the UI paints. Moving from a WebAssembly engine inside a Web Worker to a Rust server at the other end of a socket changes where the aggregation happens and which machine pays for the CPU. It does not change the code that describes the view, which is the whole reason the architecture is worth the trouble once a table outgrows the browser. Tables update incrementally and views tick in real time rather than recomputing on demand, and the README lists reactive joins across tables.
memory64 and OPFS are two separate doors to datasets past 4GB
Reaching a large table in the browser takes two mechanisms that are not the same thing. The 64-bit memory64 build exists because a 32-bit WebAssembly module runs out of addressable heap at 4GB, and it is aimed at in-browser datasets larger than that. Paging columns to disk is orthogonal: OPFS in the browser, memory-mapped files natively, so columns that will not fit in memory spill out instead of being refused.
Both mechanisms land on the reader's machine rather than yours, and that is where the costs sit. A table paged into OPFS occupies the origin's storage. A user who clears site data loses the table. Treat a 4GB-plus in-browser table as something to confirm against your own browser support matrix before you promise it to users.
The expression language is ExprTK, and edits stop at Arrow, CSV and JSON
Computed columns and aggregates are written in ExprTK, the columnar expression language Perspective builds on, not in Python, JavaScript or Rust. A notebook user expecting to define a column with a lambda writes ExprTK instead, and a React developer who wants a ratio column writes ExprTK inside the view configuration rather than TypeScript. That keeps expressions in one language across the browser and server-side engines, and leaves host-language helpers out of reach.
Editing has a similar boundary. The data grid is virtual-scrolling and editable, and the engine carries read, write and streaming support for Apache Arrow, CSV and JSON. Virtual servers are described in the other direction, translating view configurations into native queries.
The README ships no install command, so pick a binding before anything else
Perspective's README links separate packages for each binding, so choosing a binding is the first decision a user has to make. JavaScript developers choose among @perspective-dev/react for the React component, @perspective-dev/viewer for the Web Component, and @perspective-dev/client, which the documentation links separately for browser and for Node.js. Python developers install perspective-python from PyPI, and Rust users take the perspective crate from crates.io, documented on docs.rs.
The repository carries a worked example for most of those paths: examples/react-example, examples/vite-example, examples/esbuild-example, examples/esbuild-remote and examples/cdn for the browser, plus per-engine directories such as examples/esbuild-duckdb-virtual, examples/esbuild-clickhouse-virtual, examples/python-duckdb-virtual and examples/python-polars-virtual. For a first real use, open the hosted demos at perspective-dev.github.io, where projects named Superstore, Raycasting, Movies, Evictions and Fractal each expose a different view configuration, then read the API reference for the one binding you chose. Each binding has its own reference page, so a Python-only plan and a React plan read different documentation for the same view.
The toolchain is pinned to Node 16 through 26, and panics abort the host
The build is pinned tighter than most JavaScript projects, and the pins decide what you can ship. The root package.json is private, sits at version 5.6.1, and freezes the toolchain used to compile the engine:
    "type": "module",
    "emscripten": "5.0.3",
    "binaryen": "version_132",
    "llvm": "17.0.6",
    "pyodide": "314.0.7",
    "engines": {
        "node": ">=16 <27"
    },
Node 16 through 26 is the declared range, so every newer runtime line falls outside it. Rebuilding from source needs those exact Emscripten, LLVM and Binaryen versions together rather than whatever a distribution ships. The Rust workspace makes a second set of choices:
[profile.release]
panic = "abort"
opt-level = "z"
codegen-units = 1
lto = true
strip = true
opt-level "z" optimizes for size, and panic = "abort" applies to the dev and release profiles alike. In a browser tab that costs only the page. Embedded in a Python process or a Rust service, an abort inside the engine takes the host process down instead of raising an error the application can catch.
Virtual servers move the pivot into DuckDB, ClickHouse, PostgreSQL or Polars
Virtual servers change the cost model. Rather than copying a table into Perspective's own engine, the viewer can run on top of DuckDB, ClickHouse, PostgreSQL or Polars, translating the view configuration into that engine's native queries with no ETL step and no data copy.
The difference against writing the pivot yourself is where the grouping logic lives. Hand-written, you own the SQL dialect for every engine you support and every report change touches application code. Behind a virtual server, the pivot is expressed once as a view configuration and the translation happens per engine, which is a real saving for anyone serving several databases from one UI. What it does not cover is anything the configuration cannot express.
Data movement differs with the mode as well. Mirroring copies rows into the browser for fluid interaction, while virtualizing keeps the table server-side and streams only what is visible.
Authentication, rollback and row limits have no documented answer
The README lists the WebSocket transport and the aiohttp, Starlette and Tornado handlers as server bindings; confirm in the user guide how connections are authorized before exposing a server.
The release history is active: v5.5.1 shipped on 2026-09-18, v5.6.0 on 2026-10-14 and v5.6.1 on 2026-10-23, and the last push to master was on 2026-10-27. Anyone pinning a version needs to know which of those changes a saved view configuration can absorb, and CHANGELOG.md groups entries under labels named enhancement, bug and internal, so part of each release is deliberately not user-facing.
Governance, security policy and project charter live in GOVERNANCE.md, SECURITY.md and PROJECT_CHARTER.md. The code is Apache-2.0, which matters if the engine is embedded in a product you sell: read LICENSE.md for the notice and patent terms rather than trusting any summary of them, including this one.
Editorial conclusion
Adopt Perspective when a report has to stay live while rows keep arriving and one view configuration must work in a browser tab and on a server. Skip it if your report leans on hand-written SQL that uses features of your own database, since the README describes virtual servers as translating view configurations into native queries. Check first whether the browsers you must support ship a memory64 WebAssembly runtime and OPFS, because that decides whether a large table ever reaches the client at all.
Frequently asked questions
Which Perspective package should a JavaScript project start with?
@perspective-dev/client is the browser and Node.js client, @perspective-dev/viewer is the Web Component, and @perspective-dev/react is the React component, each with its own API reference page. The viewer and grid render drag-and-drop view configuration while the client handles the transport to the engine.
Does Perspective need a server to run?
No. The streaming query engine compiles to WebAssembly and runs in the browser, or runs server-side in Python, Node.js and Rust, or a virtual server puts the UI on top of DuckDB, ClickHouse, PostgreSQL or Polars. Server bindings exist for aiohttp, Starlette, Tornado, Node.js and Rust.
Can Perspective hold a dataset larger than 4GB in the browser?
A 64-bit memory64 build is provided for in-browser datasets larger than 4GB, and columns can be paged to disk through OPFS in the browser or memory-mapped files natively.
What language are Perspective expressions written in?
The columnar expression language is based on ExprTK and runs in the streaming query engine. It is not JavaScript, Python or Rust code, so computed columns cannot call helpers written in the host language.
Which Node versions does the Perspective workspace declare support for?
The root package.json sets engines to ">=16 <27", with emscripten 5.0.3, llvm 17.0.6, binaryen version_132 and pyodide 314.0.7 pinned for building the engine. Newer Node release lines fall outside that range.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/perspective-dev-perspective)Star history chart for your README
[](https://hysenlabs.com/projects/perspective-dev-perspective)Was this useful?