turboquant-pytorch's own table shows its headline configuration producing garbage
From-scratch PyTorch implementation of Google's TurboQuant (ICLR 2026) for LLM KV cache compression. 5x compression at 3-bit with 99.5% attention fidelity.
At a glance
- What is it?
- A from-scratch PyTorch reimplementation of Google's key-value cache quantizer, which reaches the opposite conclusion from the paper on its central innovation and publishes the retracted numbers alongside the corrected ones. The repository description still advertises the exact configuration the results table reports as broken, and a result that was formally withdrawn appears again further down as a positive finding.
- Who is it for?
- The most valuable thing in this repository is that it disagrees with its own paper and publishes why, which almost never happens in a reimplementation. If you are evaluating compressed key-value caches, the usable finding is that asymmetric allocation beats uniform allocation, that a residual window of recent tokens held at full precision is not optional at low bit widths, and that attention score similarity is the wrong metric to optimise for.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 6 months ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
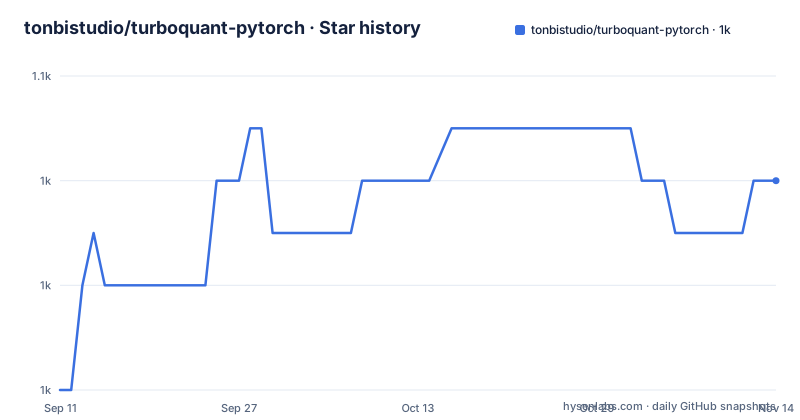
Star history
- tonbistudio/turboquant-pytorch1,048 ★ · +4
| Repository | 2026-09-11 | 2026-11-14 |
|---|---|---|
| tonbistudio/turboquant-pytorch | 1k | 1k |
4 Stars in the last 64 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The description advertises the configuration the results table calls broken
Read the repository summary and then read the results table.
The summary says 5x compression at 3-bit with 99.5 percent attention fidelity. The generation test in the README reports the opposite for that configuration. A 4-bit-key, 2-bit-value setup with no residual window, which averages three bits, gives roughly five times compression and the result MISS at both context lengths, where MISS means the model failed to output the fact it was asked to retrieve.
The README then says it in a sentence: 3 to 4 bit compression without a residual window produces garbage, and generation is broken at 3-bit keys. And one line further up: high attention score similarity at 99.5 percent and above does not guarantee working generation.
So the summary on the project page advertises the one row of the table that produces garbage, and pairs it with a fidelity figure the README explicitly disowns as a predictor of working output.
The nearest thing to a working configuration is a quarter of the compression: 4-bit keys with 4-bit values and a 128-token window of recent tokens held at full precision, which gives about twice the compression with exact output at both context lengths.
Anyone who installs this from the project description rather than the results table will benchmark the broken case.
The retracted 18/18 result is still printed as a finding
This repository published a correction, and it is one of the more honest corrections you will find.
Dated 2026-03-30, it says an earlier version of the README claimed 18 out of 18 perfect generation at 5x compression, that the claim rested on a bugged test where the residual window parameter was set to zero and therefore no compression happened at all, and that the corrected results replaced it. A community member is credited for finding the bug, with a link to the issue.
That is the right thing to do, and it is unusual.
The problem is that the withdrawn number survives. In the section explaining why the paper's second stage does not work, the evidence list ends with two lines: the version with that stage passed 0 out of 27 generation tests, and the version without it passed 18 out of 18. Same figure the correction withdrew, restated as the winning side of an argument, with no note that it came from the test that was found to be measuring nothing.
Two readings are available. The corrected suite and the original suite may be different, in which case both numbers are true about different things and the README should say which is which. Or the figure was carried over from the retracted run, in which case the strongest single claim in the argument for the redesign rests on a test that was measuring nothing at all.
Nothing in the visible text distinguishes those cases.
Six teams reached the same conclusion against the paper's stage two
The paper's method has two stages. The first is what most people would call the algorithm: rotate each vector by a random orthogonal matrix so every coordinate follows a predictable bell-shaped distribution, then apply an optimal scalar quantizer per coordinate and round to the nearest precomputed centroid. Quantizing normalizes, rotates, rounds and stores indices plus a norm. Dequantizing looks up centroids, reverses the rotation and restores the norm.
The second stage is a residual correction that stores one bit of sign information per coordinate so that inner product estimates become mathematically unbiased. This implementation calls that version two, and reports that it does not work for the key-value cache.
The reasoning is the interesting part. The correction is unbiased for raw inner products, but attention does not use raw inner products; it runs the scores through a softmax, and softmax amplifies variance exponentially. So a technique whose whole selling point is removing bias ends up injecting noise that the softmax magnifies. A mean-squared-error method, which has biased inner products but lower variance, wins once the softmax is applied.
The cited evidence is a third-party measurement of plus 300 percent error with the correction against plus 7.6 percent without it, on a small model, plus the confirmation from six independent teams.
The fairness is worth noting too. The correction is said to work for vector search, which has no softmax and is the paper's other use case, and may work with attention variants that skip the softmax entirely.
Version two made the cache 38 percent larger than not compressing
One line in the list of improvements is worth reading on its own.
Bit-packed storage, described as real compression ratios rather than theoretical ones. The parenthetical explains why it was needed: version two stored tensors that were 38 percent larger than uncompressed.
So the earlier implementation of this algorithm, the one that followed the paper's second stage, did not compress anything. It expanded the key-value cache by more than a third. The fix is described as bit-shifting in the compression routine, which is the ordinary way to pack sub-byte values, and the absence of it means the earlier version was storing a value per coordinate in storage sized for a full byte.
That has a knock-on effect on every number in the earlier results. A compression ratio computed against a cache that grew by 38 percent is not a compression ratio, and the attention score table in the current README, which lists the version two rows at 5.0x and 3.8x, is measuring the version with bit-packing, not the version that shipped without it.
It is also a caution about the paper itself. If the reference implementation this project followed had the same storage behaviour, then published ratios from that lineage may not be comparable either. Nothing in the repository says whether it does.
The configuration that works gives up half the compression
The generation test is a needle-in-a-document check. A specific fact is hidden in a long document and the model is asked to retrieve it, so the test measures whether text comes out correct rather than whether scores look close.
Six configurations, at two context lengths, with the ratios measured at the shorter one. The uncompressed baseline is exact at both and defines 1.0x. The two working configurations both keep a 128-token residual window at full precision: 6-bit keys with 4-bit values gives about 2x and is exact at both lengths, and 8-bit keys with 4-bit values gives about 1.6x and is also exact.
Everything below 6-bit keys degrades. 4-bit keys and 4-bit values with the window is partial at the short context, producing both halves of the identifier but dropping the hyphen, and misses entirely at the longer one. Remove the window and it misses at both.
The residual window is the variable that matters and it is the least discussed. It means a fixed number of recent tokens are kept at full precision and never compressed, which costs memory proportional to context length and buys correctness at low bit widths. The window is what turns three-bit keys from garbage into a partial answer.
The honest summary is that this project delivers roughly a halving of the key-value cache with no loss, and loses the cache at anything more aggressive.
The best attention configuration is the one never generation-tested
There are two results tables and they measure different things, and the README is careful to say so.
The attention score table is labelled as valid because it tests compression directly on captured key-value tensors rather than through the project's cache wrapper. It runs at 8K context and reports compression, cosine similarity of the scores, and the share of tokens where the top-ranked entry matches at rank one and rank five.
The best row there is the asymmetric configuration with protected layers: 3.6x compression, cosine similarity just under one, 99 percent top-one and 100 percent top-five. The unprotected version of the same bit allocation gives 5.1x with 94 percent and 97 percent. Both version two rows, the ones with the correction stage, sit lower: 86 percent top-one in both cases.
Protected layers are the fourth listed improvement, and they produce the best fidelity numbers in the table. There is no row for them in the generation test. The generation test covers six configurations and that is not one of them.
So the configuration that scores best on the metric is unvalidated on the metric that matters, and the README is explicit that the score metric and generation can disagree. That combination is how a research repository ends up with a best result nobody has run end to end.
The tests are modules inside the package, and there is no tests directory
The repository root is small: a workflows directory, a gitignore, a licence, the README, a packaging manifest, a requirements file and the package directory. There is no tests directory.
What there is instead is four runnable modules, all launched the same way:
python -m turboquant.generation_test
python -m turboquant.validate_v3
python -m turboquant.test_turboquant
python -m turboquant.validate
The synthetic test is the only one that needs no model, and it validates the core algorithm against the theoretical bounds in the paper. The other three load a real model, and the first run of any of them downloads an instruction-tuned 3B model of about two gigabytes.
That arrangement has one genuine advantage, which is that you can check the algorithm works before spending the download. It also means the validation code ships inside the installed package rather than in a separate test suite, so the packaging manifest declares no test tooling, no test extra, and no coverage settings, and nothing stops a user from importing a validation module that expects a two gigabyte checkpoint to be present.
The manifest also has no author field and no project URL section, which is unusual for a package that expects people to file issues about bugged tests.
Windows-first on one consumer card, with an unused dependency
The stated requirements are Python 3.10 or newer, a CUDA-capable NVIDIA graphics card, and Windows 11, with a note that it also works on Linux.
The testing claim is narrower than the requirement. It was tested on one card, a 12 GB consumer model from the previous generation. The Linux claim is a single line with no detail about what was or was not verified there.
The dependency list is five entries, duplicated verbatim in the requirements file, and one of them stands out. Alongside torch, scipy, transformers and accelerate there is a bits-and-bytes library for low-precision GPU kernels. Nothing in the visible documentation uses it. The description of the implementation says from-scratch PyTorch with a hand-written Lloyd-Max solver and bit-shifting, none of which needs it.
So the library is a hard install requirement for every user of a package that does not appear to call it, probably inherited from the paper's original implementation.
Two smaller details. The distribution is named one thing and the import package another, so the install name and the name you import differ. And the version is 0.1.0 with no published releases, so there is no artifact to pin.
Editorial conclusion
The most valuable thing in this repository is that it disagrees with its own paper and publishes why, which almost never happens in a reimplementation. If you are evaluating compressed key-value caches, the usable finding is that asymmetric allocation beats uniform allocation, that a residual window of recent tokens held at full precision is not optional at low bit widths, and that attention score similarity is the wrong metric to optimise for. If you are installing it, three things first. The repository description overstates what the code does, so read the generation table rather than the summary. The one retracted number is still printed as a result elsewhere in the same file, so treat any single pass rate with suspicion. And the project is a research reimplementation with no releases, a 0.1.0 version, a Windows-first setup validated on one consumer graphics card, and a dependency on a bits-and-bytes library that its own visible code never uses.
Frequently asked questions
What is tonbistudio/turboquant-pytorch?
It is a from-scratch PyTorch implementation of TurboQuant, Google's vector quantization algorithm for compressing large language model key-value caches, published as an ICLR 2026 paper. The implementation was tested on Windows with NVIDIA GPUs and ships as a research package rather than a release.
What compression does turboquant-pytorch actually achieve?
Its own generation test reports roughly 2x with exact output at both context lengths for 6-bit keys with 4-bit values and a 128-token residual window kept at full precision. Configurations at 3 to 4 bit keys without that window are reported as producing garbage, including the roughly 5x configuration named in the project description.
Why does turboquant-pytorch say the paper's QJL stage does not work?
Because attention runs scores through a softmax, which amplifies variance exponentially, so a correction that removes bias from raw inner products ends up injecting noise that the softmax magnifies. A mean-squared-error method with biased inner products but lower variance wins after the softmax. The README cites a third-party measurement of plus 300 percent error with the correction against plus 7.6 percent without, and confirmation from six independent teams.
What is the residual window in turboquant-pytorch?
It is a fixed number of recent tokens, 128 in the reported configurations, kept at full precision and never compressed. It is what lets low-bit configurations produce correct text at all, and the README reports that removing it turns working configurations into ones that miss the retrieved fact entirely.
What was the correction in tonbistudio/turboquant-pytorch's README?
A note dated 2026-03-30 says an earlier version claimed 18 out of 18 perfect generation at 5x compression, that this rested on a bugged test where the residual window was zero and no compression occurred, and that corrected results replaced it. A community member is credited for finding the bug.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tonbistudio-turboquant-pytorch)Star history chart for your README
[](https://hysenlabs.com/projects/tonbistudio-turboquant-pytorch)Was this useful?