MemPalace: A Local-First AI Memory System That Stores Verbatim, Not Summaries
The best-benchmarked open-source AI memory system. And it's free.
At a glance
- What is it?
- MemPalace is an open-source, MIT-licensed Python tool that stores conversation history as verbatim text and retrieves it via semantic search, with a structured index of wings, rooms, and drawers. It claims 96.6% R@5 on LongMemEval with zero API calls, but its real value is in its local-first design and pluggable backends.
- Who is it for?
- Adopt MemPalace if you need local-first, verbatim AI memory and can tolerate a Python dependency stack and first-run model downloads. Skip it if you require native Termux support or a published GPU image.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
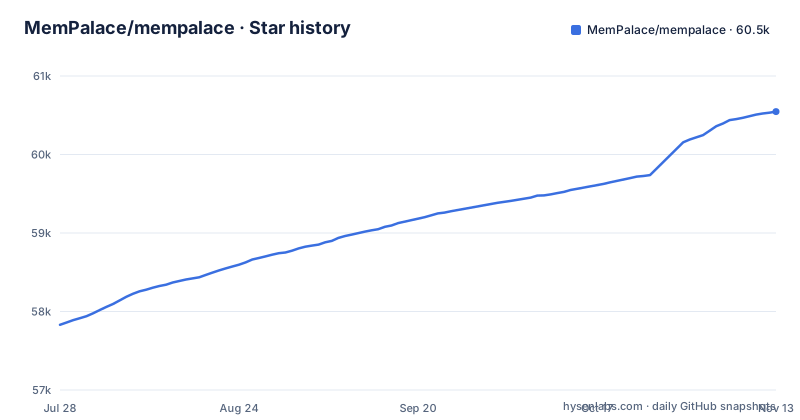
- MemPalace/mempalace60,546 ★ · +2,715
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| MemPalace/mempalace | 57.8k | 60.5k |
2,715 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What MemPalace Solves and Who It Is For
MemPalace addresses a specific failure in AI-assisted development: conversational memory that decays. Chat histories with coding agents like Claude Code are ephemeral, and summarization loses the exact wording of decisions, constraints, and code snippets. MemPalace stores conversation history as verbatim text, not as summaries or paraphrases. This matters for engineers who need to retrieve the exact phrasing of a requirement or a past debugging session. The intended user is a developer or team using an MCP-capable agent, who wants a searchable memory that stays on their machine. The README states that nothing leaves your machine unless you opt in, which positions it for privacy-conscious users and organizations with data-handling restrictions.
The Palace Metaphor: Wings, Rooms, and Drawers as a Scoping Mechanism
The retrieval index is not a flat vector store. MemPalace organizes content into a three-level structure: people and projects become wings, topics become rooms, and original content lives in drawers. This is not cosmetic. It allows searches to be scoped to a specific project or topic, which reduces noise compared to a global semantic search. The README explains that searches can be scoped rather than run against a flat corpus. For an engineer, this means you can ask 'what did we decide about the auth flow for project X' without wading through unrelated conversations. The trade-off is that you must maintain this structure, either manually or through the mining process, which adds a layer of organization overhead.
How Retrieval Works: Pluggable Backends and the ChromaDB Default
The retrieval layer is defined by an interface in mempalace/backends/base.py. The default backend is ChromaDB, but the design allows alternative backends to be dropped in without touching the rest of the system. This is a practical architecture: you can swap the vector store without rewriting the memory logic. The system uses semantic search, meaning it retrieves based on meaning rather than exact keyword match. The README claims a 96.6% R@5 raw score on LongMemEval, which is a retrieval benchmark.. You should treat that number as a marketing claim until you reproduce it on your own data.
Installation: Agent-Guided Setup, CLI, and Docker
There are three installation paths. The agent-guided setup uses npx skills add MemPalace/mempalace to install three skills: mempalace for guided installation, mempalace-recall for search-before-answer recall, and mempalace-task for logstream delegation. The setup skill detects your system, installs the Python package, configures MCP, and asks whether you want a private local palace, a shared-brain hub, or a client connected to an existing hub. The direct CLI path uses uv tool install mempalace, then mempalace init ~/projects/myapp. The README warns against plain pip install outside a virtualenv due to PEP 668 errors on Debian/Ubuntu and dependency conflicts. Docker is the third path: docker pull ghcr.io/mempalace/mempalace:latest, with everything persisting under /data. The image runs as uid 1000, which causes a permission gotcha on Linux: mounted directories must be readable by that uid, and a 0700 directory fails with PermissionError. Do not use --user to work around it, because /data is owned by uid 1000 and another uid cannot write the palace.
First-Run Costs: Model Downloads and Network Dependencies
The first command that needs embeddings downloads a model into /data. The default is minilm at about 80 MB, and embeddinggemma is about 300 MB. This is a one-off if the volume persists, but it makes the first call slow and requires network access. The README explicitly warns about this, saying it is worth knowing before assuming a hung container. For an engineer, this means a fresh deployment is not fully offline until the model is cached. It also means the container needs outbound network on first run, which may conflict with air-gapped environments. If you are considering MemPalace for a secure facility, factor this into your deployment plan.
Limitations: Termux, GPU on ARM, and Claude Code Session Expiry
MemPalace has three notable limitations. First, native Termux installation is not supported because ChromaDB and ONNX Runtime do not publish Android wheels. Android ARM64 users must run Linux packages in a Debian PRoot container. Second, the GPU image variant is not published, so you have to build it yourself from Dockerfile.gpu. Third, and most critically, the README contains a caution that Claude Code sessions expire in 30 days without auto-save hooks wired. There is a discussion link and a setup checklist, and the repository has an examples/HOOKS_TUTORIAL.md file. You must read the linked guide before relying on it for long-term retention.
Maintenance and Upgrade Cost
The project is under active development, with recent releases v3.11.0 (2026-10-14), v3.10.0 (2026-09-16) and v3.9.0 (2026-08-31), and the default branch is develop. This suggests a fast-moving codebase, which means upgrades are frequent. The release titles mention audit, repair and opt-in EmbeddingGemma 2, lighter ways in for agents, and one hub for every agent. You should expect to monitor releases if you deploy this in production. The license is MIT, which is permissive, but it comes with no warranty, and you are responsible for any legal implications of storing user conversation data, even locally. The README also warns about impostor sites, so you must only install from the official GitHub, PyPI, or mempalaceofficial.com to avoid malware.
Alternative: A Flat Vector Store with Summarization
A common alternative is to use a generic vector database like ChromaDB directly, combined with a summarization step. The difference is in the storage philosophy. MemPalace stores verbatim text, while many memory systems summarize or extract key points to save space and improve retrieval speed. Summarization loses exact wording but can reduce storage size and may be sufficient for high-level recall. The trade-off is precision versus recall of exact phrasing. If you need to retrieve a specific error message or a precise user requirement, verbatim storage is superior. If you only need the gist of past conversations, a summarization-based approach is simpler and requires less infrastructure. MemPalace's structured index is the other differentiator; a flat vector store requires you to implement your own scoping or tagging to achieve the same level of filter.
Editorial conclusion
Adopt MemPalace if you need local-first, verbatim AI memory and can tolerate a Python dependency stack and first-run model downloads. Skip it if you require native Termux support or a published GPU image. Before committing, verify the current state of the Claude Code auto-save hooks, since sessions expire in 30 days without them, and test the retrieval quality on your own conversation types, as the 96.6% benchmark may not transfer to your data.
Frequently asked questions
What is MemPalace?
It is a local-first AI memory system that stores conversation history verbatim and retrieves it with semantic search, without summarizing or paraphrasing. Content is filed into wings, rooms and drawers, and the retrieval backend is pluggable through mempalace/backends/base.py with ChromaDB as the default.
How do I install MemPalace?
The recommended route is uv tool install mempalace, then mempalace init with a project path. pipx install mempalace works the same way, and plain pip is suggested only inside a virtual environment you activated yourself.
How do I use MemPalace with Claude Code?
Run it as an MCP stdio server over JSON-RPC, with the -i flag so stdin stays open, and mount your project transcripts directory read-only at a container path such as /transcripts, using a real absolute path since ~ and $HOME are not always expanded. The README also warns that Claude Code sessions expire in 30 days unless auto-save hooks are wired.
Does MemPalace actually work?
The project reports 96.6 percent R at 5 raw on LongMemEval with zero API calls, and that is its own figure rather than an independent measurement. A benchmarks directory sits at the repository root..
Is MemPalace safe to install?
Storage is local and verbatim, and the project states that nothing leaves your machine unless you opt in. It also warns that only the GitHub repository, the PyPI package and mempalaceofficial.com are official, and that any other domain may distribute malware.
Did Milla Jovovich create an AI memory tool?
The project metadata lists a single author named milla-jovovich in pyproject.toml. The README names the GitHub repository, the PyPI package and mempalaceofficial.com as the only official sources.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/mempalace-mempalace)Star history chart for your README
[](https://hysenlabs.com/projects/mempalace-mempalace)Was this useful?