ollama_pdf_rag is three interfaces over one LangChain pipeline, and only one of them is current
A full-stack demo showcasing a local RAG (Retrieval Augmented Generation) pipeline to chat with your PDFs.
At a glance
- What is it?
- A Next.js app, a Streamlit app, and a set of notebooks sitting on a FastAPI service and a ChromaDB store, all reading local Ollama models so no document leaves the machine. The setup path is well trodden and the failure modes are documented, including an ONNX DLL error on Windows and a chunk size to lower on a CPU-only box. What has not moved is the project itself: the newest release is v3.0.0 from December 2025 and the last commit is from April 2026.
- Who is it for?
- Use it if you want a working reference for a local RAG pipeline rather than a maintained product, since the interfaces, the endpoint list, and the troubleshooting notes are all concrete enough to copy. Budget for two things the README does not flag.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Activity is slowing. The repository last received commits 7 months ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
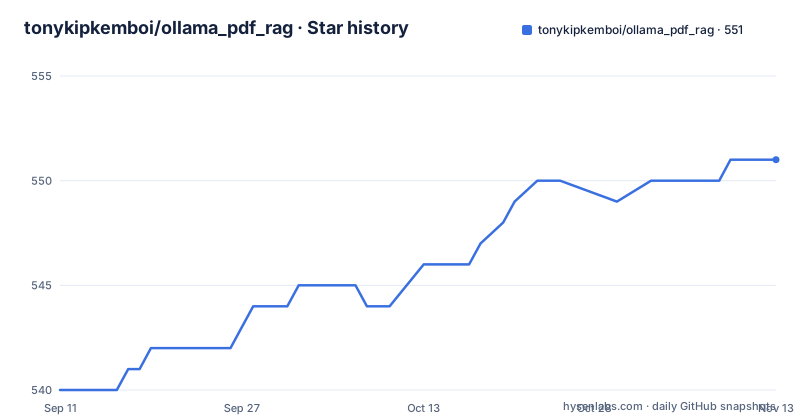
- tonykipkemboi/ollama_pdf_rag551 ★ · +11
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| tonykipkemboi/ollama_pdf_rag | 540 | 551 |
11 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three interfaces and one backend, and the frontend migrates its own database
The application is one Python core wrapped in three front ends. The core splits into a document module for PDF processing, an embeddings module, an LLM configuration module, and the RAG chain itself. The FastAPI service layers routers and services on top and runs on port 8001 with Swagger at its docs path. The Next.js app is the recommended interface on port 3000, and a Streamlit app on 8501 remains as the classic option. Notebooks sit beside them for experimentation, with one named for updated RAG experiments. Running the pair means two terminals:
python run_api.py
cd web-ui && pnpm dev
or using a convenience shell script that starts both. The API surface is six endpoints: upload and process a PDF, list uploaded PDFs, delete one by identifier, query with RAG, list available Ollama models, and a health check.
pnpm db:migrate is a setup step with no explanation anywhere
The frontend setup runs pnpm install and then pnpm db:migrate, and that second command is the one with nothing behind it. The requirements file shows why there is something to migrate: the backend pulls in SQLAlchemy, aiosqlite, and pydantic-settings, and the ChromaDB vector store is configured separately through a VECTORDB_PATH pointing at a data directory. So the stack has at least two pieces of persistent state, a relational store behind the Next.js app and a vector store behind the retrieval chain, and the README explains neither the schema, the engine, nor why the migration belongs to the frontend rather than the backend. A newcomer following the steps in order will get past it, but anyone who wants to know what is being written to disk, or how to reset it, has to read the web-ui package instead of the README.
requirements.txt pins numpy exactly and lists unstructured twice
The dependency file mixes three policies in one list. LangChain is pinned hard at 1.0.0, with langchain-core at 1.0.0 or newer, langchain-ollama at 1.0.1, and the text splitters at 1.0.0, while ChromaDB, the Ollama client, FastAPI, and pytest float with floors. Then there are exact pins that look like archaeology: numpy at 1.26.4, Pillow at 10.4.0, coverage at 7.4.0, and pdfminer.six at a calendar version, 20251107, which dates itself rather than carrying a semantic number. unstructured appears twice as well, once bare and once with the all-docs extra, so the second entry decides. pytest is the only dependency with a ceiling, held below 9. The practical effect is that upgrading this project means editing a list where some entries are load-bearing pins and others are not marked as such.
No Python version is stated anywhere in the setup
The environment step creates a virtual environment with python -m venv venv, activates it, and installs from the requirements file, with a note for Windows about the activation path. Nowhere does it say which Python that is. The tree also carries a pre-commit config, a mkdocs configuration, a changelog, and a data directory, so the project has more surface than the four numbered setup steps cover, but the interpreter version is the one thing left to the reader. That is not a small gap when a file pins numpy to an exact release and pdfminer.six to a dated one, because those two choices narrow which interpreters will resolve at all, and the resolution failure will look like a resolver complaint rather than a version mismatch. Pick a current Python, then let pip tell you what disagrees.
The screenshots section has captions and no images
The README has a screenshots section split into the Next.js interface, marked recommended, and the Streamlit interface. Each half contains a single italic line describing what you would see: a modern chat interface with PDF management, source citations and reasoning steps for one, a classic interface with a PDF viewer and chat for the other. Neither is followed by an image. The two captures exist as files at the repository root, nextjs_ui.png and st_app_ui.png, but they are not embedded where they would help, so a reader deciding between the two interfaces is reading a caption rather than comparing them. The same pattern appears a few lines down, where the video tutorial is an anchor element with nothing inside it, which renders as an empty link rather than a thumbnail. The badge row above has the same issue: one link to the test workflow with no image between the brackets.
Four documented failures, and three of them are environmental
The troubleshooting list is short and specific. Ollama not responding means the daemon is not running, and the fix is to serve it. A model not found is fixed by pulling it. An empty retrieval result is fixed by re-uploading the PDFs to rebuild the vector database, which tells you the retrieval layer caches its index and that a stale index is a state you can get stuck in without an error. Port conflicts name 3000, 8001, and 8501, the three services the project starts. Two errors are more specific. On Windows, an ONNX DLL load failure while importing the export module is fixed by installing the Microsoft Visual C++ Redistributable and restarting, which is a dependency of the unstructured stack rather than of this project. On a CPU-only machine the advice is to lower chunk_size to between 500 and 1000 in the document module, which is the only tuning knob the README names.
The last release is ten months old and the docs site is unmentioned
The release history has three tags: v2.0 in November 2024, v2.1.0 in January 2025 with testing infrastructure and project architecture, and v3.0.0 in December 2025, which is the Next.js UI, the FastAPI backend, and the enhanced RAG chain. That is the shape of a project that got its architecture right and then stopped, and the last commit is dated 2026-04-16. Read that as a maintenance signal rather than a defect: the code is a reference implementation, the interfaces are documented, and nobody is promising compatibility with a LangChain release from the future. One loose end sits in the same tree. There is an mkdocs configuration and the project publishes a Pages site at a GitHub Pages address, and the README never mentions either. The documentation you are reading is therefore not necessarily the documentation that gets built.
Editorial conclusion
Use it if you want a working reference for a local RAG pipeline rather than a maintained product, since the interfaces, the endpoint list, and the troubleshooting notes are all concrete enough to copy. Budget for two things the README does not flag. You will pick a Python version yourself, because none is stated anywhere while several dependencies are pinned exactly. And you will meet at least one of the four documented failures, most likely the empty retrieval, whose own remedy is to re-upload the files and rebuild the vector database.
Frequently asked questions
What is ollama_pdf_rag?
A local retrieval-augmented generation demo that lets you chat with PDF documents using Ollama and LangChain, with ChromaDB for vector storage. It ships three interfaces: a Next.js web app as the primary one, a Streamlit app, and Jupyter notebooks, all over a FastAPI backend.
Which models does ollama_pdf_rag need?
Two pulls. One chat model, with llama3.2 given as the example and any preferred chat model substituted, and nomic-embed-text for embeddings. Model selection also happens in the interface, from the Ollama models available locally.
How do I run ollama_pdf_rag?
Start the FastAPI backend with python run_api.py on port 8001, then the frontend with cd web-ui and pnpm dev on port 3000, or use the start_all.sh convenience script. The Streamlit alternative is python run.py on port 8501, and API documentation is at the docs path on port 8001.
Why does ollama_pdf_rag retrieve no chunks?
The documented remedy is to re-upload the PDFs so the vector database is rebuilt. On Windows, a DLL load failure while importing the ONNX export module is a different problem and needs the Microsoft Visual C++ Redistributable, and on a CPU-only machine lowering chunk_size to 500 or 1000 in the document module reduces memory pressure.
Is ollama_pdf_rag still maintained?
Slowly. The most recent release is v3.0.0 from 2025-12-19, which brought the Next.js UI, the FastAPI backend, and the enhanced RAG chain, and the last commit was on 2026-04-16. Treat it as a reference implementation rather than a service that tracks upstream library releases.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tonykipkemboi-ollama-pdf-rag)Star history chart for your README
[](https://hysenlabs.com/projects/tonykipkemboi-ollama-pdf-rag)Was this useful?