tqdm costs about 60ns per iteration, and its snap channel cannot be imported
:zap: A Fast, Extensible Progress Bar for Python and CLI
At a glance
- What is it?
- tqdm is a progress meter for Python loops and for shell pipelines, with no dependencies beyond a terminal that honours carriage return and line feed. The overhead claim is unit tested against regression, the install comes from several channels (PyPI, git, conda, snap, Docker) with different trade-offs, and predictive statistics only appear once a total is known.
- Who is it for?
- Adopt tqdm when you need a rate and an estimate on a long loop or a long pipe, and when a bar on a log stream is acceptable. Do not adopt it as a general terminal formatting library, because its scope is one progress meter and the documentation's own performance comparison is against python-progressbar rather than against richer console libraries.
- Can I use it commercially?
- Check first. The repository uses a licence we do not classify automatically, so read its LICENSE file before any commercial use.
- Is it still maintained?
- Yes. The repository last received commits 11 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
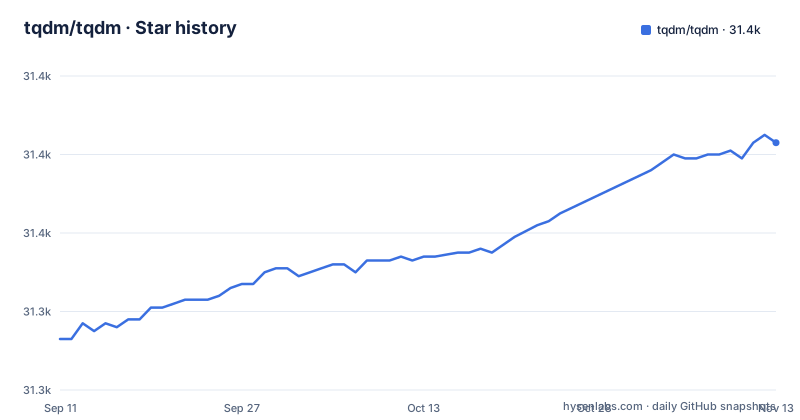
Star history
- tqdm/tqdm31,383 ★ · +50
| Repository | 2026-09-11 | 2026-11-13 |
|---|---|---|
| tqdm/tqdm | 31.3k | 31.4k |
50 Stars in the last 63 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The overhead figure is regression tested, and the name is Arabic and Spanish
The whole idea is one wrapper call. Put `tqdm()` around any iterable and the loop reports progress:
from tqdm import tqdm
for i in tqdm(range(10000)):
    ...
The cost is stated as about 60ns per iteration, rising to 80ns with `tqdm.gui`, and the README says that figure is unit tested against performance regression rather than asserted. Against the established `python-progressbar`, the same passage puts the alternative at 800ns per iteration. Two mechanisms are credited for keeping the bar cheap: smart algorithms that predict remaining time, and skipping unnecessary iteration displays.
The name has two origins rather than an acronym. It derives from the Arabic *taqaddum*, which can mean progress, and it abbreviates the Spanish *te quiero demasiado*. Neither explains the API, but both explain why the package is called what it is.
There are no dependencies, and `curses` is explicitly not one of them. The requirement is narrower and more portable: Python plus a terminal that honours carriage return and line feed control characters.
Four install channels, and only three of them give you an importable package
The stable release comes from PyPI:
pip install tqdmThe `devel` branch installs straight from git:
pip install "git+https://github.com/tqdm/tqdm.git@devel#egg=tqdm"Conda users have a forge channel with `conda install -c conda-forge tqdm`, and container users can `docker pull tqdm/tqdm` then `docker run -i --rm tqdm/tqdm --help`.
The Snapcraft channel is the one that changes what you get. It has three tracks: `snap install tqdm` implies the latest tagged release, `--candidate` follows the master branch, and `--edge` follows the devel branch. The README then draws a line under all three: snap binaries are purely for CLI use and are not import-able, and they set up bash tab-completion on their own. So the channel that gives you the most recent code is also the one that cannot be used from `from tqdm import tqdm`, and picking by instinct rather than by use case is the mistake here.
Elsewhere the README notes unofficial download locations, including a Repology badge, and points at repology.org for CLI-oriented builds.
Predictive statistics appear only once a total is supplied
Wrapping an iterable is the easy path. The manual path exists when the loop is not an iterable, and it is where the control surface shows up:
with tqdm(total=100) as pbar:
    for i in range(10):
        sleep(0.1)
        pbar.update(10)
The condition for the useful output is stated plainly: if the optional variable `total`, or an iterable with `len()`, is provided, predictive stats are displayed. Without a total, `tqdm` still counts, but the remaining-time estimate has nothing to divide by. Without a total the output is a count and rate, for example `857366it [00:03, 246471.31it/s]`, rather than a percentage bar with an ETA.
`with` is optional as well, and dropping it moves cleanup onto you. Assign `tqdm()` to a variable instead and the README is explicit that you must `del` or `close()` at the end.
As a command it is a stdin to stdout filter that writes to stderr
The CLI form is the least known entry point and often the most useful. Run `tqdm` (or `python -m tqdm`) between two pipes and it forwards everything from stdin to stdout while drawing the progress meter on stderr. Because the meter is on a different stream, it does not corrupt the data flowing through it:
find . -name '*.py' -type f -exec cat \{} \; |
    tqdm --unit loc --unit_scale --total 857366 >> /dev/null
The same pipeline without tqdm still prints the line count, so wrapping is transparent. The flags do the work here: `--unit loc` changes the unit from items to lines, `--unit_scale` switches to abbreviated counts, and `--total` supplies the count the filesystem cannot know in advance.
Two more show what the filter is for. Passing `--bytes` turns it into a byte counter, so `seq 9999999 | tqdm --bytes | wc -l` reports a transfer rate for a stream with no length. And a backup can be measured at two stages with `--desc` to label each bar and `--position 1` to stop the two bars from overwriting each other, with `BYTES=$(du -sb docs/ | cut -f1)` computed once and reused for both.
Instantiating outside the loop gives a bar you can drive by hand
There is a third usage mode between wrapping and manual updates, and it is the one to reach for when the loop body needs to report what it is doing. Create the bar first, iterate over the bar itself, and call methods on it as you go:
pbar = tqdm(["a", "b", "c", "d"])
for char in pbar:
    sleep(0.25)
    pbar.set_description("Processing %s" % char)
The difference from the wrapped form is that the object stays in scope, so `set_description` can rewrite the label mid-run. That matters when a single loop processes heterogeneous items and a fixed label would be misleading for most of them.
For counting ranges specifically, `trange` is not an alias in the ordinary sense. The README calls it a special optimised instance of `tqdm(range(i))`.
README.rst and the man page are build outputs, and coverage is gated at 80
The repository treats documentation as something it generates and then checks. The Makefile's `testsetup` target runs `@make README.rst`, `@make tqdm/tqdm.1` and `@make tqdm/completion.sh`, so the README you read on GitHub is a build artifact rather than a hand-edited file, and the man page target declares its inputs explicitly:
tqdm/tqdm.1: .meta/.tqdm.1.md tqdm/cli.py tqdm/std.pyRegenerating the man page therefore depends on the CLI and standard-output modules, which is how a signature change in `tqdm/std.py` ends up reaching `tqdm.1`.
The test targets are split by cost. Coverage runs with `pytest -k "not perf" --cov=tqdm --cov-fail-under=80`, so the suite fails below 80 percent, and performance is a separate target:
pytest -k perfcarrying the comment that coverage must not be used there because it is extremely slow. Notebook behaviour is tested too, by running `tests_notebook.ipynb` under pytest with the nbval plugin and a sanitising config at `.meta/nbval.ini`. Linting is routed through pre-commit rather than a direct flake8 call, and `asv.conf.json` with the `benchmarks/` directory drive `asv run -j 8 HEAD~3..HEAD` to compare the last three commits.
Python 3.8 is the floor, the version is derived from tags, and the licence is dual
Compatibility is stated broadly. `requires-python` is `>=3.8`, and the classifier list names Console, MacOS X, Win32 and X11 environments, the IPython and Jupyter frameworks, and operating systems from MS-DOS and FreeBSD through Linux and SunOS/Solaris. The README makes the matching claim in prose, adding NetBSD to the platform list and stating that it works in any console or in a GUI and is friendly with IPython and Jupyter notebooks.
The version is not written down. `[project]` declares `dynamic = ["version"]` and the build backend is setuptools with `setuptools-scm[toml]>=3.4`, so the version comes from git tags at build time. That is why a source checkout reports something different from a wheel, and it is also why the tags are the thing to pin against.
The licence is worth reading twice, because it explains a metadata oddity:
license = {text = "MPL-2.0 AND MIT"}Two licences apply at once, which is why repository metadata reports no single licence rather than picking one. Recent tags are v4.70.1 on 2026-09-11, v4.70.0 on 2026-07-27 and v4.69.1 on 2026-07-24. The last push was on 2026-10-05, the repository is not archived, and the default branch is `master`, which is also what the snap `--candidate` track follows.
Editorial conclusion
Adopt tqdm when you need a rate and an estimate on a long loop or a long pipe, and when a bar on a log stream is acceptable. Do not adopt it as a general terminal formatting library, because its scope is one progress meter and the documentation's own performance comparison is against python-progressbar rather than against richer console libraries. Verify three things before you commit: whether your channel can be imported, since the snap binaries are documented as CLI-only, not import-able; whether your iterable has a length, because without `total` you get a counter and no predictive statistics; and whether you can afford a manual `close()`, since dropping the `with` statement makes cleanup your responsibility. On the packaging side, `license = {text = "MPL-2.0 AND MIT"}` is a dual licence and the reason repository metadata shows no single licence, and the installed version comes from git tags through setuptools-scm rather than a literal in `pyproject.toml`.
Frequently asked questions
Why is tqdm called tqdm?
It has two unrelated origins. It derives from the Arabic word taqaddum, which can mean progress, and it is an abbreviation for the Spanish phrase te quiero demasiado.
What does tqdm do in Python?
It wraps an iterable to draw a progress meter showing percentage, count, elapsed time, rate and estimated time remaining. It also runs as a command line filter, passing stdin through to stdout while printing progress to stderr.
How does tqdm work?
You wrap any iterable with tqdm(), or create a bar yourself and drive it with update() calls. If the optional total variable, or an iterable with len(), is provided, predictive statistics are displayed, and smart algorithms predict the remaining time and skip unnecessary iteration displays.
Does tqdm slow down code?
The README puts the overhead at about 60ns per iteration, or 80ns with tqdm.gui, and says that figure is unit tested against performance regression. The repository keeps a benchmarks/ directory and an asv.conf.json so performance across commits can be compared, and the test suite separates perf runs from coverage runs.
What are the key differences between tqdm and Rich?
The README's overview compares performance against python-progressbar, put at 800ns per iteration against tqdm's roughly 60ns, so differences from Rich have to be established elsewhere.
What does from tqdm import tqdm bring in?
It imports the bar class itself, which you then wrap around an iterable. The same module also provides trange(i), described as a special optimised instance of tqdm(range(i)).
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tqdm-tqdm)Star history chart for your README
[](https://hysenlabs.com/projects/tqdm-tqdm)Was this useful?