Tube Archivist Docker Compose: Elasticsearch, Redis and your YouTube archive
Your self hosted YouTube media server
At a glance
- What is it?
- Tube Archivist is a self hosted YouTube media server that subscribes to channels, indexes them with YouTube metadata and plays them from a web interface. The search index lives in ElasticSearch, which is what you give up, and what you get, by running it as a three container stack.
- Who is it for?
- Adopt Tube Archivist if you already run Docker and want subscription indexing, viewed state and offline search over a YouTube backlog, and skip it if you only want files on a disk or you cannot spare the memory and the separate ElasticSearch volume. Before moving a live library across, check your CPU architecture first, because the bundled bbilly1/tubearchivist-es image is amd64 only and swapping in the official es 9.5.5 image is a step you take once, at install time.
- Can I use it commercially?
- Yes, with conditions. GPL-3.0 is a copyleft licence: if you distribute software that includes it, you must release that software's source code under the same licence. Running it internally without distributing it does not trigger that obligation.
- Is it still maintained?
- Yes. The repository last received commits 21 days ago.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
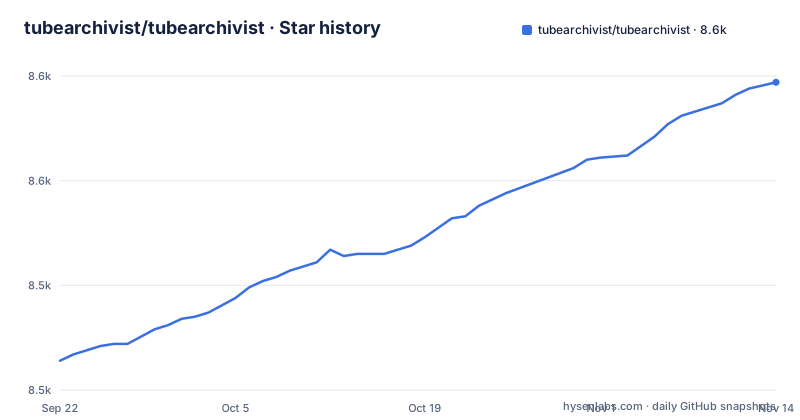
- tubearchivist/tubearchivist8,597 ★ · +133
| Repository | 2026-09-22 | 2026-11-14 |
|---|---|---|
| tubearchivist/tubearchivist | 8.5k | 8.6k |
133 Stars in the last 53 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Three containers, and one of them owns the search index
Tube Archivist is not a single app. The shipped docker-compose.yml starts three services: tubearchivist on port 8000, archivist-redis with 6379 exposed only inside the compose network, and archivist-es holding the index. REDIS_CON connects the app to Redis, ElasticSearch holds the metadata you search over, and two named volumes carry the data you would miss most, media at /youtube and cache at /cache.
That split is the design decision that shapes everything else. Your video files live in the media volume and nowhere else, so a backup of that volume matters more than a backup of the index. The web container can be rebuilt from the Dockerfile without touching a single video, while the ElasticSearch volume holds the searchable metadata and needs its own path.repo pointing at a snapshot directory, which the compose file sets to /usr/share/elasticsearch/data/snapshot. Set ES_SNAPSHOT_DIR if you want those snapshots somewhere other than the default, and mind the comment on the es volume line about checking for permissions.
    volumes:
      - media:/youtube
      - cache:/cache
The README asks for around 2GB of available memory for a small testing setup and around 4GB for a mid to large sized installation, on a dual core with 4 threads minimum and a quad core preferred. Those numbers cover the whole stack, and the compose file pins the JVM with ES_JAVA_OPTS=-Xms1g -Xmx1g, so ElasticSearch starts with a 1GB heap and does not claim more on its own. Size that heap yourself once the library outgrows it.
TA_HOST and the initial credentials cannot be changed from the web interface
Six environment variables are required: TA_HOST, TA_USERNAME, TA_PASSWORD, ELASTIC_PASSWORD, REDIS_CON and TZ. TA_HOST is the full URL including protocol and port, http://tubearchivist.local:8000 in the example. TZ is not cosmetic, the README describes it as the scheduler's timezone.
TA_USERNAME and TA_PASSWORD are the initial login credentials.
      - TA_HOST=http://tubearchivist.local:8000  # set your host name with protocol and port
      - TA_USERNAME=tubearchivist           # your initial TA credentials
      - TA_PASSWORD=verysecret              # your initial TA credentials
      - ELASTIC_PASSWORD=verysecret         # set password for Elasticsearch
Both TA_PASSWORD and ELASTIC_PASSWORD accept a _FILE suffix so the value can come from a file instead of an environment variable, a convention the README borrows from ElasticSearch and other images. That matters if your compose file lives in a git repository, because the example ships the literal password verysecret in both slots. The footer of the interface shows the running version.
TA_LOGIN_AUTH_MODE picks one backend, and DISABLE_STATIC_AUTH drops the rest
Authentication has its own switch. TA_LOGIN_AUTH_MODE takes five documented values and the default is single, meaning exactly one backend is live, chosen by whether you set TA_LDAP or TA_ENABLE_AUTH_PROXY. local uses the local password database only, ldap uses LDAP only, forwardauth reads headers from your reverse proxy only, and ldap_local is the one that keeps both.
The mode value decides what happens when the configuration is half done. Under single with TA_LDAP unset, a stale local account still authenticates. Under forwardauth the username arrives in the header named by TA_AUTH_PROXY_USERNAME_HEADER and logout goes to TA_AUTH_PROXY_LOGOUT_URL, so a misconfigured proxy locks you out rather than falling back to a password. Read that table before putting a reverse proxy in front of the instance.
A second decision has a wider blast radius. DISABLE_STATIC_AUTH removes authentication from media files, which the README notes for cases like Google Cast. Turn it on and every file under /youtube is reachable by anything that can reach the port. The README says what the variable does and links to its env var entry, and documents no rate limit or token to compensate, so treat it as a network control decision rather than a convenience toggle.
The bundled ElasticSearch image is amd64 only, and it ships tuned settings you must reapply
The compose file carries its own warning on the image line: bbilly1/tubearchivist-es is only for amd64, or use official es 9.5.5. On an arm64 host, an Apple Silicon machine or an ARM NAS, that comment is the whole of your migration path. You point ES_URL at your own ElasticSearch, http://archivist-es:9200 with the protocol and the port spelled out, and you supply a matching ELASTIC_PASSWORD yourself, because the two containers must agree or the index never opens.
If you substitute the official image, keep the settings the compose file passes to the archivist-es service. discovery.type=single-node is what lets a lone node form a cluster without complaining about replicas, xpack.security.enabled=true is what gives ELASTIC_PASSWORD meaning, and path.repo is what allows snapshots at all. ELASTIC_USER changes the default ElasticSearch user, and ES_DISABLE_VERIFY_SSL turns off certificate verification between the two containers, which is a plain text warning that you are trading verification for a connection that works.
If you start on the bundled image and later move to the official one, budget for a reindex from the start instead of assuming the index travels with you. The Dockerfile also fetches ffmpeg and ffprobe per target platform through docker_assets/ffmpeg_download.py, so image builds follow the same per architecture split.
Bring the stack up and wait on the health endpoint before you subscribe
The install path the README describes is Docker, with separate community instructions linked for Unraid, Synology and Podman. Copy the example docker-compose.yml, set TA_HOST to the URL you will type into the browser, set TZ, and bring the stack up with your Docker Compose tool. The compose file names the images and volume mounts for you, so an install that diverges from the example usually diverges on those six required variables.
The tubearchivist service carries its own healthcheck, which tells you what a healthy instance answers to before you go looking for it in a browser:
    healthcheck:
      test: ["CMD", "curl", "-f", "http://localhost:8000/api/health/"]
      interval: 2m
      timeout: 10s
      retries: 3
      start_period: 30s
Check the same endpoint by hand with curl -f http://localhost:8000/api/health/ and a non-zero exit means the backend is not answering. Once it answers, the loop is the one the project describes: subscribe to channels, download with yt-dlp, let the indexer make the results searchable, then play them and mark them viewed. The companion browser extension covers Firefox and Chrome, and separate plugins hand the library to Jellyfin and Plex, so playback does not have to stay inside the bundled interface. Set TA_AUTO_UPDATE_YTDLP to have the container install the latest yt-dlp on start.
Port 8000 collides, and the healthcheck still points at the old port
The README gives port collisions their own section, and the compose file publishes 8000:8000 with no host side override. The documented override is TA_PORT, which overwrites the Nginx port. It is not reflected in the healthcheck, which is hardcoded to http://localhost:8000/api/health/, so if you change TA_PORT, update the probe as well.
Two of the three services avoid that problem on purpose. archivist-redis declares 6379 with expose rather than ports, so it stays inside the compose network and cannot collide with a host service, and archivist-es publishes no host port at all in the example because you reach it through ES_URL on the internal network name. Publishing every service to the host is what turns a homelab into the collision case the README warns about.
Upgrade cost is the ElasticSearch volume, and the release cadence is uneven
Updates run through Docker images, and the README's rule is to use the latest tag, which is the default, or a named semantic version tag. Unstable tags sit behind the beta testing section of CONTRIBUTING.md, which is a separate opt-in. The version number in the interface footer is how you confirm what is running, backed by a daily version check. Pin a version tag if you would rather know what changed than find out on a schedule.
The release history shows how uneven that cadence is. v0.6.0 shipped on 2026-10-25, two months after v0.5.12 on 2026-08-25, which came ten days after v0.5.11 on 2026-08-15. The repository is not archived and the last push was on 2026-10-25. The README says the project is tested for updates between one or two releases maximum, so plan around that: the index is your data and the compose file documents no rollback step for a bad upgrade.
Two costs sit outside the upgrade itself. Replacing the index means a full reindex rather than a container restart, because the search metadata lives in the ElasticSearch volume. And the base images are pinned hard in the Dockerfile, python:3.14.8-slim-trixie for the builder and the final stage, node:24.22.1-alpine for the frontend build that runs npm run build:deploy. Nothing in that file is exposed as a variable you are meant to change.
Where a yt-dlp script and TubeSync differ from a live index
The honest comparison is about where the index lives, not about download quality. A yt-dlp script plus cron puts files on disk in folders and nothing else: no index, no search, no viewed state, and metadata re-derived every time you want it. Tube Archivist keeps the ElasticSearch index as the way you find a video, and that index is exactly what you lose the moment archivist-es goes away.
TubeSync comes from the Plex side of the ecosystem and works in the opposite direction. It pulls channel subscriptions into a library directory that a Plex or Jellyfin server scans, so browsing comes from the media server's own metadata agent rather than a separate search database. You get a library, not a search layer, which is the axis the two projects genuinely differ on.
Neither approach removes the yt-dlp dependency. Both sit downstream of a downloader YouTube can break, which is why TA_AUTO_UPDATE_YTDLP exists at all: that breakage is a recurring maintenance event, not a one-time setup cost.
Editorial conclusion
Adopt Tube Archivist if you already run Docker and want subscription indexing, viewed state and offline search over a YouTube backlog, and skip it if you only want files on a disk or you cannot spare the memory and the separate ElasticSearch volume. Before moving a live library across, check your CPU architecture first, because the bundled bbilly1/tubearchivist-es image is amd64 only and swapping in the official es 9.5.5 image is a step you take once, at install time.
Frequently asked questions
What is Tube Archivist?
It is a self hosted YouTube media server that subscribes to channels, downloads videos with yt-dlp, indexes them with YouTube metadata and plays them from a web interface. Because the search index lives in ElasticSearch alongside a Redis container, it runs as a Docker Compose stack rather than a single binary.
How do I install Tube Archivist?
Docker is the requirement. Copy the example docker-compose.yml, set the six required variables including TA_HOST, TA_USERNAME, TA_PASSWORD, ELASTIC_PASSWORD, REDIS_CON and TZ, then start the stack and wait for http://localhost:8000/api/health/ to answer. Separate instructions are linked for Unraid, Synology and Podman.
How do I use Tube Archivist day to day?
Subscribe to channels, download with yt-dlp, let the indexer make results searchable, then play videos and keep track of viewed and unviewed ones. A companion extension exists for Firefox and Chrome, and plugins pass the library to Jellyfin and Plex.
How do I update Tube Archivist?
Use the latest Docker tag, which is the default, or pin a named semantic version tag, and confirm what is running from the version number in the interface footer, which is backed by a daily version check. Unstable tags are documented separately in the beta testing section of CONTRIBUTING.md.
Is Tube Archivist safe to run on a network?
It is licensed GPL-3.0 and requires Docker. The security-relevant decisions are yours and each has a documented variable: DISABLE_STATIC_AUTH removes authentication from media files, TA_ENABLE_AUTH_PROXY with TA_AUTH_PROXY_USERNAME_HEADER delegates login to a reverse proxy, and ES_DISABLE_VERIFY_SSL turns off ElasticSearch certificate verification.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/tubearchivist-tubearchivist)Star history chart for your README
[](https://hysenlabs.com/projects/tubearchivist-tubearchivist)Was this useful?