Chipyard: four hardware flows, and most of the cores live in other repositories
An Agile RISC-V SoC Design Framework with in-order cores, out-of-order cores, accelerators, and more
At a glance
- What is it?
- ucb-bar/chipyard is a Berkeley framework for building RISC-V systems on chip with Chisel. Its readme is a signpost and a citation list: two of the three cores it names, both vector units and the workload generator are separate projects, the release titles use three different naming patterns, and the tree carries a second licence file named after a company.
- Who is it for?
- Chipyard fits a hardware team that wants a SoC generator plus simulation, physical design and workload generation under one repository rather than four, and that reads the academic output of its own components. It does not fit someone who wants a single self-contained design: the cores, the vector units and the workload generator are separate projects with their own release cycles, and the readme will not tell you which version of each a given Chipyard release expects.
- Can I use it commercially?
- Yes. BSD-3-Clause is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 5 days ago.
- What is it written in?
- Mainly Scala, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
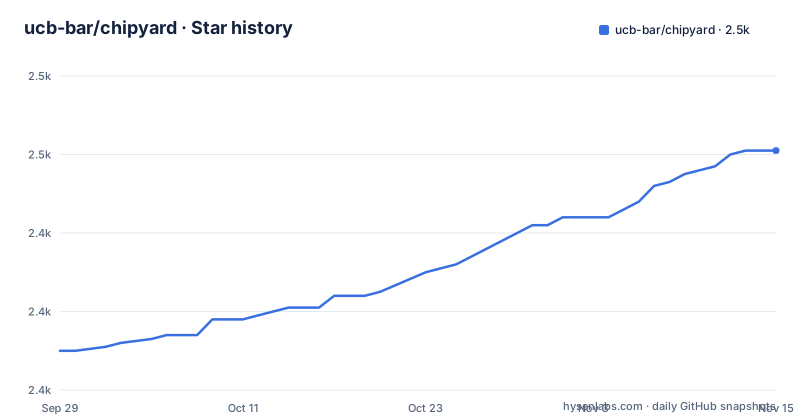
- ucb-bar/chipyard2,461 ★ · +51
| Repository | 2026-09-29 | 2026-11-15 |
|---|---|---|
| ucb-bar/chipyard | 2.4k | 2.5k |
51 Stars in the last 47 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The readme is a signpost and a citation list
The entry point for Chipyard is short. The section on using it is one sentence pointing at the documentation site, and the documentation site is where the setup, the configuration and the current versions live. Around that sit three quick links: latest documentation, a user question forum on a Google group, and the issue tracker for bugs and feature requests. The resources section adds a tutorial that covers Chipyard together with its simulation tool, hosted on that tool's own domain, and a set of slides called Chipyard Basics, which are an ASPLOS conference deck hosted on the same third party domain. So the parts of the readme that are really the project are a statement of what Chipyard is, a help section that repeats the forum and the tracker, a contributing line pointing at one file, and an acknowledgements line naming a single National Science Foundation award number. If you want to know how to configure a core, the answer is not here.
Most of what the readme says it contains lives in other repositories
Read the component list as if you were cloning all of it, and you would clone the wrong thing. The processor cores it names are Rocket Chip, BOOM and CVA6, also known as Ariane, and each of those links out to a different organisation's repository rather than to a directory inside this tree. The vector units, Saturn and Ara, are the same story: Saturn is linked inside this research group's namespace and Ara is linked to a different platform organisation. The workload generator for bare-metal and Linux systems is a separate project again. Of everything named as contents, the accelerator listed with an in-group link is Gemmini, the second vector unit is Saturn, and the third accelerator, NVDLA, is linked by a plain http address while every other link in that block uses https, as do the documentation links, so the odd one out is not accidental-looking so much as forgotten. The pattern is coherent rather than broken. Chipyard is an integration framework, and its readme is mostly a manifest of what it integrates.
Four concurrent flows, and a tree that mirrors them
The project's claim is that it supports several concurrent flows of hardware development at once, and the directory names at the root are the evidence. Software RTL simulation, FPGA-accelerated simulation through the simulator that shares its name, automated physical design flows, and workload generation for bare-metal and Linux targets each have their own top level area, alongside a generators directory, a tools directory, a software directory, a toolchains directory, a dockerfiles directory and a conda requirements directory. The build is assembled from several files rather than one: a Scala build definition, a setup shell script, a common make fragment, a variables fragment, and a large set of tests. Two automation details are visible too: a merge automation configuration for handling pull requests, and a read the docs configuration. And two ignore files that exist to keep generated output out of version control, plus a ctags configuration, a git attributes file, a git submodules file and a commit hooks directory.
Three release title patterns and a two year gap
The version numbers follow a clean minor scheme and the release titles do not follow any scheme at all. The oldest of the three visible releases is 1.12.3, titled as a minor release. The next is 1.13.0, titled with the project name and the number and nothing else. The newest is 1.14.0, titled as a release. So the same repository has shipped releases called three different things, and a script that tried to parse those titles would have to handle all three. The dates matter more than the titles. Version 1.13.0 was published in September 2024 and version 1.14.0 in June 2026, a gap of about twenty one months, while the branch's last recorded push is 2026-09-30, roughly three months after the newer release. A framework whose components live in other repositories is exactly the kind of project where a long gap between releases accumulates component version bumps that are documented in the docs rather than in the tag name.
Hammer is cited twice, and the physical design list is the shortest
The longest section of the readme is a publication list, and its shape is a map of the project. It is grouped by component kind rather than by year: generators first, with a technical report for the Rocket Chip generator, a Hot Chips paper for BOOM, a conference paper for the third generation of BOOM, another for its branch prediction work, and one for the accelerator. Then simulators, which is the largest group with six entries including the FPGA work and a retrospective. Then tools, four entries covering the hardware description language, its intermediate representation, an extension, and the workload generator. Then physical design, which has two entries, and both of them are named Hammer with different first authors and different venues. So one tool gets two citations under the same label while the physical design flow as a whole is the least documented part of the framework, which is a useful thing to know before you plan a tape-out.
Two licence files, one of them named after a company
The repository record reports a BSD three clause licence, and the root contains a licence file that matches. It also contains a second licence file whose name ends with the name of a commercial chip company. That is not automatically a problem, and in a project of this lineage it is explicable, since one of the processor cores descends from work done at that company and some subtrees can carry different terms from the surrounding repository. What matters is that the readme does not explain the split, so a reader has to work out for themselves which terms govern which directory. The same pattern shows up in the project links: several components are external repositories with their own licences and their own release schedules, which means the effective licensing of a Chipyard based design is a question about several repositories at once rather than one file at the root. If that matters to you, ask before you synthesise anything.
A temporary Java directory is committed at the root
Small repository details are worth listing because they tell you how the build behaves. There is a directory at the root whose name says it is a temporary Java directory, committed to version control, which is almost always a byproduct of running a Scala build with a Java toolchain in the working directory. Alongside it are three separate ignore files doing three different jobs: one tells continuous integration what to ignore, one tells the tag indexer what to ignore, and the git ignore does the rest. There is also a changes file, a contributing file and a documentation directory, which is where the readme's own advice points: for the most up to date details, users are told to refer to the documentation rather than to the publications listed above, because those describe internal components as they were rather than as they are. That sentence is the most important one in the attribution section, and it is easy to skim past.
Editorial conclusion
Chipyard fits a hardware team that wants a SoC generator plus simulation, physical design and workload generation under one repository rather than four, and that reads the academic output of its own components. It does not fit someone who wants a single self-contained design: the cores, the vector units and the workload generator are separate projects with their own release cycles, and the readme will not tell you which version of each a given Chipyard release expects. Before you build on it, check four things. Which component versions belong together, since that mapping is in the documentation rather than in the repository. Which licences apply where, because the root carries a second licence file named after a company alongside the BSD one. What the build actually needs, since the tree assembles it from a Scala build definition, two make fragments, a setup script and a conda requirements directory. And how you cite your work, because the readme makes citation a condition of research use.
Frequently asked questions
What is a chipyard?
Chipyard is an open source framework for the agile development of Chisel based systems on chip, produced with the Chisel hardware description language, the Rocket Chip SoC generator and other Berkeley projects, to build RISC-V systems from memory mapped peripherals through to custom accelerators. It is developed in the Berkeley Architecture Research Group and is BSD-3-Clause licensed.
what is chipyard
It is a framework that assembles existing open source components into a complete system on chip: processor cores such as Rocket, BOOM and CVA6, vector units, accelerators including Gemmini and NVDLA, memory systems and peripherals. It also supports four concurrent flows, software RTL simulation, FPGA-accelerated simulation, automated physical design flows, and workload generation.
how to use chipyard
The readme points at the project's documentation site for anything beyond an overview, and the short version is that you describe the system you want in Chisel, pick the cores and accelerators, and run it through the flows the framework provides. Help is offered through a user question forum on a mailing list and through the issue tracker.
how to install chipyard
The readme itself contains no install command and sends you to the documentation site. What the repository does carry is the build material: a Scala build definition, a build setup script, a common make fragment, a variables fragment, a dockerfiles directory and a conda requirements directory, with toolchains in their own top level directory.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/ucb-bar-chipyard)Star history chart for your README
[](https://hysenlabs.com/projects/ucb-bar-chipyard)Was this useful?