UCCL states two collective speedups and leaves the other comparisons empty
UCCL is an efficient communication library for GPUs, covering collectives, P2P (e.g., KV cache transfer, RL weight transfer), and EP (e.g., GPU-driven)
At a glance
- What is it?
- UCCL is a C++ communication library for GPUs with three components built from one source tree: a collective layer that aims to replace NCCL or RCCL, a point to point transfer API, and an expert parallelism path. The two headline multipliers for AllReduce are written out in prose; the comparison panels for the other two components carry a caption and nothing else.
- Who is it for?
- UCCL is worth reading for anyone running NCCL, RCCL or DeepEP across mixed NIC fleets, but two things have to be settled before it goes anywhere near a training job. First, the evidence in the README covers the collective component only: the AllReduce multipliers come with their hardware named, while the P2P and EP comparison panels hold a caption line and no rows, so anyone expecting numbers for KV cache transfer or EP32 dispatch has to get them elsewhere.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 1 day ago.
- What is it written in?
- Mainly C++, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
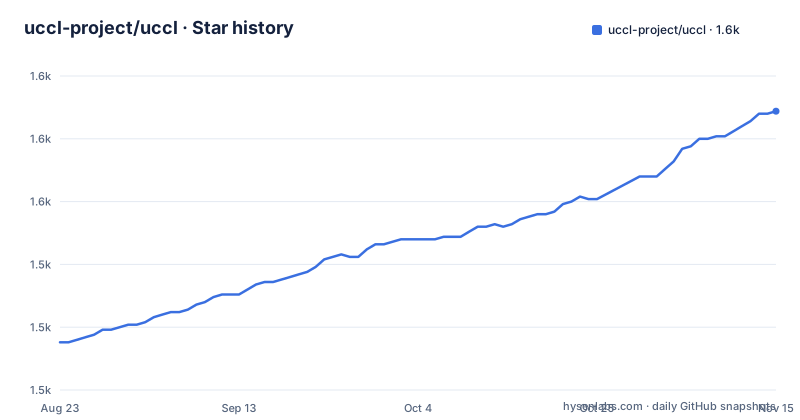
- uccl-project/uccl1,586 ★ · +92
| Repository | 2026-08-23 | 2026-11-15 |
|---|---|---|
| uccl-project/uccl | 1.5k | 1.6k |
92 Stars in the last 84 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
Two speedups in prose, three comparison panels with no rows
Only the collective component has numbers written as text. On six HGX servers spread across two racks, each with 8x400G CX-7 RoCE NICs and 8xH100 GPUs, UCCL-collective beats NCCL by up to 2.5x for AllReduce. On two AWS g4dn.8xlarge instances with 1x50G ENA NICs and 1xT4 GPUs inside the same cluster placement group, the same claim reads up to 3.7x. Both numbers are qualified with up to, and both are attached to a specific machine list rather than a range of workloads. The other two components get the same treatment in the page layout and none of it in the text. The UCCL-P2P panel is headed Message transfer bandwidth over RDMA on AMD MI300X + Broadcom Thor-2 and carries no rows under that line. The UCCL-EP panel is headed EP32 dispatch and combine on AWS p5en (8x H200 + 16x 200Gb/s EFA) and is empty in the same way. Hardware is named for both; results are not.
Three components, one package, variant encoded in the filename
The repository holds collective/, p2p/ and ep/ as separate component directories, and setup.py ships all of them inside a single package named uccl, the arrangement described in its own comments as vLLM-style. What separates one build from another is not a second package but a local version identifier in the wheel filename, with uccl-0.1.0+cu13 and uccl-0.1.0+cu12.efa given as the examples. Distribution follows the same split: the default cu12 build carries no local version and is published to PyPI, while every other variant is handed out through GitHub Releases, which means a CUDA 13 or ROCm user downloads a file rather than naming a package. The build script matches that shape with two argument positions, a platform of cu12, cu13, roc7, roc6 or therock, and a component of all, ccl_rdma, ccl_efa, p2p or ep. The rest of the tree, including experimental/, thirdparty/, docker/, scripts/, docs/ and examples/, is shared rather than per component.
requires-python 3.12 next to a build script that takes a py_version
The manifest sets requires-python to >=3.12, and the packaging code goes further by keying off the interpreter in two ways. In setup.py, limited API use is decided by not freethreaded and sys.version_info at or above 3, 12, which then defines Py_LIMITED_API as 0x030C0000 for an extension named uccl._platform_tag_stub. The comments say that stub still exists on older interpreters to force a platform-specific wheel tag, without the limited API flag, so a CPython-version-specific wheel comes out instead. The build script agrees with that older path: it detects the py_version of the current environment by itself, and the quick start says to pass one explicitly when you need to target a specific version, with 3.10 as the worked example. So the machinery supports interpreters the manifest forbids, and the documented example is one of them. Binding work runs through nanobind, with cp312-abi3 tags on 3.12 and later.
The ROCm wheel in the documentation lives in a local wheelhouse
Building for ROCm through TheRock means passing the index url yourself, because the default points at https://rocm.prereleases.amd.com/whl/gfx94X-dcgpu and the documentation warns it may not be the one you want. The install example it gives is long enough to hide the detail that matters:
pip install --extra-index-url https://rocm.prereleases.amd.com/whl/gfx94X-dcgpu wheelhouse-therock/uccl-0.0.1.post4-py3-none-manylinux_2_27_x86_64.manylinux_2_28_x86_64.whl[rocm]The path prefix is a directory on the machine that ran the build, not a download location, and the version in it, 0.0.1.post4, sits behind both published tags, v0.0.1.post6 from 2026-03-14 and v0.1.1 from 2026-05-10, and behind the 0.1.1 in pyproject.toml. The trailing [rocm] extra is also optional by design, declared in the manifest as an empty list. A reader copying that line from a release download has to change both the directory and the filename.
The quick start clone skips the submodules the dev guide asks for
There are two documented entry points and they do not agree on the first step. The quick start for users is a clone and a build:
# Eg, bash build.sh cu12 ep --install
bash build.sh [cu12|cu13|roc7|roc6|therock] [all|ccl_rdma|ccl_efa|p2p|ep] \
              [py_version] [rocm_index_url] --install
The developer path instead says to clone the repository and init submodules, and then exports UCCL_HOME as the clone directory relative to wherever the clone landed. The repository does carry a .gitmodules file and a thirdparty/ directory, so the submodule step is not decorative, yet the clone line in the quick start has no submodule init and never sets UCCL_HOME. Defaults are documented inline as well: cu12 targets CUDA 12.8, roc7 targets ROCm 7.1, and cu13 and roc6 are the opt-ins for CUDA 13.0 and ROCm 6.4.
Two environment variables, and which one depends on your NIC family
Installation does not wire the library into PyTorch by itself. What the project asks for is that the plugin path be resolved from the installed package and exported before the training run starts:
NCCL_NET_PLUGIN=`python -c "import uccl; print(uccl.nccl_plugin_path())"`

LD_PRELOAD=`python -c "import uccl; print(uccl.efa_nccl_path())"`
NCCL_NET_PLUGIN=`python -c "import uccl; print(uccl.efa_plugin_path())"`
The NCCL line is for IB or RoCE on x86 or GH200 ARM hosts, the RCCL function covers IB or RoCE on x86, and the EFA pair is different in kind: it needs both LD_PRELOAD and NCCL_NET_PLUGIN, and the comment limits it to p4d and p4de instances. That is consistent with the collective component's claim of working as a drop-in replacement for NCCL or RCCL without changes to application code, since only environment variables move. It is also consistent with how the wheel is chosen, because the cu12 build is the one a pip command can name and the rest arrive as files.
Packet spraying by software, and the boxes still empty on the roadmap
The stated reason for rewriting the transport is congestion. The project argues that existing transports use one or a few paths to stream large volumes and are therefore exposed to a single point of congestion in a datacenter network, and that it sprays packets in software across many paths instead. The listed benefits are 256 paths, congestion control that is latency-based and receiver-driven, loss recovery by selective repeat, and use in public clouds with legacy NICs and plain Ethernet, all behind NCCL APIs. The technical report is arxiv 2504.17307, and UCCL has been taken into AMD's TheRock ecosystem. The roadmap marks its checkboxes honestly in both directions: KV cache transfer, expert parallelism, AMD GPU support and flow control are done, consumer parts on 4090, 5090 and GB10 are in progress, while support for other accelerators such as TPUs and Trainium and device kernels in a vendor-agnostic Triton language are both still empty.
Editorial conclusion
UCCL is worth reading for anyone running NCCL, RCCL or DeepEP across mixed NIC fleets, but two things have to be settled before it goes anywhere near a training job. First, the evidence in the README covers the collective component only: the AllReduce multipliers come with their hardware named, while the P2P and EP comparison panels hold a caption line and no rows, so anyone expecting numbers for KV cache transfer or EP32 dispatch has to get them elsewhere. Second, check the packaging against your interpreter and your platform, because the manifest asks for Python 3.12 while the build script still takes a py_version argument, and the ROCm instructions point at a wheelhouse directory that only exists on a machine that built the project itself. The tree carries Apache-2.0 with a LICENSE file at the root, the latest release tag is v0.1.1 from 2026-05-10, and the last commit on main is dated 2026-09-28.
Frequently asked questions
What is UCCL used for?
UCCL is a communication library for GPUs with three components: a collective layer intended as a drop-in replacement for NCCL or RCCL, a point to point API in the NIXL style of initiator and target transfers, and an expert parallelism component that runs DeepEP over AMD and Nvidia GPUs with RDMA NICs such as AWS EFA and Broadcom parts.
How do you install and activate UCCL for PyTorch?
Build it with build.sh for your platform and component, then export the plugin path that the installed package reports. NCCL over IB or RoCE uses NCCL_NET_PLUGIN set from uccl.nccl_plugin_path(), RCCL uses uccl.rccl_plugin_path(), and AWS EFA needs LD_PRELOAD from uccl.efa_nccl_path() alongside NCCL_NET_PLUGIN, limited to p4d and p4de instances.
Why does the UCCL wheel filename carry a plus and a dot?
All backends ship in one package named uccl, and variants are distinguished by PEP 440 local version identifiers in the filename, with uccl-0.1.0+cu13 and uccl-0.1.0+cu12.efa as the given examples. The default cu12 build has no local version and is on PyPI, while other variants are distributed through GitHub Releases.
What Python versions does UCCL support?
pyproject.toml requires Python 3.12 or later, and on 3.12 and later the wheels are tagged cp312-abi3 against the stable ABI so one wheel covers every newer interpreter. setup.py still carries a path that produces CPython-version-specific wheels on older interpreters, and the build script accepts a py_version argument with 3.10 given as the example.
Which UCCL performance figures are actually given?
Two, both for UCCL-collective and AllReduce: up to 2.5x over NCCL on six HGX servers across two racks with 8x400G CX-7 RoCE NICs and 8xH100 GPUs, and up to 3.7x on two AWS g4dn.8xlarge instances with 1x50G ENA NICs and 1xT4 GPUs. The P2P and EP panels name their hardware but show no results.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/uccl-project-uccl)Star history chart for your README
[](https://hysenlabs.com/projects/uccl-project-uccl)Was this useful?