VedAstro's readme hides its two best demos in HTML comments and calls itself 9 years old
A non-profit, open source project to make Vedic Astrology easily available to all.
At a glance
- What is it?
- A non-profit C# toolkit for computing Vedic astrology charts, shipping as a NuGet library, a PyPI package, a Docker image and a hosted API. The engineering is a 17-project solution; the readme dates itself from before the code was written.
- Who is it for?
- Read VedAstro as a piece of software and not as evidence for anything. What it is: a large, long-lived, permissively licensed computation library with a hosted API, a package for three ecosystems and an MCP server, all built from one solution with tests beside the code.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 42 days ago.
- What is it written in?
- Mainly C#, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 15, 2026, and from our analysis. They are not legal advice.
Star history
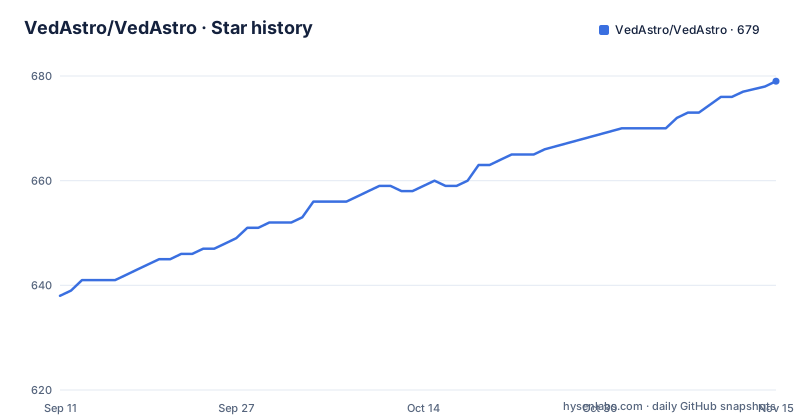
- VedAstro/VedAstro679 ★ · +41
| Repository | 2026-09-11 | 2026-11-15 |
|---|---|---|
| VedAstro/VedAstro | 638 | 679 |
41 Stars in the last 65 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
The two demonstration sections are wrapped in HTML comments
The most impressive material in this readme does not render.
There are two large HTML comment blocks. The first is headed with a count of API calls and is meant to show a sample response for a named planet on a given date at a given place. Inside it is a link to a live demo call and a JSON payload whose keys are things like the Swiss ephemeris values, several strength measures, whether the body is benefic or malefic, its declination, its nodal and sign-related values. The payload stops partway through a key.
So the block is commented out and the JSON inside it is cut off mid-field. The complete portion of the payload looks like this, and it is the shape every endpoint returns:
"AbdaBala": "0",
"AspectedByMalefics": "False",
"AyanaBala": "118.071100045034",
"Benefic": "False",
"ChestaBala": "0",
"ConjunctWithMalefics": "True",
"Constellation": "Aridra - 3",
"Debilitated": "False",
"Declination": "23.2284400180136",
"DigBala": "5.222314814814815",
"Drekkana": "Libra",
"DrekkanaBala": "0",
The second block is headed as examples of accurate predictions. It describes a life-event calculator applied to the charts of two named historical figures, states that every major event in their lives can be seen predicted in a summary row, and attributes the result to a combination of four period divisions across nine planets. It also warns that generating the chart takes a lot of computational power.
Also commented out. Also not visible to anyone reading the project page.
What a visitor to the repository actually sees is a list of links and a paragraph about a sage who taught astrology without asking for money. The evidence sections exist in the source and are not part of the rendered readme, which is a documentation decision rather than a claim, but it does mean the rendered page carries none of the demonstration.
The readme says nine years old, and that the first line was written in late 2014
Two numbers in the same section disagree, and one of them is a heading.
The heading says nine years old. The paragraph underneath says the first line of code was written in late 2014, in Itä-Pasila, starting as a desktop program with no interface and text output only.
Late 2014 plus nine years lands in 2023. If the page is being read now, the age implied by its own start date is closer to eleven or twelve.
A stale age heading is small. It matters more because of what else is missing.
The repository has no GitHub releases at all. Not one tag, according to the release history. Meanwhile the project distributes itself through a package on NuGet, a package on PyPI, a Docker image on a registry, a hosted REST API, a WordPress plugin, mobile clients for two platforms, a hosted model context protocol server, and a hosted website with a dozen interactive pages.
So there are at least four independent distribution channels and a decade of development, and no release history on the platform most people would look at first. Nothing in the readme explains where a given deployment came from or when it was cut.
A seventeen-project solution, with the scraper and the data migration in it
The repository root is a solution file and seventeen project directories.
The projects visible in the tree are a library, a test project, the API, an API tester, a console program, a desktop program, the website, a mobile website, a publisher, a web scraper, a match-related machine learning pipeline, a geolocation data migration, a documentation-to-embeddings tool, a static table generator, a HuggingFace helper, a package publisher, a directory named only as other things, and one named for code generation.
That last one is never mentioned anywhere in the readme. Neither is the scraper, the migration, the table generator or the embeddings tool.
So the data-collection and data-preparation tooling lives in the same solution as the astronomical calculation library. For a project whose stated origin is a person teaching astrology without charging for it, that is a choice worth naming: the harvesting of biographical data is part of the same build as the maths.
Two root files are also worth noting. Alongside the solution file there is a settings file for a specific .NET editor, committed at the root rather than under a configuration directory. And there is a registry manifest for the model context protocol listing, consistent with the MCP server the readme advertises.
The default branch is master, not main, and most of the project's own documentation links are written against that branch name.
A C# library, a NuGet package and a PyPI package with the same name
The primary language of this repository is C#, and the calculation library is .NET code.
The distribution story is broader than that. There is a package on NuGet for the library, a package on PyPI under the same product name that the readme tells you to install with pip, a Docker image for self-hosting the whole API stack, and a WordPress plugin plus mobile clients for the hosted version.
The readme also offers two entry points aimed at developers who want the algorithm rather than the service. One points into the calculation logic directory and describes it as a way to learn the exact maths. The other points at the library as a whole and describes importing the code directly into an existing project.
For a Python developer the interesting consequence is that the source of truth for the maths is C#. A pip install gives you a binding, and the readme's own pointer to how the computation works is a .NET source tree. Anyone evaluating whether the implementation is correct has to read C# regardless of which package they use.
The API surface is described as two hundred or more calculation endpoints, with a browser-based builder for constructing calls, and the MCP server exposes the same family of operations to agents.
That is a lot of surface area for a library whose correctness is a question of convention rather than of measurement, which makes the open source pointer the most load-bearing part of the readme.
Thirteen tools, including one that forecasts earthquakes
The user-facing list runs to thirteen hosted pages, and one of them is unlike the rest.
Most are chart computations. A full birth chart with a hundred or more Vedic predictions and divisional charts. A horoscope page. A match checker offering marriage compatibility through ten classical methods, and a separate page to find the most compatible partner from a list. A horary page that takes a question and answers it through the question-answering branch of the tradition. A numerology page using a specific shastra for names. A birth time finder for rectifying unknown or uncertain times. A journal page that maps logged life events against your chart.
Two more are live-data pages: current planetary positions and the daily almanac.
One is an earthquake predictor, and the readme labels it experimental astrological seismic forecasts. That label matters. It is the only page in the list whose output would be acted on by people other than the person who generated it, and the word experimental is doing all of the work of the disclaimer.
Two are model-driven rather than deterministic: an astrological chatbot described as the first open source one of its kind, and a dream interpreter.
Counting them, thirteen pages against a claim of two hundred calculation endpoints underneath. The endpoints are the product; the pages are thirteen ways in.
Two research datasets about fifteen thousand named people
Under a heading for machine learning and research, the project publishes two datasets on a model hub.
One is fifteen thousand famous people with their birth date, time and location. The other is fifteen thousand famous people with their marriage and divorce information.
These are the items in the repository that deserve the most care, and not because of any technical problem. They are structured biographical data about fifteen thousand identifiable individuals, assembled by the scraper project that sits in the same solution, and published for training.
Birth times in particular are not the sort of field people choose to share and not the sort of field a subject can meaningfully consent to in advance if they did. And the second dataset turns relationship history into a training signal.
The readme describes both as curated and does not say how the individuals were selected, whether any were asked, or what the selection criteria were. No licence, terms or takedown route appears in the visible material for either dataset.
For a project whose stated ethic is that knowledge should be free to all, the asymmetry is worth sitting with. The astrology is given away; the people are collected.
The development model is described as chaotic, as a deliberate choice
There is a section naming a development pattern, and it is not a software one.
It is called the Gonzo development pattern, described as celebrating the methodology of chaotic development for the benefit of low cost and fast paced prototyping, and inspired by Gonzo journalism as pioneered by one writer in the 1970s. The stated reason for choosing it is the volatile nature of this project.
The section also concedes that other patterns are equally good when the need is, naming waterfall and scrum. So the claim is not that the project has a process but that it does not want one.
Then the readme lists what the project wants to do, and the list is cut off partway through its first item, at a fragment about trying out novel ideas.
Set against the rest of the repository, the model reads as consistent rather than chaotic. There are tests in a project beside the library, a publisher for packages, a static table generator, an API tester, a solution file and editor settings. Whatever is not specified, the structure is not.
It is also a nine-year-old non-profit project with 652 stars, 287 forks and 21 open issues, and a pattern chosen for low cost and fast prototyping is a defensible way to run something at that scale with volunteer labour.
The MCP server is the newest surface and the only one with registry metadata
Among the developer-facing entries, one is newer than the rest and shaped differently.
The model context protocol server is hosted on its own subdomain, documented in a document inside the repository rather than only on the site, and described as working with three named clients plus any other MCP client. Its documentation lives in a file under the docs directory, which is the only developer entry in the list that points at a document in the repo.
The corresponding registry metadata is the manifest at the repository root. Having that file means the server can be listed in a protocol registry, which is how a hosted tool becomes discoverable by agents without anyone configuring it by hand.
The rest of the developer entries are distribution channels: packages, a container, plugins, clients. The MCP server is the only one that is an interface for a model rather than for an application.
That is a meaningful shift for a project of this kind. The computation library was always going to be a library. Wrapping it so an agent can call it changes who the caller is, and it moves the correctness question from a reviewer's problem to a prompt's problem: a model decides which endpoint to call, and the documentation has to make the right call the obvious one.
The readme does not say how that is handled. Whether the readme says how anything is handled is a separate question, and the one that actually constrains what this project is.
Editorial conclusion
Read VedAstro as a piece of software and not as evidence for anything. What it is: a large, long-lived, permissively licensed computation library with a hosted API, a package for three ecosystems and an MCP server, all built from one solution with tests beside the code. What it is not: a validated predictor. The readme's own demonstration of that is commented out and truncated, so before you build anything on it, decide whether you want an astrological calculation engine or an evidence-backed one, and read the compute directory rather than the marketing pages.
Frequently asked questions
What does VedAstro compute?
It is a C# library and hosted API for Vedic astrology, described as two hundred or more calculation endpoints covering birth charts, divisional charts, planetary positions, compatibility by ten classical methods, horary questions, numerology and birth-time rectification. The maths lives in .NET source under the library directory.
How do I install VedAstro?
As a package on NuGet for the .NET library, as a PyPI package installed with pip, or as a Docker image for self-hosting the full API stack. There is also a hosted REST API with a browser-based call builder, a WordPress plugin, mobile clients and a hosted MCP server.
Does VedAstro have any GitHub releases?
None. The repository has no GitHub releases despite roughly a decade of development and at least four independent distribution channels. Nothing in the readme explains where a deployed version came from or when it was cut.
What datasets does VedAstro publish for machine learning?
Two on a model hub, each covering fifteen thousand famous people: one with birth date, time and location, and one with marriage and divorce information. The readme describes them as curated and does not say how the individuals were selected or whether any were asked.
Does VedAstro predict earthquakes?
It publishes a page the readme labels experimental astrological seismic forecasts. It is the only one of thirteen hosted pages whose output other people might act on, and the experimental label is the whole of the disclaimer.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vedastro-vedastro)Star history chart for your README
[](https://hysenlabs.com/projects/vedastro-vedastro)Was this useful?