One agent, three names, and a sandbox pool that only allows read commands
Open source file-system and knowledge based agent template. Build AI agents that stay up to date with your knowledge base
At a glance
- What is it?
- The Knowledge Agent Template is a Vercel Labs starter for building an agent that searches a knowledge base by running grep, find and cat inside sandboxed machines, with no vector database and no embeddings. What the repository documents is a set of specific choices: three different names for the same project, two startup figures for a pooled sandbox, a command policy that permits reads and nothing else, an admin agent with a run_sql tool, and an SDK sample that reads two environment variables the setup instructions do not list.
- Who is it for?
- This template is worth reading if you want an agent whose answers can be traced to files, since the search surface is a shell rather than a similarity index, and the tool visualisation shows which files were read and how long each step took. Four things to check before you build on it.
- Can I use it commercially?
- Yes. MIT is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository last received commits 3 days ago.
- What is it written in?
- Mainly TypeScript, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
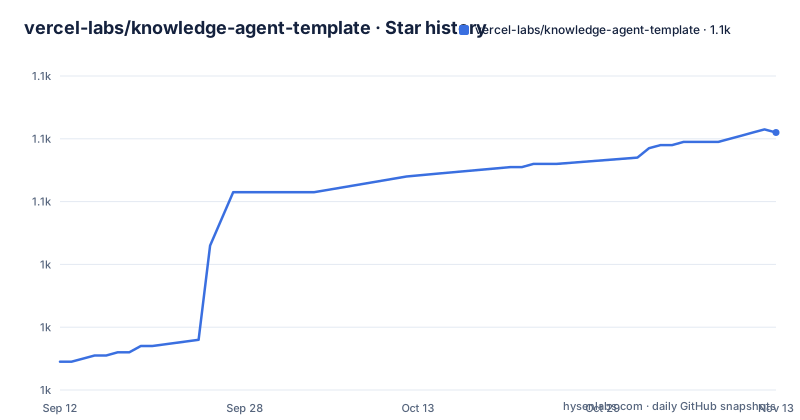
- vercel-labs/knowledge-agent-template1,082 ★ · +73
| Repository | 2026-09-12 | 2026-11-13 |
|---|---|---|
| vercel-labs/knowledge-agent-template | 1k | 1.1k |
73 Stars in the last 62 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
grep, find and cat replace the vector store
The retrieval decision is the template's main argument. There is no vector database, no chunking pipeline, and no embedding model. Agents run `grep`, `find`, and `cat` inside isolated sandboxes to search across the configured sources, and the claim for that approach is that results are deterministic, explainable, and instant, with no infrastructure overhead. Sources can be GitHub repositories, YouTube transcripts, or custom APIs, and `search` spans all of them, so the unit of retrieval is a file rather than a chunk with an embedding attached.
The SDK turns that into two tools for an agent that speaks the AI SDK:
import { generateText } from 'ai'
import { createSavoir } from '@savoir/sdk'

const savoir = createSavoir({
  apiUrl: process.env.SAVOIR_API_URL!,
  apiKey: process.env.SAVOIR_API_KEY,
})

const { text } = await generateText({
  model: yourModel, // any AI SDK compatible model
  tools: savoir.tools, // bash and bash_batch tools
  maxSteps: 10,
  prompt: 'How do I configure authentication?',
})

console.log(text)
The tool surface is a shell, `bash` and `bash_batch`, which is why the sandbox command policy in the next section is the mechanism that decides what the agent is allowed to do.
A pooled sandbox gives two startup numbers and a read-only policy
Sandboxes are shared across users and conversations rather than created per chat. When a chat starts it attaches to an already running sandbox, which the documentation puts at startup under 100ms. When none is free, a pre-built snapshot spins one up in 1 to 3 seconds. So a fast path and a cold path exist, and the visible figure for the cold path is a range rather than a single number.
Sharing is what forces the restriction. Because the machine is not private to one conversation, agents reach it through a parsed command policy that permits only read-only commands: nothing that can write a file, nothing that spawns a process. The stated benefit is that several agents search the same current content without duplicating resources or affecting each other. The cost is architectural, since a template task that needs to write into the sandbox has to go around that policy.
Where the snapshot comes from is configurable in two steps. `NUXT_GITHUB_SNAPSHOT_REPO` sets an optional default repository that can also be changed from the admin sandbox interface, and `NUXT_GITHUB_TOKEN` is an optional fallback override, with a GitHub App named as the default path instead.
Three names for one project
The same template is called four different things in four different places. The repository is `vercel-labs/knowledge-agent-template`, the published packages are scoped `@savoir/sdk` and `@savoir/agent`, the root manifest is named `@savoir/monorepo`, and the deployed instance is `chatsdk-knowledge-agent.vercel.app`, named after the Chat SDK rather than after the scope. The Vercel clone link fills in yet another pair of names, `project-name=knowledge-agent` and `repository-name=knowledge-agent`.
So a reader who forked this and renamed it will find documentation that refers to a scope they never installed, a deployed URL that does not match the repository, and a package name that no npm identifier resolves to. Nothing in the tree forces one vocabulary over another, and the packages table is the only place the mapping from `@savoir/sdk` and `@savoir/agent` to `apps/app` is written down. The author field in the root manifest is a person's handle, `HugoRCD`, while the repository sits under the Vercel Labs organisation.
The SDK sample reads two variables the setup list does not show
The self-hosting path is five commands, ending with a copy of the example environment file:
# Clone the repository
git clone https://github.com/vercel-labs/knowledge-agent-template.git
cd knowledge-agent-template

# Install dependencies
bun install

# Configure environment variables
cp apps/app/.env.example apps/app/.env
# Edit .env with your configuration

# Start the app
bun run dev
The environment block that follows names three required values, `BETTER_AUTH_SECRET` for signing sessions and tokens, `GITHUB_CLIENT_ID`, and `GITHUB_CLIENT_SECRET` from a GitHub OAuth app, plus an optional `AI_GATEWAY_API_KEY` that is described as needed only for local development because Vercel uses OIDC automatically. The sandbox variables are optional and commented out.
The SDK sample at the top of this page is not on that list. It reads `SAVOIR_API_URL` with a non-null assertion and `SAVOIR_API_KEY`, and neither appears in the printed environment block. A pointer to a separate ENVIRONMENT.md for the full list is given, which is where they would have to be, but the two documents a reader is most likely to copy from disagree about what the SDK needs.
The admin agent can run SQL and conversations can be published
The built-in admin panel covers usage statistics, error logs, user management, source configuration, and content sync controls, and there is a second agent on top of it that answers questions about the app in natural language. Its internal tools are named in the text: `query_stats`, `query_errors`, `run_sql`, and `chart`, so the prompts it is built for are things like which errors happened in the last 24 hours, token usage by model, and which endpoints are slowest.
Two other features sit close to that surface. Model selection is automatic: every incoming question is classified by complexity from trivial to complex and routed accordingly, with simple questions sent to fast, cheap models and hard ones to heavier models, with no manual rules to keep. And any conversation can be shared with one click, which generates a public read-only link carrying the author, the title, and the complete exchange.
Put together, those three features decide what may end up outside your boundary. A share link republishes a full transcript, the admin agent has SQL access, and the transcript can contain tool output that came from your own sources.
Dependency patches, generated docs, and a hardcoded port
The root manifest is a Bun workspace with `apps/*` and `packages/*`, driven by Turborepo. `build` and `dev` run across everything, `dev:app` filters to `@savoir/app`, and `prepare` builds only the packages. Two scripts are more revealing than the rest. `automd` regenerates documentation, which is why the README can carry tables that describe the repository rather than restate it, and `dev:gateway` is a bare `curl -X GET http://localhost:3000/api/discord/gateway`, a Discord-specific endpoint pinned to port 3000 while the SDK sample asks for a configurable `SAVOIR_API_URL`.
Dependency handling is a mix of two mechanisms. There is a `patches/` directory at the root, and the manifest also carries a single override, `minimatch` at `^10.0.1`, alongside dev dependencies on `@hrcd/eslint-config`, `automd`, `playwright`, and `turbo`, with the package manager pinned to `[email protected]`. Configuration for other tools is checked in as well, with `.agents/`, `AGENTS.md`, `.config/`, an ESLint flat config, `renovate.json`, and `bunfig.toml`, which means the working rules of the repository are visible as files rather than described in a document.
Platform reach is adapters, and one of them is Discord
The same agent is meant to run as a chat app, a GitHub Issues bot, and a Discord bot, or all three at once, with Slack and Linear named as coming. Those surfaces are connected through pluggable adapters from the Chat SDK, and the customization guide states that adding a new platform is a single adapter file. That is the extension point to judge the template by: whether your own channel needs code or configuration.
The rest of the customization surface is naming and sources. An instance can be renamed with its name, icon, and description, and sources can be added beyond GitHub repositories and YouTube channels through custom connectors. Combined with the file-based search, the shape of the finished product is a set of repositories mirrored into a sandbox plus a shell the agent may read from, which is why the read-only policy is the constraint that decides how much of the surrounding workflow can be copied unchanged.
Editorial conclusion
This template is worth reading if you want an agent whose answers can be traced to files, since the search surface is a shell rather than a similarity index, and the tool visualisation shows which files were read and how long each step took. Four things to check before you build on it. First, sharing sandboxes across users is what forces the read-only command policy, so anything your agent genuinely needs to write will not work in the default architecture. Second, the admin agent holds `run_sql`, and conversations can be published as public read-only links carrying author, title, and the full exchange, so decide what may end up in a shareable transcript. Third, the local development path wants BETTER_AUTH_SECRET, a GitHub OAuth client id and secret, and copies `apps/app/.env.example`, while the SDK sample separately expects SAVOIR_API_URL and SAVOIR_API_KEY that the printed list does not contain. Fourth, the package scope, the deployed URL, and the repository name are all different words, which makes searching for your own fork harder than it should be.
Frequently asked questions
What is the Vercel Labs Knowledge Agent Template?
It is an open source template for building a file-system based agent that stays current with a knowledge base, meant to be forked and customized. Sources can be GitHub repositories, YouTube transcripts, or custom APIs, and the same agent deploys as a chat app, a GitHub Issues bot, a Discord bot, or all three.
Does the Knowledge Agent Template need an embedding model or a vector database?
Neither, by design. There is no vector database, no chunking pipeline, and no embedding model; agents search with `grep`, `find`, and `cat` inside isolated sandboxes. The `@savoir/sdk` exposes this as two AI SDK compatible tools, `bash` and `bash_batch`, and the results are described as deterministic and explainable.
What environment variables does the Knowledge Agent Template need?
Three values are required: `BETTER_AUTH_SECRET` for signing sessions and tokens, plus `GITHUB_CLIENT_ID` and `GITHUB_CLIENT_SECRET` from a GitHub OAuth app. `AI_GATEWAY_API_KEY` is optional and needed only for local development because Vercel uses OIDC automatically, while `NUXT_GITHUB_SNAPSHOT_REPO` and `NUXT_GITHUB_TOKEN` are optional sandbox overrides where the GitHub App is the default path. A separate ENVIRONMENT.md holds the full list.
How do I run the Knowledge Agent Template locally?
Clone the repository, run `bun install`, copy `apps/app/.env.example` to `apps/app/.env`, edit it with your configuration, and start with `bun run dev`. The Vercel clone link takes the same values as prompts, including the instruction to generate the secret with `openssl rand -hex 32` and to create a GitHub App for the client id and secret.
Can one knowledge agent serve several chat platforms?
Yes, through pluggable adapters from the Chat SDK. The documented targets are the web chat app, GitHub Issues, and Discord, with Slack and Linear named as coming, and adding a platform is described as a single adapter file. The Discord path also has a development script that requests the gateway endpoint on localhost port 3000.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/vercel-labs-knowledge-agent-template)Star history chart for your README
[](https://hysenlabs.com/projects/vercel-labs-knowledge-agent-template)Was this useful?