verl caps Python at 3.12 and ships a second dependency list
verl/HybridFlow: A Flexible and Efficient RL Post-Training Framework.
At a glance
- What is it?
- verl is an RL post-training library for large language models, initiated by the ByteDance Seed team, whose packaging metadata carries the load-bearing detail: a Python ceiling, a transformers exclusion justified by a crash, one backend deferred, and CUDA versions copied into a Dockerfile by hand.
- Who is it for?
- verl suits teams that already run PyTorch GPU clusters and want an RL dataflow written as code rather than wired together by hand; the hybrid-controller model and the 3D-HybridEngine resharding are the reasons to look. It does not suit anyone on Python 3.13, on a TensorRT-LLM backend, or on a CPU-only interpreter, because the pyproject caps Python below 3.13, defers trtllm, and keeps a separate CPU fork for CI.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 14, 2026, and from our analysis. They are not legal advice.
Star history
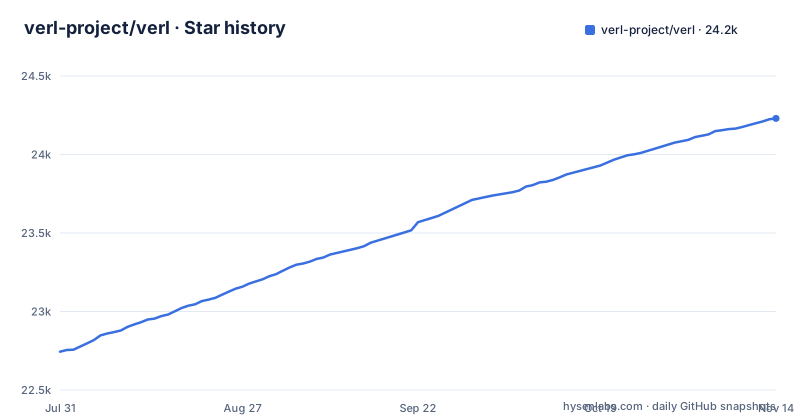
- verl-project/verl24,230 ★ · +1,486
| Repository | 2026-07-31 | 2026-11-14 |
|---|---|---|
| verl-project/verl | 22.7k | 24.2k |
1,486 Stars in the last 106 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
requires-python pins the ceiling at 3.12 and refuses anything newer
The packaging metadata caps the interpreter. pyproject.toml sets requires-python to >=3.10,<3.13, which admits 3.10, 3.11, and 3.12 and rejects 3.13 and everything after it. That is a hard stop at resolution time rather than a warning, so an environment already on a newer Python hits a resolver error on the pyproject path instead of a broken install discovered partway through. The repository also carries a second installer: setup.py describes itself as the fallback installation script when pyproject.toml does not work. Neither file states which Python it was last exercised on, so the limit has to be discovered by reading metadata.
transformers is capped below 5.13 because 5.6.0 broke sink-less models
setup.py and requirements.txt both carry the same constraint, transformers>=5.5.3,!=5.6.0,<5.17, and the reason is written into the source rather than left to a lockfile. A comment records that 5.6.0 ships a broken flash-attention path which crashes on s_aux=None for sink-less models, that it was fixed in 5.6.1, and that the report is huggingface/transformers#45588. So the single excluded release is a deliberate, documented workaround for a real crash. The <5.13 ceiling is a separate decision and the part to watch, since the constraint has to be edited in more than one file at once when transformers reaches 5.17. A stale ceiling then surfaces as an install failure on a machine that has nothing wrong with it.
trtllm is deferred from the unified lock because its sdist breaks uv
The packaging plan is one universal uv.lock in which every backend is a PEP 621 extra, with mutually exclusive backends declared in [tool.uv].conflicts so a single lock resolves all of them. At runtime you sync one conflict-free combination into a .venv shared by every Ray worker group:
uv sync --extra fsdp --extra vllm # or: python manage_envs.py sync fsdp vllmOne backend is deliberately left out of that scheme. The file records trtllm, against torch 2.10.0+cu130, as DEFERRED, with the stated reason that its release candidate sdist makes `uv lock` explode. The consequence is a documented gap rather than an oversight: there is no TensorRT-LLM extra reachable through the recommended path, so anyone who needs that inference backend cannot get it from a single lock. The reason given is a dependency-resolver problem rather than anything a flag can route around, and the file does not say when it will be picked back up.
torch sits at 2.13.0 while torchaudio is held at 2.11.0 on purpose
All backends are pinned to torch 2.13.0, with vllm, sglang, fsdp, and megatron on the cu130 wheels and cpu on the cpu wheels used for CI and development. torchaudio is held back at 2.11.0, described as its last release and the version that vllm 0.32 and sglang 0.5.20 themselves pin alongside torch 2.13. So the gap between the audio stack and the core framework is intentional, dictated by the inference engines rather than picked for convenience. Two torch worlds also coexist through [tool.uv].conflicts forks, one for the GPU backends and one for CPU. The cost is that there is no single version to quote: the GPU environment and the CI environment are deliberately different trees, so a result verified on one does not automatically describe the other.
cuDNN and NCCL versions have to be copied into the Dockerfile by hand after locking
Locking is not the last step. The instructions inside pyproject.toml say that torch's wheel pins cuDNN and NCCL, so after `uv lock` you must sync CUDNN_VERSION and NCCL_VERSION in docker/Dockerfile.uv.cu130 to whatever values were resolved. The consequence is a documented manual step that has to be repeated every time the resolved CUDA stack moves, and a drift between the Dockerfile and uv.lock shows up as a runtime failure rather than an install error, which is the expensive kind to diagnose. Anyone who builds the container from a published tag rather than from a lock they produced themselves is trusting that somebody else already ran this step.
The recipe directory is a submodule, so a plain clone arrives without recipes
The recipe directory was moved out to a dedicated repository, verl-recipe, and wired back in as a git submodule instead of being vendored. To use it you run:
git submodule update --init --recursive recipeand the project notes it can be used as it was after that step. A .gitmodules file at the top level confirms the arrangement. So a fresh clone that stops at git clone has no recipes in it, and the symptom is a missing directory rather than an error message you would recognise. Four other modules take the opposite route and are kept in the tree: transfer_queue, fully_async_policy, one_step_off_policy, and vla sit under verl/experimental because they are planned to be merged into the main library, and they are reached through verl.experimental.{module}. Those import paths are temporary by design, so code written against them will need editing later.
setup.py and pyproject.toml maintain two dependency lists that do not match
The fallback installer declares its own install_requires instead of reading the extras, and the two lists are not the same set. setup.py pulls in ray[default]>=2.41.0, torchdata, tensordict, wandb, packaging, and tensorboard, while pyproject.toml sorts packages into extras, with verl-core carrying TransferQueue>=0.1.11 plus the shared runtime dependencies and the test and math extras marked as kept verbatim from setup.py. requirements.txt, described as recording the full set of dependencies for development, is a third list, and it pins TransferQueue==0.1.11 exactly where the extra states only a floor. Anyone comparing the files can see that the fallback path does not reconstruct the environment the pyproject path builds. PRIME_REQUIRES is left empty on purpose, since PRIME code scoring dropped pyext, and the extra survives only so verl[prime] stays installable.
The example tree is 24 directories and 15 of them are named after algorithm acronyms
The examples directory is organised per algorithm, and many of its subdirectories end in _trainer, among them cispo, dppo, gdpo, gmpo, gpg, grpo, gspo, mtp, on_policy_distillation, otb, ppo, reinforce_plus_plus, remax and rloo. The README names GRPO and PPO as dataflows you can build in a few lines of code, and examples/README.md sits at the top of the directory. The remaining directories take supporting roles: data_preprocess, generation, rewards, profile, prefix_grouper, rollout_correction, muon, mxfp8, real_nvfp4 and ascend_extras. For someone about to launch a run, picking an algorithm name is the first decision.
Editorial conclusion
verl suits teams that already run PyTorch GPU clusters and want an RL dataflow written as code rather than wired together by hand; the hybrid-controller model and the 3D-HybridEngine resharding are the reasons to look. It does not suit anyone on Python 3.13, on a TensorRT-LLM backend, or on a CPU-only interpreter, because the pyproject caps Python below 3.13, defers trtllm, and keeps a separate CPU fork for CI. Before adopting it, read the comments inside pyproject.toml, because the transformers 5.6.0 exclusion and the cuDNN/NCCL hand-sync are documented there.
Frequently asked questions
What does Verl do?
It is an RL training library for large language models, initiated by the ByteDance Seed team and maintained by the verl community. Its hybrid-controller programming model lets you build post-training dataflows such as GRPO or PPO in a few lines of code.
Is verl open source?
Yes. It carries an Apache-2.0 license and is the open-source version of the HybridFlow paper. Recent tags include v0.9.1 from September 20, 2026, v0.9.0 from August 14, 2026, and v0.8.0 from June 1, 2026.
Does Verl use vLLM?
vLLM is one of the named integrations, alongside FSDP, Megatron-LM, and SGLang. Each backend is a PEP 621 extra, and mutually exclusive ones are resolved through [tool.uv].conflicts from a single uv.lock.
How do I install veRL?
The package name in pyproject.toml is verl, and requires-python is set to >=3.10,<3.13. The documented sync command is `uv sync --extra fsdp --extra vllm`, with `python manage_envs.py sync fsdp vllm` as the alternative, while setup.py is kept as the fallback when pyproject.toml does not work.
Official sources
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/verl-project-verl)Star history chart for your README
[](https://hysenlabs.com/projects/verl-project-verl)Was this useful?