TRL 1.17: A Practical Look at Hugging Face's RL Post-Training Toolkit
Train transformer language models with reinforcement learning. Built on top of the Transformers ecosystem, TRL supports a variety of model architectures and modalities, and can be scaled-up across various hardware setups.
At a glance
- What is it?
- TRL bundles SFT, GRPO, DPO, and KTO trainers into one library on top of Transformers, but its breadth comes with setup and scaling trade-offs. This review assesses what the repository actually offers and where it may fall short.
- Who is it for?
- Adopt TRL if you are already in the Hugging Face Transformers ecosystem and need a single library to run SFT, GRPO, DPO, or KTO on standard datasets with minimal code. Avoid it if you require fine-grained control over RL algorithms, need to support exotic model architectures outside Transformers, or expect turnkey performance on multi-node clusters without tuning Accelerate and DeepSpeed.
- Can I use it commercially?
- Yes. Apache-2.0 is a permissive licence: you can use, modify and sell software built on it, as long as you keep its copyright and licence notices.
- Is it still maintained?
- Yes. The repository received new commits within the last day.
- What is it written in?
- Mainly Python, according to GitHub's language statistics.
Answers come from the project's GitHub data, last synced on November 13, 2026, and from our analysis. They are not legal advice.
Star history
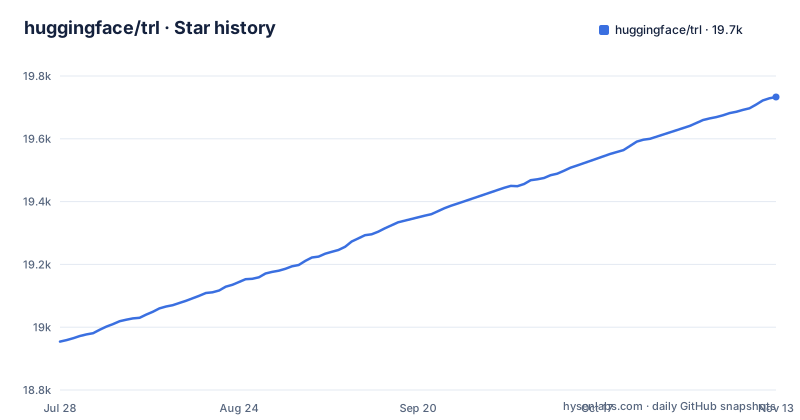
- huggingface/trl19,733 ★ · +779
| Repository | 2026-07-28 | 2026-11-13 |
|---|---|---|
| huggingface/trl | 19k | 19.7k |
779 Stars in the last 108 days, measured from the daily GitHub snapshot. Compare with other projects
Editorial analysis
What TRL Solves and Who It Serves
TRL addresses a specific pain point: wiring reinforcement learning and preference optimization into transformer language models without building the training loop from scratch. The library targets engineers and researchers who already live in the Hugging Face Transformers ecosystem and want to post-train a model using SFT, GRPO, DPO, KTO, or reward modeling. The README positions it as a comprehensive library for post-training foundation models, and the trainer examples show that the intended user is someone who can point a trainer at a model name and a dataset, then call train(). This is not a research playground for novel algorithms; it is a set of well-known methods packaged for practical use. The mention of DeepSeek R1's use of GRPO signals that the library is meant to reproduce proven techniques, not to push algorithmic boundaries.
How the Trainers Work Under the Hood
Each trainer in TRL is a light wrapper around the Hugging Face Transformers trainer, which means it inherits the standard training loop, checkpointing, and logging machinery. The GRPOTrainer, for instance, implements Group Relative Policy Optimization, a memory-efficient alternative to PPO. The DPO trainer implements Direct Preference Optimization, which uses paired preference data rather than a separate reward model. KTO takes a different route, using binary desirable or undesirable feedback instead of paired comparisons. The reward trainer fits a scalar reward model on preference data. The key architectural detail is that all of these share the same underlying training infrastructure, so switching between methods is a matter of swapping the trainer class and the dataset format. The README also notes that each trainer natively supports distributed training via DDP, DeepSpeed ZeRO, and FSDP, which is a direct consequence of the Accelerate integration. This uniformity is both a strength and a constraint: you get consistency, but you also inherit the Transformers trainer's assumptions about data collation and model interfaces.
Getting Started: Installation and the Quick Start Path
Installation is straightforward. The README gives three options: pip install trl, pip install git+https://github.com/huggingface/trl.git for the latest source, or a git clone for the examples. The quick start examples are minimal. For SFT, you instantiate SFTTrainer with a model name and a dataset, then call train(). The GRPO example uses a reward function, accuracy_reward, which is imported from trl.rewards. The DPO and KTO examples follow the same pattern, each with a different dataset. The CLI offers an even lower-friction path. The README lists a command line interface that lets you fine-tune models without writing code, and pyproject.toml registers a trl console script. The CLI is a notable feature because it lets a user run a post-training job without writing a single line of Python. The examples all use small models like Qwen2.5-0.5B, which suggests the default settings are tuned for modest hardware. That is a practical entry point, but it also means you will need to adjust batch sizes and gradient accumulation for larger models.
Scaling and Hardware Support: What the README Claims
The README claims that TRL scales from a single GPU to multi-node clusters using DDP, DeepSpeed, and FSDP. It also highlights integration with PEFT for LoRA and QLoRA, and with Unsloth for optimized kernels. These are real mechanisms, and the examples directory includes an accelerate_configs folder. The GRPO section notes it is more memory-efficient than PPO, which is a genuine advantage for large models, but the exact memory savings are not quantified. The practical takeaway is that TRL gives you the hooks, but the onus is on you to tune the distributed settings. If you are not familiar with Accelerate's launch scripts or DeepSpeed's ZeRO stages, the scaling story will be rough.
A Genuine Limitation: The Trainer Wrapper's Assumptions
The main limitation is that TRL's trainers are wrappers around the Transformers trainer. That means they inherit its assumptions about model architecture, data collation, and training loop behavior. If your model does not conform to the standard causal LM interface, or if your reward function needs custom generation logic, you may hit walls. The reasoning_accuracy_reward() function is mentioned as a better fit for reasoning models. Another limitation is the reliance on external services: the examples load datasets from the Hugging Face hub, which requires network access. For air-gapped environments, you will need to handle dataset caching and offline mode yourself. The library is also Python-only, so if your stack is not Python-based, TRL is not an option. These are not fatal flaws, but they define the boundaries of where TRL is the right tool.
The Alternative: Building on Raw Transformers and Accelerate
The most direct alternative is to skip TRL and build your own training loop using Transformers, Accelerate, and a custom RL implementation. The difference in approach is control. TRL gives you a fixed set of algorithms with preset behaviors. With raw Transformers, you can implement any variation of PPO, any custom reward shaping, or a new preference optimization method that TRL does not support. The cost is that you have to write the distributed logic, checkpointing, and data handling yourself, which is exactly what TRL automates. For a team that needs a specific algorithm variant or has unusual data formats, raw Transformers is more flexible. For a team that wants to run a standard DPO or GRPO run quickly, TRL saves days of boilerplate. The trade-off is clear: TRL is a convenience layer, and convenience always comes with a loss of flexibility.
Maintenance and Upgrade Considerations
TRL is under active development, with three recent releases: v1.17.1 on 2026-10-30, v1.17.0 on 2026-10-29 and v1.16.0 on 2026-10-15. That is a fast cadence, which means new features and bug fixes arrive often, but it also means the API can shift. The license is Apache-2.0, which is permissive and allows commercial use, modification, and redistribution, with the condition of preserving copyright notices. From a maintenance perspective, you should track release notes before upgrading, because a minor version bump could change trainer signatures or default behaviors. The repository is not archived, and the last push is recent, so the project is alive. The documentation is hosted at hf.co/docs/trl, which is the canonical reference. For an engineer, the upgrade cost is moderate: the library is a dependency that you can pin, but you will want to test against your specific training configuration after each release.
Editorial conclusion
Adopt TRL if you are already in the Hugging Face Transformers ecosystem and need a single library to run SFT, GRPO, DPO, or KTO on standard datasets with minimal code. Avoid it if you require fine-grained control over RL algorithms, need to support exotic model architectures outside Transformers, or expect turnkey performance on multi-node clusters without tuning Accelerate and DeepSpeed. Before committing, verify that your target model and reward function are compatible with the trainer's assumptions, and check the documentation for the specific algorithm's memory footprint and generation settings. TRL is a practical default for common post-training tasks, but it is not a substitute for understanding the underlying RL mechanics.
Frequently asked questions
What is Hugging Face TRL?
TRL is the Transformers Reinforcement Learning library, an Apache-2.0 Python package for post-training foundation models with Supervised Fine-Tuning, Group Relative Policy Optimization and Direct Preference Optimization. It is built on the Transformers ecosystem and each trainer is a light wrapper around the Transformers trainer, supporting DDP, DeepSpeed ZeRO and FSDP.
What is TRL AI used for?
It is used to post-train language models or PEFT adapters on a custom dataset, through trainers such as SFTTrainer, GRPOTrainer, DPOTrainer, KTOTrainer and RewardTrainer. The package requires Python 3.11 or newer and depends on accelerate, datasets, jinja2, packaging and transformers.
How do I install huggingface TRL?
The README gives `pip install trl`, `pip install git+https://github.com/huggingface/trl.git` for the latest features before a release, and `git clone https://github.com/huggingface/trl.git` if you want the examples. Optional extras include deepspeed, harbor and kernels.
Is TRL an alternative to Unsloth, and how do they differ?
The README describes Unsloth as an integration, listed alongside Accelerate and PEFT: TRL integrates Unsloth for accelerating training using optimized kernels. TRL supplies the trainers and algorithms, PEFT supplies adapters, Accelerate supplies distribution, and Unsloth supplies the faster kernels.
Official sources
Where this project is recommended
Add this badge to your README
If you maintain this project, the badge below links readers to this analysis and shows its maintenance status from the daily GitHub snapshot. Paste the markdown into your README; add ?metric=license or ?metric=stars to the image URL for a different field.
[](https://hysenlabs.com/projects/huggingface-trl)Star history chart for your README
[](https://hysenlabs.com/projects/huggingface-trl)Was this useful?